初始化 Qwen-Asr 本地仓库
 Bifang
commit
dde3e12476
|
|
@ -0,0 +1,70 @@
|
|||
# Git文件
|
||||
.git
|
||||
.gitignore
|
||||
.gitmodules
|
||||
|
||||
# Python缓存
|
||||
__pycache__
|
||||
*.pyc
|
||||
*.pyo
|
||||
*.pyd
|
||||
.Python
|
||||
*.so
|
||||
|
||||
# 虚拟环境
|
||||
venv
|
||||
env
|
||||
ENV
|
||||
.venv
|
||||
|
||||
# IDE文件
|
||||
.vscode
|
||||
.idea
|
||||
*.swp
|
||||
*.swo
|
||||
|
||||
# 系统文件
|
||||
.DS_Store
|
||||
Thumbs.db
|
||||
|
||||
# 日志文件
|
||||
*.log
|
||||
logs/
|
||||
|
||||
# 临时文件
|
||||
temp/
|
||||
tmp/
|
||||
*.tmp
|
||||
build-file/
|
||||
|
||||
# 模型文件(这些将通过volume挂载)
|
||||
tts/third_party/CosyVoice/pretrained_models/
|
||||
models/
|
||||
*.pt
|
||||
*.pth
|
||||
*.bin
|
||||
*.safetensors
|
||||
*.tar.gz
|
||||
|
||||
# 测试文件
|
||||
tests/
|
||||
*.test
|
||||
coverage.*
|
||||
|
||||
# 文档
|
||||
README.md
|
||||
*.md
|
||||
docs/
|
||||
|
||||
# 配置文件(可能包含敏感信息)
|
||||
.env
|
||||
.env.*
|
||||
|
||||
# 本地音视频样本
|
||||
*.m4a
|
||||
*.mp4
|
||||
|
||||
# 其他
|
||||
.pytest_cache
|
||||
.coverage
|
||||
node_modules
|
||||
|
|
@ -0,0 +1,150 @@
|
|||
# Qwen3-ASR 环境变量覆盖示例
|
||||
# 复制为 .env 后,只取消你需要修改的项的注释即可。
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# 仅在需要 API Key 鉴权时开启。
|
||||
# -----------------------------------------------------------------------------
|
||||
# API_KEY=your_api_key_here
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# Docker / 部署入口配置。
|
||||
# -----------------------------------------------------------------------------
|
||||
# NGINX_PORT:宿主机暴露的 Nginx 端口。
|
||||
# NGINX_PORT=17003
|
||||
# ASR_IMAGE:离线包或自定义部署时使用的镜像标签。
|
||||
# ASR_IMAGE=unis/qwen3-asr:gpu-latest
|
||||
# ASR_VISIBLE_DEVICES:统一可见卡编号配置,多个用逗号分隔;程序会按当前 accelerator 自动映射到底层变量。
|
||||
# ASR_VISIBLE_DEVICES=0
|
||||
# METAX_DRI_DEVICE:沐曦 / MuXi 需要映射的 DRI 设备路径。
|
||||
# METAX_DRI_DEVICE=/dev/dri
|
||||
# METAX_MXSMI_PATH:沐曦 / MuXi 的 mx-smi 工具路径。
|
||||
# METAX_MXSMI_PATH=/opt/mxdriver/bin/mx-smi
|
||||
# METAX_PRIVILEGED:沐曦 / MuXi 容器是否以 privileged 方式运行。
|
||||
# METAX_PRIVILEGED=false
|
||||
# ILUVATAR_USR_SRC:天数 / Iluvatar 容器内 usr/src 挂载路径。
|
||||
# ILUVATAR_USR_SRC=/usr/src
|
||||
# ILUVATAR_LIB_MODULES:天数 / Iluvatar 容器内模块目录挂载路径。
|
||||
# ILUVATAR_LIB_MODULES=/lib/modules
|
||||
# ILUVATAR_DEV:天数 / Iluvatar 设备目录挂载路径。
|
||||
# ILUVATAR_DEV=/dev
|
||||
# ILUVATAR_HOME:天数 / Iluvatar 主目录挂载路径。
|
||||
# ILUVATAR_HOME=/home
|
||||
# ILUVATAR_DATA:天数 / Iluvatar 数据目录挂载路径。
|
||||
# ILUVATAR_DATA=/data
|
||||
# MTHREADS_DEV:摩尔线程 / Moore Threads 设备目录挂载路径。
|
||||
# MTHREADS_DEV=/dev
|
||||
# MTHREADS_USR_SRC:摩尔线程 / Moore Threads 容器内 usr/src 挂载路径。
|
||||
# MTHREADS_USR_SRC=/usr/src
|
||||
# MTHREADS_LIB_MODULES:摩尔线程 / Moore Threads 容器内模块目录挂载路径。
|
||||
# MTHREADS_LIB_MODULES=/lib/modules
|
||||
# MTHREADS_HOME:摩尔线程 / Moore Threads 主目录挂载路径。
|
||||
# MTHREADS_HOME=/home
|
||||
# MTHREADS_DATA:摩尔线程 / Moore Threads 数据目录挂载路径。
|
||||
# MTHREADS_DATA=/data
|
||||
# MODEL_STORAGE_DIR:模型宿主机挂载目录。
|
||||
# MODEL_STORAGE_DIR=/opt/dep/asr/models
|
||||
# DATA_STORAGE_DIR:业务数据宿主机挂载目录。
|
||||
# DATA_STORAGE_DIR=/opt/dep/asr/data
|
||||
# NGINX_RATE_LIMIT_RPS:Nginx 全局限流,单位为每秒请求数。
|
||||
# NGINX_RATE_LIMIT_RPS=0
|
||||
# NGINX_RATE_LIMIT_BURST:Nginx 全局突发限流额度,0 表示自动按 RPS 处理。
|
||||
# NGINX_RATE_LIMIT_BURST=0
|
||||
# ASR_DEPLOY_TOPOLOGY:部署拓扑,isolated=每卡一个实例,sharded=单实例多卡分片,auto=优先 sharded 失败回退 isolated。
|
||||
# ASR_DEPLOY_TOPOLOGY=isolated
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# 运行时模型选择。
|
||||
# 留空 QWEN3_ASR_MODEL 时会自动选择。
|
||||
# 支持值:qwen3-asr-0.6b、qwen3-asr-1.7b
|
||||
# -----------------------------------------------------------------------------
|
||||
# ACCELERATOR:加速后端类型,常见值有 auto、cpu、nvidia、metax、iluvatar、mthreads。
|
||||
# ACCELERATOR=auto
|
||||
# DEVICE:具体运行设备,常见值有 auto、cpu、cuda:0。
|
||||
# DEVICE=auto
|
||||
# QWEN3_ASR_MODEL:手动指定离线识别模型,留空则自动挑选。
|
||||
# QWEN3_ASR_MODEL=
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# 模型下载 / 缓存行为。
|
||||
# 在 Docker Compose 中,默认宿主机挂载目录是 /opt/dep/asr/models。
|
||||
# 实际模型目录通常位于:
|
||||
# /opt/dep/asr/models/Qwen
|
||||
# /opt/dep/asr/models/iic
|
||||
# /opt/dep/asr/models/damo
|
||||
# -----------------------------------------------------------------------------
|
||||
# MODELS_DIR:项目主模型目录。
|
||||
# MODELS_DIR=/opt/dep/asr/models
|
||||
# MODELSCOPE_CACHE:ModelScope 缓存根目录,下面会生成 models/{publisher}/{model}。
|
||||
# MODELSCOPE_CACHE=/opt/dep/asr
|
||||
# MODELSCOPE_PATH:ModelScope 实际模型目录,建议保持在 models 目录下。
|
||||
# MODELSCOPE_PATH=/opt/dep/asr/models
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# 说话人注册 / pgvector 数据库配置。
|
||||
# 表结构与 Model-Test-New 保持一致:speakers(id, name, user_id, embedding)。
|
||||
# -----------------------------------------------------------------------------
|
||||
# SPEAKER_DB_ENABLED:是否启用说话人库与 pgvector 检索。
|
||||
# SPEAKER_DB_ENABLED=true
|
||||
# DB_HOST:PostgreSQL 主机地址。
|
||||
# DB_HOST=127.0.0.1
|
||||
# DB_PORT:PostgreSQL 端口。
|
||||
# DB_PORT=5432
|
||||
# DB_USER:PostgreSQL 用户名。
|
||||
# DB_USER=postgres
|
||||
# DB_PASSWORD:PostgreSQL 密码。
|
||||
# DB_PASSWORD=postgres
|
||||
# DB_NAME:PostgreSQL 数据库名。
|
||||
# DB_NAME=asr_db
|
||||
# SV_MODEL:说话人识别模型。
|
||||
# SV_MODEL=iic/speech_campplus_sv_zh-cn_16k-common
|
||||
# SV_THRESHOLD:说话人相似度阈值,越大越严格。
|
||||
# SV_THRESHOLD=0.6
|
||||
# TEMP_DIR:临时文件目录。
|
||||
# TEMP_DIR=/opt/dep/asr/data/temp
|
||||
# LOG_FILE:日志文件路径。
|
||||
# LOG_FILE=/opt/dep/asr/data/logs/qwen3-asr.log
|
||||
# TASK_STATE_DIR:任务状态持久化目录。
|
||||
# TASK_STATE_DIR=/opt/dep/asr/data/tasks
|
||||
# TASK_RETENTION_HOURS:任务结果保留时间,单位小时。
|
||||
# TASK_RETENTION_HOURS=24
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# CPU Rust 后端覆盖配置。
|
||||
# 一般不需要改;自动检测会检查 vendor/qwenasr/target/{release,debug}。
|
||||
# -----------------------------------------------------------------------------
|
||||
# QWENASR_LIBRARY_PATH:手动指定 libqwen_asr.so 的绝对路径。
|
||||
# QWENASR_LIBRARY_PATH=/absolute/path/to/libqwen_asr.so
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# 调优参数。除非你在做特定瓶颈测试,否则建议保持默认。
|
||||
# -----------------------------------------------------------------------------
|
||||
# ASR_BATCH_SIZE:批处理大小,表示一次并行推理的片段数。
|
||||
# ASR_BATCH_SIZE=4
|
||||
# ASR_ENABLE_WORD_TIMESTAMPS:是否启用字词级时间戳。
|
||||
# ASR_ENABLE_WORD_TIMESTAMPS=false
|
||||
# MAX_SEGMENT_SEC:离线 ASR 单段最大时长,单位秒。
|
||||
# MAX_SEGMENT_SEC=60
|
||||
# QWEN_RUST_CPU_WORKERS:Qwen Rust CPU 后端 worker 数。
|
||||
# QWEN_RUST_CPU_WORKERS=4
|
||||
# QWEN_RUST_ASR_CONCURRENCY:Qwen Rust ASR 并发数,0 通常表示自动。
|
||||
# QWEN_RUST_ASR_CONCURRENCY=0
|
||||
# QWEN_RUST_ALIGN_CONCURRENCY:Qwen Rust 对齐并发数,0 通常表示自动。
|
||||
# QWEN_RUST_ALIGN_CONCURRENCY=0
|
||||
# QWEN_GPU_MEMORY_UTILIZATION:GPU 显存使用比例。
|
||||
# QWEN_GPU_MEMORY_UTILIZATION=0.9
|
||||
# QWEN_VLLM_ENFORCE_EAGER:是否强制 vLLM eager 执行;国产卡/稳定优先建议 true,NVIDIA 性能测试可设 false。
|
||||
# QWEN_VLLM_ENFORCE_EAGER=true
|
||||
# QWEN_FORCE_ALIGNER_GPU_MEMORY_UTILIZATION:forced aligner 预留的显存比例。
|
||||
# QWEN_FORCE_ALIGNER_GPU_MEMORY_UTILIZATION=0.15
|
||||
# ASR_ENABLE_NEARFIELD_FILTER:是否启用近场/远场过滤。
|
||||
# ASR_ENABLE_NEARFIELD_FILTER=true
|
||||
# ASR_NEARFIELD_RMS_THRESHOLD:近场判断的 RMS 能量阈值。
|
||||
# ASR_NEARFIELD_RMS_THRESHOLD=0.01
|
||||
|
||||
# -----------------------------------------------------------------------------
|
||||
# 仅用于本地开发调试。
|
||||
# -----------------------------------------------------------------------------
|
||||
# LOG_LEVEL:日志级别。
|
||||
# LOG_LEVEL=INFO
|
||||
# FUNASR_STARTUP_UI:FunASR 启动界面模式。
|
||||
# FUNASR_STARTUP_UI=auto
|
||||
|
|
@ -0,0 +1,48 @@
|
|||
# Environment files (contain sensitive information)
|
||||
.env
|
||||
*.env.local
|
||||
*.env.*.local
|
||||
|
||||
# Build and deployment files
|
||||
build-file/
|
||||
|
||||
# Downloaded models directory
|
||||
/models/
|
||||
|
||||
# Large binary packages
|
||||
*.tar.gz
|
||||
*.tar
|
||||
*.zip
|
||||
|
||||
# Python cache
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
*$py.class
|
||||
*.so
|
||||
|
||||
# Model files (downloaded)
|
||||
*.pt
|
||||
*.pth
|
||||
*.onnx
|
||||
*.safetensors
|
||||
*.bin
|
||||
|
||||
# Log files
|
||||
*.log
|
||||
logs/
|
||||
|
||||
# OS files
|
||||
.DS_Store
|
||||
Thumbs.db
|
||||
|
||||
# IDE
|
||||
.idea/
|
||||
.vscode/
|
||||
*.swp
|
||||
*.swo
|
||||
|
||||
# Temporary files
|
||||
*.tmp
|
||||
*.temp
|
||||
.cache/
|
||||
.code-review-graph/
|
||||
|
|
@ -0,0 +1,36 @@
|
|||
# Code Review Graph MCP
|
||||
|
||||
Generated from the `agent-tool-basic` template.
|
||||
|
||||
## Contributions
|
||||
|
||||
- Agent tool `echo_text`
|
||||
|
||||
## Develop
|
||||
|
||||
1. Open the Plugins page and use **Load development plugin**, pointing at this
|
||||
directory. PI-Desktop reloads the plugin whenever you save a file here.
|
||||
2. Verify the contributions from the command palette.
|
||||
3. Validate and package:
|
||||
|
||||
```bash
|
||||
pnpm pi-plugin check .
|
||||
pnpm pi-plugin pack .
|
||||
# writes dist/crg-mcp-0.1.0.piplug
|
||||
```
|
||||
|
||||
Install the resulting `.piplug` from the Plugins page to test it the way a
|
||||
user would.
|
||||
|
||||
### Panel top drag band
|
||||
|
||||
PI-Desktop reserves exactly a transparent 46px frameless drag band above panel
|
||||
content and renders a minimal fixed three-button window-control capsule in its
|
||||
top-right corner. Normal-flow content is offset automatically. The panel title,
|
||||
toolbar, and every other visible surface belong to the plugin. Development
|
||||
panels show a reminder that the top 46px is not clickable outside the capsule.
|
||||
For `position: fixed` or `position: sticky` content, use
|
||||
`top: var(--pi-plugin-titlebar-height, 46px)` and account for the same value
|
||||
in viewport-height calculations. Add `-webkit-app-region: drag` to a
|
||||
plugin-owned toolbar when it should move the window, and
|
||||
`-webkit-app-region: no-drag` to controls inside it.
|
||||
|
|
@ -0,0 +1,57 @@
|
|||
@echo off
|
||||
chcp 65001 >nul
|
||||
setlocal
|
||||
|
||||
rem ---------------------------------------------------------------------------
|
||||
rem code-review-graph MCP launcher for PI-Desktop.
|
||||
rem
|
||||
rem The MCP host spawns this with a minimal environment (PATH, SystemRoot,
|
||||
rem windir, TEMP, TMP, LANG plus the manifest's env block) and cwd = plugin
|
||||
rem directory, with stdin/stdout used for JSON-RPC. Never write to stdout.
|
||||
rem ---------------------------------------------------------------------------
|
||||
|
||||
if defined CRG_HOME goto have_home
|
||||
set "CRG_HOME=D:\github-project\code-review-graph"
|
||||
:have_home
|
||||
|
||||
rem code_review_graph/constants.py calls Path.home() at import time; without a
|
||||
rem user profile the server dies with "Could not determine home directory.".
|
||||
if defined USERPROFILE goto have_profile
|
||||
set "USERPROFILE=C:\Users\%USERNAME%"
|
||||
:have_profile
|
||||
if defined HOMEDRIVE goto have_hd
|
||||
set "HOMEDRIVE=C:"
|
||||
:have_hd
|
||||
if defined HOMEPATH goto have_hp
|
||||
set "HOMEPATH=\Users\%USERNAME%"
|
||||
:have_hp
|
||||
if defined APPDATA set "APPDATA=%USERPROFILE%\AppData\Roaming"
|
||||
if defined LOCALAPPDATA set "LOCALAPPDATA=%USERPROFILE%\AppData\Local"
|
||||
|
||||
set "PYTHONUTF8=1"
|
||||
set "PYTHONIOENCODING=utf-8"
|
||||
|
||||
rem The editable install's .pth points at D:\github_project\... (underscore)
|
||||
rem while the checkout lives at D:\github-project\... (hyphen), so the package
|
||||
rem is only importable with the checkout explicitly on sys.path.
|
||||
set "PYTHONPATH=%CRG_HOME%"
|
||||
|
||||
rem The venv's code-review-graph.exe is a broken uv trampoline
|
||||
rem ("failed to canonicalize script path"), so prefer a working interpreter.
|
||||
set "CRG_PY=%CRG_HOME%\.venv\Scripts\python.exe"
|
||||
if exist "%CRG_PY%" goto py_ready
|
||||
set "CRG_PY=python"
|
||||
:py_ready
|
||||
|
||||
rem Upstream ships 30 tools; keep the surface small unless overridden.
|
||||
if defined CRG_TOOLS goto tools_ready
|
||||
set "CRG_TOOLS=build_or_update_graph_tool,run_postprocess_tool,get_minimal_context_tool,get_review_context_tool,get_impact_radius_tool,query_graph_tool,semantic_search_nodes_tool,detect_changes_tool,list_graph_stats_tool,get_affected_flows_tool"
|
||||
:tools_ready
|
||||
|
||||
if defined CRG_REPO goto repo_ready
|
||||
set "CRG_REPO=%CRG_HOME%"
|
||||
:repo_ready
|
||||
|
||||
"%CRG_PY%" -m code_review_graph serve --repo "%CRG_REPO%"
|
||||
|
||||
endlocal
|
||||
|
|
@ -0,0 +1,16 @@
|
|||
/**
|
||||
* crg-mcp — thin loader for the code-review-graph MCP bridge.
|
||||
*
|
||||
* All wiring lives in manifest.json under `contributes.mcpServers`: the host
|
||||
* spawns `crg.cmd`, speaks MCP over its stdio, and publishes each upstream tool
|
||||
* as `plugin_crg_mcp_crg_<tool>`. The host owns the client, the retry on the
|
||||
* next call, and the tool lifecycle, so there is nothing to register here.
|
||||
*/
|
||||
|
||||
async function onLoad() {
|
||||
// Intentionally empty: the MCP client is owned by the host.
|
||||
}
|
||||
|
||||
async function onUnload() {}
|
||||
|
||||
module.exports = { onLoad, onUnload };
|
||||
|
|
@ -0,0 +1,33 @@
|
|||
{
|
||||
"schemaVersion": 1,
|
||||
"id": "crg-mcp",
|
||||
"name": "Code Review Graph MCP",
|
||||
"version": "1.0.0",
|
||||
"description": "Bridges the locally deployed code-review-graph MCP server into the agent as native tools.",
|
||||
"main": "main.js",
|
||||
"contributes": {
|
||||
"mcpServers": [
|
||||
{
|
||||
"id": "crg",
|
||||
"label": "Code Review Graph",
|
||||
"transport": "stdio",
|
||||
"command": "crg.cmd",
|
||||
"env": {
|
||||
"PYTHONPATH": "D:\\github-project\\code-review-graph",
|
||||
"USERPROFILE": "C:\\Users\\admin",
|
||||
"HOMEDRIVE": "C:",
|
||||
"HOMEPATH": "\\Users\\admin"
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
"permissions": [
|
||||
"mcp.server.local"
|
||||
],
|
||||
"engines": {
|
||||
"piDesktop": ">=0.1.0"
|
||||
},
|
||||
"activationEvents": [
|
||||
"onStartup"
|
||||
]
|
||||
}
|
||||
|
|
@ -0,0 +1,96 @@
|
|||
<#
|
||||
Self-check for the crg-mcp plugin.
|
||||
|
||||
Drives crg.cmd exactly the way the PI-Desktop MCP host does — `cmd /c crg.cmd`
|
||||
with piped stdio and cwd = this folder — then reports the MCP handshake, the
|
||||
tool list, and one real tool call. Run it from PowerShell:
|
||||
|
||||
powershell -NoProfile -ExecutionPolicy Bypass -File .\selfcheck.ps1
|
||||
#>
|
||||
$ErrorActionPreference = 'Stop'
|
||||
|
||||
$dir = Split-Path -Parent $MyInvocation.MyCommand.Path
|
||||
|
||||
# Mirror the host's minimal environment plus the manifest's env block.
|
||||
foreach ($k in 'PATH', 'SystemRoot', 'TEMP', 'TMP') {
|
||||
if (-not (Test-Path "Env:$k")) { Write-Warning "missing $k in ambient env" }
|
||||
}
|
||||
|
||||
$psi = New-Object System.Diagnostics.ProcessStartInfo
|
||||
$psi.FileName = 'cmd.exe'
|
||||
$psi.Arguments = '/c crg.cmd'
|
||||
$psi.WorkingDirectory = $dir
|
||||
$psi.RedirectStandardInput = $true
|
||||
$psi.RedirectStandardOutput = $true
|
||||
$psi.RedirectStandardError = $true
|
||||
$psi.UseShellExecute = $false
|
||||
$psi.StandardOutputEncoding = [System.Text.Encoding]::UTF8
|
||||
|
||||
$proc = [System.Diagnostics.Process]::Start($psi)
|
||||
|
||||
function Send($obj) {
|
||||
$proc.StandardInput.WriteLine(($obj | ConvertTo-Json -Compress -Depth 8))
|
||||
$proc.StandardInput.Flush()
|
||||
}
|
||||
|
||||
function ReadLine([int]$waitSeconds = 25) {
|
||||
$task = $proc.StandardOutput.ReadLineAsync()
|
||||
if ($task.Wait([TimeSpan]::FromSeconds($waitSeconds))) { return $task.Result }
|
||||
return $null
|
||||
}
|
||||
|
||||
Send @{
|
||||
jsonrpc = '2.0'; id = 1; method = 'initialize'
|
||||
params = @{
|
||||
protocolVersion = '2025-06-18'
|
||||
capabilities = @{}
|
||||
clientInfo = @{ name = 'crg-selfcheck'; version = '1' }
|
||||
}
|
||||
}
|
||||
|
||||
$initLine = ReadLine 40
|
||||
if (-not $initLine) {
|
||||
Write-Host 'HANDSHAKE FAILED: no stdout from crg.cmd' -ForegroundColor Red
|
||||
Write-Host '--- stderr ---'
|
||||
Write-Host $proc.StandardError.ReadToEnd()
|
||||
try { $proc.Kill() } catch { }
|
||||
exit 1
|
||||
}
|
||||
|
||||
$init = $initLine | ConvertFrom-Json
|
||||
Write-Host ("HANDSHAKE OK server={0} {1}" -f $init.result.serverInfo.name, $init.result.serverInfo.version) -ForegroundColor Green
|
||||
|
||||
Send @{ jsonrpc = '2.0'; method = 'notifications/initialized'; params = @{} }
|
||||
Send @{ jsonrpc = '2.0'; id = 2; method = 'tools/list'; params = @{} }
|
||||
|
||||
$toolsLine = ReadLine
|
||||
if (-not $toolsLine) {
|
||||
Write-Host 'tools/list returned nothing' -ForegroundColor Red
|
||||
try { $proc.Kill() } catch { }
|
||||
exit 1
|
||||
}
|
||||
$tools = ($toolsLine | ConvertFrom-Json).result.tools
|
||||
Write-Host ("TOOLS: {0}" -f $tools.Count) -ForegroundColor Green
|
||||
foreach ($t in $tools) { Write-Host (" plugin_crg_mcp_crg_{0}" -f $t.name) }
|
||||
|
||||
Send @{
|
||||
jsonrpc = '2.0'; id = 3; method = 'tools/call'
|
||||
params = @{ name = 'list_graph_stats_tool'; arguments = @{} }
|
||||
}
|
||||
$callLine = ReadLine 40
|
||||
if ($callLine) {
|
||||
$call = $callLine | ConvertFrom-Json
|
||||
if ($call.result) {
|
||||
$text = $call.result.content[0].text
|
||||
Write-Host 'TOOL CALL OK' -ForegroundColor Green
|
||||
Write-Host (' ' + ($text -split "`n")[0..3] -join ' | ')
|
||||
}
|
||||
else {
|
||||
Write-Host ("TOOL CALL ERROR: {0}" -f ($call | ConvertTo-Json -Compress -Depth 6)) -ForegroundColor Red
|
||||
}
|
||||
}
|
||||
else {
|
||||
Write-Host 'TOOL CALL: no response' -ForegroundColor Red
|
||||
}
|
||||
|
||||
try { $proc.Kill() } catch { }
|
||||
|
|
@ -0,0 +1,73 @@
|
|||
FROM python:3.10-slim AS runtime
|
||||
|
||||
ENV DEBIAN_FRONTEND=noninteractive \
|
||||
PYTHONUNBUFFERED=1 \
|
||||
PYTHONDONTWRITEBYTECODE=1 \
|
||||
HF_HUB_DISABLE_SYMLINKS_WARNING=1 \
|
||||
HF_HUB_DISABLE_PROGRESS_BARS=1 \
|
||||
OPENBLAS_NUM_THREADS=1 \
|
||||
OMP_NUM_THREADS=1 \
|
||||
GOTO_NUM_THREADS=1 \
|
||||
QWENASR_LIBRARY_PATH=/opt/qwenasr/lib/libqwen_asr.so
|
||||
|
||||
# Install system packages required for audio processing
|
||||
RUN apt-get update && apt-get install -y --no-install-recommends \
|
||||
ffmpeg \
|
||||
sox \
|
||||
libsox-dev \
|
||||
libsndfile1 \
|
||||
libopenblas-dev \
|
||||
nginx \
|
||||
build-essential \
|
||||
curl
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
ARG TARGETARCH
|
||||
ARG QWENASR_RUST_TARGET_CPU=x86-64-v2
|
||||
|
||||
COPY vendor/qwenasr /tmp/qwenasr
|
||||
|
||||
# Install Rust compiler (required for sudachipy on ARM64)
|
||||
RUN curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh -s -- -y
|
||||
ENV PATH="/root/.cargo/bin:${PATH}"
|
||||
|
||||
# Build QwenASR Rust shared library for CPU Qwen3-ASR inference. The default
|
||||
# amd64 target stays portable across common AVX2-era servers; set
|
||||
# QWENASR_RUST_TARGET_CPU=native only for self-built, host-specific images.
|
||||
RUN if [ "$TARGETARCH" = "amd64" ]; then export RUSTFLAGS="-C target-cpu=${QWENASR_RUST_TARGET_CPU}"; fi \
|
||||
&& cargo build --release -p qwen-asr --features ffi --manifest-path /tmp/qwenasr/Cargo.toml \
|
||||
&& mkdir -p /opt/qwenasr/lib \
|
||||
&& cp /tmp/qwenasr/target/release/libqwen_asr.so /opt/qwenasr/lib/libqwen_asr.so
|
||||
|
||||
# Install Python dependencies (CPU mode)
|
||||
COPY environments/cpu/pyproject.toml /app/environments/cpu/pyproject.toml
|
||||
RUN python - <<'PY' > /tmp/qwen3-asr-cpu-reqs.txt
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
data = tomllib.loads(Path("/app/environments/cpu/pyproject.toml").read_text())
|
||||
for dep in data["project"]["dependencies"]:
|
||||
print(dep)
|
||||
print("asyncpg==0.31.0")
|
||||
PY
|
||||
RUN pip install --no-cache-dir -r /tmp/qwen3-asr-cpu-reqs.txt && \
|
||||
rm -f /tmp/qwen3-asr-cpu-reqs.txt
|
||||
|
||||
# Clean build tools and cache to reduce image size
|
||||
RUN apt remove -y build-essential curl && apt autoremove -y \
|
||||
&& rm -rf /tmp/qwenasr \
|
||||
&& rm -rf /root/.cargo /root/.rustup \
|
||||
&& apt-get clean && rm -rf /var/lib/apt/lists/*
|
||||
|
||||
# Copy application code
|
||||
COPY . .
|
||||
|
||||
# Create runtime directories
|
||||
RUN mkdir -p /app/data/temp /app/data/logs /app/data/tasks \
|
||||
&& chmod +x start.py /app/scripts/docker/entrypoint.sh
|
||||
|
||||
EXPOSE 8000
|
||||
|
||||
ENTRYPOINT ["/app/scripts/docker/entrypoint.sh"]
|
||||
CMD ["python", "start.py"]
|
||||
|
|
@ -0,0 +1,101 @@
|
|||
ARG PYTORCH_BASE_IMAGE=pytorch/pytorch:2.11.0-cuda13.0-cudnn9-runtime
|
||||
FROM ${PYTORCH_BASE_IMAGE}
|
||||
|
||||
ARG CUDA_NVCC_PACKAGE=cuda-nvcc-13-0
|
||||
ARG PYTORCH_CUDA_INDEX=https://download.pytorch.org/whl/cu130
|
||||
ARG TORCH_VERSION=2.11.0
|
||||
ARG TORCHAUDIO_VERSION=2.11.0
|
||||
ARG TORCHVISION_VERSION=0.26.0
|
||||
ARG VLLM_VERSION=0.20.0
|
||||
ARG TORCH_CUDA_ARCH_LIST=12.0+PTX
|
||||
|
||||
ENV DEBIAN_FRONTEND=noninteractive \
|
||||
PYTHONUNBUFFERED=1 \
|
||||
PYTHONDONTWRITEBYTECODE=1 \
|
||||
HF_HUB_DISABLE_SYMLINKS_WARNING=1 \
|
||||
HF_HUB_DISABLE_PROGRESS_BARS=1 \
|
||||
PIP_BREAK_SYSTEM_PACKAGES=1 \
|
||||
TORCH_CUDA_ARCH_LIST=${TORCH_CUDA_ARCH_LIST}
|
||||
|
||||
# Add NVIDIA apt repository for CUDA packages
|
||||
RUN apt-get update && apt-get install -y --no-install-recommends \
|
||||
ca-certificates \
|
||||
gnupg \
|
||||
wget \
|
||||
&& wget -qO - https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2404/x86_64/3bf863cc.pub | apt-key add - \
|
||||
&& echo "deb https://developer.download.nvidia.com/compute/cuda/repos/ubuntu2404/x86_64 /" > /etc/apt/sources.list.d/cuda.list \
|
||||
&& apt-get update
|
||||
|
||||
# Install system packages required for audio processing
|
||||
# Note: nvcc and build-essential are required for FlashInfer JIT compilation.
|
||||
RUN apt-get install -y --no-install-recommends \
|
||||
ffmpeg \
|
||||
sox \
|
||||
libsox-dev \
|
||||
libsndfile1 \
|
||||
nginx \
|
||||
build-essential \
|
||||
${CUDA_NVCC_PACKAGE}
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
# Install Python dependencies directly into the image runtime Python.
|
||||
# The image defaults to CUDA 13.0/cu130 for Blackwell-capable GPUs. Developers
|
||||
# can rebuild with a different PyTorch CUDA backend by overriding:
|
||||
# PYTORCH_BASE_IMAGE, PYTORCH_CUDA_INDEX, CUDA_NVCC_PACKAGE, TORCH_CUDA_ARCH_LIST.
|
||||
COPY pyproject.toml /app/
|
||||
RUN python - <<'PY' > /tmp/qwen3-asr-gpu-reqs.txt
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
data = tomllib.loads(Path("/app/pyproject.toml").read_text())
|
||||
for dep in data["project"]["dependencies"]:
|
||||
if dep.startswith("torch=="):
|
||||
continue
|
||||
if dep.startswith("torchaudio=="):
|
||||
continue
|
||||
if dep.startswith("torchvision=="):
|
||||
continue
|
||||
if dep.startswith("vllm=="):
|
||||
continue
|
||||
print(dep)
|
||||
PY
|
||||
RUN pip install --no-cache-dir -r /tmp/qwen3-asr-gpu-reqs.txt && \
|
||||
pip install --no-cache-dir \
|
||||
--index-url "${PYTORCH_CUDA_INDEX}" \
|
||||
--extra-index-url https://pypi.org/simple \
|
||||
"torch==${TORCH_VERSION}" \
|
||||
"torchaudio==${TORCHAUDIO_VERSION}" \
|
||||
"torchvision==${TORCHVISION_VERSION}" && \
|
||||
pip install --no-cache-dir "vllm==${VLLM_VERSION}" && \
|
||||
rm -f /tmp/qwen3-asr-gpu-reqs.txt
|
||||
|
||||
# Fail the image build early if the runtime dependency chain is inconsistent.
|
||||
RUN python - <<'PY'
|
||||
import torch
|
||||
import torchaudio
|
||||
import transformers
|
||||
import vllm
|
||||
from transformers import PreTrainedModel
|
||||
|
||||
print("torch", torch.__version__)
|
||||
print("torchaudio", torchaudio.__version__)
|
||||
print("transformers", transformers.__version__)
|
||||
print("vllm", vllm.__version__)
|
||||
print("PreTrainedModel", PreTrainedModel)
|
||||
PY
|
||||
|
||||
# Clean apt cache but keep build-essential and nvcc for FlashInfer JIT compilation.
|
||||
RUN apt-get clean && rm -rf /var/lib/apt/lists/*
|
||||
|
||||
# Copy application code
|
||||
COPY . .
|
||||
|
||||
# Create runtime directories
|
||||
RUN mkdir -p /app/data/temp /app/data/logs /app/data/tasks \
|
||||
&& chmod +x start.py /app/scripts/docker/entrypoint.sh
|
||||
|
||||
EXPOSE 8000
|
||||
|
||||
ENTRYPOINT ["/app/scripts/docker/entrypoint.sh"]
|
||||
CMD ["python", "start.py"]
|
||||
|
|
@ -0,0 +1,51 @@
|
|||
ARG ILUVATAR_BASE_IMAGE=registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
FROM ${ILUVATAR_BASE_IMAGE}
|
||||
|
||||
ARG PYTHON_BIN=python3
|
||||
ARG INSTALL_SYSTEM_PACKAGES=false
|
||||
|
||||
ENV DEBIAN_FRONTEND=noninteractive \
|
||||
PYTHONUNBUFFERED=1 \
|
||||
PYTHONDONTWRITEBYTECODE=1 \
|
||||
HF_HUB_DISABLE_SYMLINKS_WARNING=1 \
|
||||
HF_HUB_DISABLE_PROGRESS_BARS=1 \
|
||||
PIP_BREAK_SYSTEM_PACKAGES=1 \
|
||||
ACCELERATOR=iluvatar \
|
||||
DEVICE=auto \
|
||||
APP_PYTHON_BIN=${PYTHON_BIN}
|
||||
|
||||
# Iluvatar production images should be built on top of the official Iluvatar
|
||||
# vLLM image. The base image owns the IX runtime, PyTorch, vLLM, and kernels;
|
||||
# this layer only adds generic project/runtime dependencies and app code.
|
||||
RUN if [ "${INSTALL_SYSTEM_PACKAGES}" = "true" ]; then \
|
||||
apt-get update && apt-get install -y --no-install-recommends \
|
||||
python3 python3-pip python3-venv ffmpeg sox libsox-dev libsndfile1 nginx \
|
||||
&& apt-get clean && rm -rf /var/lib/apt/lists/*; \
|
||||
fi
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
COPY environments/iluvatar/requirements.txt /tmp/qwen3-asr-iluvatar-requirements.txt
|
||||
RUN ${APP_PYTHON_BIN} -m pip install --no-cache-dir -r /tmp/qwen3-asr-iluvatar-requirements.txt && \
|
||||
rm -f /tmp/qwen3-asr-iluvatar-requirements.txt
|
||||
|
||||
RUN ${APP_PYTHON_BIN} - <<'PY'
|
||||
import importlib
|
||||
import torch
|
||||
|
||||
print("torch", torch.__version__)
|
||||
print("torch.cuda.is_available", torch.cuda.is_available())
|
||||
for name in ("vllm",):
|
||||
module = importlib.import_module(name)
|
||||
print(name, getattr(module, "__version__", "unknown"))
|
||||
PY
|
||||
|
||||
COPY . .
|
||||
|
||||
RUN mkdir -p /app/data/temp /app/data/logs /app/data/tasks \
|
||||
&& chmod +x start.py /app/scripts/docker/entrypoint.sh
|
||||
|
||||
EXPOSE 8000
|
||||
|
||||
ENTRYPOINT ["/app/scripts/docker/entrypoint.sh"]
|
||||
CMD ["python3", "start.py"]
|
||||
|
|
@ -0,0 +1,55 @@
|
|||
ARG METAX_BASE_IMAGE
|
||||
FROM ${METAX_BASE_IMAGE}
|
||||
|
||||
ARG PYTHON_BIN=/opt/conda/bin/python
|
||||
ARG INSTALL_SYSTEM_PACKAGES=true
|
||||
|
||||
ENV DEBIAN_FRONTEND=noninteractive \
|
||||
PYTHONUNBUFFERED=1 \
|
||||
PYTHONDONTWRITEBYTECODE=1 \
|
||||
HF_HUB_DISABLE_SYMLINKS_WARNING=1 \
|
||||
HF_HUB_DISABLE_PROGRESS_BARS=1 \
|
||||
PIP_BREAK_SYSTEM_PACKAGES=1 \
|
||||
ACCELERATOR=metax \
|
||||
DEVICE=auto \
|
||||
APP_PYTHON_BIN=${PYTHON_BIN}
|
||||
|
||||
# MetaX production images should be built on top of an official MetaX vLLM
|
||||
# image that already contains MACA, PyTorch, vLLM, and their compiled kernels.
|
||||
# We only add generic project/runtime dependencies and the application code.
|
||||
RUN if [ "${INSTALL_SYSTEM_PACKAGES}" = "true" ]; then \
|
||||
apt-get update && apt-get install -y --no-install-recommends \
|
||||
python3 python3-pip python3-venv ffmpeg sox libsox-dev libsndfile1 nginx \
|
||||
&& apt-get clean && rm -rf /var/lib/apt/lists/*; \
|
||||
fi
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
COPY environments/metax/requirements.txt /tmp/qwen3-asr-metax-requirements.txt
|
||||
RUN ${APP_PYTHON_BIN} -m pip install \
|
||||
--no-cache-dir \
|
||||
--no-warn-conflicts \
|
||||
--root-user-action=ignore \
|
||||
-r /tmp/qwen3-asr-metax-requirements.txt && \
|
||||
rm -f /tmp/qwen3-asr-metax-requirements.txt
|
||||
|
||||
RUN ${APP_PYTHON_BIN} - <<'PY'
|
||||
import importlib
|
||||
import torch
|
||||
|
||||
print("torch", torch.__version__)
|
||||
print("torch.cuda.is_available", torch.cuda.is_available())
|
||||
for name in ("vllm",):
|
||||
module = importlib.import_module(name)
|
||||
print(name, getattr(module, "__version__", "unknown"))
|
||||
PY
|
||||
|
||||
COPY . .
|
||||
|
||||
RUN mkdir -p /app/data/temp /app/data/logs /app/data/tasks \
|
||||
&& chmod +x start.py /app/scripts/docker/entrypoint.sh
|
||||
|
||||
EXPOSE 8000
|
||||
|
||||
ENTRYPOINT ["/app/scripts/docker/entrypoint.sh"]
|
||||
CMD ["/opt/conda/bin/python", "start.py"]
|
||||
|
|
@ -0,0 +1,40 @@
|
|||
ARG MTHREADS_BASE_IMAGE=registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519
|
||||
FROM ${MTHREADS_BASE_IMAGE}
|
||||
|
||||
ARG PYTHON_BIN=python3
|
||||
ARG INSTALL_SYSTEM_PACKAGES=true
|
||||
|
||||
ENV DEBIAN_FRONTEND=noninteractive \
|
||||
PYTHONUNBUFFERED=1 \
|
||||
PYTHONDONTWRITEBYTECODE=1 \
|
||||
HF_HUB_DISABLE_SYMLINKS_WARNING=1 \
|
||||
HF_HUB_DISABLE_PROGRESS_BARS=1 \
|
||||
PIP_BREAK_SYSTEM_PACKAGES=1 \
|
||||
ACCELERATOR=mthreads \
|
||||
DEVICE=auto \
|
||||
APP_PYTHON_BIN=${PYTHON_BIN}
|
||||
|
||||
# Moore Threads production images should be built on top of the official MUSA
|
||||
# vLLM image. Keep the vendor Python/runtime stack intact and only add the
|
||||
# extra system tools needed by the application.
|
||||
RUN if [ "${INSTALL_SYSTEM_PACKAGES}" = "true" ]; then \
|
||||
apt-get update && apt-get install -y --no-install-recommends \
|
||||
ffmpeg sox libsox-dev libsndfile1 nginx \
|
||||
&& apt-get clean && rm -rf /var/lib/apt/lists/*; \
|
||||
fi
|
||||
|
||||
WORKDIR /app
|
||||
|
||||
COPY environments/mthreads/requirements.txt /tmp/qwen3-asr-mthreads-requirements.txt
|
||||
RUN ${APP_PYTHON_BIN} -m pip install --no-cache-dir -r /tmp/qwen3-asr-mthreads-requirements.txt && \
|
||||
rm -f /tmp/qwen3-asr-mthreads-requirements.txt
|
||||
|
||||
COPY . .
|
||||
|
||||
RUN mkdir -p /app/data/temp /app/data/logs /app/data/tasks \
|
||||
&& chmod +x start.py /app/scripts/docker/entrypoint.sh
|
||||
|
||||
EXPOSE 8000
|
||||
|
||||
ENTRYPOINT ["/app/scripts/docker/entrypoint.sh"]
|
||||
CMD ["python3", "start.py"]
|
||||
|
|
@ -0,0 +1,610 @@
|
|||
<div align="center">
|
||||
|
||||
<h1>Qwen3-ASR</h1>
|
||||
<h3>Ready-to-use Local Speech Recognition API Service</h3>
|
||||
|
||||
Speech recognition API service centered on [Qwen3-ASR](https://github.com/QwenLM/Qwen3-ASR), with NVIDIA CUDA vLLM, MetaX/MuXi MACA vLLM, and CPU Rust backends, OpenAI API compatibility, Alibaba Cloud Speech API compatibility, and a Paraformer realtime websocket capability.
|
||||
|
||||
[简体中文](./docs/README_zh.md)
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
</div>
|
||||
|
||||
## Live Demo Site
|
||||
|
||||
- **Web Demo**: https://asr.vect.one
|
||||
|
||||
## Demo
|
||||
|
||||
[](https://media.cdn.vect.one/qwenasr_client_demo.mp4)
|
||||
|
||||
## Release 1.0.1
|
||||
|
||||
> `v1.0.1` is the current patch release. `v1.0.0` introduced a large breaking refactor relative to the earlier `main` branch.
|
||||
> If you are upgrading from `main`, read the release notes before reusing old deployment assumptions.
|
||||
>
|
||||
> Key breaking changes:
|
||||
> - Python dependency management is now `uv`-based (`pyproject.toml` + `uv.lock`); `requirements*.txt` are gone
|
||||
> - Runtime stack changed to `NVIDIA/MetaX GPU -> vLLM`, `CPU/macOS -> vendored QwenASR Rust`
|
||||
> - `MLX` / Apple Silicon GPU path has been removed; `mps` is normalized to `cpu`
|
||||
> - macOS / Apple Silicon now defaults to `qwen3-asr-0.6b`; set `QWEN3_ASR_MODEL` to override it
|
||||
> - `ENABLED_MODELS` has been removed
|
||||
|
||||
## Features
|
||||
|
||||
- **Hybrid Runtime Stack** - Uses auto-selected Qwen3-ASR for offline inference and Paraformer realtime for websocket streaming
|
||||
- **Speaker Diarization** - Automatic multi-speaker identification using CAM++ model
|
||||
- **OpenAI API Compatible** - Supports `/v1/audio/transcriptions` endpoint, works with OpenAI SDK
|
||||
- **Alibaba Cloud API Compatible** - Supports Alibaba Cloud Speech RESTful API and WebSocket streaming protocol
|
||||
- **WebSocket Streaming** - Real-time streaming speech recognition with low latency
|
||||
- **Smart Far-Field Filtering** - Automatically filters far-field sounds and ambient noise in streaming ASR
|
||||
- **Intelligent Audio Segmentation** - VAD-based greedy merge algorithm for automatic long audio splitting
|
||||
- **GPU Batch Processing** - Batch inference support, 2-3x faster than sequential processing
|
||||
- **Resource-Aware Runtime** - Auto-selects the appropriate Qwen3-ASR model for the current machine
|
||||
|
||||
## Acknowledgements
|
||||
|
||||
- [Qwen3-ASR](https://github.com/QwenLM/Qwen3-ASR) provides the official model family and multimodal/vLLM usage guidance
|
||||
- [QwenASR](https://github.com/huanglizhuo/QwenASR) provides the CPU Rust backend vendored by this project
|
||||
|
||||
## Quick Deployment
|
||||
|
||||
### 1. Docker Deployment (Recommended)
|
||||
|
||||
```bash
|
||||
# Copy and edit configuration
|
||||
cp .env.example .env
|
||||
# Edit .env to set API_KEY (optional)
|
||||
|
||||
# Compose defaults:
|
||||
# /opt/dep/asr/models -> /app/models
|
||||
# /opt/dep/asr/data -> /app/data
|
||||
# /opt/dep/asr/data/logs, temp, tasks live under this data mount
|
||||
# Optional: override any host mount root in .env
|
||||
# export MODEL_STORAGE_DIR=/data/qwen3-asr-models
|
||||
# export DATA_STORAGE_DIR=/data/qwen3-asr-data
|
||||
|
||||
# Start service (NVIDIA GPU version)
|
||||
docker-compose up -d
|
||||
|
||||
# Or MetaX/MuXi GPU version
|
||||
docker-compose -f docker-compose-metax.yml up -d
|
||||
|
||||
# Or Iluvatar/Tianshu GPU version
|
||||
docker-compose -f docker-compose-iluvatar.yml up -d
|
||||
|
||||
# Or Moore Threads / MUSA GPU version
|
||||
docker-compose -f docker-compose-mthreads.yml up -d
|
||||
|
||||
# Or CPU version
|
||||
docker-compose -f docker-compose-cpu.yml up -d
|
||||
|
||||
# NVIDIA multi-GPU auto mode (one instance per visible GPU)
|
||||
CUDA_VISIBLE_DEVICES=0,1,2,3 docker-compose up -d
|
||||
|
||||
# MetaX/MuXi multi-GPU auto mode
|
||||
METAX_VISIBLE_DEVICES=0,1 docker-compose -f docker-compose-metax.yml up -d
|
||||
|
||||
# Iluvatar/Tianshu multi-GPU auto mode
|
||||
ILUVATAR_VISIBLE_DEVICES=0,1 docker-compose -f docker-compose-iluvatar.yml up -d
|
||||
|
||||
# Moore Threads / MUSA multi-GPU auto mode
|
||||
MTHREADS_VISIBLE_DEVICES=0,1 docker-compose -f docker-compose-mthreads.yml up -d
|
||||
```
|
||||
|
||||
Service URLs:
|
||||
- **API Endpoint**: `http://localhost:17003`
|
||||
- **API Docs**: `http://localhost:17003/docs`
|
||||
|
||||
Optional built-in rate limit settings:
|
||||
- `NGINX_RATE_LIMIT_RPS` (global requests/sec, `0` = disabled)
|
||||
- `NGINX_RATE_LIMIT_BURST` (global burst, `0` = auto use RPS)
|
||||
|
||||
**docker run (alternative):**
|
||||
|
||||
```bash
|
||||
# NVIDIA GPU version
|
||||
docker run -d --name qwen3-asr \
|
||||
--gpus all \
|
||||
-p 17003:8000 \
|
||||
-e ACCELERATOR=nvidia \
|
||||
-e CUDA_VISIBLE_DEVICES=0,1,2,3 \
|
||||
-e API_KEY=your_api_key \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
unis/qwen3-asr:gpu-latest
|
||||
|
||||
# MetaX/MuXi GPU version
|
||||
docker run -d --name qwen3-asr-metax \
|
||||
--privileged \
|
||||
--network=host \
|
||||
--pid=host \
|
||||
--ipc=host \
|
||||
-v /dev:/dev \
|
||||
-v /opt/mxdriver:/opt/mxdriver:ro \
|
||||
-e ACCELERATOR=metax \
|
||||
-e PORT=17003 \
|
||||
-e METAX_VISIBLE_DEVICES=0 \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
unis/qwen3-asr:metax-latest
|
||||
|
||||
# CPU version
|
||||
docker run -d --name qwen3-asr \
|
||||
-p 17003:8000 \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
unis/qwen3-asr:cpu-latest
|
||||
```
|
||||
|
||||
> **Note**: NVIDIA GPU images default to CUDA 13.0/cu130 with `torch 2.11.0` + `vllm 0.20.0`.
|
||||
> Developers can rebuild `Dockerfile.gpu` for CUDA 12.6, CUDA 13.0, or another backend by overriding Docker build args.
|
||||
> MetaX/MuXi images use `Dockerfile.metax` on top of an official MetaX vLLM image. In field deployments, use host networking plus privileged `/dev` and `/opt/mxdriver` mounts so both `mx-smi` and the MetaX PyTorch runtime can initialize devices.
|
||||
> CPU images now support `qwen3-asr-0.6b` via the bundled QwenASR Rust backend. The default CPU image uses a portable Rust target; set `QWENASR_RUST_TARGET_CPU=native` only for self-built, host-specific images.
|
||||
> On CUDA vLLM and CPU Rust, `word_timestamps=true` now triggers the forced aligner automatically.
|
||||
> On macOS / Apple Silicon, Qwen3-ASR now runs through the Rust CPU backend.
|
||||
> `start.py` now forces the vLLM multiprocessing method to `spawn` so startup does not hit CUDA re-initialization failures in forked subprocesses.
|
||||
|
||||
**Custom GPU backend builds:**
|
||||
|
||||
```bash
|
||||
# Default GPU build: CUDA 13.0 / PyTorch cu130
|
||||
docker build -t qwen3-asr:gpu-cu130 -f Dockerfile.gpu .
|
||||
|
||||
# CUDA 12.6 build for older deployments
|
||||
docker build -t qwen3-asr:gpu-cu126 -f Dockerfile.gpu \
|
||||
--build-arg PYTORCH_BASE_IMAGE=pytorch/pytorch:2.11.0-cuda12.6-cudnn9-runtime \
|
||||
--build-arg PYTORCH_CUDA_INDEX=https://download.pytorch.org/whl/cu126 \
|
||||
--build-arg CUDA_NVCC_PACKAGE=cuda-nvcc-12-6 \
|
||||
--build-arg TORCH_CUDA_ARCH_LIST="8.0;8.6;8.9" \
|
||||
.
|
||||
|
||||
# CUDA 13.0 build when your driver/toolchain requires it
|
||||
docker build -t qwen3-asr:gpu-cu130 -f Dockerfile.gpu \
|
||||
--build-arg PYTORCH_BASE_IMAGE=pytorch/pytorch:2.11.0-cuda13.0-cudnn9-runtime \
|
||||
--build-arg PYTORCH_CUDA_INDEX=https://download.pytorch.org/whl/cu130 \
|
||||
--build-arg CUDA_NVCC_PACKAGE=cuda-nvcc-13-0 \
|
||||
--build-arg TORCH_CUDA_ARCH_LIST="12.0+PTX" \
|
||||
.
|
||||
|
||||
# MetaX/MuXi build: fuse this project into an official MetaX vLLM image
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor metax \
|
||||
--base-image <official-metax-vllm-image> \
|
||||
-v n260-3.7.0.38
|
||||
|
||||
# Iluvatar/Tianshu build: fuse this project into the official Iluvatar vLLM image
|
||||
docker pull registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor iluvatar \
|
||||
--base-image registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5 \
|
||||
-v vllm0.17.0-4.4.0-v5
|
||||
|
||||
# Moore Threads / MUSA build: fuse this project into the official MUSA vLLM image
|
||||
docker pull registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor mthreads \
|
||||
--base-image registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519 \
|
||||
-v s4000_4.3.5_d0519
|
||||
```
|
||||
|
||||
For MetaX/MuXi offline delivery, see [docs/metax_offline_deployment.md](docs/metax_offline_deployment.md).
|
||||
For Iluvatar/Tianshu offline delivery, see [docs/iluvatar_offline_deployment.md](docs/iluvatar_offline_deployment.md).
|
||||
For Moore Threads / MUSA offline delivery, see [docs/mthreads_offline_deployment.md](docs/mthreads_offline_deployment.md).
|
||||
|
||||
**Offline Deployment**: You can now build a timestamped offline delivery folder that includes the image archive, compose file, env template, host-dir init script, and usage docs. The export script uses plain `docker build` + `docker save`, so it does not depend on `buildx`:
|
||||
|
||||
```bash
|
||||
# 1. Build an offline delivery folder
|
||||
./export_offline_bundle.sh --type gpu
|
||||
# or
|
||||
./export_offline_bundle.sh --type cpu
|
||||
# or MetaX/MuXi GPU
|
||||
./export_offline_bundle.sh \
|
||||
--type metax \
|
||||
--metax-base cr.metax-tech.com/public-ai-release/maca/vllm-metax:0.17.0-maca.ai3.5.3.307-torch2.8-py312-ubuntu22.04-amd64 \
|
||||
--skip-models
|
||||
# or Iluvatar/Tianshu GPU
|
||||
./export_offline_bundle.sh --type iluvatar --iluvatar-base registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
# or Moore Threads / MUSA GPU
|
||||
./export_offline_bundle.sh --type mthreads --mthreads-base registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519
|
||||
# or build both in one bundle
|
||||
./export_offline_bundle.sh --type all
|
||||
|
||||
# 2. Prepare models separately, without deleting existing model files
|
||||
./scripts/download-models.sh --models-dir /opt/dep/asr/models
|
||||
|
||||
# 3. Copy the generated folder to the offline server
|
||||
scp -r build-file/<timestamp>-all user@server:/opt/dep/asr/
|
||||
|
||||
# 4. On the offline server
|
||||
cd /opt/dep/asr/<timestamp>-all
|
||||
./init_host_dirs.sh
|
||||
gunzip -c qwen3-asr-gpu-<timestamp>-amd64.tar.gz | docker load
|
||||
gunzip -c qwen3-asr-cpu-<timestamp>-amd64.tar.gz | docker load
|
||||
# NVIDIA GPU
|
||||
docker compose up -d
|
||||
# or MetaX/MuXi GPU
|
||||
# docker compose -f docker-compose-metax.yml up -d
|
||||
# or Iluvatar/Tianshu GPU
|
||||
# docker compose -f docker-compose-iluvatar.yml up -d
|
||||
# or Moore Threads / MUSA GPU
|
||||
# docker compose -f docker-compose-mthreads.yml up -d
|
||||
# or CPU
|
||||
# docker compose -f docker-compose-cpu.yml up -d
|
||||
```
|
||||
|
||||
> Detailed deployment instructions: [Deployment Guide](./docs/deployment.md)
|
||||
|
||||
### Local Development
|
||||
|
||||
**System Requirements:**
|
||||
|
||||
- Python 3.10+
|
||||
- CUDA 13.0+ for the default GPU image; CUDA 12.6 / 13.0 can be built with Docker args
|
||||
- FFmpeg (audio format conversion)
|
||||
|
||||
**Installation:**
|
||||
|
||||
Runtime dependency locks now default to the GPU stack at the repo root, with CPU kept as a specialized environment:
|
||||
|
||||
| Mode | Command | Notes |
|
||||
|------|---------|-------|
|
||||
| NVIDIA GPU (default) | `uv sync` or `./scripts/sync_gpu_env.sh` | Syncs the root [pyproject.toml](/opt/qwen3-asr/pyproject.toml) and [uv.lock](/opt/qwen3-asr/uv.lock) into `.venv`, including CUDA 13.0/cu130 `torch 2.11.0` / `torchaudio 2.11.0` / `torchvision 0.26.0` / `vllm 0.20.0` |
|
||||
| MetaX/MuXi GPU | `./scripts/sync_metax_env.sh` | Syncs common dependencies from [environments/metax/pyproject.toml](/opt/qwen3-asr/environments/metax/pyproject.toml); optional GPU-stack install uses the MetaX MACA PyPI index with `--no-deps` by default |
|
||||
| Iluvatar/Tianshu GPU | `./scripts/sync_iluvatar_env.sh` | Syncs common dependencies from [environments/iluvatar/pyproject.toml](/opt/qwen3-asr/environments/iluvatar/pyproject.toml); GPU stack should come from the official Iluvatar vLLM image |
|
||||
| Moore Threads / MUSA GPU | `./scripts/sync_mthreads_env.sh` | Syncs common dependencies from [environments/mthreads/pyproject.toml](/opt/qwen3-asr/environments/mthreads/pyproject.toml); GPU stack should come from the official Moore Threads MUSA vLLM image |
|
||||
| CPU (specialized) | `./scripts/sync_cpu_env.sh` | Syncs the dedicated CPU lock in [environments/cpu/pyproject.toml](/opt/qwen3-asr/environments/cpu/pyproject.toml) into `.venv` |
|
||||
| Auto | `./scripts/sync_accel_env.sh` | Chooses MetaX when `mx-smi` is present, Iluvatar when `ixsmi` is present, Moore Threads when `mthreads-gmi` is present, otherwise NVIDIA when `nvidia-smi` is present, otherwise CPU |
|
||||
|
||||
```bash
|
||||
# Clone project
|
||||
cd qwen3-asr
|
||||
|
||||
# Install dependencies (Linux/NVIDIA CUDA)
|
||||
uv sync
|
||||
|
||||
# Start service
|
||||
source .venv/bin/activate
|
||||
python start.py
|
||||
```
|
||||
|
||||
MetaX/MuXi local development:
|
||||
|
||||
```bash
|
||||
./scripts/sync_metax_env.sh
|
||||
source .venv/bin/activate
|
||||
ACCELERATOR=metax python start.py
|
||||
```
|
||||
|
||||
Local model storage defaults to `./models` under the project root:
|
||||
|
||||
```text
|
||||
./models/
|
||||
Qwen/
|
||||
iic/
|
||||
damo/
|
||||
```
|
||||
|
||||
Override it when needed:
|
||||
|
||||
```bash
|
||||
export MODELS_DIR=/data/qwen3-asr-models
|
||||
export MODELSCOPE_CACHE=/data
|
||||
export MODELSCOPE_PATH=$MODELS_DIR
|
||||
```
|
||||
|
||||
macOS / Apple Silicon local development:
|
||||
|
||||
```bash
|
||||
./scripts/sync_cpu_env.sh
|
||||
source .venv/bin/activate
|
||||
python start.py
|
||||
```
|
||||
|
||||
## Runtime Defaults
|
||||
|
||||
Current runtime behavior on the mainline codebase:
|
||||
|
||||
- `ACCELERATOR=auto` resolves to `metax` when `mx-smi` reports devices, then `iluvatar` when `ixsmi` reports devices, then `mthreads` when `mthreads-gmi` reports devices, otherwise `nvidia` when NVIDIA CUDA is available, otherwise `cpu`
|
||||
- `DEVICE=auto` resolves to the active accelerator device (`cuda:0` for NVIDIA/MetaX/Iluvatar GPU, otherwise `cpu`)
|
||||
- `DEVICE=mps` is normalized to `cpu`
|
||||
- `Linux + NVIDIA CUDA` uses official `vLLM`
|
||||
- `Linux + MetaX/MuXi MACA` uses the MetaX-compatible PyTorch/vLLM stack
|
||||
- `Linux + Iluvatar/Tianshu` uses the Iluvatar official vLLM image stack
|
||||
- `Linux + CPU` uses vendored `QwenASR` Rust
|
||||
- `macOS / Apple Silicon` also uses vendored `QwenASR` Rust
|
||||
- macOS / Apple Silicon defaults to `qwen3-asr-0.6b`
|
||||
- `qwen3-asr-1.7b` on macOS is only used when `QWEN3_ASR_MODEL=qwen3-asr-1.7b`
|
||||
- `word_timestamps=true` works on the current offline CUDA and CPU Rust paths
|
||||
- WebSocket streaming does not currently return word-level timestamps
|
||||
- CAM++ speaker diarization remains required and still follows `DEVICE`; on CPU its main hotspot is speaker verification embedding
|
||||
|
||||
## API Endpoints
|
||||
|
||||
### OpenAI Compatible API
|
||||
|
||||
| Endpoint | Method | Function |
|
||||
|----------|--------|----------|
|
||||
| `/v1/audio/transcriptions` | POST | Audio transcription (OpenAI compatible) |
|
||||
| `/v1/models` | GET | Offline model list |
|
||||
|
||||
**Request Parameters:**
|
||||
|
||||
| Parameter | Type | Default | Description |
|
||||
|-----------|------|---------|-------------|
|
||||
| `file` | file | Preferred when provided | Audio/video file |
|
||||
| `audio_address` | string | Optional | Audio/video URL (HTTP/HTTPS), `file://`, or server-local path. Ignored when `file` is also provided |
|
||||
| `language` | string | Auto-detect | Language code (zh/en/ja) |
|
||||
| `enable_speaker_diarization` | bool | `true` | Enable speaker diarization |
|
||||
| `enable_speaker_identification` | bool | `true` | Match registered speaker database when diarization is enabled |
|
||||
| `enable_text_cleanup` | bool | `true` | Enable text deduplication, boundary-overlap trimming, and filler cleanup |
|
||||
| `word_timestamps` | bool | `false` | Return word-level timestamps when the backend supports them. Qwen CUDA vLLM and CPU Rust automatically use the forced aligner when enabled. |
|
||||
| `hotwords` | string | - | Hotwords, format: `word1 weight1 word2 weight2` |
|
||||
| `response_format` | string | `verbose_json` | Output format |
|
||||
| `prompt` | string | - | Prompt text (reserved) |
|
||||
| `temperature` | float | `0` | Sampling temperature (reserved) |
|
||||
|
||||
**Audio / Video Input Methods:**
|
||||
- **File Upload**: Use `file` parameter to upload an audio file or a video container with an audio track
|
||||
- **URL / Local Path**: Use `audio_address` parameter to provide an audio/video URL or server-local path, service will read it automatically
|
||||
- **Precedence**: If both `file` and `audio_address` are provided, the service uses `file` and ignores `audio_address`
|
||||
|
||||
**Usage Examples:**
|
||||
|
||||
```python
|
||||
# Using OpenAI SDK
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(base_url="http://localhost:8000/v1", api_key="your_api_key")
|
||||
|
||||
with open("audio.wav", "rb") as f:
|
||||
transcript = client.audio.transcriptions.create(
|
||||
file=f,
|
||||
response_format="verbose_json" # Get segments and speaker info
|
||||
)
|
||||
print(transcript.text)
|
||||
```
|
||||
|
||||
```bash
|
||||
# Using curl
|
||||
curl -X POST "http://localhost:8000/v1/audio/transcriptions" \
|
||||
-H "Authorization: Bearer your_api_key" \
|
||||
-F "file=@audio.wav" \
|
||||
-F "model=qwen3-asr-0.6b" \
|
||||
-F "response_format=verbose_json" \
|
||||
-F "enable_speaker_diarization=true" \
|
||||
-F "enable_speaker_identification=true" \
|
||||
-F "enable_text_cleanup=true" \
|
||||
-F "hotwords=Qwen 2.0 ModelScope 1.5"
|
||||
```
|
||||
|
||||
**Supported Response Formats:** `json`, `text`, `srt`, `vtt`, `verbose_json`
|
||||
|
||||
### Alibaba Cloud Compatible API
|
||||
|
||||
| Endpoint | Method | Function |
|
||||
|----------|--------|----------|
|
||||
| `/stream/v1/asr` | POST | Speech recognition (long audio support) |
|
||||
| `/stream/v1/asr/models` | GET | Declared model/capability entries |
|
||||
| `/stream/v1/asr/health` | GET | Health check |
|
||||
| `/ws/v1/asr` | WebSocket | Qwen3-ASR streaming |
|
||||
| `/ws/v1/asr/qwen` | WebSocket | Qwen3-ASR streaming (explicit path) |
|
||||
| `/ws/v1/asr/funasr` | WebSocket | Removed; returns a deprecation error and asks clients to switch to `/ws/v1/asr/qwen` |
|
||||
|
||||
**Request Parameters:**
|
||||
|
||||
| Parameter | Type | Default | Description |
|
||||
|-----------|------|---------|-------------|
|
||||
| `audio_address` | string | `https://media.cdn.vect.one/podcast_demo.mp4` (docs example) | Audio/video URL, `file://`, or server-local path (optional; ignored when body content is uploaded) |
|
||||
| `sample_rate` | int | `16000` | Sample rate |
|
||||
| `enable_speaker_diarization` | bool | `true` | Enable speaker diarization |
|
||||
| `enable_speaker_identification` | bool | `true` | Match registered speaker database when diarization is enabled |
|
||||
| `enable_text_cleanup` | bool | `true` | Enable text deduplication, boundary-overlap trimming, and filler cleanup |
|
||||
| `word_timestamps` | bool | `false` | Return word-level timestamps when the backend supports them. Qwen CUDA vLLM and CPU Rust automatically use the forced aligner when enabled. |
|
||||
| `vocabulary_id` | string | - | Hotwords (format: `word1 weight1 word2 weight2`) |
|
||||
|
||||
**Usage Examples:**
|
||||
|
||||
```bash
|
||||
# Basic usage
|
||||
curl -X POST "http://localhost:8000/stream/v1/asr" \
|
||||
-H "Content-Type: application/octet-stream" \
|
||||
--data-binary @audio.wav
|
||||
|
||||
# With parameters
|
||||
curl -X POST "http://localhost:8000/stream/v1/asr?enable_speaker_diarization=true&enable_speaker_identification=true&enable_text_cleanup=true&vocabulary_id=Qwen%202.0%20ModelScope%201.5" \
|
||||
-H "Content-Type: application/octet-stream" \
|
||||
--data-binary @audio.wav
|
||||
```
|
||||
|
||||
### Meeting Offline API
|
||||
|
||||
| Endpoint | Method | Function |
|
||||
|----------|--------|----------|
|
||||
| `/api/v1/asr/transcriptions` | POST | Create an offline meeting transcription task |
|
||||
| `/api/v1/asr/transcriptions/{task_id}` | GET | Query task status and result |
|
||||
|
||||
`audio_address` is the required production input field for this endpoint.
|
||||
|
||||
```json
|
||||
{
|
||||
"audio_address": "https://example.com/media/meeting.mp4",
|
||||
"config": {
|
||||
"enable_speaker": true,
|
||||
"match_speaker_registry": true,
|
||||
"enable_text_cleanup": true,
|
||||
"speaker_threshold": 0.6,
|
||||
"word_timestamps": false,
|
||||
"hotwords": [
|
||||
{ "hotword": "Qwen", "weight": 2.0 },
|
||||
{ "hotword": "ModelScope", "weight": 1.5 }
|
||||
]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**Response Example:**
|
||||
|
||||
```json
|
||||
{
|
||||
"task_id": "xxx",
|
||||
"status": 200,
|
||||
"message": "SUCCESS",
|
||||
"result": "Speaker1 content...\nSpeaker2 content...",
|
||||
"duration": 60.5,
|
||||
"processing_time": 1.234,
|
||||
"segments": [
|
||||
{
|
||||
"text": "Today is a nice day.",
|
||||
"start_time": 0.0,
|
||||
"end_time": 2.5,
|
||||
"speaker_id": "Speaker1",
|
||||
"word_tokens": [
|
||||
{"text": "Today", "start_time": 0.0, "end_time": 0.5},
|
||||
{"text": "is", "start_time": 0.5, "end_time": 0.7},
|
||||
{"text": "a nice day", "start_time": 0.7, "end_time": 1.5}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
## Speaker Diarization
|
||||
|
||||
Multi-speaker automatic identification based on CAM++ model:
|
||||
|
||||
- **Enabled by Default** - `enable_speaker_diarization=true`
|
||||
- **Automatic Detection** - No preset speaker count needed, model auto-detects
|
||||
- **Speaker Labels** - Response includes `speaker_id` field (e.g., "Speaker1", "Speaker2")
|
||||
- **Smart Merging** - Two-layer merge strategy to avoid isolated short segments:
|
||||
- Layer 1: Accumulate merge same-speaker segments < 10 seconds
|
||||
- Layer 2: Accumulate merge continuous segments up to 60 seconds
|
||||
- **Subtitle Support** - SRT/VTT output includes speaker labels `[Speaker1] text content`
|
||||
|
||||
Disable speaker diarization:
|
||||
|
||||
```bash
|
||||
# OpenAI API
|
||||
-F "enable_speaker_diarization=false"
|
||||
|
||||
# Alibaba Cloud API
|
||||
?enable_speaker_diarization=false
|
||||
```
|
||||
|
||||
## Audio Processing
|
||||
|
||||
### Intelligent Segmentation Strategy
|
||||
|
||||
Automatic long audio segmentation:
|
||||
|
||||
1. **VAD Voice Detection** - Detect voice boundaries, filter silence
|
||||
2. **Greedy Merge** - Accumulate voice segments, ensure each segment does not exceed `MAX_SEGMENT_SEC` (default 60s)
|
||||
3. **Silence Split** - Force split when silence between voice segments exceeds 3 seconds
|
||||
4. **Batch Inference** - Multi-segment parallel processing, 2-3x performance improvement in GPU mode
|
||||
|
||||
### WebSocket Streaming Limitations
|
||||
|
||||
**Qwen3-ASR Streaming** (using `/ws/v1/asr` or `/ws/v1/asr/qwen`):
|
||||
- ✅ Multi-language real-time recognition
|
||||
- ✅ CUDA vLLM and CPU Rust both support the current streaming path
|
||||
- ❌ Word-level timestamps are not available in the current streaming path
|
||||
|
||||
### Qwen3 Runtime Matrix
|
||||
|
||||
| Runtime | Backend | Offline | WebSocket Streaming | Word Timestamps Offline | Word Timestamps Streaming | Maturity |
|
||||
|---------|---------|---------|---------------------|-------------------------|---------------------------|----------|
|
||||
| Linux + NVIDIA GPU | Official vLLM 0.20.0 | ✅ | ✅ | ✅ | ❌ | Production-oriented |
|
||||
| CPU / macOS | QwenASR Rust | ✅ | ✅ | ✅ (forced aligner) | ❌ | Recommended local fallback |
|
||||
|
||||
## Offline-Capable Models
|
||||
|
||||
| Model ID | Name | Description | Features |
|
||||
|----------|------|-------------|----------|
|
||||
| `qwen3-asr-1.7b` | Qwen3-ASR 1.7B | High-performance multilingual ASR, 52 languages + dialects; CUDA uses vLLM | Offline/Realtime |
|
||||
| `qwen3-asr-0.6b` | Qwen3-ASR 0.6B | Lightweight multilingual ASR; CUDA uses vLLM, CPU/macOS uses Rust backend | Offline/Realtime |
|
||||
|
||||
**Runtime selection:**
|
||||
- **VRAM >= 32GB**: Select `qwen3-asr-1.7b`
|
||||
- **VRAM < 32GB**: Select `qwen3-asr-0.6b`
|
||||
- **No CUDA**: Select the vendored Rust-backed `qwen3-asr-0.6b`
|
||||
- **macOS / Apple Silicon**: Always default to `qwen3-asr-0.6b`, regardless of memory size
|
||||
- **Environment override**: Set `QWEN3_ASR_MODEL=qwen3-asr-1.7b` or `QWEN3_ASR_MODEL=qwen3-asr-0.6b` to bypass automatic selection
|
||||
|
||||
At startup the service checks the current runtime model plan and downloads missing models from ModelScope by default.
|
||||
|
||||
## Environment Variables
|
||||
|
||||
Recommended public settings:
|
||||
|
||||
| Variable | Default | Description |
|
||||
|----------|---------|-------------|
|
||||
| `API_KEY` | - | API authentication key (optional, unauthenticated if not set) |
|
||||
| `LOG_LEVEL` | `INFO` | Log level (DEBUG/INFO/WARNING/ERROR) |
|
||||
| `MAX_AUDIO_SIZE` | `2048` | Max audio file size (MB, supports units like 2GB) |
|
||||
| `ASR_BATCH_SIZE` | `4` | ASR batch size for long-audio segment processing |
|
||||
| `MAX_SEGMENT_SEC` | `60` | Max audio segment duration (seconds) |
|
||||
| `ASR_ENABLE_NEARFIELD_FILTER` | `true` | Enable far-field sound filtering |
|
||||
| `QWEN3_ASR_MODEL` | auto | Force `qwen3-asr-1.7b` or `qwen3-asr-0.6b` instead of VRAM-based selection |
|
||||
| `QWEN_GPU_MEMORY_UTILIZATION` | `0.9` | Upper bound for vLLM GPU memory reservation; lower it on shared GPUs, raise it when KV cache is too small |
|
||||
| `QWEN_VLLM_ENFORCE_EAGER` | `true` | Force vLLM eager execution for compatibility; set `false` to allow CUDA Graph optimization on supported NVIDIA deployments |
|
||||
|
||||
Far-field filter notes:
|
||||
|
||||
- `ASR_NEARFIELD_RMS_THRESHOLD=0.01` is the current default and recommended starting point
|
||||
- raise it in noisy rooms to filter more background speech
|
||||
- lower it in quiet rooms if soft speech is being dropped
|
||||
- use `LOG_LEVEL=DEBUG` temporarily when you need to inspect filter behavior
|
||||
|
||||
Advanced backend-specific settings:
|
||||
|
||||
| Variable | Default | Description |
|
||||
|----------|---------|-------------|
|
||||
| `QWEN_RUST_CPU_WORKERS` | `4` | CPU Rust backend worker count (Rust ASR / forced align default to 4 runtimes) |
|
||||
| `QWENASR_LIBRARY_PATH` | auto-detect | Override vendored Rust dylib/so path |
|
||||
|
||||
## Resource Requirements
|
||||
|
||||
**Minimum (CPU):**
|
||||
|
||||
- CPU: 4 cores
|
||||
- Memory: 16GB
|
||||
- Disk: 20GB
|
||||
|
||||
**Recommended (GPU):**
|
||||
|
||||
- CPU: 4 cores
|
||||
- Memory: 16GB
|
||||
- GPU: NVIDIA GPU (16GB+ VRAM)
|
||||
- Disk: 20GB
|
||||
|
||||
## API Documentation
|
||||
|
||||
After starting the service:
|
||||
|
||||
- Swagger UI: `http://localhost:8000/docs`
|
||||
- ReDoc: `http://localhost:8000/redoc`
|
||||
|
||||
## Links
|
||||
|
||||
- **Deployment Guide**: [Detailed Docs](./docs/deployment.md)
|
||||
- **Qwen3-ASR**: [Qwen3-ASR GitHub](https://github.com/QwenLM/Qwen3-ASR)
|
||||
- **FunASR**: [FunASR GitHub](https://github.com/alibaba-damo-academy/FunASR)
|
||||
- **Chinese README**: [中文文档](./docs/README_zh.md)
|
||||
|
||||
## License
|
||||
|
||||
This project uses the MIT License - see [LICENSE](LICENSE) file for details.
|
||||
|
||||
## Star History
|
||||
|
||||
[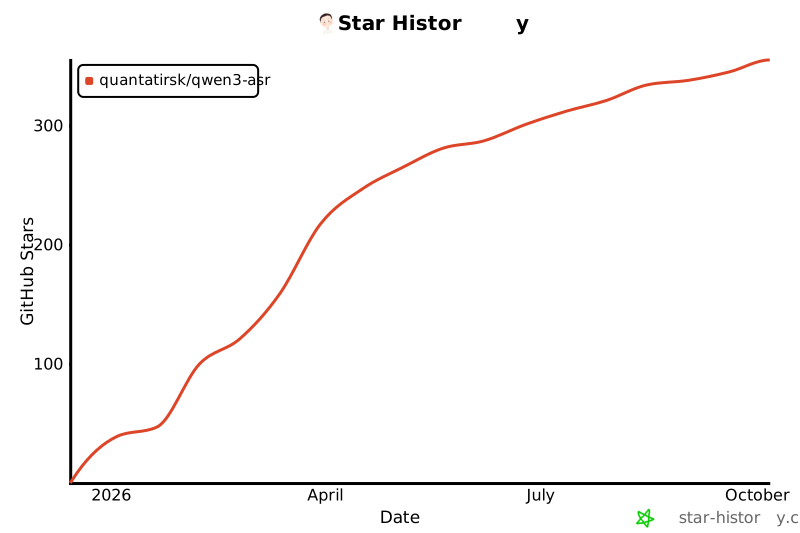](https://star-history.com/#Quantatirsk/qwen3-asr&Date)
|
||||
|
||||
## Contributing
|
||||
|
||||
Issues and Pull Requests are welcome to improve the project!
|
||||
|
|
@ -0,0 +1,310 @@
|
|||
# 实时 ASR 当前问题排查记录
|
||||
|
||||
更新时间:2026-09-07
|
||||
排查范围:实时 ASR、原生流式 partial、说话人识别、声纹姓名匹配、WebSocket 输出和前端展示。
|
||||
|
||||
## 1. 当前结论
|
||||
|
||||
目前发现的问题分布在三个层次:
|
||||
|
||||
```text
|
||||
识别层 原生 partial 默认关闭,非原生路径会反复重识别窗口
|
||||
说话人层 短片段无条件继承上一位实名,并可能把复制的 embedding 写回记录池
|
||||
输出层 内部物理切段直接作为前端展示单元,导致同一说话人被拆成多行
|
||||
```
|
||||
|
||||
其中,“不同的人进入已经确定的说话人气泡”最明确的根因是说话人层的短段快路径:小于 1.6 秒的片段在提取新特征之前直接继承上一位已命名说话人。WebSocket 本身负责传递这些结果,但错误身份是在上游状态机中产生的。
|
||||
|
||||
“同一说话人被切成几行”主要是输出层问题。silence 和 max duration 可以结束一次内部识别片段,但不应直接决定前端展示换行。
|
||||
|
||||
## 2. 当前实时 WebSocket 链路
|
||||
|
||||
入口位于 [app/api/v1/websocket_asr.py](app/api/v1/websocket_asr.py)。`/ws/v1/asr` 和 `/ws/v1/asr/qwen` 最终都进入 [Qwen3ASRService.handle_connection](app/services/qwen3_websocket_asr.py#L2538)。
|
||||
|
||||
主流程如下:
|
||||
|
||||
```text
|
||||
客户端 start
|
||||
↓
|
||||
初始化 ConnectionContext 和 streaming state
|
||||
↓
|
||||
接收二进制音频
|
||||
↓
|
||||
RMS/peak 判断是否有声音,维护 pre-roll 和当前 turn
|
||||
↓
|
||||
partial 解码并向前端发送 sentence_type=0
|
||||
↓
|
||||
silence / max_duration / sentence_limit / stop 触发内部提交
|
||||
↓
|
||||
最终重识别,创建 confirmed segment
|
||||
↓
|
||||
异步 speaker worker 处理说话人
|
||||
↓
|
||||
通过相同 sentence_id 发送 speaker update
|
||||
↓
|
||||
stop 时发送最终 sentences 和 end
|
||||
```
|
||||
|
||||
图谱分析显示 `handle_connection` 是当前实时链路的关键汇聚点;说话人解析又连接到 `RealtimeSpeakerClusterer.resolve_segment_speaker`、声纹注册服务和历史记录重聚类。因此直接修改主服务的影响范围较大,本次验证优先放在独立 demo 中。
|
||||
|
||||
## 3. 问题一:内部切段直接变成前端展示行
|
||||
|
||||
### 3.1 当前切段触发器
|
||||
|
||||
| 触发器 | 当前条件 | 当前作用 | 对展示的实际影响 |
|
||||
|---|---|---|---|
|
||||
| `silence` | 连续静音默认 `800ms` | 主力结束当前 turn | 直接产生一个 confirmed segment |
|
||||
| `max_duration` | 缓冲默认最多 `12s` | 防止单段无限增长 | 长讲话被硬切成多个 segment |
|
||||
| `sentence_limit` | 段内达到默认 `8` 句 | 兜底限制 | 可能提前提交 |
|
||||
| `complete_sentence` | 标点结尾、时长达到阈值且字数足够 | 长独讲兜底 | 正常短句通常到不了该条件 |
|
||||
| `final` | 客户端发送 `stop` | 提交最后一段 | 输出最终结果 |
|
||||
|
||||
相关逻辑位于 [qwen3_websocket_asr.py](app/services/qwen3_websocket_asr.py#L2538)、[_should_commit_complete_sentence](app/services/qwen3_websocket_asr.py#L1100) 和 [_commit_retranscribe_turn](app/services/qwen3_websocket_asr.py#L2333)。
|
||||
|
||||
### 3.2 当前输出方式
|
||||
|
||||
每次内部提交都会:
|
||||
|
||||
1. 创建一条 `confirmed_segments` 记录;
|
||||
2. 使用该记录的 `index` 作为 `sentence_id`;
|
||||
3. 立即发送 `sentence_type=1` 的 `sentences` 事件;
|
||||
4. 把所有记录用换行连接成 `full_text`。
|
||||
|
||||
代码中 `full_text` 使用 `"\\n".join(...)`,位置在 [_commit_retranscribe_turn](app/services/qwen3_websocket_asr.py#L2464) 和 [_stop](app/services/qwen3_websocket_asr.py#L2916)。因此这里的 `sentence_id` 实际上是“物理切段编号”,不一定是语义完整句子编号。
|
||||
|
||||
项目协议文档明确区分了 `sentence_type=0` 的 partial 和 `sentence_type=1` 的 final,但没有把“内部 segment”和“前端 display block”分开,见 [realtime_meeting_websocket.md](docs/realtime_meeting_websocket.md#L162)。
|
||||
|
||||
前端可以根据相同 `sentence_id` 更新原记录,但不会把不同 `sentence_id` 且说话人相同的记录合并。因此停顿、12 秒硬切和前端换行目前形成了直接关系。
|
||||
|
||||
另外,图谱显示 [_should_force_stable_segment](app/services/qwen3_websocket_asr.py#L2051) 当前没有调用方,它不能实际改变实时切段;`complete_sentence` 主要是长段兜底。
|
||||
|
||||
## 4. 问题二:原生流式 partial 与输出合并不是同一层
|
||||
|
||||
当前配置中 `REALTIME_STREAM_CHUNK_SEC` 默认约为 `1.2s`,`REALTIME_PARTIAL_WINDOW_SEC` 默认约为 `8s`,原生 partial 开关默认关闭,相关默认值在 [app/core/config.py](app/core/config.py#L103)。
|
||||
|
||||
非原生路径会维护窗口并调用 `_transcribe_audio_text` 重识别;原生路径则通过:
|
||||
|
||||
```text
|
||||
create_stream → push_stream/feed_stream → finish_stream
|
||||
```
|
||||
|
||||
对应 [qwen3_engine.py](app/services/asr/qwen3_engine.py#L570) 和 [qwen3_websocket_asr.py](app/services/qwen3_websocket_asr.py#L1162)。
|
||||
|
||||
原生 partial 影响的是:
|
||||
|
||||
- partial 首次出现的延迟;
|
||||
- 每次增量识别的计算量;
|
||||
- 流式状态维护方式;
|
||||
- 文本回滚和未固定 token 的处理。
|
||||
|
||||
它不应决定:
|
||||
|
||||
- 是否因为停顿产生前端新行;
|
||||
- 哪些物理 segment 合并成一个说话人气泡;
|
||||
- 是否把某个 speaker 姓名写入展示结果。
|
||||
|
||||
所以两个优化需要同时做,但必须保持两个独立状态:ASR streaming state 和 display aggregation state。
|
||||
|
||||
## 5. 问题三:短音频无条件继承实名
|
||||
|
||||
### 5.1 已确认的代码路径
|
||||
|
||||
在 [realtime_speaker_clusterer.py](app/services/realtime_speaker_clusterer.py#L27) 中,`_FAST_ATTACH_MAX_SEC = 1.6`。
|
||||
|
||||
`resolve_segment_speaker` 的入口逻辑是:
|
||||
|
||||
```text
|
||||
duration_sec < 1.6s
|
||||
且 speaker_records 非空
|
||||
且上一条记录存在实名身份
|
||||
↓
|
||||
直接复制上一条记录的 speaker_id / speaker_name / user_id / registry_speaker_id
|
||||
speaker_confidence = 0.0
|
||||
speaker_strategy = "short_attach"
|
||||
```
|
||||
|
||||
该分支在 [realtime_speaker_clusterer.py](app/services/realtime_speaker_clusterer.py#L505),早于 `extract_chunk_embeddings`。因此短段没有经过新的声纹特征验证。
|
||||
|
||||
### 5.2 为什么实名会直接通过稳定性判断
|
||||
|
||||
[_is_stable_speaker_info](app/services/qwen3_websocket_asr.py#L613) 首先检查 `registry_speaker_id` 或 `user_id`。短段继承时这两个字段被完整复制,所以即使 `speaker_confidence=0.0`,仍会被判断为 stable。
|
||||
|
||||
随后 [_resolve_segment_speaker](app/services/qwen3_websocket_asr.py#L2156) 会把该身份写入最终 segment,并由 [_emit_speaker_update](app/services/qwen3_websocket_asr.py#L498) 通过相同 `sentence_id` 推送给客户端。
|
||||
|
||||
这解释了为什么匿名 `SpeakerNN` 的继承可能被拦截,而带 `user_id` 或注册声纹 ID 的实名继承可以直接进入前端。
|
||||
|
||||
### 5.3 为什么短段是高风险场景
|
||||
|
||||
“嗯”“对”“好的”“可以”等短插话通常不到 1.6 秒,恰好是多人会议中最容易发生换人的场景。当前快路径把上一位实名当作新片段身份,产生的结果就是:新说话人的短句进入上一位实名气泡。
|
||||
|
||||
## 6. 问题四:特征提取失败分支与实际路径
|
||||
|
||||
代码中确实存在 `embedding_attach` 分支:特征提取后如果 `current_chunks` 为空,则尝试继承上一位实名,位置在 [realtime_speaker_clusterer.py](app/services/realtime_speaker_clusterer.py#L521)。
|
||||
|
||||
但当前 `extract_chunk_embeddings` 在没有 chunk 时会回退为整段单 chunk,因此正常情况下很难返回空列表;如果模型真正抛异常,异常会向上传递,最终由 [_resolve_and_emit_segment_speaker](app/services/qwen3_websocket_asr.py#L2220) 捕获,当前片段保持 pending。
|
||||
|
||||
准确结论是:
|
||||
|
||||
- 模型抛异常:当前片段通常保持 `speaker_id=-1`,不会走继承;
|
||||
- chunk 为空:代码意图是继承实名,但该分支近乎不可达;
|
||||
- 模型不抛异常但产生垃圾 embedding:仍需单独检查零向量、NaN 和相似度边界;
|
||||
- 当前最确定、最直接的错误来源是 `<1.6s` 的 `short_attach`。
|
||||
|
||||
## 7. 问题五:继承 embedding 造成污染链
|
||||
|
||||
短段继承返回时还会复制上一条记录的 `_embedding`、`_chunk_embeddings` 和 `_chunks`。下游 [_record_segment_speaker](app/services/qwen3_websocket_asr.py#L644) 只要发现 `_embedding` 非空,就会把它作为正常 speaker record 保存。
|
||||
|
||||
污染链如下:
|
||||
|
||||
```text
|
||||
上一位实名离场
|
||||
↓
|
||||
新人的短段直接复制实名和 embedding
|
||||
↓
|
||||
复制结果成为新的 last_record
|
||||
↓
|
||||
后续短段继续继承这条记录
|
||||
↓
|
||||
历史匹配池重复出现同一个 embedding
|
||||
↓
|
||||
相似度、聚类中心和重聚类结果被污染
|
||||
```
|
||||
|
||||
影响包括:
|
||||
|
||||
1. 继承链持续延长,错误实名被不断续写;
|
||||
2. 历史 embedding 被重复计数,匹配置信度可能虚高;
|
||||
3. `cluster_records_with_ranges` 会把复制的 chunk 作为真实样本参与聚类;
|
||||
4. 后续重聚类可能把错误身份回写到更多 segment。
|
||||
|
||||
## 8. 问题六:speaker update 是异步的
|
||||
|
||||
实时最终段先写入 `confirmed_segments`,speaker worker 再异步处理,处理完成后通过相同 `sentence_id` 发送更新,相关位置是 [_speaker_worker_loop](app/services/qwen3_websocket_asr.py#L442) 和 [_emit_speaker_update](app/services/qwen3_websocket_asr.py#L498)。
|
||||
|
||||
当前协议允许首次 final 没有姓名,后续再补姓名,这一点在 [realtime_meeting_websocket.md](docs/realtime_meeting_websocket.md#L240) 有说明。
|
||||
|
||||
这里有两个风险:
|
||||
|
||||
- 前端如果把每次事件当成追加消息,会出现重复行;
|
||||
- 上游异步继承结果如果带着错误实名,前端的幂等更新会把错误身份稳定显示出来。
|
||||
|
||||
因此上层 WebSocket 需要维护 segment 状态表,按 `sentence_id` 覆盖更新,然后根据完整状态重新生成 display block 快照。
|
||||
|
||||
## 9. 需要同时实施的两层优化
|
||||
|
||||
### 9.1 识别层:原生流式 partial
|
||||
|
||||
目标是让同一轮语音持续使用一个 streaming state,通过增量音频推进识别,减少窗口重复重识别。
|
||||
|
||||
demo 应透传并记录:
|
||||
|
||||
- `enable_native_partial_stream`;
|
||||
- partial 产生时间;
|
||||
- 每次 partial 的文本长度和修订次数;
|
||||
- 首次 partial 延迟;
|
||||
- final 延迟;
|
||||
- 原服务返回的 chunk 或 segment 时间范围。
|
||||
|
||||
### 9.2 说话人与输出层
|
||||
|
||||
目标是把“身份确认”和“展示合并”分开:
|
||||
|
||||
1. `<1.6s` 片段不继承上一位实名;
|
||||
2. 没有新鲜声纹证据时保持 pending;
|
||||
3. 特征提取异常时保持 pending;
|
||||
4. 不复制上一条记录的 embedding;
|
||||
5. 只有达到确认阈值的独立特征才能更新身份缓存;
|
||||
6. 同一 `sentence_id` 的更新覆盖原片段;
|
||||
7. 相邻且身份可信度一致的物理 segment 才合并为 display block;
|
||||
8. A→B→A 保留时间顺序,不把非相邻发言重新拼接到一起;
|
||||
9. 前端展示使用 display block,入库和诊断仍保留 raw segment。
|
||||
|
||||
推荐的状态关系是:
|
||||
|
||||
```text
|
||||
raw segment
|
||||
├─ ASR text state:partial / final
|
||||
├─ speaker evidence:pending / fresh / confirmed
|
||||
├─ speaker identity:cluster / registry / user
|
||||
└─ display block:按时间和可信身份重新生成
|
||||
```
|
||||
|
||||
## 10. 服务器接口边界
|
||||
|
||||
已验证服务器 `10.100.53.199:8000` 可访问,原实时 WebSocket 地址为:
|
||||
|
||||
```text
|
||||
ws://10.100.53.199:8000/ws/v1/asr/qwen
|
||||
```
|
||||
|
||||
当前公开接口包括:
|
||||
|
||||
- `/ws/v1/asr/qwen`:原实时 WebSocket,已经包含主服务内部的 ASR、切段和 speaker 逻辑;
|
||||
- `/v1/audio/transcriptions`:整段音频转写;
|
||||
- `/api/v1/speakers/identify`:通过文件来源识别注册说话人;
|
||||
- `/api/v1/speakers`:声纹注册和人员管理。
|
||||
|
||||
当前公开接口没有返回实时聚类所需的原始 embedding,也没有把 [Qwen3ASREngine](app/services/asr/qwen3_engine.py#L570) 的 `create_stream`、`feed_stream`、`finish_stream` 暴露为独立远程模型 RPC。
|
||||
|
||||
所以存在一个边界:
|
||||
|
||||
- 上层 demo WebSocket 可以独立重写事件顺序、切段提交策略、pending 保护和展示合并;
|
||||
- 如果要在 demo 中完整重建原项目的声纹聚类,服务器还需要提供 embedding 接口或模型 RPC;
|
||||
- 只依赖当前 `/ws/v1/asr/qwen` 返回字段,无法重新计算已被原服务错误归类的长段身份。
|
||||
|
||||
## 11. 当前独立 demo 状态
|
||||
|
||||
独立验证项目位于 [realtime_asr_optimization_demo](realtime_asr_optimization_demo)。
|
||||
|
||||
当前结构:
|
||||
|
||||
```text
|
||||
浏览器
|
||||
↓ ws://127.0.0.1:8082/ws
|
||||
demo 上层 WebSocket
|
||||
↓ model_service.py 远程模型服务适配层
|
||||
↓ ws://10.100.53.199:8000/ws/v1/asr/qwen
|
||||
已部署模型服务
|
||||
```
|
||||
|
||||
当前 demo 已具备:
|
||||
|
||||
- 原生 partial 参数透传;
|
||||
- 同一 `sentence_id` 覆盖更新;
|
||||
- raw event 与 display block 分离;
|
||||
- 同一说话人的相邻片段合并;
|
||||
- `<1.6s` 实名结果降级为 pending;
|
||||
- 已命名身份不接受只有弱 cluster id 的片段加入;
|
||||
- embedding 字段不进入 demo 状态池。
|
||||
- 模型服务与 WebSocket 解耦;demo 不启动或加载模型;
|
||||
- 模型服务地址可通过页面或 `--model-service-url` 配置。
|
||||
|
||||
对应实现见 [server.py](realtime_asr_optimization_demo/server.py)、[model_service.py](realtime_asr_optimization_demo/model_service.py)、[speaker_assembler.py](realtime_asr_optimization_demo/speaker_assembler.py) 和 [static/app.js](realtime_asr_optimization_demo/static/app.js)。
|
||||
|
||||
这个 demo 当前主要验证上层协议、状态覆盖和展示保护。后续把模型服务部署到新服务器时,只需替换模型服务地址;若新模型服务协议不同,则替换 `model_service.py`,不改变 WebSocket 编排层。若要验证“demo 自己完成声纹特征提取、聚类和按需姓名匹配”,仍需服务器提供远程 embedding/model RPC。
|
||||
|
||||
## 12. 建议验证用例
|
||||
|
||||
| 用例 | 关注结果 |
|
||||
|---|---|
|
||||
| 单人连续讲话,中间停顿 800ms 以上 | 前端仍属于同一个 display block |
|
||||
| A 讲话后,B 说“嗯/好的” | B 的短段保持 pending,不进入 A 的实名块 |
|
||||
| A→B→A | 保持三个时间顺序块 |
|
||||
| 同一 `sentence_id` 先 partial 后 final | 文本覆盖,不重复追加 |
|
||||
| final 先返回,speaker update 后返回 | 原 block 更新并重新归并 |
|
||||
| 声纹模型异常 | 片段保持 pending,不继承上一位实名 |
|
||||
| 连续多个短插话 | 不复制上一条 embedding,不形成继承链 |
|
||||
| 关闭 native partial | 只影响识别延迟和资源,不改变展示合并规则 |
|
||||
| 关闭 display merge | 可以看到原始物理 segment,用于对照 |
|
||||
|
||||
## 13. 当前未确认项
|
||||
|
||||
以下问题不能仅靠现有公开 WebSocket 字段确认:
|
||||
|
||||
- 原服务是否存在未写入 OpenAPI 的内部 embedding/model RPC;
|
||||
- 实际使用的 realtime speaker 模型是否会输出零向量或 NaN;
|
||||
- 不同真实说话人被分配相同稳定 cluster id 的比例;
|
||||
- speaker worker 完成时间与 `end` 事件之间是否存在竞态;
|
||||
- 远程 Docker 是否还映射了独立的模型后端端口。
|
||||
|
||||
这些项目需要通过服务器日志、embedding 接口或带原始音频的端到端录音继续验证。
|
||||
|
|
@ -0,0 +1,6 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Qwen3-ASR application package."""
|
||||
|
||||
__version__ = "1.0.1"
|
||||
__author__ = "Nexa Team"
|
||||
__description__ = "Qwen3-ASR speech recognition API service"
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
API路由模块
|
||||
包含所有API端点的路由定义
|
||||
"""
|
||||
|
|
@ -0,0 +1,22 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""API v1版本路由"""
|
||||
|
||||
from fastapi import APIRouter
|
||||
from .asr import router as asr_router
|
||||
from .websocket_asr import router as websocket_asr_router
|
||||
from .openai_compatible import router as openai_router
|
||||
from .meeting import router as meeting_router
|
||||
|
||||
api_router = APIRouter()
|
||||
|
||||
# 原有 API (阿里云兼容)
|
||||
api_router.include_router(asr_router)
|
||||
|
||||
# WebSocket ASR 端点(包含阿里云协议和 Qwen3 流式协议)
|
||||
api_router.include_router(websocket_asr_router)
|
||||
|
||||
# OpenAI 兼容 API
|
||||
api_router.include_router(openai_router)
|
||||
|
||||
# 独立会议离线/声纹管理 API(Model-Test-New 兼容形状)
|
||||
api_router.include_router(meeting_router)
|
||||
|
|
@ -0,0 +1,481 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
ASR API路由
|
||||
"""
|
||||
|
||||
from fastapi import (
|
||||
APIRouter,
|
||||
Request,
|
||||
HTTPException,
|
||||
Depends
|
||||
)
|
||||
from fastapi.responses import JSONResponse
|
||||
from typing import Annotated, Optional
|
||||
import time
|
||||
import logging
|
||||
|
||||
from ...core.config import settings
|
||||
from ...core.exceptions import (
|
||||
AuthenticationException,
|
||||
InvalidParameterException,
|
||||
InvalidMessageException,
|
||||
UnsupportedSampleRateException,
|
||||
DefaultServerErrorException,
|
||||
get_http_status_code,
|
||||
)
|
||||
from ...core.security import validate_token
|
||||
from ...models.common import SampleRate
|
||||
from ...models.asr import (
|
||||
ASRResponse,
|
||||
ASRHealthCheckResponse,
|
||||
ASRModelsResponse,
|
||||
ASRSuccessResponse,
|
||||
ASRErrorResponse,
|
||||
ASRQueryParams,
|
||||
)
|
||||
from ...utils.common import generate_task_id
|
||||
from ...services.asr.manager import get_model_manager
|
||||
from ...services.asr.model_selection import validate_offline_model_id
|
||||
from ...services.asr.runtime import get_runtime_router
|
||||
from ...services.asr.audio_validation import validate_sample_rate
|
||||
from ...services.asr.offline_transcription_service import (
|
||||
OfflineTranscriptionOptions,
|
||||
PreparedAudio,
|
||||
get_offline_transcription_service,
|
||||
)
|
||||
|
||||
# 配置日志
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# 创建路由器
|
||||
router = APIRouter(prefix="/stream/v1", tags=["ASR"])
|
||||
|
||||
|
||||
def _build_asr_openapi_parameters() -> list[dict]:
|
||||
parameters: list[dict] = [
|
||||
{
|
||||
"name": "model",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "string",
|
||||
"maxLength": 128,
|
||||
"example": "qwen3-asr-0.6b",
|
||||
},
|
||||
"description": "可选。离线 ASR 模型 ID;不传则使用服务当前默认模型",
|
||||
},
|
||||
{
|
||||
"name": "audio_address",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "string",
|
||||
"maxLength": 512,
|
||||
"example": "https://media.cdn.vect.one/podcast_demo.mp4",
|
||||
},
|
||||
"description": "音频/视频文件地址,支持 HTTP/HTTPS URL、file:// 或服务端本地路径。仅当请求体为空时使用;若同时上传请求体,服务会忽略此参数",
|
||||
},
|
||||
{
|
||||
"name": "sample_rate",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "integer",
|
||||
"enum": [8000, 16000, 22050, 24000, 32000, 44100, 48000],
|
||||
"default": 16000,
|
||||
"example": 16000,
|
||||
},
|
||||
"description": "音频采样率(Hz)。音频会在服务端自动转换,通常保持默认值即可",
|
||||
},
|
||||
{
|
||||
"name": "enable_speaker_diarization",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "boolean",
|
||||
"default": True,
|
||||
"example": True,
|
||||
},
|
||||
"description": "是否启用说话人分离。启用后响应会包含 speaker_id 字段",
|
||||
},
|
||||
{
|
||||
"name": "enable_speaker_identification",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "boolean",
|
||||
"default": True,
|
||||
"example": True,
|
||||
},
|
||||
"description": "是否匹配已注册声纹库。仅在 enable_speaker_diarization=true 时生效,命中后响应会包含 speaker_name/user_id",
|
||||
},
|
||||
{
|
||||
"name": "enable_text_cleanup",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "boolean",
|
||||
"default": True,
|
||||
"example": True,
|
||||
},
|
||||
"description": "是否启用文本去重、跨段重叠裁剪和口头语清理",
|
||||
},
|
||||
{
|
||||
"name": "vocabulary_id",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "string",
|
||||
"maxLength": 512,
|
||||
"example": "阿里巴巴 20 腾讯 15",
|
||||
},
|
||||
"description": "热词字符串,格式:`热词1 权重1 热词2 权重2`。权重范围 1-100,建议 10-30。可提升特定词汇的识别准确率",
|
||||
},
|
||||
{
|
||||
"name": "X-NLS-Token",
|
||||
"in": "header",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "string",
|
||||
"minLength": 1,
|
||||
"maxLength": 256,
|
||||
"example": "",
|
||||
},
|
||||
"description": "访问令牌,用于身份认证。未配置 API_KEY 环境变量时可忽略",
|
||||
},
|
||||
]
|
||||
if settings.ASR_ENABLE_WORD_TIMESTAMPS:
|
||||
parameters.insert(
|
||||
5,
|
||||
{
|
||||
"name": "word_timestamps",
|
||||
"in": "query",
|
||||
"required": False,
|
||||
"schema": {
|
||||
"type": "boolean",
|
||||
"default": False,
|
||||
"example": False,
|
||||
},
|
||||
"description": "是否返回字词级时间戳(默认关闭;启用时会自动调用 forced aligner)",
|
||||
},
|
||||
)
|
||||
return parameters
|
||||
|
||||
|
||||
async def get_asr_params(request: Request) -> ASRQueryParams:
|
||||
"""从请求中提取并验证ASR参数"""
|
||||
# 从URL查询参数中获取
|
||||
query_params = dict(request.query_params)
|
||||
|
||||
# 使用统一的验证器验证参数
|
||||
try:
|
||||
# 验证采样率(转换为整数)
|
||||
if "sample_rate" in query_params and query_params["sample_rate"]:
|
||||
try:
|
||||
sample_rate = int(query_params["sample_rate"]) # type: ignore
|
||||
validated_rate = validate_sample_rate(sample_rate)
|
||||
query_params["sample_rate"] = str(validated_rate) # type: ignore
|
||||
except ValueError:
|
||||
raise InvalidParameterException(
|
||||
f"采样率必须是整数,收到: {query_params['sample_rate']}"
|
||||
)
|
||||
|
||||
# 创建ASRQueryParams实例,Pydantic会自动验证和设置默认值
|
||||
return ASRQueryParams.model_validate(query_params)
|
||||
except InvalidParameterException:
|
||||
raise
|
||||
except Exception as e:
|
||||
raise InvalidParameterException(f"请求参数错误: {str(e)}")
|
||||
|
||||
|
||||
@router.post(
|
||||
"/asr",
|
||||
response_model=ASRResponse,
|
||||
responses={
|
||||
200: {
|
||||
"description": "识别成功",
|
||||
"model": ASRSuccessResponse,
|
||||
},
|
||||
400: {
|
||||
"description": "请求参数错误",
|
||||
"model": ASRErrorResponse,
|
||||
},
|
||||
401: {"description": "认证失败", "model": ASRErrorResponse},
|
||||
500: {"description": "服务器内部错误", "model": ASRErrorResponse},
|
||||
},
|
||||
summary="语音识别(支持长音频)",
|
||||
description="""
|
||||
将音频文件转写为文本,兼容阿里云语音识别 RESTful API。
|
||||
|
||||
## 功能特性
|
||||
- 支持多种音频格式与常见含音轨视频容器:WAV, MP3, M4A, FLAC, OGG, AAC, AMR, PCM, WEBM, MP4, MOV, MKV, AVI 等
|
||||
- 自动音频格式检测和转换
|
||||
- 支持长音频自动分段识别(返回带时间戳的分段结果)
|
||||
- 最大文件大小:{settings.MAX_AUDIO_SIZE // (1024 * 1024)}MB(可通过环境变量 MAX_AUDIO_SIZE 配置)
|
||||
|
||||
## 音频输入方式
|
||||
1. **请求体上传**:将音频/视频二进制数据作为请求体发送
|
||||
2. **URL/本地路径读取**:通过 `audio_address` 参数指定音频/视频文件 URL(HTTP/HTTPS)或服务端本地路径
|
||||
|
||||
如果请求体和 `audio_address` 同时存在,服务会优先使用请求体,并忽略 `audio_address`。
|
||||
|
||||
## 注意事项
|
||||
- 默认使用服务当前启用的 Qwen3-ASR 模型;也可通过可选 `model` 参数指定当前可用离线模型
|
||||
- `vocabulary_id` 参数用于传递热词,格式:`热词1 权重1 热词2 权重2`(如:`阿里巴巴 20 腾讯 15`)
|
||||
- `enable_speaker_identification` 仅在 `enable_speaker_diarization=true` 时生效,用于匹配已注册声纹库
|
||||
- `enable_text_cleanup` 控制识别后的文本去重、跨段重叠裁剪和口头语清理
|
||||
- 音频会自动转换为 16kHz 采样率进行识别
|
||||
""",
|
||||
openapi_extra={
|
||||
"parameters": _build_asr_openapi_parameters(),
|
||||
"requestBody": {
|
||||
"description": "音频/视频文件二进制数据。支持格式:WAV, MP3, M4A, FLAC, OGG, AAC, AMR, PCM, WEBM, MP4, MOV, MKV, AVI 等。若同时提供 audio_address,服务会优先使用这里上传的内容",
|
||||
"content": {
|
||||
"application/octet-stream": {
|
||||
"schema": {"type": "string", "format": "binary"}
|
||||
}
|
||||
},
|
||||
"required": False,
|
||||
},
|
||||
},
|
||||
)
|
||||
async def asr_transcribe(
|
||||
request: Request, params: Annotated[ASRQueryParams, Depends(get_asr_params)]
|
||||
) -> JSONResponse:
|
||||
"""语音识别API端点"""
|
||||
task_id = generate_task_id()
|
||||
prepared_audio: Optional[PreparedAudio] = None
|
||||
|
||||
# 性能计时
|
||||
request_start_time = time.time()
|
||||
|
||||
# 记录请求开始(此时文件已上传完成)
|
||||
content_length = request.headers.get("content-length", "unknown")
|
||||
logger.info(f"[{task_id}] 收到ASR请求, content_length={content_length}")
|
||||
|
||||
transcription_service = get_offline_transcription_service()
|
||||
|
||||
try:
|
||||
# 验证请求头部(鉴权)
|
||||
result, content = validate_token(request, task_id)
|
||||
if not result:
|
||||
raise AuthenticationException(content, task_id)
|
||||
|
||||
model_id = validate_offline_model_id(params.model)
|
||||
|
||||
# 使用音频服务处理音频
|
||||
target_sample_rate = int(params.sample_rate) if params.sample_rate else 16000
|
||||
prepared_audio = await transcription_service.prepare_from_request(
|
||||
request=request,
|
||||
audio_address=params.audio_address,
|
||||
task_id=task_id,
|
||||
sample_rate=target_sample_rate,
|
||||
)
|
||||
|
||||
logger.info(f"[{task_id}] 开始调用 transcribe_long_audio (enable_speaker_diarization={params.enable_speaker_diarization})...")
|
||||
asr_result = await transcription_service.transcribe(
|
||||
prepared_audio,
|
||||
OfflineTranscriptionOptions(
|
||||
model_id=model_id,
|
||||
sample_rate=int(params.sample_rate or SampleRate.RATE_16000),
|
||||
hotwords=params.vocabulary_id or "",
|
||||
enable_speaker_diarization=params.enable_speaker_diarization is not False,
|
||||
enable_speaker_identification=(
|
||||
params.enable_speaker_diarization is not False
|
||||
and params.enable_speaker_identification is not False
|
||||
),
|
||||
enable_text_cleanup=params.enable_text_cleanup is not False,
|
||||
word_timestamps=(
|
||||
settings.ASR_ENABLE_WORD_TIMESTAMPS
|
||||
and params.word_timestamps is True
|
||||
),
|
||||
task_id=task_id,
|
||||
),
|
||||
)
|
||||
|
||||
logger.info(f"[{task_id}] 识别完成,共 {len(asr_result.segments)} 个分段,总字符: {len(asr_result.text)}")
|
||||
|
||||
# 构建分段结果(始终返回 segments,短音频也是 1 个 segment)
|
||||
segments_data = []
|
||||
for seg in asr_result.segments:
|
||||
seg_dict = {
|
||||
"text": seg.text,
|
||||
"start_time": round(seg.start_time, 2),
|
||||
"end_time": round(seg.end_time, 2),
|
||||
}
|
||||
if seg.speaker_id:
|
||||
seg_dict["speaker_id"] = seg.speaker_id
|
||||
if seg.speaker_name:
|
||||
seg_dict["speaker_name"] = seg.speaker_name
|
||||
if seg.user_id:
|
||||
seg_dict["user_id"] = seg.user_id
|
||||
# 添加字词级时间戳(如果存在)
|
||||
if seg.word_tokens:
|
||||
seg_dict["word_tokens"] = [
|
||||
{
|
||||
"text": wt.text,
|
||||
"start_time": round(wt.start_time, 3),
|
||||
"end_time": round(wt.end_time, 3),
|
||||
}
|
||||
for wt in seg.word_tokens
|
||||
]
|
||||
segments_data.append(seg_dict)
|
||||
|
||||
# 计算请求处理时间
|
||||
request_duration = time.time() - request_start_time
|
||||
|
||||
# 返回成功响应(统一数据结构)
|
||||
response_data = {
|
||||
"task_id": task_id,
|
||||
"result": asr_result.text,
|
||||
"status": 200,
|
||||
"message": "SUCCESS",
|
||||
"segments": segments_data,
|
||||
"duration": round(asr_result.duration, 2),
|
||||
"processing_time": round(request_duration, 3),
|
||||
}
|
||||
|
||||
return JSONResponse(content=response_data, headers={"task_id": task_id})
|
||||
|
||||
except (
|
||||
AuthenticationException,
|
||||
InvalidParameterException,
|
||||
InvalidMessageException,
|
||||
UnsupportedSampleRateException,
|
||||
DefaultServerErrorException,
|
||||
) as e:
|
||||
e.task_id = task_id
|
||||
logger.error(f"[{task_id}] ASR异常: {e.message}")
|
||||
|
||||
# 使用标准错误格式
|
||||
response_data = e.to_dict()
|
||||
return JSONResponse(
|
||||
content=response_data,
|
||||
headers={"task_id": task_id},
|
||||
status_code=get_http_status_code(e.status_code),
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"[{task_id}] 未知异常: {str(e)}")
|
||||
|
||||
# 使用标准错误格式
|
||||
from ...core.exceptions import create_error_response
|
||||
response_data = create_error_response(
|
||||
error_code="DEFAULT_SERVER_ERROR",
|
||||
message=f"内部服务错误: {str(e)}",
|
||||
task_id=task_id,
|
||||
)
|
||||
return JSONResponse(content=response_data, headers={"task_id": task_id})
|
||||
|
||||
finally:
|
||||
transcription_service.cleanup(prepared_audio)
|
||||
|
||||
|
||||
@router.get(
|
||||
"/asr/health",
|
||||
response_model=ASRHealthCheckResponse,
|
||||
summary="ASR 服务健康检查",
|
||||
description="""
|
||||
检查语音识别服务的运行状态和资源使用情况。
|
||||
|
||||
## 返回信息
|
||||
- **status**: 服务状态(healthy/unhealthy/error)
|
||||
- **model_loaded**: 默认模型是否已加载
|
||||
- **device**: 当前推理设备(cuda:0/cpu)
|
||||
- **loaded_models**: 已加载的模型列表
|
||||
- **memory_usage**: GPU 显存使用情况(仅 GPU 模式)
|
||||
""",
|
||||
)
|
||||
async def health_check(request: Request):
|
||||
"""ASR服务健康检查端点"""
|
||||
# 鉴权
|
||||
result, content = validate_token(request)
|
||||
if not result:
|
||||
raise AuthenticationException(content, "health_check")
|
||||
|
||||
try:
|
||||
# 尝试获取默认模型的引擎
|
||||
try:
|
||||
runtime_router = get_runtime_router()
|
||||
default_model = runtime_router.resolve_model_id(None)
|
||||
async with await runtime_router.acquire_engine(default_model) as engine:
|
||||
model_loaded = True
|
||||
device = engine.device
|
||||
except Exception:
|
||||
model_loaded = False
|
||||
device = "unknown"
|
||||
|
||||
runtime_router = get_runtime_router()
|
||||
memory_info = runtime_router.get_memory_usage()
|
||||
loaded_models = runtime_router.get_loaded_model_ids()
|
||||
accelerator_info = memory_info.get("accelerator")
|
||||
|
||||
return {
|
||||
"status": "healthy" if model_loaded else "unhealthy",
|
||||
"model_loaded": model_loaded,
|
||||
"device": device,
|
||||
"version": settings.APP_VERSION,
|
||||
"message": (
|
||||
"ASR service is running normally"
|
||||
if model_loaded
|
||||
else "ASR model not loaded"
|
||||
),
|
||||
"loaded_models": loaded_models,
|
||||
"memory_usage": memory_info.get("gpu_memory"),
|
||||
"accelerator": accelerator_info,
|
||||
}
|
||||
except Exception as e:
|
||||
return {
|
||||
"status": "error",
|
||||
"model_loaded": False,
|
||||
"device": "unknown",
|
||||
"version": settings.APP_VERSION,
|
||||
"message": str(e),
|
||||
"accelerator": None,
|
||||
}
|
||||
|
||||
@router.get(
|
||||
"/asr/models",
|
||||
response_model=ASRModelsResponse,
|
||||
summary="获取声明条目列表",
|
||||
description="""
|
||||
返回系统声明的离线模型与 realtime capability 信息。
|
||||
|
||||
## 条目说明
|
||||
|
||||
| ID | 类型 | 说明 |
|
||||
|----|------|------|
|
||||
| qwen3-asr-1.7b | model | 离线/实时共用的 Qwen3-ASR 模型条目 |
|
||||
| qwen3-asr-0.6b | model | 轻量版 Qwen3-ASR 模型条目 |
|
||||
## 返回信息
|
||||
- **declared_entries**: 声明的模型与 capability 列表
|
||||
- **declared_count**: 声明项总数
|
||||
- **runtime**: 运行时加载状态
|
||||
""",
|
||||
)
|
||||
async def list_models(request: Request):
|
||||
"""获取声明条目列表端点"""
|
||||
# 鉴权
|
||||
result, content = validate_token(request)
|
||||
if not result:
|
||||
raise AuthenticationException(content, "list_models")
|
||||
|
||||
try:
|
||||
|
||||
model_manager = get_model_manager()
|
||||
runtime_router = get_runtime_router()
|
||||
loaded_model_ids = runtime_router.get_loaded_model_ids()
|
||||
entries = model_manager.list_declared_entries()
|
||||
|
||||
return {
|
||||
"declared_entries": entries,
|
||||
"declared_count": len(entries),
|
||||
"runtime": {
|
||||
"loaded_model_ids": loaded_model_ids,
|
||||
"loaded_count": len(loaded_model_ids),
|
||||
"default_offline_model_id": runtime_router.resolve_model_id(None),
|
||||
},
|
||||
}
|
||||
except Exception as e:
|
||||
logger.error(f"获取模型列表时发生错误: {str(e)}")
|
||||
raise HTTPException(status_code=500, detail=f"获取模型列表失败: {str(e)}")
|
||||
|
|
@ -0,0 +1,855 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Independent meeting-style offline API compatible with Model-Test-New shapes."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import math
|
||||
import time
|
||||
import uuid
|
||||
from pathlib import Path
|
||||
from typing import Any, Optional
|
||||
from urllib.parse import unquote, urlparse
|
||||
|
||||
import requests
|
||||
from fastapi import APIRouter, BackgroundTasks, Body, File, HTTPException, UploadFile
|
||||
from pydantic import BaseModel, ConfigDict, Field
|
||||
|
||||
from app.core.config import settings
|
||||
from app.core.database import pg_speaker_db
|
||||
from app.core.exceptions import InvalidParameterException
|
||||
from app.core.task_store import create_task_record, get_task_record, update_task_record
|
||||
from app.models.common import SampleRate
|
||||
from app.services.asr.model_selection import validate_offline_model_id
|
||||
from app.services.asr.offline_transcription_service import (
|
||||
OfflineTranscriptionOptions,
|
||||
PreparedAudio,
|
||||
get_offline_transcription_service,
|
||||
)
|
||||
from app.services.speaker_registry import get_speaker_registry_service
|
||||
|
||||
router = APIRouter(prefix=settings.API_PREFIX)
|
||||
|
||||
_UPLOAD_DIR = Path(settings.TEMP_DIR) / "api_uploads"
|
||||
_UPLOAD_DIR.mkdir(parents=True, exist_ok=True)
|
||||
_uploaded_files: dict[str, dict[str, str]] = {}
|
||||
|
||||
|
||||
def _recognition_request_config_example() -> dict[str, Any]:
|
||||
example: dict[str, Any] = {
|
||||
"enable_speaker": True,
|
||||
"match_speaker_registry": True,
|
||||
"enable_text_cleanup": True,
|
||||
"speaker_threshold": 0.6,
|
||||
"hotwords": [
|
||||
{"hotword": "阿里巴巴", "weight": 2.0},
|
||||
{"hotword": "腾讯", "weight": 1.5},
|
||||
],
|
||||
}
|
||||
if settings.ASR_ENABLE_WORD_TIMESTAMPS:
|
||||
example["word_timestamps"] = False
|
||||
return example
|
||||
|
||||
|
||||
def _meeting_request_examples() -> dict[str, Any]:
|
||||
return {
|
||||
"url_with_hotwords": {
|
||||
"summary": "URL + 结构化热词",
|
||||
"description": "推荐的生产调用格式。",
|
||||
"value": {
|
||||
"model": "qwen3-asr-0.6b",
|
||||
"audio_address": "https://example.com/media/meeting.mp4",
|
||||
"config": _recognition_request_config_example(),
|
||||
},
|
||||
},
|
||||
"local_path": {
|
||||
"summary": "服务端本地路径",
|
||||
"value": {
|
||||
"audio_address": "/data/audio/meeting.m4a",
|
||||
"config": {
|
||||
"enable_speaker": True,
|
||||
"match_speaker_registry": False,
|
||||
"enable_text_cleanup": True,
|
||||
},
|
||||
},
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def _recognition_request_config_schema_extra(schema: dict[str, Any], _model: Any) -> None:
|
||||
schema["example"] = _recognition_request_config_example()
|
||||
if settings.ASR_ENABLE_WORD_TIMESTAMPS:
|
||||
return
|
||||
properties = schema.get("properties")
|
||||
if isinstance(properties, dict):
|
||||
properties.pop("word_timestamps", None)
|
||||
required = schema.get("required")
|
||||
if isinstance(required, list):
|
||||
schema["required"] = [item for item in required if item != "word_timestamps"]
|
||||
|
||||
|
||||
class HotwordItem(BaseModel):
|
||||
model_config = ConfigDict(json_schema_extra={"example": {"hotword": "汇智", "weight": 2.0}})
|
||||
|
||||
hotword: str = Field(
|
||||
...,
|
||||
title="热词内容",
|
||||
description="需要优先匹配或纠正的业务词、专有名词、人名、产品名等。Qwen3-ASR 无原生热词能力,服务会在识别后做规则化热词纠正。",
|
||||
examples=["通义千问"],
|
||||
)
|
||||
weight: float = Field(
|
||||
1.0,
|
||||
title="热词权重",
|
||||
description="热词权重,兼容老项目 Model-Test-New 的传参格式;当前规则纠正主要使用热词文本,权重保留用于接口兼容和后续扩展。",
|
||||
examples=[2.0],
|
||||
)
|
||||
|
||||
|
||||
class RecognitionRequestConfig(BaseModel):
|
||||
model_config = ConfigDict(
|
||||
json_schema_extra=_recognition_request_config_schema_extra
|
||||
)
|
||||
enable_speaker: bool = Field(
|
||||
True,
|
||||
title="是否启用说话人分离",
|
||||
description="是否执行说话人分离。开启后返回的分段会带 speaker 字段;关闭后不做说话人分离和声纹库匹配。",
|
||||
examples=[True],
|
||||
)
|
||||
match_speaker_registry: bool = Field(
|
||||
True,
|
||||
title="是否匹配已注册声纹库",
|
||||
description="是否在说话人分离后匹配已注册声纹库。只有 enable_speaker=true 时生效。",
|
||||
examples=[True],
|
||||
)
|
||||
enable_text_cleanup: bool = Field(
|
||||
True,
|
||||
title="是否启用文字去重",
|
||||
description="是否启用识别结果去重/边界重叠裁剪,适合长音频分段识别后的重复文本清理。",
|
||||
examples=[True],
|
||||
)
|
||||
speaker_threshold: Optional[float] = Field(
|
||||
None,
|
||||
title="声纹匹配阈值",
|
||||
description="本次声纹库匹配阈值,范围通常为 0~1;不传则使用服务默认配置。",
|
||||
examples=[0.6],
|
||||
)
|
||||
word_timestamps: bool = Field(
|
||||
False,
|
||||
title="是否返回字词级时间戳",
|
||||
description="是否返回字词级时间戳。长会议场景建议默认关闭以降低耗时和结果体积。",
|
||||
examples=[False],
|
||||
)
|
||||
hotwords: str | list[HotwordItem] = Field(
|
||||
default_factory=list,
|
||||
title="热词",
|
||||
description=(
|
||||
"热词参数。推荐传老项目兼容的结构化数组:"
|
||||
"[{\"hotword\":\"通义千问\",\"weight\":2.0}];也兼容字符串:\"通义千问 2.0 ModelScope 1.5\"。"
|
||||
"Qwen3-ASR 本身没有原生热词参数,服务会在识别后使用热词规则做文本纠正。"
|
||||
),
|
||||
examples=[[{"hotword": "通义千问", "weight": 2.0}, {"hotword": "ModelScope", "weight": 1.5}]],
|
||||
)
|
||||
sample_rate: int = Field(
|
||||
16000,
|
||||
title="采样率",
|
||||
description="音频处理采样率,默认 16000。",
|
||||
examples=[16000],
|
||||
)
|
||||
|
||||
|
||||
class TranscriptionCreateRequest(BaseModel):
|
||||
model_config = ConfigDict(
|
||||
json_schema_extra={
|
||||
"example": {
|
||||
"model": "qwen3-asr-0.6b",
|
||||
"audio_address": "https://example.com/meeting.m4a",
|
||||
"config": {
|
||||
"enable_speaker": True,
|
||||
"match_speaker_registry": True,
|
||||
"enable_text_cleanup": True,
|
||||
"speaker_threshold": 0.6,
|
||||
"hotwords": [
|
||||
{"hotword": "汇智", "weight": 2.0},
|
||||
{"hotword": "通义千问", "weight": 2.5},
|
||||
],
|
||||
},
|
||||
}
|
||||
}
|
||||
)
|
||||
model: Optional[str] = Field(
|
||||
None,
|
||||
title="离线 ASR 模型 ID",
|
||||
description="可选。不传则使用服务当前默认模型;可传当前可用的本地模型 ID,如 qwen3-asr-0.6b 或 qwen3-asr-1.7b。",
|
||||
examples=["qwen3-asr-0.6b"],
|
||||
max_length=128,
|
||||
)
|
||||
audio_address: str = Field(
|
||||
...,
|
||||
title="音视频地址",
|
||||
description="必填。音频/视频文件地址,支持 HTTP/HTTPS URL、file:// 地址或服务端本地音视频路径。该接口生产调用不使用 file_id/file_url。",
|
||||
examples=["https://example.com/meeting.m4a"],
|
||||
)
|
||||
config: RecognitionRequestConfig = Field(
|
||||
default_factory=RecognitionRequestConfig,
|
||||
title="识别配置",
|
||||
description=(
|
||||
"离线会议识别配置,包括说话人分离、声纹库匹配、文字去重和热词规则。"
|
||||
if not settings.ASR_ENABLE_WORD_TIMESTAMPS
|
||||
else "离线会议识别配置,包括说话人分离、声纹库匹配、文字去重、字词时间戳和热词规则。"
|
||||
)
|
||||
)
|
||||
|
||||
|
||||
class SpeakerRegisterRequest(BaseModel):
|
||||
model_config = ConfigDict(
|
||||
json_schema_extra={"example": {"name": "张三", "user_id": "u001", "audio_address": "/data/speakers/zhangsan.wav"}}
|
||||
)
|
||||
name: str
|
||||
audio_address: Optional[str] = None
|
||||
file_url: Optional[str] = None
|
||||
file_id: Optional[str] = None
|
||||
user_id: Optional[str] = None
|
||||
|
||||
|
||||
class SpeakerIdentifyRequest(BaseModel):
|
||||
model_config = ConfigDict(json_schema_extra={"example": {"audio_address": "/data/audio/sample.wav", "threshold": 0.6}})
|
||||
audio_address: Optional[str] = None
|
||||
file_url: Optional[str] = None
|
||||
file_id: Optional[str] = None
|
||||
threshold: Optional[float] = None
|
||||
|
||||
|
||||
def _get_meeting_transcription_description() -> str:
|
||||
return """创建离线会议转写任务。该接口采用 **JSON 请求体**,适合业务系统直接提交会议音频/视频地址并异步轮询结果。
|
||||
|
||||
**音频输入方式:**
|
||||
1. **HTTP/HTTPS URL**:`audio_address="https://example.com/meeting.mp4"`
|
||||
2. **file:// 地址**:`audio_address="file:///data/audio/meeting.m4a"`
|
||||
3. **服务端本地路径**:`audio_address="/data/audio/meeting.m4a"`
|
||||
|
||||
> 生产调用只使用 `audio_address`。`file_id` / `file_url` 不属于该接口参数,上传接口仅用于测试页面调试。
|
||||
|
||||
**请求参数:**
|
||||
| 字段 | 类型 | 必填 | 默认值 | 说明 |
|
||||
|------|------|------|--------|------|
|
||||
| `model` | string/null | 否 | 服务默认模型 | 离线 ASR 模型 ID;不传则使用 `QWEN3_ASR_MODEL` 或自动选择结果 |
|
||||
| `audio_address` | string | 是 | - | 音频/视频文件地址,支持 HTTP/HTTPS、`file://`、服务端本地路径 |
|
||||
| `config` | object | 否 | 默认配置 | 识别配置对象 |
|
||||
| `config.enable_speaker` | boolean | 否 | `true` | 是否启用说话人分离 |
|
||||
| `config.match_speaker_registry` | boolean | 否 | `true` | 是否匹配已注册声纹库,仅在 `enable_speaker=true` 时生效 |
|
||||
| `config.enable_text_cleanup` | boolean | 否 | `true` | 是否启用文字去重、边界重叠裁剪 |
|
||||
| `config.speaker_threshold` | number/null | 否 | 服务默认值 | 本次声纹库匹配阈值,通常为 `0~1` |
|
||||
""" + (
|
||||
"| `config.word_timestamps` | boolean | 否 | `false` | 是否返回字词级时间戳;开启后会调用 Qwen3 ForcedAligner |\n"
|
||||
if settings.ASR_ENABLE_WORD_TIMESTAMPS
|
||||
else ""
|
||||
) + """
|
||||
| `config.hotwords` | array/string | 否 | `[]` | 热词。推荐老项目兼容数组格式:`[{\"hotword\":\"通义千问\",\"weight\":2.0}]` |
|
||||
| `config.sample_rate` | integer | 否 | `16000` | 音频处理采样率 |
|
||||
|
||||
**热词说明:**
|
||||
- Qwen3-ASR 本身没有原生热词参数。
|
||||
- 本服务兼容 Model-Test-New 的热词格式,识别完成后通过规则做热词纠正。
|
||||
- 推荐格式:`[{\"hotword\":\"通义千问\",\"weight\":2.0},{\"hotword\":\"ModelScope\",\"weight\":1.5}]`
|
||||
- 兼容字符串格式:`\"通义千问 2.0 ModelScope 1.5\"`
|
||||
|
||||
**创建任务返回:**
|
||||
| 字段 | 类型 | 说明 |
|
||||
|------|------|------|
|
||||
| `code` | integer | 业务状态码,`0` 表示成功 |
|
||||
| `message` | string | 业务消息 |
|
||||
| `data.task_id` | string | 任务 ID,用于查询识别进度与结果 |
|
||||
| `data.status` | string | 初始状态,通常为 `queued` |
|
||||
| `data.stage` | string | 当前阶段 |
|
||||
| `data.percentage` | number | 当前进度百分比 |
|
||||
|
||||
**查询任务返回:**
|
||||
调用 `GET /api/v1/asr/transcriptions/{task_id}` 查询任务。完成后 `data.result` 包含完整结果。
|
||||
|
||||
| 字段 | 类型 | 说明 |
|
||||
|------|------|------|
|
||||
| `data.status` | string | `queued` / `processing` / `completed` / `failed` |
|
||||
| `data.result.text` | string | 完整转写文本 |
|
||||
| `data.result.segments` | array | 分段结果 |
|
||||
| `data.result.segments[].start` | number | 分段开始时间,秒 |
|
||||
| `data.result.segments[].end` | number | 分段结束时间,秒 |
|
||||
| `data.result.segments[].text` | string | 分段文本 |
|
||||
| `data.result.segments[].speaker_id` | string | 说话人 ID,启用说话人分离时返回 |
|
||||
| `data.result.segments[].speaker_name` | string | 匹配到声纹库时返回姓名,否则通常等于 speaker_id |
|
||||
| `data.result.segments[].user_id` | string | 匹配到声纹库用户时返回 |
|
||||
| `data.result.segments[].word_tokens` | array | 字词级时间戳,仅 `word_timestamps=true` 且模型支持时返回 |
|
||||
| `data.result.audio_duration_seconds` | number | 音频总时长,秒 |
|
||||
| `data.result.speaker_count` | integer | 说话人数量 |
|
||||
| `data.result.speakers` | array | 说话人列表 |
|
||||
"""
|
||||
|
||||
|
||||
def _ok(data: Any) -> dict[str, Any]:
|
||||
return {"code": 0, "message": "ok", "data": data or {}}
|
||||
|
||||
|
||||
def _public_task_payload(task_id: str, task: dict[str, Any]) -> dict[str, Any]:
|
||||
payload: dict[str, Any] = {"task_id": task_id, "status": task["status"]}
|
||||
for key in (
|
||||
"stage",
|
||||
"message",
|
||||
"percentage",
|
||||
"detail",
|
||||
"created_at",
|
||||
"updated_at",
|
||||
):
|
||||
if task.get(key) is not None:
|
||||
payload[key] = task[key]
|
||||
if (
|
||||
task["status"] == "processing"
|
||||
and task.get("created_at") is not None
|
||||
and task.get("percentage") not in (None, 0)
|
||||
):
|
||||
elapsed_seconds = max(1.0, time.time() - float(task["created_at"]))
|
||||
percentage = max(1.0, float(task.get("percentage") or 0))
|
||||
payload["eta_seconds"] = max(
|
||||
0,
|
||||
int(math.ceil(elapsed_seconds * (100.0 - percentage) / percentage)),
|
||||
)
|
||||
elif task["status"] == "completed":
|
||||
payload["eta_seconds"] = 0
|
||||
if task.get("result") is not None:
|
||||
payload["result"] = task["result"]
|
||||
if task.get("error"):
|
||||
payload["error"] = task["error"]
|
||||
return payload
|
||||
|
||||
|
||||
def _require_db() -> None:
|
||||
if not pg_speaker_db.is_connected:
|
||||
raise HTTPException(
|
||||
status_code=503,
|
||||
detail={"code": 1001, "message": "speaker database is not connected"},
|
||||
)
|
||||
|
||||
|
||||
def _normalize_hotwords_for_asr(hotwords: str | list[HotwordItem] | None) -> str:
|
||||
if isinstance(hotwords, str):
|
||||
return hotwords.strip()
|
||||
parts: list[str] = []
|
||||
for item in hotwords or []:
|
||||
text = item.hotword.strip()
|
||||
if not text:
|
||||
continue
|
||||
parts.extend([text, f"{float(item.weight):g}"])
|
||||
return " ".join(parts)
|
||||
|
||||
|
||||
async def _download_url(url: str) -> bytes:
|
||||
loop = asyncio.get_running_loop()
|
||||
|
||||
def _download() -> bytes:
|
||||
response = requests.get(url, timeout=60)
|
||||
response.raise_for_status()
|
||||
return response.content
|
||||
|
||||
return await loop.run_in_executor(None, _download)
|
||||
|
||||
|
||||
def _is_http_url(value: str) -> bool:
|
||||
return value.lower().startswith(("http://", "https://"))
|
||||
|
||||
|
||||
def _source_filename(source: str) -> str:
|
||||
parsed = urlparse(source)
|
||||
path = unquote(parsed.path or source)
|
||||
return Path(path).name or "audio"
|
||||
|
||||
|
||||
async def _read_local_file(path_value: str) -> bytes:
|
||||
parsed = urlparse(path_value)
|
||||
local_path = Path(unquote(parsed.path)) if parsed.scheme == "file" else Path(path_value).expanduser()
|
||||
if not local_path.is_file():
|
||||
raise HTTPException(status_code=404, detail={"code": 1001, "message": "local media file not found"})
|
||||
loop = asyncio.get_running_loop()
|
||||
return await loop.run_in_executor(None, local_path.read_bytes)
|
||||
|
||||
|
||||
async def _resolve_source_bytes(audio_address: Optional[str], file_id: Optional[str]) -> tuple[bytes, Optional[str]]:
|
||||
if audio_address:
|
||||
source = audio_address.strip()
|
||||
if _is_http_url(source):
|
||||
return await _download_url(source), _source_filename(source)
|
||||
return await _read_local_file(source), _source_filename(source)
|
||||
if file_id:
|
||||
item = _uploaded_files.get(file_id)
|
||||
if not item:
|
||||
matched_files = sorted(_UPLOAD_DIR.glob(f"{file_id}.*"))
|
||||
if not matched_files:
|
||||
raise HTTPException(status_code=404, detail={"code": 1001, "message": "file_id not found"})
|
||||
matched_path = matched_files[0]
|
||||
item = {"path": str(matched_path), "filename": matched_path.name}
|
||||
_uploaded_files[file_id] = item
|
||||
path = item["path"]
|
||||
with open(path, "rb") as file_obj:
|
||||
return file_obj.read(), item.get("filename")
|
||||
raise HTTPException(status_code=400, detail={"code": 1001, "message": "audio_address or file_id is required"})
|
||||
|
||||
|
||||
def _cleanup_uploaded_file(file_id: Optional[str]) -> None:
|
||||
if not file_id:
|
||||
return
|
||||
item = _uploaded_files.pop(file_id, None)
|
||||
candidate_paths: list[Path] = []
|
||||
if item and item.get("path"):
|
||||
candidate_paths.append(Path(item["path"]))
|
||||
candidate_paths.extend(sorted(_UPLOAD_DIR.glob(f"{file_id}.*")))
|
||||
for path in candidate_paths:
|
||||
try:
|
||||
path.unlink(missing_ok=True)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
def _format_segments(asr_result: Any) -> list[dict[str, Any]]:
|
||||
segments: list[dict[str, Any]] = []
|
||||
for segment in asr_result.segments:
|
||||
item: dict[str, Any] = {
|
||||
"start": round(float(segment.start_time), 2),
|
||||
"end": round(float(segment.end_time), 2),
|
||||
"duration": round(float(segment.end_time - segment.start_time), 2),
|
||||
"text": segment.text,
|
||||
}
|
||||
if segment.speaker_id:
|
||||
item["speaker_id"] = segment.speaker_id
|
||||
if segment.speaker_name:
|
||||
item["speaker_name"] = segment.speaker_name
|
||||
elif segment.speaker_id:
|
||||
item["speaker_name"] = segment.speaker_id
|
||||
if segment.user_id:
|
||||
item["user_id"] = segment.user_id
|
||||
if segment.word_tokens:
|
||||
item["word_tokens"] = [
|
||||
{
|
||||
"text": token.text,
|
||||
"start": round(float(token.start_time), 3),
|
||||
"end": round(float(token.end_time), 3),
|
||||
}
|
||||
for token in segment.word_tokens
|
||||
]
|
||||
segments.append(item)
|
||||
return segments
|
||||
|
||||
|
||||
def _build_transcription_result(asr_result: Any) -> dict[str, Any]:
|
||||
segments = _format_segments(asr_result)
|
||||
speakers: list[str] = []
|
||||
for segment in segments:
|
||||
name = str(segment.get("speaker_name") or segment.get("speaker_id") or "").strip()
|
||||
if name and name not in speakers:
|
||||
speakers.append(name)
|
||||
return {
|
||||
"text": asr_result.text,
|
||||
"segments": segments,
|
||||
"audio_duration_seconds": round(float(asr_result.duration), 2),
|
||||
"speaker_count": len(speakers),
|
||||
"speakers": speakers,
|
||||
}
|
||||
|
||||
|
||||
def _update_task_progress(
|
||||
task_id: str,
|
||||
*,
|
||||
status: str,
|
||||
stage: str,
|
||||
message: str,
|
||||
percentage: int,
|
||||
detail: Optional[dict[str, Any]] = None,
|
||||
) -> None:
|
||||
current_task = get_task_record(task_id) or {}
|
||||
current_status = str(current_task.get("status") or "")
|
||||
current_percentage = int(current_task.get("percentage") or 0)
|
||||
incoming_percentage = max(0, min(100, int(percentage)))
|
||||
if (
|
||||
current_status in {"queued", "processing"}
|
||||
and status in {"queued", "processing"}
|
||||
and incoming_percentage < current_percentage
|
||||
):
|
||||
return
|
||||
payload: dict[str, Any] = {
|
||||
"status": status,
|
||||
"stage": stage,
|
||||
"message": message,
|
||||
"percentage": incoming_percentage,
|
||||
}
|
||||
if detail is not None:
|
||||
payload["detail"] = detail
|
||||
update_task_record(task_id, payload)
|
||||
|
||||
|
||||
async def _run_transcription_task(
|
||||
*,
|
||||
task_id: str,
|
||||
model: Optional[str],
|
||||
audio_address: Optional[str],
|
||||
config: RecognitionRequestConfig,
|
||||
) -> None:
|
||||
service = get_offline_transcription_service()
|
||||
prepared_audio: Optional[PreparedAudio] = None
|
||||
_update_task_progress(
|
||||
task_id,
|
||||
status="processing",
|
||||
stage="preparing",
|
||||
message="任务已开始,正在准备音频文件。",
|
||||
percentage=5,
|
||||
detail={"segment_total": 0, "segment_completed": 0},
|
||||
)
|
||||
try:
|
||||
audio_data, filename = await _resolve_source_bytes(audio_address, None)
|
||||
_update_task_progress(
|
||||
task_id,
|
||||
status="processing",
|
||||
stage="normalizing",
|
||||
message="音频来源已读取,正在转换为识别格式。",
|
||||
percentage=8,
|
||||
detail={"segment_total": 0, "segment_completed": 0},
|
||||
)
|
||||
prepared_audio = await service.prepare_upload(
|
||||
audio_data=audio_data,
|
||||
filename=filename,
|
||||
task_id=task_id,
|
||||
sample_rate=config.sample_rate or int(SampleRate.RATE_16000),
|
||||
)
|
||||
_update_task_progress(
|
||||
task_id,
|
||||
status="processing",
|
||||
stage="transcribing",
|
||||
message="音频已准备完成,正在执行离线识别。",
|
||||
percentage=12,
|
||||
detail={
|
||||
"segment_total": 0,
|
||||
"segment_completed": 0,
|
||||
"audio_duration_seconds": round(float(prepared_audio.duration), 2),
|
||||
},
|
||||
)
|
||||
|
||||
def progress_callback(
|
||||
stage: str,
|
||||
message: str,
|
||||
percentage: int,
|
||||
detail: Optional[dict[str, Any]] = None,
|
||||
) -> None:
|
||||
_update_task_progress(
|
||||
task_id,
|
||||
status="processing",
|
||||
stage=stage,
|
||||
message=message,
|
||||
percentage=percentage,
|
||||
detail=detail,
|
||||
)
|
||||
|
||||
asr_result = await service.transcribe(
|
||||
prepared_audio,
|
||||
OfflineTranscriptionOptions(
|
||||
model_id=model,
|
||||
sample_rate=config.sample_rate or int(SampleRate.RATE_16000),
|
||||
hotwords=_normalize_hotwords_for_asr(config.hotwords),
|
||||
enable_speaker_diarization=config.enable_speaker,
|
||||
enable_speaker_identification=(
|
||||
config.enable_speaker and config.match_speaker_registry
|
||||
),
|
||||
enable_text_cleanup=config.enable_text_cleanup,
|
||||
word_timestamps=(
|
||||
settings.ASR_ENABLE_WORD_TIMESTAMPS and config.word_timestamps
|
||||
),
|
||||
task_id=task_id,
|
||||
progress_callback=progress_callback,
|
||||
),
|
||||
)
|
||||
if (
|
||||
config.enable_speaker
|
||||
and config.match_speaker_registry
|
||||
and config.speaker_threshold is not None
|
||||
):
|
||||
_update_task_progress(
|
||||
task_id,
|
||||
status="processing",
|
||||
stage="speaker_matching",
|
||||
message="正在使用本次阈值匹配已注册声纹库。",
|
||||
percentage=95,
|
||||
detail={
|
||||
"segment_total": len(asr_result.segments),
|
||||
"segment_completed": len(asr_result.segments),
|
||||
"audio_duration_seconds": round(float(asr_result.duration), 2),
|
||||
},
|
||||
)
|
||||
await get_speaker_registry_service().apply_registered_speakers(
|
||||
asr_result,
|
||||
threshold=config.speaker_threshold,
|
||||
)
|
||||
result = _build_transcription_result(asr_result)
|
||||
_update_task_progress(
|
||||
task_id,
|
||||
status="completed",
|
||||
stage="completed",
|
||||
message="离线识别已经完成。",
|
||||
percentage=100,
|
||||
detail={
|
||||
"segment_total": len(result.get("segments") or []),
|
||||
"segment_completed": len(result.get("segments") or []),
|
||||
"audio_duration_seconds": result.get("audio_duration_seconds"),
|
||||
"speaker_count": result.get("speaker_count"),
|
||||
"speakers": result.get("speakers"),
|
||||
},
|
||||
)
|
||||
update_task_record(task_id, {"result": result})
|
||||
except Exception as exc:
|
||||
_update_task_progress(
|
||||
task_id,
|
||||
status="failed",
|
||||
stage="failed",
|
||||
message="离线识别执行失败。",
|
||||
percentage=100,
|
||||
)
|
||||
update_task_record(task_id, {"error": str(exc)})
|
||||
finally:
|
||||
service.cleanup(prepared_audio)
|
||||
|
||||
|
||||
@router.post("/files", tags=["会议离线接口"], summary="上传音频文件")
|
||||
async def upload_file(file: UploadFile = File(...)) -> dict[str, Any]:
|
||||
file_id = uuid.uuid4().hex
|
||||
suffix = Path(file.filename or "").suffix or ".audio"
|
||||
path = _UPLOAD_DIR / f"{file_id}{suffix}"
|
||||
content = await file.read()
|
||||
path.write_bytes(content)
|
||||
_uploaded_files[file_id] = {"path": str(path), "filename": file.filename or path.name}
|
||||
return _ok({"file_id": file_id, "file_path": str(path)})
|
||||
|
||||
|
||||
@router.post(
|
||||
"/asr/transcriptions",
|
||||
tags=["会议离线接口"],
|
||||
summary="创建离线会议识别任务",
|
||||
description=_get_meeting_transcription_description(),
|
||||
response_description="任务创建成功,返回 task_id;后续调用 GET /api/v1/asr/transcriptions/{task_id} 查询进度和结果。",
|
||||
responses={
|
||||
200: {
|
||||
"description": "任务创建成功",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"example": {
|
||||
"code": 0,
|
||||
"message": "ok",
|
||||
"data": {
|
||||
"task_id": "task_6fd90daffd2f446f944b64fdf6c17572",
|
||||
"status": "queued",
|
||||
"stage": "queued",
|
||||
"message": "任务已创建,等待进入处理流程。",
|
||||
"percentage": 0,
|
||||
},
|
||||
}
|
||||
}
|
||||
},
|
||||
},
|
||||
400: {
|
||||
"description": "请求参数错误",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"example": {
|
||||
"detail": {
|
||||
"code": 1001,
|
||||
"message": "audio_address is required",
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
},
|
||||
},
|
||||
)
|
||||
async def create_transcription_task(
|
||||
background_tasks: BackgroundTasks,
|
||||
item: TranscriptionCreateRequest = Body(
|
||||
...,
|
||||
description="离线会议识别任务 JSON 请求体。必须提供 audio_address,可在 config 中配置说话人分离、声纹库匹配、文字去重、热词等。",
|
||||
examples=_meeting_request_examples(),
|
||||
),
|
||||
) -> dict[str, Any]:
|
||||
if not item.audio_address:
|
||||
raise HTTPException(status_code=400, detail={"code": 1001, "message": "audio_address is required"})
|
||||
try:
|
||||
model_id = validate_offline_model_id(item.model)
|
||||
except InvalidParameterException as exc:
|
||||
raise HTTPException(status_code=400, detail={"code": 1001, "message": exc.message}) from exc
|
||||
task_id = f"task_{uuid.uuid4().hex}"
|
||||
create_task_record(
|
||||
task_id,
|
||||
{
|
||||
"status": "queued",
|
||||
"stage": "queued",
|
||||
"message": "任务已创建,等待进入处理流程。",
|
||||
"percentage": 0,
|
||||
"result": None,
|
||||
"detail": {"segment_total": 0, "segment_completed": 0},
|
||||
},
|
||||
)
|
||||
background_tasks.add_task(
|
||||
_run_transcription_task,
|
||||
task_id=task_id,
|
||||
model=model_id,
|
||||
audio_address=item.audio_address,
|
||||
config=item.config,
|
||||
)
|
||||
return _ok(
|
||||
{
|
||||
"task_id": task_id,
|
||||
"status": "queued",
|
||||
"stage": "queued",
|
||||
"message": "任务已创建,等待进入处理流程。",
|
||||
"percentage": 0,
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
@router.get(
|
||||
"/asr/transcriptions/{task_id}",
|
||||
tags=["会议离线接口"],
|
||||
summary="查询离线会议识别任务",
|
||||
description=(
|
||||
"根据创建任务时返回的 `task_id` 查询离线会议识别进度和结果。"
|
||||
"`status=completed` 时,`data.result` 会包含完整文本、分段、说话人和可选字词级时间戳。"
|
||||
),
|
||||
responses={
|
||||
200: {
|
||||
"description": "查询成功",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"examples": {
|
||||
"processing": {
|
||||
"summary": "处理中",
|
||||
"value": {
|
||||
"code": 0,
|
||||
"message": "ok",
|
||||
"data": {
|
||||
"task_id": "task_6fd90daffd2f446f944b64fdf6c17572",
|
||||
"status": "processing",
|
||||
"stage": "asr",
|
||||
"message": "正在识别分段 80/127",
|
||||
"percentage": 62,
|
||||
"detail": {"segment_total": 127, "segment_completed": 80},
|
||||
"eta_seconds": 38,
|
||||
},
|
||||
},
|
||||
},
|
||||
"completed": {
|
||||
"summary": "已完成",
|
||||
"value": {
|
||||
"code": 0,
|
||||
"message": "ok",
|
||||
"data": {
|
||||
"task_id": "task_6fd90daffd2f446f944b64fdf6c17572",
|
||||
"status": "completed",
|
||||
"stage": "completed",
|
||||
"message": "识别完成。",
|
||||
"percentage": 100,
|
||||
"eta_seconds": 0,
|
||||
"result": {
|
||||
"text": "大家好,今天我们讨论通义千问和 ModelScope 的接入方案。",
|
||||
"segments": [
|
||||
{
|
||||
"start": 0.0,
|
||||
"end": 4.28,
|
||||
"duration": 4.28,
|
||||
"text": "大家好,今天我们讨论通义千问和 ModelScope 的接入方案。",
|
||||
"speaker_id": "speaker_1",
|
||||
"speaker_name": "张三",
|
||||
"user_id": "u001",
|
||||
"word_tokens": [
|
||||
{"text": "大家好", "start": 0.12, "end": 0.68}
|
||||
],
|
||||
}
|
||||
],
|
||||
"audio_duration_seconds": 4669.05,
|
||||
"speaker_count": 1,
|
||||
"speakers": ["张三"],
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
}
|
||||
}
|
||||
},
|
||||
},
|
||||
404: {
|
||||
"description": "任务不存在",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"example": {
|
||||
"detail": {
|
||||
"code": 1004,
|
||||
"message": "task not found",
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
},
|
||||
},
|
||||
)
|
||||
async def get_transcription_task(task_id: str) -> dict[str, Any]:
|
||||
task = get_task_record(task_id, include_result=True)
|
||||
if not task:
|
||||
raise HTTPException(status_code=404, detail={"code": 1001, "message": "Task not found"})
|
||||
return _ok(_public_task_payload(task_id, task))
|
||||
|
||||
|
||||
@router.post("/speakers", tags=["声纹管理"], summary="注册声纹")
|
||||
async def register_speaker(item: SpeakerRegisterRequest) -> dict[str, Any]:
|
||||
_require_db()
|
||||
temp_path: Optional[str] = None
|
||||
try:
|
||||
audio_data, filename = await _resolve_source_bytes(item.audio_address or item.file_url, item.file_id)
|
||||
suffix = Path(filename or "").suffix or ".wav"
|
||||
temp_path = await get_speaker_registry_service().save_upload_to_temp(audio_data, suffix=suffix)
|
||||
result = await get_speaker_registry_service().register_file(
|
||||
name=item.name,
|
||||
file_path=temp_path,
|
||||
user_id=item.user_id,
|
||||
)
|
||||
return _ok(result)
|
||||
finally:
|
||||
get_speaker_registry_service().cleanup_file(temp_path)
|
||||
_cleanup_uploaded_file(item.file_id)
|
||||
|
||||
|
||||
@router.get("/speakers", tags=["声纹管理"], summary="获取声纹人员列表")
|
||||
async def list_speakers() -> dict[str, Any]:
|
||||
_require_db()
|
||||
return _ok(
|
||||
{
|
||||
"items": await get_speaker_registry_service().list_speakers(),
|
||||
"speaker_model": "CampPlus",
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
@router.delete("/speakers/{speaker_id}", tags=["声纹管理"], summary="删除声纹人员")
|
||||
async def delete_speaker(speaker_id: str) -> dict[str, Any]:
|
||||
_require_db()
|
||||
deleted = await get_speaker_registry_service().delete_speaker(speaker_id)
|
||||
if not deleted:
|
||||
raise HTTPException(status_code=404, detail={"code": 1001, "message": "Speaker not found"})
|
||||
return _ok({"id": speaker_id})
|
||||
|
||||
|
||||
@router.post("/speakers/identify", tags=["声纹管理"], summary="识别音频中的说话人")
|
||||
async def identify_speaker(item: SpeakerIdentifyRequest) -> dict[str, Any]:
|
||||
_require_db()
|
||||
temp_path: Optional[str] = None
|
||||
try:
|
||||
audio_data, filename = await _resolve_source_bytes(item.audio_address or item.file_url, item.file_id)
|
||||
suffix = Path(filename or "").suffix or ".wav"
|
||||
temp_path = await get_speaker_registry_service().save_upload_to_temp(audio_data, suffix=suffix)
|
||||
return _ok(
|
||||
await get_speaker_registry_service().identify_file(
|
||||
file_path=temp_path,
|
||||
threshold=item.threshold,
|
||||
)
|
||||
)
|
||||
finally:
|
||||
get_speaker_registry_service().cleanup_file(temp_path)
|
||||
_cleanup_uploaded_file(item.file_id)
|
||||
|
|
@ -0,0 +1,692 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
OpenAI 兼容 API
|
||||
实现 OpenAI Audio API 规范,兼容 OpenAI SDK 和第三方客户端
|
||||
"""
|
||||
|
||||
import asyncio
|
||||
import json
|
||||
import time
|
||||
import logging
|
||||
from typing import Any, Optional, List
|
||||
from enum import Enum
|
||||
|
||||
from fastapi import APIRouter, File, Form, UploadFile, Request, HTTPException
|
||||
from fastapi.responses import JSONResponse, PlainTextResponse, StreamingResponse
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
from ...core.config import settings
|
||||
from ...core.security import validate_openai_token
|
||||
from ...core.exceptions import (
|
||||
create_error_response,
|
||||
InvalidParameterException,
|
||||
)
|
||||
from ...services.asr.model_selection import (
|
||||
get_default_offline_model_id,
|
||||
get_offline_model_ids,
|
||||
validate_offline_model_id,
|
||||
)
|
||||
from ...services.asr.offline_transcription_service import (
|
||||
OfflineTranscriptionOptions,
|
||||
PreparedAudio,
|
||||
get_offline_transcription_service,
|
||||
)
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
def _parse_hidden_bool(raw_value: Any) -> bool:
|
||||
if isinstance(raw_value, bool):
|
||||
return raw_value
|
||||
if raw_value is None:
|
||||
return False
|
||||
return str(raw_value).strip().lower() in {"1", "true", "yes", "on"}
|
||||
|
||||
|
||||
router = APIRouter(prefix="/v1", tags=["OpenAI Compatible"])
|
||||
HEARTBEAT_INTERVAL_SECONDS = 15.0
|
||||
|
||||
|
||||
# ============= 枚举类型 =============
|
||||
|
||||
class ResponseFormat(str, Enum):
|
||||
JSON = "json"
|
||||
TEXT = "text"
|
||||
SRT = "srt"
|
||||
VERBOSE_JSON = "verbose_json"
|
||||
VTT = "vtt"
|
||||
|
||||
|
||||
# ============= 响应模型 =============
|
||||
|
||||
class TranscriptionSegment(BaseModel):
|
||||
"""转写分段"""
|
||||
id: int
|
||||
seek: int = 0
|
||||
start: float
|
||||
end: float
|
||||
text: str
|
||||
tokens: List[int] = Field(default_factory=list)
|
||||
temperature: float = 0.0
|
||||
avg_logprob: float = 0.0
|
||||
compression_ratio: float = 0.0
|
||||
no_speech_prob: float = 0.0
|
||||
speaker: Optional[str] = Field(default=None, description="说话人ID")
|
||||
|
||||
|
||||
class TranscriptionWord(BaseModel):
|
||||
"""转写词级别信息"""
|
||||
word: str
|
||||
start: float
|
||||
end: float
|
||||
|
||||
|
||||
class TranscriptionResponse(BaseModel):
|
||||
"""简单转写响应 (json 格式)"""
|
||||
text: str
|
||||
|
||||
|
||||
class VerboseTranscriptionResponse(BaseModel):
|
||||
"""详细转写响应 (verbose_json 格式)"""
|
||||
task: str = "transcribe"
|
||||
language: str
|
||||
duration: float
|
||||
text: str
|
||||
segments: List[TranscriptionSegment] = Field(default_factory=list)
|
||||
words: Optional[List[TranscriptionWord]] = None
|
||||
|
||||
|
||||
class ModelObject(BaseModel):
|
||||
"""模型对象"""
|
||||
id: str
|
||||
object: str = "model"
|
||||
created: int = Field(default_factory=lambda: int(time.time()))
|
||||
owned_by: str = "qwen3-asr"
|
||||
|
||||
|
||||
class ModelsResponse(BaseModel):
|
||||
"""模型列表响应"""
|
||||
object: str = "list"
|
||||
data: List[ModelObject]
|
||||
|
||||
|
||||
# ============= 辅助函数 =============
|
||||
|
||||
def format_timestamp_srt(seconds: float) -> str:
|
||||
"""格式化时间戳为 SRT 格式 (HH:MM:SS,mmm)"""
|
||||
hours = int(seconds // 3600)
|
||||
minutes = int((seconds % 3600) // 60)
|
||||
secs = int(seconds % 60)
|
||||
millis = int((seconds % 1) * 1000)
|
||||
return f"{hours:02d}:{minutes:02d}:{secs:02d},{millis:03d}"
|
||||
|
||||
|
||||
def format_timestamp_vtt(seconds: float) -> str:
|
||||
"""格式化时间戳为 VTT 格式 (HH:MM:SS.mmm)"""
|
||||
hours = int(seconds // 3600)
|
||||
minutes = int((seconds % 3600) // 60)
|
||||
secs = int(seconds % 60)
|
||||
millis = int((seconds % 1) * 1000)
|
||||
return f"{hours:02d}:{minutes:02d}:{secs:02d}.{millis:03d}"
|
||||
|
||||
|
||||
def generate_srt(segments: List[TranscriptionSegment]) -> str:
|
||||
"""生成 SRT 字幕格式"""
|
||||
lines = []
|
||||
for i, seg in enumerate(segments, 1):
|
||||
start = format_timestamp_srt(seg.start)
|
||||
end = format_timestamp_srt(seg.end)
|
||||
lines.append(f"{i}")
|
||||
lines.append(f"{start} --> {end}")
|
||||
text = seg.text.strip()
|
||||
if seg.speaker:
|
||||
text = f"[{seg.speaker}] {text}"
|
||||
lines.append(text)
|
||||
lines.append("")
|
||||
return "\n".join(lines)
|
||||
|
||||
|
||||
def generate_vtt(segments: List[TranscriptionSegment]) -> str:
|
||||
"""生成 WebVTT 字幕格式"""
|
||||
lines = ["WEBVTT", ""]
|
||||
for seg in segments:
|
||||
start = format_timestamp_vtt(seg.start)
|
||||
end = format_timestamp_vtt(seg.end)
|
||||
lines.append(f"{start} --> {end}")
|
||||
text = seg.text.strip()
|
||||
if seg.speaker:
|
||||
text = f"[{seg.speaker}] {text}"
|
||||
lines.append(text)
|
||||
lines.append("")
|
||||
return "\n".join(lines)
|
||||
|
||||
|
||||
def detect_language(text: str, language: Optional[str]) -> str:
|
||||
"""检测识别语言。"""
|
||||
if language:
|
||||
return language
|
||||
|
||||
import re
|
||||
|
||||
if re.search(r"[\u4e00-\u9fff]", text):
|
||||
return "zh"
|
||||
return "en"
|
||||
|
||||
|
||||
def build_transcription_payload(
|
||||
*,
|
||||
response_format: ResponseFormat,
|
||||
asr_result,
|
||||
audio_duration: float,
|
||||
language: Optional[str],
|
||||
) -> tuple[object, int, int]:
|
||||
"""构建 OpenAI 转写响应载荷,并返回 segments / words 计数。"""
|
||||
segments: List[TranscriptionSegment] = []
|
||||
words: List[TranscriptionWord] = []
|
||||
|
||||
for i, seg in enumerate(asr_result.segments):
|
||||
segments.append(
|
||||
TranscriptionSegment(
|
||||
id=i,
|
||||
seek=int(seg.start_time * 100),
|
||||
start=seg.start_time,
|
||||
end=seg.end_time,
|
||||
text=seg.text,
|
||||
speaker=seg.speaker_id,
|
||||
)
|
||||
)
|
||||
if seg.word_tokens:
|
||||
for wt in seg.word_tokens:
|
||||
words.append(
|
||||
TranscriptionWord(
|
||||
word=wt.text,
|
||||
start=round(seg.start_time + wt.start_time, 3),
|
||||
end=round(seg.start_time + wt.end_time, 3),
|
||||
)
|
||||
)
|
||||
|
||||
detected_language = detect_language(asr_result.text, language)
|
||||
|
||||
if response_format == ResponseFormat.VERBOSE_JSON:
|
||||
payload = VerboseTranscriptionResponse(
|
||||
task="transcribe",
|
||||
language=detected_language,
|
||||
duration=audio_duration,
|
||||
text=asr_result.text,
|
||||
segments=segments,
|
||||
words=words if words else None,
|
||||
).model_dump()
|
||||
elif response_format == ResponseFormat.JSON:
|
||||
payload = {"text": asr_result.text}
|
||||
elif response_format == ResponseFormat.TEXT:
|
||||
payload = asr_result.text
|
||||
elif response_format == ResponseFormat.SRT:
|
||||
if not segments:
|
||||
segments = [
|
||||
TranscriptionSegment(
|
||||
id=0,
|
||||
start=0,
|
||||
end=audio_duration,
|
||||
text=asr_result.text,
|
||||
)
|
||||
]
|
||||
payload = generate_srt(segments)
|
||||
elif response_format == ResponseFormat.VTT:
|
||||
if not segments:
|
||||
segments = [
|
||||
TranscriptionSegment(
|
||||
id=0,
|
||||
start=0,
|
||||
end=audio_duration,
|
||||
text=asr_result.text,
|
||||
)
|
||||
]
|
||||
payload = generate_vtt(segments)
|
||||
else:
|
||||
payload = {"text": asr_result.text}
|
||||
|
||||
return payload, len(segments), len(words)
|
||||
|
||||
|
||||
def create_heartbeat_streaming_response(
|
||||
*,
|
||||
response_format: ResponseFormat,
|
||||
inference_coro,
|
||||
audio_duration: float,
|
||||
language: Optional[str],
|
||||
cleanup_callback,
|
||||
) -> StreamingResponse:
|
||||
"""为长耗时 JSON 响应生成带心跳的流式输出。"""
|
||||
|
||||
async def response_stream():
|
||||
inference_task = asyncio.create_task(inference_coro)
|
||||
heartbeat_count = 0
|
||||
|
||||
try:
|
||||
while True:
|
||||
done, _pending = await asyncio.wait(
|
||||
{inference_task},
|
||||
timeout=HEARTBEAT_INTERVAL_SECONDS,
|
||||
return_when=asyncio.FIRST_COMPLETED,
|
||||
)
|
||||
if inference_task in done:
|
||||
break
|
||||
|
||||
heartbeat_count += 1
|
||||
logger.info(
|
||||
"[OpenAI API] 发送响应心跳: "
|
||||
f"format={response_format}, heartbeat_count={heartbeat_count}"
|
||||
)
|
||||
yield b" \n"
|
||||
|
||||
asr_result = await inference_task
|
||||
logger.info(f"[OpenAI API] 识别完成: {len(asr_result.text)} 字符")
|
||||
|
||||
payload, segments_count, words_count = build_transcription_payload(
|
||||
response_format=response_format,
|
||||
asr_result=asr_result,
|
||||
audio_duration=audio_duration,
|
||||
language=language,
|
||||
)
|
||||
response_bytes = json.dumps(
|
||||
payload,
|
||||
ensure_ascii=False,
|
||||
separators=(",", ":"),
|
||||
).encode("utf-8")
|
||||
|
||||
logger.info(
|
||||
"[OpenAI API] 准备发送 JSON 响应: "
|
||||
f"format={response_format}, "
|
||||
f"segments={segments_count}, "
|
||||
f"words={words_count}, "
|
||||
f"payload_bytes={len(response_bytes)}, "
|
||||
f"heartbeat_count={heartbeat_count}"
|
||||
)
|
||||
yield response_bytes
|
||||
finally:
|
||||
cleanup_callback()
|
||||
|
||||
return StreamingResponse(
|
||||
response_stream(),
|
||||
media_type="application/json",
|
||||
headers={
|
||||
"Cache-Control": "no-cache",
|
||||
"X-Accel-Buffering": "no",
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
# ============= API 端点 =============
|
||||
|
||||
def _get_openai_model_description() -> str:
|
||||
"""获取动态的模型描述"""
|
||||
available_models = get_offline_model_ids()
|
||||
default_model = get_default_offline_model_id()
|
||||
|
||||
model_descriptions = {
|
||||
"qwen3-asr-1.7b": "Qwen3-ASR 1.7B,52 种语言,vLLM 高性能",
|
||||
"qwen3-asr-0.6b": "Qwen3-ASR 0.6B,轻量版,适合小显存环境",
|
||||
"qwen3-asr": "自动路由到当前已启动的 Qwen3-ASR 版本",
|
||||
}
|
||||
|
||||
# 构建表格行
|
||||
table_rows = []
|
||||
for m in available_models:
|
||||
desc = model_descriptions.get(m, "")
|
||||
if m == default_model:
|
||||
desc += "(默认)"
|
||||
table_rows.append(f"| `{m}` | {desc} |")
|
||||
|
||||
return f"""返回当前可用的离线 Qwen3-ASR 模型列表(OpenAI `/v1/models` 兼容)。
|
||||
|
||||
**可用离线模型:**
|
||||
|
||||
| 模型 ID | 说明 |
|
||||
|---------|------|
|
||||
{chr(10).join(table_rows)}
|
||||
|
||||
**兼容性说明:**
|
||||
- 支持 OpenAI SDK 和第三方客户端调用
|
||||
- 当前默认模型根据显存自动选择;也可通过 `QWEN3_ASR_MODEL` 覆盖
|
||||
"""
|
||||
|
||||
|
||||
@router.get(
|
||||
"/models",
|
||||
response_model=ModelsResponse,
|
||||
summary="列出可用离线模型",
|
||||
description=_get_openai_model_description(),
|
||||
)
|
||||
async def list_models(request: Request):
|
||||
"""列出可用离线模型 (OpenAI 兼容)"""
|
||||
result, _ = validate_openai_token(request)
|
||||
if not result:
|
||||
response_data = create_error_response(
|
||||
error_code="AUTHENTICATION_FAILED",
|
||||
message="Invalid authentication",
|
||||
)
|
||||
return JSONResponse(content=response_data, status_code=401)
|
||||
|
||||
try:
|
||||
# 使用动态模型列表
|
||||
model_ids = get_offline_model_ids()
|
||||
|
||||
model_objects = []
|
||||
for model_id in model_ids:
|
||||
model_objects.append(ModelObject(
|
||||
id=model_id,
|
||||
owned_by="qwen3-asr",
|
||||
))
|
||||
|
||||
return ModelsResponse(data=model_objects)
|
||||
except Exception as e:
|
||||
logger.error(f"获取模型列表失败: {e}")
|
||||
raise HTTPException(status_code=500, detail=str(e))
|
||||
|
||||
|
||||
def _get_transcription_description() -> str:
|
||||
"""获取动态的转写端点描述"""
|
||||
return f"""将音频文件转写为文本(完全兼容 OpenAI Audio API)。
|
||||
|
||||
**支持的音频格式与常见含音轨视频容器:**
|
||||
`mp3`, `mp4`, `mpeg`, `mpga`, `m4a`, `wav`, `webm`, `flac`, `ogg`, `amr`, `pcm`, `mov`, `mkv`, `avi`
|
||||
|
||||
**音频输入方式:**
|
||||
1. **文件上传**:通过 `file` 参数上传音频/视频文件(标准 OpenAI 方式)
|
||||
2. **URL/本地路径读取**:通过 `audio_address` 参数提供音频/视频文件 URL(HTTP/HTTPS)或服务端本地路径
|
||||
|
||||
如果同时提供 `file` 和 `audio_address`,服务会优先使用 `file`,并忽略 `audio_address`。
|
||||
|
||||
**文件大小限制:**
|
||||
- 最大支持 {settings.MAX_AUDIO_SIZE // (1024 * 1024)}MB(可通过 `MAX_AUDIO_SIZE` 环境变量配置)
|
||||
- OpenAI 原生限制为 25MB
|
||||
|
||||
**说话人分离:**
|
||||
- 默认开启 (`enable_speaker_diarization=true`)
|
||||
- 启用后 `verbose_json` 格式的 segments 会包含 `speaker` 字段(如 "说话人1")
|
||||
- 可设置 `enable_speaker_diarization=false` 关闭
|
||||
|
||||
**增强选项:**
|
||||
- `enable_speaker_identification=true` 时会尝试匹配已注册声纹库,仅在说话人分离开启时生效
|
||||
- `enable_text_cleanup=true` 时会执行文本去重、跨段重叠裁剪和口头语清理
|
||||
- `hotwords` 可传热词字符串,格式:`热词1 权重1 热词2 权重2`
|
||||
|
||||
**输出格式:**
|
||||
| 格式 | Content-Type | 说明 |
|
||||
|------|-------------|------|
|
||||
| `json` | application/json | 简单 JSON,仅含 text 字段(默认) |
|
||||
| `text` | text/plain | 纯文本 |
|
||||
| `verbose_json` | application/json | 详细 JSON,含时间戳、分段和说话人 |
|
||||
| `srt` | text/plain | SRT 字幕格式 |
|
||||
| `vtt` | text/vtt | WebVTT 字幕格式 |
|
||||
|
||||
**模型选择:**
|
||||
- 默认使用当前服务启用的 Qwen3-ASR 模型
|
||||
- 可通过可选 `model` 表单字段指定当前可用离线模型
|
||||
- 通过 `QWEN3_ASR_MODEL` 控制服务端默认模型型号
|
||||
- `/v1/models` 仍可用于查看当前服务端实际在线模型
|
||||
|
||||
**兼容参数:**
|
||||
`prompt`、`temperature`、`timestamp_granularities` 参数已保留;其中 `prompt` 可作为热词提示的兼容入口
|
||||
"""
|
||||
|
||||
|
||||
@router.post(
|
||||
"/audio/transcriptions",
|
||||
summary="音频转写",
|
||||
description=_get_transcription_description(),
|
||||
responses={
|
||||
200: {
|
||||
"description": "转写成功",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"example": {"text": "今天天气不错,明天可能会下雨。"}
|
||||
},
|
||||
"text/plain": {
|
||||
"example": "今天天气不错,明天可能会下雨。"
|
||||
},
|
||||
},
|
||||
},
|
||||
400: {
|
||||
"description": "请求错误",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"example": {
|
||||
"error_code": "INVALID_PARAMETER",
|
||||
"message": f"File too large. Maximum size is {settings.MAX_AUDIO_SIZE // (1024 * 1024)}MB",
|
||||
"task_id": "",
|
||||
"timestamp": "2025-01-31T12:00:00Z",
|
||||
"details": {}
|
||||
}
|
||||
}
|
||||
},
|
||||
},
|
||||
401: {
|
||||
"description": "认证失败",
|
||||
"content": {
|
||||
"application/json": {
|
||||
"example": {
|
||||
"error_code": "AUTHENTICATION_FAILED",
|
||||
"message": "Invalid API key",
|
||||
"task_id": "",
|
||||
"timestamp": "2025-01-31T12:00:00Z",
|
||||
"details": {}
|
||||
}
|
||||
}
|
||||
},
|
||||
},
|
||||
},
|
||||
)
|
||||
async def create_transcription(
|
||||
request: Request,
|
||||
# 1. 音频输入(二选一)
|
||||
file: Optional[UploadFile] = File(
|
||||
default=None,
|
||||
description="要转写的音频/视频文件。若同时提供 audio_address,服务会优先使用这里上传的文件"
|
||||
),
|
||||
audio_address: Optional[str] = Form(
|
||||
default=None,
|
||||
description="音频/视频文件地址,支持 HTTP/HTTPS URL、file:// 或服务端本地路径。仅当 file 为空时使用;若同时上传 file,服务会忽略此参数",
|
||||
json_schema_extra={"example": "https://media.cdn.vect.one/podcast_demo.mp4"},
|
||||
),
|
||||
model: Optional[str] = Form(
|
||||
default=None,
|
||||
description="可选。离线 ASR 模型 ID;不传则使用服务当前默认模型",
|
||||
examples=["qwen3-asr-0.6b"],
|
||||
),
|
||||
language: Optional[str] = Form(
|
||||
None,
|
||||
description="音频语言代码(ISO-639-1),如 zh/en/ja,不填则自动检测",
|
||||
examples=["zh", "en", "ja"],
|
||||
),
|
||||
# 4. 功能开关
|
||||
enable_speaker_diarization: bool = Form(
|
||||
True,
|
||||
description="是否启用说话人分离(默认开启)。启用后响应 segments 会包含 speaker 字段"
|
||||
),
|
||||
enable_speaker_identification: bool = Form(
|
||||
True,
|
||||
description="是否匹配已注册声纹库。仅在 enable_speaker_diarization=true 时生效"
|
||||
),
|
||||
enable_text_cleanup: bool = Form(
|
||||
True,
|
||||
description="是否启用文本去重、跨段重叠裁剪和口头语清理"
|
||||
),
|
||||
hotwords: Optional[str] = Form(
|
||||
None,
|
||||
description="热词字符串,格式:热词1 权重1 热词2 权重2"
|
||||
),
|
||||
# 5. 输出选项
|
||||
response_format: ResponseFormat = Form(
|
||||
ResponseFormat.VERBOSE_JSON,
|
||||
description="输出格式",
|
||||
examples=["verbose_json", "json", "text", "srt", "vtt"],
|
||||
),
|
||||
# 6. 兼容性参数(暂不支持)
|
||||
prompt: Optional[str] = Form(None, description="提示文本(暂不支持,保留兼容)"), # noqa: ARG001
|
||||
temperature: Optional[float] = Form(0, description="采样温度(暂不支持,保留兼容)"), # noqa: ARG001
|
||||
timestamp_granularities: Optional[List[str]] = Form( # noqa: ARG001
|
||||
None,
|
||||
alias="timestamp_granularities[]",
|
||||
description="时间戳粒度(暂不支持,保留兼容)"
|
||||
),
|
||||
):
|
||||
"""音频转写 API (OpenAI Audio API 兼容)"""
|
||||
# 标记暂不支持的参数(保留以兼容 OpenAI API)
|
||||
_ = (temperature, timestamp_granularities)
|
||||
hotword_text = (hotwords or prompt or "").strip()
|
||||
form_data = await request.form()
|
||||
requested_word_timestamps = _parse_hidden_bool(form_data.get("word_timestamps"))
|
||||
word_timestamps = settings.ASR_ENABLE_WORD_TIMESTAMPS and requested_word_timestamps
|
||||
|
||||
prepared_audio: Optional[PreparedAudio] = None
|
||||
response_cleanup_managed = False
|
||||
|
||||
logger.info(f"[OpenAI API] 收到转写请求: model={model or 'default'}, format={response_format}, "
|
||||
f"speaker_diarization={enable_speaker_diarization}, word_level={word_timestamps}, "
|
||||
f"audio_address={'有' if audio_address else '无'}")
|
||||
|
||||
# 验证输入:至少提供一种输入源;若二者同时存在,优先 file
|
||||
if not file and not audio_address:
|
||||
response_data = create_error_response(
|
||||
error_code="INVALID_PARAMETER",
|
||||
message="必须提供 file(上传文件)或 audio_address(音频 URL)其中之一",
|
||||
)
|
||||
return JSONResponse(content=response_data, status_code=400)
|
||||
|
||||
transcription_service = get_offline_transcription_service()
|
||||
|
||||
try:
|
||||
result, _ = validate_openai_token(request)
|
||||
if not result:
|
||||
response_data = create_error_response(
|
||||
error_code="AUTHENTICATION_FAILED",
|
||||
message="Invalid authentication",
|
||||
)
|
||||
return JSONResponse(content=response_data, status_code=401)
|
||||
|
||||
model_id = validate_offline_model_id(model)
|
||||
|
||||
# 处理音频输入:优先 file,其次 audio_address
|
||||
if file is not None:
|
||||
if audio_address:
|
||||
logger.info("[OpenAI API] 检测到同时提供 file 和 audio_address,已忽略 audio_address")
|
||||
|
||||
logger.info(f"[OpenAI API] 从上传文件读取音频: {file.filename}")
|
||||
audio_data = await file.read()
|
||||
|
||||
prepared_audio = await transcription_service.prepare_upload(
|
||||
audio_data=audio_data,
|
||||
filename=file.filename if file else None,
|
||||
task_id=f"openai-{int(time.time() * 1000)}",
|
||||
sample_rate=16000,
|
||||
)
|
||||
else:
|
||||
logger.info(f"[OpenAI API] 从 URL 下载音频: {audio_address}")
|
||||
prepared_audio = await transcription_service.prepare_from_request(
|
||||
request=request,
|
||||
audio_address=audio_address,
|
||||
task_id=f"openai-{int(time.time() * 1000)}",
|
||||
sample_rate=16000,
|
||||
)
|
||||
|
||||
inference_coro = transcription_service.transcribe(
|
||||
prepared_audio,
|
||||
OfflineTranscriptionOptions(
|
||||
model_id=model_id,
|
||||
sample_rate=16000,
|
||||
hotwords=hotword_text,
|
||||
enable_speaker_diarization=enable_speaker_diarization,
|
||||
enable_speaker_identification=(
|
||||
enable_speaker_diarization and enable_speaker_identification
|
||||
),
|
||||
enable_text_cleanup=enable_text_cleanup,
|
||||
word_timestamps=word_timestamps,
|
||||
),
|
||||
)
|
||||
audio_duration = prepared_audio.duration
|
||||
|
||||
# 根据 response_format 返回不同格式
|
||||
if response_format == ResponseFormat.TEXT:
|
||||
asr_result = await inference_coro
|
||||
logger.info(f"[OpenAI API] 识别完成: {len(asr_result.text)} 字符")
|
||||
payload, _, _ = build_transcription_payload(
|
||||
response_format=response_format,
|
||||
asr_result=asr_result,
|
||||
audio_duration=audio_duration,
|
||||
language=language,
|
||||
)
|
||||
return PlainTextResponse(content=payload)
|
||||
|
||||
elif response_format == ResponseFormat.SRT:
|
||||
asr_result = await inference_coro
|
||||
logger.info(f"[OpenAI API] 识别完成: {len(asr_result.text)} 字符")
|
||||
payload, _, _ = build_transcription_payload(
|
||||
response_format=response_format,
|
||||
asr_result=asr_result,
|
||||
audio_duration=audio_duration,
|
||||
language=language,
|
||||
)
|
||||
return PlainTextResponse(content=payload, media_type="text/plain")
|
||||
|
||||
elif response_format == ResponseFormat.VTT:
|
||||
asr_result = await inference_coro
|
||||
logger.info(f"[OpenAI API] 识别完成: {len(asr_result.text)} 字符")
|
||||
payload, _, _ = build_transcription_payload(
|
||||
response_format=response_format,
|
||||
asr_result=asr_result,
|
||||
audio_duration=audio_duration,
|
||||
language=language,
|
||||
)
|
||||
return PlainTextResponse(content=payload, media_type="text/vtt")
|
||||
|
||||
elif response_format in {ResponseFormat.VERBOSE_JSON, ResponseFormat.JSON}:
|
||||
response_cleanup_managed = True
|
||||
return create_heartbeat_streaming_response(
|
||||
response_format=response_format,
|
||||
inference_coro=inference_coro,
|
||||
audio_duration=audio_duration,
|
||||
language=language,
|
||||
cleanup_callback=lambda: transcription_service.cleanup(prepared_audio),
|
||||
)
|
||||
|
||||
else:
|
||||
asr_result = await inference_coro
|
||||
logger.info(f"[OpenAI API] 识别完成: {len(asr_result.text)} 字符")
|
||||
payload, _, _ = build_transcription_payload(
|
||||
response_format=ResponseFormat.JSON,
|
||||
asr_result=asr_result,
|
||||
audio_duration=audio_duration,
|
||||
language=language,
|
||||
)
|
||||
return JSONResponse(content=payload)
|
||||
|
||||
except HTTPException as http_exc:
|
||||
# 将 HTTPException 转换为标准错误格式
|
||||
logger.error(f"[OpenAI API] HTTP异常: {http_exc.detail}")
|
||||
|
||||
response_data = create_error_response(
|
||||
error_code="DEFAULT_CLIENT_ERROR" if http_exc.status_code < 500 else "DEFAULT_SERVER_ERROR",
|
||||
message=http_exc.detail,
|
||||
)
|
||||
return JSONResponse(content=response_data, status_code=http_exc.status_code)
|
||||
except InvalidParameterException as e:
|
||||
logger.error(f"[OpenAI API] 参数异常: {e.message}")
|
||||
response_data = create_error_response(
|
||||
error_code=e.error_code,
|
||||
message=e.message,
|
||||
details=e.details,
|
||||
)
|
||||
return JSONResponse(content=response_data, status_code=400)
|
||||
except Exception as e:
|
||||
logger.error(f"[OpenAI API] 转写失败: {e}")
|
||||
|
||||
# 使用标准错误格式
|
||||
response_data = create_error_response(
|
||||
error_code="DEFAULT_SERVER_ERROR",
|
||||
message=str(e),
|
||||
)
|
||||
return JSONResponse(content=response_data, status_code=500)
|
||||
|
||||
finally:
|
||||
if not response_cleanup_managed:
|
||||
transcription_service.cleanup(prepared_audio)
|
||||
|
|
@ -0,0 +1,47 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""WebSocket ASR API routes."""
|
||||
|
||||
import logging
|
||||
import time
|
||||
import uuid
|
||||
from typing import Optional
|
||||
|
||||
from fastapi import APIRouter, WebSocket
|
||||
|
||||
from ...services.qwen3_websocket_asr import Qwen3ASRService
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
router = APIRouter(prefix="/ws/v1/asr", tags=["WebSocket ASR"])
|
||||
|
||||
|
||||
@router.websocket("/funasr")
|
||||
async def funasr_websocket(websocket: WebSocket) -> None:
|
||||
await websocket.accept()
|
||||
task_id = f"deprecated_funasr_ws_{int(time.time())}_{id(websocket)}"
|
||||
try:
|
||||
await websocket.send_json(
|
||||
{
|
||||
"type": "error",
|
||||
"task_id": task_id,
|
||||
"code": "FUNASR_REALTIME_REMOVED",
|
||||
"message": "FunASR/Paraformer realtime websocket has been removed. Use /ws/v1/asr/qwen instead.",
|
||||
}
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
finally:
|
||||
await websocket.close(code=1008, reason="Use /ws/v1/asr/qwen")
|
||||
|
||||
|
||||
_qwen3_service = Qwen3ASRService()
|
||||
|
||||
|
||||
@router.websocket("")
|
||||
@router.websocket("/qwen")
|
||||
async def qwen_asr_websocket(
|
||||
websocket: WebSocket,
|
||||
task_id: Optional[str] = None,
|
||||
) -> None:
|
||||
if task_id is None:
|
||||
task_id = str(uuid.uuid4())[:8]
|
||||
await _qwen3_service.handle_connection(websocket, task_id)
|
||||
|
|
@ -0,0 +1,58 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Shared bootstrap helpers for process startup."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import sys
|
||||
|
||||
|
||||
def ensure_models_downloaded(interactive: bool) -> bool:
|
||||
"""Ensure declared deployment models exist locally, downloading if needed."""
|
||||
try:
|
||||
from app.utils.download_models import check_all_models, download_models
|
||||
|
||||
missing = check_all_models()
|
||||
if not missing:
|
||||
return True
|
||||
|
||||
print(f"\n⚠️ 检测到 {len(missing)} 个模型未下载")
|
||||
for model_id, *_ in missing:
|
||||
print(f" - {model_id}")
|
||||
|
||||
print("\n将自动下载缺失模型后继续启动。")
|
||||
if download_models(auto_mode=True):
|
||||
return True
|
||||
|
||||
print("\n模型自动下载失败。")
|
||||
if interactive:
|
||||
print("可手动运行以下命令排查:")
|
||||
print(" uv run python -m app.utils.download_models")
|
||||
print(" ./scripts/prepare-models.sh")
|
||||
else:
|
||||
print("非交互式终端下请确认网络可用,或预先准备模型缓存。")
|
||||
return False
|
||||
except Exception as exc:
|
||||
print(f"⚠️ 模型检查失败: {exc}")
|
||||
return False
|
||||
|
||||
|
||||
def run_cli_preflight() -> bool:
|
||||
"""Preflight checks for the CLI entrypoint."""
|
||||
try:
|
||||
from app.core.accelerator import get_accelerator_info, validate_accelerator_runtime
|
||||
|
||||
ok, message = validate_accelerator_runtime()
|
||||
info = get_accelerator_info()
|
||||
print(
|
||||
"Accelerator | "
|
||||
f"vendor={info.vendor} runtime={info.runtime} device={info.device} "
|
||||
f"count={info.device_count}"
|
||||
)
|
||||
if not ok:
|
||||
print(f"加速器运行栈检查失败: {message}")
|
||||
return False
|
||||
except Exception as exc:
|
||||
print(f"加速器检查失败: {exc}")
|
||||
return False
|
||||
|
||||
return ensure_models_downloaded(interactive=sys.stdin.isatty())
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
核心模块
|
||||
包含配置、异常、安全等基础组件
|
||||
"""
|
||||
|
|
@ -0,0 +1,162 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Unified accelerator detection and runtime validation."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from functools import lru_cache
|
||||
from typing import Optional
|
||||
|
||||
from .accelerators import (
|
||||
AcceleratorInfo,
|
||||
IluvatarAcceleratorAdapter,
|
||||
MetaxAcceleratorAdapter,
|
||||
MThreadsAcceleratorAdapter,
|
||||
NvidiaAcceleratorAdapter,
|
||||
)
|
||||
|
||||
SUPPORTED_ACCELERATORS = {"auto", "cpu", "nvidia", "metax", "iluvatar", "mthreads"}
|
||||
|
||||
|
||||
def _cpu_info(reason: str = "") -> AcceleratorInfo:
|
||||
return AcceleratorInfo(
|
||||
vendor="cpu",
|
||||
runtime="cpu",
|
||||
device="cpu",
|
||||
available=True,
|
||||
reason=reason,
|
||||
)
|
||||
|
||||
|
||||
def _normalize_configured(configured: Optional[str]) -> str:
|
||||
value = (configured or os.getenv("ACCELERATOR") or "auto").strip().lower()
|
||||
if value == "cuda":
|
||||
return "nvidia"
|
||||
if value in {"maca", "muxi", "mx"}:
|
||||
return "metax"
|
||||
if value in {"ix", "tianshu", "天数"}:
|
||||
return "iluvatar"
|
||||
if value in {"mthreads", "musa", "moorethreads", "摩尔线程"}:
|
||||
return "mthreads"
|
||||
if value not in SUPPORTED_ACCELERATORS:
|
||||
raise ValueError(
|
||||
f"Unsupported ACCELERATOR={value!r}; expected one of: "
|
||||
f"{', '.join(sorted(SUPPORTED_ACCELERATORS))}"
|
||||
)
|
||||
return value
|
||||
|
||||
|
||||
def _detect_uncached(configured: Optional[str]) -> AcceleratorInfo:
|
||||
accelerator = _normalize_configured(configured)
|
||||
if accelerator == "cpu":
|
||||
return _cpu_info("forced by ACCELERATOR=cpu")
|
||||
|
||||
if accelerator == "nvidia":
|
||||
return NvidiaAcceleratorAdapter().detect()
|
||||
|
||||
if accelerator == "metax":
|
||||
return MetaxAcceleratorAdapter().detect()
|
||||
|
||||
if accelerator == "iluvatar":
|
||||
return IluvatarAcceleratorAdapter().detect()
|
||||
|
||||
if accelerator == "mthreads":
|
||||
return MThreadsAcceleratorAdapter().detect()
|
||||
|
||||
# Auto mode prefers vendor SMI commands before NVIDIA. This avoids a vendor
|
||||
# PyTorch build exposing torch.cuda and being mistaken for NVIDIA.
|
||||
metax = MetaxAcceleratorAdapter().detect()
|
||||
if metax.available:
|
||||
return metax
|
||||
|
||||
iluvatar = IluvatarAcceleratorAdapter().detect()
|
||||
if iluvatar.available:
|
||||
return iluvatar
|
||||
|
||||
mthreads = MThreadsAcceleratorAdapter().detect()
|
||||
if mthreads.available:
|
||||
return mthreads
|
||||
|
||||
nvidia = NvidiaAcceleratorAdapter().detect()
|
||||
if nvidia.available:
|
||||
return nvidia
|
||||
|
||||
return _cpu_info("no supported accelerator detected")
|
||||
|
||||
|
||||
@lru_cache(maxsize=8)
|
||||
def _detect_cached(configured: str) -> AcceleratorInfo:
|
||||
return _detect_uncached(configured)
|
||||
|
||||
|
||||
def detect_accelerator(configured: Optional[str] = None, *, refresh: bool = False) -> AcceleratorInfo:
|
||||
"""Detect the active accelerator.
|
||||
|
||||
Args:
|
||||
configured: Optional override matching ACCELERATOR values.
|
||||
refresh: Clear cached detection before probing.
|
||||
"""
|
||||
normalized = _normalize_configured(configured)
|
||||
if refresh:
|
||||
_detect_cached.cache_clear()
|
||||
return _detect_cached(normalized)
|
||||
|
||||
|
||||
def get_accelerator_info(*, refresh: bool = False) -> AcceleratorInfo:
|
||||
try:
|
||||
from app.core.config import settings
|
||||
|
||||
configured = settings.ACCELERATOR
|
||||
except Exception:
|
||||
configured = os.getenv("ACCELERATOR", "auto")
|
||||
return detect_accelerator(configured, refresh=refresh)
|
||||
|
||||
|
||||
def validate_accelerator_runtime() -> tuple[bool, str]:
|
||||
"""Validate explicit accelerator selections before model loading."""
|
||||
try:
|
||||
from app.core.config import settings
|
||||
|
||||
configured = _normalize_configured(settings.ACCELERATOR)
|
||||
except Exception:
|
||||
configured = _normalize_configured(os.getenv("ACCELERATOR", "auto"))
|
||||
|
||||
info = detect_accelerator(configured, refresh=True)
|
||||
if configured in {"auto", "cpu", ""}:
|
||||
return True, ""
|
||||
|
||||
if not info.available:
|
||||
return False, f"ACCELERATOR={configured} requested but {info.reason}"
|
||||
|
||||
if configured == "metax" and not info.metadata.get("torch_cuda_available"):
|
||||
return (
|
||||
False,
|
||||
"ACCELERATOR=metax detected mx-smi devices, but the active Python "
|
||||
"environment does not expose torch.cuda. Run ./scripts/sync_metax_env.sh "
|
||||
"or install the MetaX MACA PyTorch stack.",
|
||||
)
|
||||
|
||||
if configured == "iluvatar" and not info.metadata.get("torch_cuda_available"):
|
||||
return (
|
||||
False,
|
||||
"ACCELERATOR=iluvatar detected ixsmi devices, but the active Python "
|
||||
"environment does not expose torch.cuda. Use the official Iluvatar "
|
||||
"vLLM image as the base image or install the Iluvatar PyTorch stack.",
|
||||
)
|
||||
|
||||
if configured == "mthreads" and not info.metadata.get("torch_cuda_available"):
|
||||
return (
|
||||
False,
|
||||
"ACCELERATOR=mthreads detected mthreads-gmi devices, but the active Python "
|
||||
"environment does not expose torch.cuda. Use the official Moore Threads "
|
||||
"MUSA vLLM image as the base image or install the matching MUSA PyTorch stack.",
|
||||
)
|
||||
|
||||
if configured == "nvidia" and not info.metadata.get("torch_cuda_available"):
|
||||
return (
|
||||
False,
|
||||
"ACCELERATOR=nvidia detected NVIDIA devices, but torch.cuda is not "
|
||||
"available in the active Python environment. Run ./scripts/sync_gpu_env.sh.",
|
||||
)
|
||||
|
||||
return True, ""
|
||||
|
|
@ -0,0 +1,16 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Accelerator adapter exports."""
|
||||
|
||||
from .base import AcceleratorInfo
|
||||
from .iluvatar import IluvatarAcceleratorAdapter
|
||||
from .metax import MetaxAcceleratorAdapter
|
||||
from .mthreads import MThreadsAcceleratorAdapter
|
||||
from .nvidia import NvidiaAcceleratorAdapter
|
||||
|
||||
__all__ = [
|
||||
"AcceleratorInfo",
|
||||
"IluvatarAcceleratorAdapter",
|
||||
"MetaxAcceleratorAdapter",
|
||||
"MThreadsAcceleratorAdapter",
|
||||
"NvidiaAcceleratorAdapter",
|
||||
]
|
||||
|
|
@ -0,0 +1,109 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Shared accelerator adapter primitives."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
import re
|
||||
import shutil
|
||||
import subprocess
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Optional, Protocol
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class AcceleratorInfo:
|
||||
"""Normalized hardware/runtime information used by the application."""
|
||||
|
||||
vendor: str
|
||||
runtime: str
|
||||
device: str
|
||||
device_count: int = 0
|
||||
visible_devices: tuple[str, ...] = ()
|
||||
total_memory_gb: float = 0.0
|
||||
smi_command: Optional[str] = None
|
||||
available: bool = False
|
||||
reason: str = ""
|
||||
metadata: dict[str, object] = field(default_factory=dict)
|
||||
|
||||
@property
|
||||
def is_gpu(self) -> bool:
|
||||
return self.vendor not in {"cpu", "unknown"} and self.available
|
||||
|
||||
def as_dict(self) -> dict[str, object]:
|
||||
return {
|
||||
"vendor": self.vendor,
|
||||
"runtime": self.runtime,
|
||||
"device": self.device,
|
||||
"device_count": self.device_count,
|
||||
"visible_devices": list(self.visible_devices),
|
||||
"total_memory_gb": self.total_memory_gb,
|
||||
"smi_command": self.smi_command,
|
||||
"available": self.available,
|
||||
"reason": self.reason,
|
||||
"metadata": self.metadata,
|
||||
}
|
||||
|
||||
@property
|
||||
def supports_sharded(self) -> bool:
|
||||
value = self.metadata.get("supports_sharded")
|
||||
return bool(value)
|
||||
|
||||
|
||||
class AcceleratorAdapter(Protocol):
|
||||
vendor: str
|
||||
runtime: str
|
||||
|
||||
def detect(self) -> AcceleratorInfo:
|
||||
"""Return normalized accelerator info."""
|
||||
|
||||
|
||||
def command_exists(command: str) -> bool:
|
||||
return shutil.which(command) is not None
|
||||
|
||||
|
||||
def run_command(command: list[str], timeout: float = 3.0) -> str:
|
||||
try:
|
||||
completed = subprocess.run(
|
||||
command,
|
||||
check=False,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
timeout=timeout,
|
||||
)
|
||||
except (OSError, subprocess.TimeoutExpired):
|
||||
return ""
|
||||
|
||||
if completed.returncode != 0:
|
||||
return ""
|
||||
return completed.stdout.strip()
|
||||
|
||||
|
||||
def parse_visible_devices(raw: str | None) -> tuple[str, ...]:
|
||||
value = (raw or "").strip()
|
||||
if not value or value.lower() in {"all", "none", "void"}:
|
||||
return ()
|
||||
return tuple(part.strip() for part in value.split(",") if part.strip())
|
||||
|
||||
|
||||
def first_env_devices(names: tuple[str, ...]) -> tuple[str, ...]:
|
||||
shared = parse_visible_devices(os.getenv("ASR_VISIBLE_DEVICES"))
|
||||
if shared:
|
||||
return shared
|
||||
for name in names:
|
||||
devices = parse_visible_devices(os.getenv(name))
|
||||
if devices:
|
||||
return devices
|
||||
return ()
|
||||
|
||||
|
||||
def parse_memory_gb(text: str) -> float:
|
||||
"""Parse the smallest memory value from common smi outputs."""
|
||||
values: list[float] = []
|
||||
for number, unit in re.findall(r"([0-9]+(?:\.[0-9]+)?)\s*(GiB|GB|MiB|MB)", text, re.I):
|
||||
value = float(number)
|
||||
normalized_unit = unit.lower()
|
||||
if normalized_unit in {"mib", "mb"}:
|
||||
value = value / 1024
|
||||
values.append(value)
|
||||
return min(values) if values else 0.0
|
||||
|
|
@ -0,0 +1,106 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Iluvatar/Tianshu accelerator adapter."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
|
||||
from .base import (
|
||||
AcceleratorInfo,
|
||||
command_exists,
|
||||
first_env_devices,
|
||||
parse_memory_gb,
|
||||
run_command,
|
||||
)
|
||||
|
||||
|
||||
class IluvatarAcceleratorAdapter:
|
||||
vendor = "iluvatar"
|
||||
runtime = "ix"
|
||||
smi_command = "ixsmi"
|
||||
visible_env_names = (
|
||||
"ILUVATAR_VISIBLE_DEVICES",
|
||||
"IX_VISIBLE_DEVICES",
|
||||
"CUDA_VISIBLE_DEVICES",
|
||||
)
|
||||
|
||||
def _query_device_count(self) -> tuple[int, str]:
|
||||
list_output = run_command([self.smi_command, "-L"])
|
||||
if list_output:
|
||||
lines = [line for line in list_output.splitlines() if line.strip()]
|
||||
gpu_lines = [
|
||||
line
|
||||
for line in lines
|
||||
if re.search(r"\b(gpu|device|card)\b", line, re.I)
|
||||
]
|
||||
return len(gpu_lines or lines), list_output
|
||||
|
||||
table_output = run_command([self.smi_command])
|
||||
if table_output:
|
||||
indexes = set(re.findall(r"(?:GPU|Device|Card)\s*[:#]?\s*([0-9]+)", table_output, re.I))
|
||||
if not indexes:
|
||||
indexes = set(re.findall(r"^\s*\|\s*([0-9]+)\s+", table_output, re.M))
|
||||
if indexes:
|
||||
return len(indexes), table_output
|
||||
if re.search(r"\bIluvatar\b|\b天数\b|\bIX\b", table_output, re.I):
|
||||
return 1, table_output
|
||||
|
||||
return 0, ""
|
||||
|
||||
def detect(self) -> AcceleratorInfo:
|
||||
visible_devices = first_env_devices(self.visible_env_names)
|
||||
smi_available = command_exists(self.smi_command)
|
||||
if not smi_available:
|
||||
return AcceleratorInfo(
|
||||
vendor=self.vendor,
|
||||
runtime=self.runtime,
|
||||
device="cpu",
|
||||
visible_devices=visible_devices,
|
||||
smi_command=None,
|
||||
available=False,
|
||||
reason="ixsmi not found",
|
||||
)
|
||||
|
||||
device_count, raw_output = self._query_device_count()
|
||||
if visible_devices:
|
||||
device_count = min(device_count or len(visible_devices), len(visible_devices))
|
||||
|
||||
torch_cuda_available = False
|
||||
torch_count = 0
|
||||
torch_memory_gb = 0.0
|
||||
torch_version = ""
|
||||
try:
|
||||
import torch
|
||||
|
||||
torch_version = getattr(torch, "__version__", "")
|
||||
torch_cuda_available = bool(torch.cuda.is_available())
|
||||
if torch_cuda_available:
|
||||
torch_count = int(torch.cuda.device_count())
|
||||
torch_memory_gb = min(
|
||||
torch.cuda.get_device_properties(i).total_memory / (1024**3)
|
||||
for i in range(torch_count)
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
if torch_count:
|
||||
device_count = min(torch_count, len(visible_devices)) if visible_devices else torch_count
|
||||
total_memory_gb = torch_memory_gb or parse_memory_gb(raw_output)
|
||||
available = device_count > 0
|
||||
|
||||
return AcceleratorInfo(
|
||||
vendor=self.vendor,
|
||||
runtime=self.runtime,
|
||||
device="cuda:0" if available else "cpu",
|
||||
device_count=device_count,
|
||||
visible_devices=visible_devices,
|
||||
total_memory_gb=total_memory_gb,
|
||||
smi_command=self.smi_command,
|
||||
available=available,
|
||||
reason="" if available else "ixsmi did not report any device",
|
||||
metadata={
|
||||
"torch_cuda_available": torch_cuda_available,
|
||||
"torch_version": torch_version,
|
||||
"supports_sharded": available,
|
||||
},
|
||||
)
|
||||
|
|
@ -0,0 +1,174 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""MetaX/MuXi MACA accelerator adapter."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import re
|
||||
from typing import Any
|
||||
|
||||
from .base import (
|
||||
AcceleratorInfo,
|
||||
command_exists,
|
||||
first_env_devices,
|
||||
parse_memory_gb,
|
||||
run_command,
|
||||
)
|
||||
|
||||
|
||||
class MetaxAcceleratorAdapter:
|
||||
vendor = "metax"
|
||||
runtime = "maca"
|
||||
smi_command = "mx-smi"
|
||||
visible_env_names = (
|
||||
"METAX_VISIBLE_DEVICES",
|
||||
"MACA_VISIBLE_DEVICES",
|
||||
"MX_VISIBLE_DEVICES",
|
||||
)
|
||||
|
||||
def _json_output(self, command: list[str]) -> Any:
|
||||
output = run_command(command)
|
||||
if not output:
|
||||
return None
|
||||
try:
|
||||
return json.loads(output)
|
||||
except json.JSONDecodeError:
|
||||
return None
|
||||
|
||||
def _walk_json(self, value: Any):
|
||||
if isinstance(value, dict):
|
||||
yield value
|
||||
for child in value.values():
|
||||
yield from self._walk_json(child)
|
||||
elif isinstance(value, list):
|
||||
for item in value:
|
||||
yield from self._walk_json(item)
|
||||
|
||||
def _count_from_json(self, value: Any) -> int:
|
||||
max_index = -1
|
||||
device_like = 0
|
||||
for item in self._walk_json(value):
|
||||
keys = {str(key).lower(): key for key in item.keys()}
|
||||
if any(key in keys for key in ("gpu id", "gpu_id", "gpu", "device id", "device_id", "index")):
|
||||
device_like += 1
|
||||
for key_name in ("gpu id", "gpu_id", "device id", "device_id", "index", "id"):
|
||||
original = keys.get(key_name)
|
||||
if original is None:
|
||||
continue
|
||||
try:
|
||||
max_index = max(max_index, int(item[original]))
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
if max_index >= 0:
|
||||
return max_index + 1
|
||||
return device_like
|
||||
|
||||
def _memory_from_json(self, value: Any) -> float:
|
||||
memory_values: list[float] = []
|
||||
for item in self._walk_json(value):
|
||||
for raw_key, raw_value in item.items():
|
||||
key = str(raw_key).lower()
|
||||
if not any(token in key for token in ("memory", "mem", "hbm", "vram", "容量")):
|
||||
continue
|
||||
if isinstance(raw_value, (int, float)):
|
||||
numeric = float(raw_value)
|
||||
# mx-smi reports are commonly MiB for memory counters.
|
||||
if numeric > 1024:
|
||||
numeric = numeric / 1024
|
||||
memory_values.append(numeric)
|
||||
continue
|
||||
if isinstance(raw_value, str):
|
||||
parsed = parse_memory_gb(raw_value)
|
||||
if parsed > 0:
|
||||
memory_values.append(parsed)
|
||||
return min(memory_values) if memory_values else 0.0
|
||||
|
||||
def _query_device_count(self) -> tuple[int, str]:
|
||||
json_info = self._json_output([self.smi_command, "-j"])
|
||||
json_count = self._count_from_json(json_info)
|
||||
if json_count > 0:
|
||||
return json_count, json.dumps(json_info, ensure_ascii=False)
|
||||
|
||||
list_output = run_command([self.smi_command, "-L"])
|
||||
if list_output:
|
||||
lines = [line for line in list_output.splitlines() if line.strip()]
|
||||
gpu_lines = [
|
||||
line
|
||||
for line in lines
|
||||
if re.search(r"\b(gpu|device|card)\b", line, re.I)
|
||||
]
|
||||
return len(gpu_lines or lines), list_output
|
||||
|
||||
table_output = run_command([self.smi_command])
|
||||
if table_output:
|
||||
indexes = set(re.findall(r"(?:GPU|Device|Card)\s*[:#]?\s*([0-9]+)", table_output, re.I))
|
||||
if not indexes:
|
||||
indexes = set(re.findall(r"^\s*\|\s*([0-9]+)\s+", table_output, re.M))
|
||||
return len(indexes), table_output
|
||||
|
||||
return 0, ""
|
||||
|
||||
def _query_memory_gb(self, fallback_output: str) -> float:
|
||||
for command in (
|
||||
[self.smi_command, "--show-memory", "-j"],
|
||||
[self.smi_command, "--show-hwinfo", "-j"],
|
||||
[self.smi_command, "-j"],
|
||||
):
|
||||
parsed = self._memory_from_json(self._json_output(command))
|
||||
if parsed > 0:
|
||||
return parsed
|
||||
|
||||
memory_output = run_command([self.smi_command, "--show-memory"])
|
||||
hwinfo_output = run_command([self.smi_command, "--show-hwinfo"])
|
||||
return (
|
||||
parse_memory_gb(memory_output)
|
||||
or parse_memory_gb(hwinfo_output)
|
||||
or parse_memory_gb(fallback_output)
|
||||
)
|
||||
|
||||
def detect(self) -> AcceleratorInfo:
|
||||
visible_devices = first_env_devices(self.visible_env_names)
|
||||
smi_available = command_exists(self.smi_command)
|
||||
if not smi_available:
|
||||
return AcceleratorInfo(
|
||||
vendor=self.vendor,
|
||||
runtime=self.runtime,
|
||||
device="cpu",
|
||||
visible_devices=visible_devices,
|
||||
smi_command=None,
|
||||
available=False,
|
||||
reason="mx-smi not found",
|
||||
)
|
||||
|
||||
device_count, raw_output = self._query_device_count()
|
||||
if visible_devices:
|
||||
device_count = min(device_count or len(visible_devices), len(visible_devices))
|
||||
total_memory_gb = self._query_memory_gb(raw_output)
|
||||
|
||||
torch_cuda_available = False
|
||||
torch_version = ""
|
||||
try:
|
||||
import torch
|
||||
|
||||
torch_version = getattr(torch, "__version__", "")
|
||||
torch_cuda_available = bool(torch.cuda.is_available())
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
available = device_count > 0
|
||||
return AcceleratorInfo(
|
||||
vendor=self.vendor,
|
||||
runtime=self.runtime,
|
||||
device="cuda:0" if available else "cpu",
|
||||
device_count=device_count,
|
||||
visible_devices=visible_devices,
|
||||
total_memory_gb=total_memory_gb,
|
||||
smi_command=self.smi_command,
|
||||
available=available,
|
||||
reason="" if available else "mx-smi did not report any device",
|
||||
metadata={
|
||||
"torch_cuda_available": torch_cuda_available,
|
||||
"torch_version": torch_version,
|
||||
"supports_sharded": available,
|
||||
},
|
||||
)
|
||||
|
|
@ -0,0 +1,114 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Moore Threads / MUSA accelerator adapter."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
|
||||
from .base import (
|
||||
AcceleratorInfo,
|
||||
command_exists,
|
||||
first_env_devices,
|
||||
parse_memory_gb,
|
||||
run_command,
|
||||
)
|
||||
|
||||
|
||||
class MThreadsAcceleratorAdapter:
|
||||
vendor = "mthreads"
|
||||
runtime = "musa"
|
||||
smi_command = "mthreads-gmi"
|
||||
visible_env_names = (
|
||||
"MTHREADS_VISIBLE_DEVICES",
|
||||
"MUSA_VISIBLE_DEVICES",
|
||||
"CUDA_VISIBLE_DEVICES",
|
||||
)
|
||||
|
||||
def _query_device_count(self) -> tuple[int, str]:
|
||||
for command in (
|
||||
[self.smi_command, "-L"],
|
||||
[self.smi_command, "list"],
|
||||
[self.smi_command],
|
||||
):
|
||||
output = run_command(command)
|
||||
if not output:
|
||||
continue
|
||||
lines = [line for line in output.splitlines() if line.strip()]
|
||||
gpu_lines = [
|
||||
line
|
||||
for line in lines
|
||||
if re.search(r"\b(gpu|device|card|musa|mthreads|moore)\b", line, re.I)
|
||||
]
|
||||
if gpu_lines:
|
||||
return len(gpu_lines), output
|
||||
|
||||
indexes = set(
|
||||
re.findall(r"(?:GPU|Device|Card)\s*[:#]?\s*([0-9]+)", output, re.I)
|
||||
)
|
||||
if not indexes:
|
||||
indexes = set(re.findall(r"^\s*\|\s*([0-9]+)\s+", output, re.M))
|
||||
if indexes:
|
||||
return len(indexes), output
|
||||
|
||||
if re.search(r"\bMUSA\b|\bMoore\s+Threads\b|\bMThreads\b", output, re.I):
|
||||
return max(len(lines), 1), output
|
||||
|
||||
return 0, ""
|
||||
|
||||
def detect(self) -> AcceleratorInfo:
|
||||
visible_devices = first_env_devices(self.visible_env_names)
|
||||
smi_available = command_exists(self.smi_command)
|
||||
if not smi_available:
|
||||
return AcceleratorInfo(
|
||||
vendor=self.vendor,
|
||||
runtime=self.runtime,
|
||||
device="cpu",
|
||||
visible_devices=visible_devices,
|
||||
smi_command=None,
|
||||
available=False,
|
||||
reason="mthreads-gmi not found",
|
||||
)
|
||||
|
||||
device_count, raw_output = self._query_device_count()
|
||||
if visible_devices:
|
||||
device_count = min(device_count or len(visible_devices), len(visible_devices))
|
||||
|
||||
torch_cuda_available = False
|
||||
torch_count = 0
|
||||
torch_memory_gb = 0.0
|
||||
torch_version = ""
|
||||
try:
|
||||
import torch
|
||||
|
||||
torch_version = getattr(torch, "__version__", "")
|
||||
torch_cuda_available = bool(torch.cuda.is_available())
|
||||
if torch_cuda_available:
|
||||
torch_count = int(torch.cuda.device_count())
|
||||
torch_memory_gb = min(
|
||||
torch.cuda.get_device_properties(i).total_memory / (1024**3)
|
||||
for i in range(torch_count)
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
if torch_count:
|
||||
device_count = min(torch_count, len(visible_devices)) if visible_devices else torch_count
|
||||
total_memory_gb = torch_memory_gb or parse_memory_gb(raw_output)
|
||||
available = device_count > 0
|
||||
|
||||
return AcceleratorInfo(
|
||||
vendor=self.vendor,
|
||||
runtime=self.runtime,
|
||||
device="cuda:0" if available else "cpu",
|
||||
device_count=device_count,
|
||||
visible_devices=visible_devices,
|
||||
total_memory_gb=total_memory_gb,
|
||||
smi_command=self.smi_command,
|
||||
available=available,
|
||||
reason="" if available else "mthreads-gmi did not report any device",
|
||||
metadata={
|
||||
"torch_cuda_available": torch_cuda_available,
|
||||
"torch_version": torch_version,
|
||||
"supports_sharded": available,
|
||||
},
|
||||
)
|
||||
|
|
@ -0,0 +1,85 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""NVIDIA CUDA accelerator adapter."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from .base import (
|
||||
AcceleratorInfo,
|
||||
command_exists,
|
||||
first_env_devices,
|
||||
parse_memory_gb,
|
||||
run_command,
|
||||
)
|
||||
|
||||
|
||||
class NvidiaAcceleratorAdapter:
|
||||
vendor = "nvidia"
|
||||
runtime = "cuda"
|
||||
smi_command = "nvidia-smi"
|
||||
|
||||
def detect(self) -> AcceleratorInfo:
|
||||
visible_devices = first_env_devices(("CUDA_VISIBLE_DEVICES",))
|
||||
smi_available = command_exists(self.smi_command)
|
||||
smi_count = 0
|
||||
smi_memory_gb = 0.0
|
||||
|
||||
if smi_available:
|
||||
indexes_output = run_command(
|
||||
[
|
||||
self.smi_command,
|
||||
"--query-gpu=index",
|
||||
"--format=csv,noheader,nounits",
|
||||
]
|
||||
)
|
||||
if indexes_output:
|
||||
smi_count = len([line for line in indexes_output.splitlines() if line.strip()])
|
||||
memory_output = run_command(
|
||||
[
|
||||
self.smi_command,
|
||||
"--query-gpu=memory.total",
|
||||
"--format=csv,noheader",
|
||||
]
|
||||
)
|
||||
smi_memory_gb = parse_memory_gb(memory_output)
|
||||
|
||||
torch_available = False
|
||||
torch_count = 0
|
||||
torch_memory_gb = 0.0
|
||||
torch_version = ""
|
||||
try:
|
||||
import torch
|
||||
|
||||
torch_version = getattr(torch, "__version__", "")
|
||||
torch_available = bool(torch.cuda.is_available())
|
||||
if torch_available:
|
||||
torch_count = int(torch.cuda.device_count())
|
||||
torch_memory_gb = min(
|
||||
torch.cuda.get_device_properties(i).total_memory / (1024**3)
|
||||
for i in range(torch_count)
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
device_count = torch_count or smi_count
|
||||
if visible_devices:
|
||||
device_count = min(device_count or len(visible_devices), len(visible_devices))
|
||||
total_memory_gb = torch_memory_gb or smi_memory_gb
|
||||
available = bool(torch_available or smi_count > 0)
|
||||
reason = "" if available else "nvidia runtime not detected"
|
||||
|
||||
return AcceleratorInfo(
|
||||
vendor=self.vendor,
|
||||
runtime=self.runtime,
|
||||
device="cuda:0" if available else "cpu",
|
||||
device_count=device_count,
|
||||
visible_devices=visible_devices,
|
||||
total_memory_gb=total_memory_gb,
|
||||
smi_command=self.smi_command if smi_available else None,
|
||||
available=available,
|
||||
reason=reason,
|
||||
metadata={
|
||||
"torch_cuda_available": torch_available,
|
||||
"torch_version": torch_version,
|
||||
"supports_sharded": available,
|
||||
},
|
||||
)
|
||||
|
|
@ -0,0 +1,536 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
统一配置管理
|
||||
ASR语音识别配置选项
|
||||
"""
|
||||
|
||||
import os
|
||||
from typing import Optional
|
||||
from pathlib import Path
|
||||
|
||||
|
||||
class Settings:
|
||||
"""统一应用配置类"""
|
||||
|
||||
# 应用信息
|
||||
APP_NAME: str = "Qwen3-ASR Server"
|
||||
APP_VERSION: str = "1.0.1"
|
||||
APP_DESCRIPTION: str = "Qwen3-ASR speech recognition API service"
|
||||
|
||||
# 服务器配置
|
||||
HOST: str = "0.0.0.0"
|
||||
PORT: int = 8000
|
||||
DEBUG: bool = False
|
||||
|
||||
# 鉴权配置
|
||||
API_KEY: Optional[str] = None # 从环境变量API_KEY读取,如果为None则鉴权可选
|
||||
|
||||
# 设备配置
|
||||
ACCELERATOR: str = "auto" # auto, cpu, nvidia, metax, iluvatar, mthreads
|
||||
DEVICE: str = "auto" # auto, cpu, cuda:0
|
||||
ASR_DEPLOY_TOPOLOGY: str = "isolated" # isolated, sharded, auto
|
||||
|
||||
# 路径配置
|
||||
BASE_DIR: Path = Path(__file__).parent.parent.parent
|
||||
DATA_DIR: str = str(BASE_DIR / "data")
|
||||
TEMP_DIR: str = str(BASE_DIR / "data" / "temp")
|
||||
# 项目总模型目录。实际模型目录直接扁平化到:
|
||||
# /models/{Qwen,iic,damo,...}
|
||||
MODELS_DIR: str = str(BASE_DIR / "models")
|
||||
# ModelScope 会在 MODELSCOPE_CACHE 下创建 models/{publisher}/{model_name}。
|
||||
# 因此 cache 根目录应指向 models 的上一级,实际运行模型根目录仍由 MODELSCOPE_PATH 指定。
|
||||
MODELSCOPE_CACHE: str = str(BASE_DIR)
|
||||
MODELSCOPE_PATH: str = str(BASE_DIR / "models")
|
||||
|
||||
# 日志配置
|
||||
LOG_LEVEL: str = "INFO"
|
||||
LOG_FILE: Optional[str] = str(BASE_DIR / "data" / "logs" / "qwen3-asr.log")
|
||||
LOG_MAX_BYTES: int = 20 * 1024 * 1024 # 20MB
|
||||
LOG_BACKUP_COUNT: int = 50 # 保留50个备份文件
|
||||
|
||||
# ASR模型配置
|
||||
WS_MAX_BUFFER_SIZE: int = 10 * 16000 # WebSocket音频缓冲区最大大小(10秒@16kHz)
|
||||
|
||||
FUNASR_AUTOMODEL_KWARGS = {
|
||||
"trust_remote_code": False,
|
||||
"disable_update": True,
|
||||
"disable_pbar": True,
|
||||
"disable_log": True, # 禁用FunASR的tables输出
|
||||
"local_files_only": True, # 强制使用本地模型,禁止联网下载
|
||||
}
|
||||
ASR_MODELS_CONFIG: str = str(BASE_DIR / "app/services/asr/models.json")
|
||||
ASR_ENABLE_REALTIME_PUNC: bool = True # 是否启用实时标点模型(用于中间结果展示)
|
||||
VAD_MODEL: str = "damo/speech_fsmn_vad_zh-cn-16k-common-pytorch"
|
||||
PUNC_MODEL: str = "iic/punc_ct-transformer_zh-cn-common-vocab272727-pytorch"
|
||||
PUNC_REALTIME_MODEL: str = (
|
||||
"iic/punc_ct-transformer_zh-cn-common-vad_realtime-vocab272727"
|
||||
)
|
||||
|
||||
# 流式ASR远场过滤配置
|
||||
ASR_ENABLE_NEARFIELD_FILTER: bool = True # 是否启用远场声音过滤
|
||||
ASR_NEARFIELD_RMS_THRESHOLD: float = 0.01 # RMS能量阈值(宽松模式,适合大多数场景)
|
||||
# 音频处理配置
|
||||
MAX_AUDIO_SIZE: int = 2048 * 1024 * 1024 # 2GB
|
||||
|
||||
# 批处理推理配置(GPU 真并行)
|
||||
ASR_BATCH_SIZE: int = 4 # ASR 批处理大小(同时推理的片段数),建议 2-8
|
||||
ASR_ENABLE_WORD_TIMESTAMPS: bool = False # 全局字词级时间戳开关;关闭时不预热 forced aligner,接口参数也默认隐藏
|
||||
|
||||
# 音频分段配置
|
||||
MAX_SEGMENT_SEC: float = 60.0 # Max offline ASR segment duration in seconds.
|
||||
|
||||
# Runtime 并发配置(按 backend 独立控制)
|
||||
QWEN_VLLM_SHARED_CONCURRENCY: int = 8
|
||||
QWEN_VLLM_ENFORCE_EAGER: bool = True
|
||||
QWEN_RUST_CPU_WORKERS: int = 4
|
||||
QWEN_RUST_ASR_CONCURRENCY: int = 0
|
||||
QWEN_RUST_ALIGN_CONCURRENCY: int = 0
|
||||
FUNASR_WORKERS: int = 1
|
||||
|
||||
# 声纹数据库配置(与 Model-Test-New 使用同一套 PostgreSQL/pgvector 表结构)
|
||||
SPEAKER_DB_ENABLED: bool = True
|
||||
DB_USER: str = "postgres"
|
||||
DB_PASSWORD: str = "postgres"
|
||||
DB_NAME: str = "asr_db"
|
||||
DB_HOST: str = "127.0.0.1"
|
||||
DB_PORT: int = 5432
|
||||
DB_POOL_MAX_SIZE: int = 5
|
||||
SV_MODEL: str = "iic/speech_campplus_sv_zh-cn_16k-common"
|
||||
SV_MODEL_REVISION: str = "v2.0.2"
|
||||
REALTIME_SV_MODEL: str = "iic/speech_eres2netv2_sv_zh-cn_16k-common"
|
||||
REALTIME_SV_MODEL_REVISION: str = ""
|
||||
SV_THRESHOLD: float = 0.6
|
||||
REALTIME_MAX_SEGMENT_SEC: float = 12.0
|
||||
REALTIME_MAX_SEGMENT_TAIL_SEC: float = 1.6
|
||||
REALTIME_FORCE_STABLE_SEGMENT_SEC: float = 8.0
|
||||
REALTIME_FORCE_STABLE_MIN_CHARS: int = 24
|
||||
REALTIME_MIN_PARTIAL_SEC: float = 0.45
|
||||
REALTIME_PARTIAL_EMIT_INTERVAL_SEC: float = 0.25
|
||||
REALTIME_PARTIAL_WINDOW_SEC: float = 8.0
|
||||
REALTIME_STREAM_CHUNK_SEC: float = 1.2
|
||||
REALTIME_STREAM_MAX_PENDING_CHUNKS: int = 3
|
||||
REALTIME_STREAM_WINDOW_SEC: float = 8.0
|
||||
REALTIME_STREAM_STABLE_TAIL_CHARS: int = 8
|
||||
REALTIME_STREAM_STABLE_MIN_GROW_CHARS: int = 2
|
||||
REALTIME_STREAM_DIVERGENCE_TOLERANCE_CHARS: int = 2
|
||||
REALTIME_PARTIAL_HOLDBACK_CHARS: int = 6
|
||||
REALTIME_LONGFORM_MIN_SEC: float = 8.0
|
||||
REALTIME_LONGFORM_CHUNK_SEC: float = 6.0
|
||||
REALTIME_LONGFORM_OVERLAP_SEC: float = 1.2
|
||||
REALTIME_VAD_CHECK_INTERVAL_SEC: float = 0.8
|
||||
REALTIME_VAD_FINALIZE_SILENCE_SEC: float = 0.6
|
||||
REALTIME_FINAL_SEGMENT_SOFT_LIMIT_SEC: float = 8.0
|
||||
REALTIME_FINAL_SEGMENT_HARD_LIMIT_SEC: float = 12.0
|
||||
REALTIME_ENABLE_DIARIZATION: bool = True
|
||||
REALTIME_ENABLE_SEGMENT_REFINE: bool = False
|
||||
REALTIME_DIARIZATION_MIN_SEC: float = 3.0
|
||||
REALTIME_DIARIZATION_LOOKBACK_SEC: float = 3.0
|
||||
REALTIME_DIARIZATION_WINDOW_SEC: float = 15.0
|
||||
REALTIME_SPEAKER_MIN_SEC: float = 1.2
|
||||
REALTIME_SPEAKER_CLUSTER_THRESHOLD: float = 0.75
|
||||
REALTIME_UNKNOWN_SPK_CLUSTER_THRESHOLD: float = 0.58
|
||||
REALTIME_RECENT_UNKNOWN_SPK_THRESHOLD: float = 0.50
|
||||
REALTIME_SPEAKER_CONFIRM_THRESHOLD: float = 0.62
|
||||
REALTIME_REGISTRY_MIN_CLUSTER_CONFIDENCE: float = 0.72
|
||||
REALTIME_SPEAKER_MAX_SLOTS: int = 8
|
||||
REALTIME_SESSION_RESUME_TTL_SEC: int = 120 # WebSocket 断线后保留会话上下文的秒数;TTL 内同 session_id 可恢复
|
||||
API_PREFIX: str = "/api/v1"
|
||||
TASK_STATE_DIR: str = str(BASE_DIR / "data" / "tasks")
|
||||
TASK_RETENTION_HOURS: int = 24
|
||||
|
||||
def __init__(self):
|
||||
"""从环境变量读取配置"""
|
||||
self._load_from_env()
|
||||
self._ensure_directories()
|
||||
|
||||
def _load_from_env(self):
|
||||
"""从环境变量加载配置"""
|
||||
# 服务器配置
|
||||
self.HOST = os.getenv("HOST", self.HOST)
|
||||
self.PORT = int(os.getenv("PORT", str(self.PORT)))
|
||||
self.DEBUG = os.getenv("DEBUG", "false").lower() == "true"
|
||||
|
||||
self.DATA_DIR = os.getenv("DATA_DIR", self.DATA_DIR)
|
||||
self.TEMP_DIR = os.getenv("TEMP_DIR", self.TEMP_DIR)
|
||||
|
||||
# 日志配置
|
||||
self.LOG_LEVEL = os.getenv("LOG_LEVEL", self.LOG_LEVEL)
|
||||
self.LOG_FILE = os.getenv("LOG_FILE", self.LOG_FILE)
|
||||
self.LOG_MAX_BYTES = int(os.getenv("LOG_MAX_BYTES", str(self.LOG_MAX_BYTES)))
|
||||
self.LOG_BACKUP_COUNT = int(
|
||||
os.getenv("LOG_BACKUP_COUNT", str(self.LOG_BACKUP_COUNT))
|
||||
)
|
||||
|
||||
# 鉴权配置:空值/空白统一视为未配置
|
||||
self.API_KEY = (os.getenv("API_KEY") or "").strip() or None
|
||||
|
||||
# 设备配置
|
||||
self.ACCELERATOR = os.getenv("ACCELERATOR", self.ACCELERATOR)
|
||||
self.DEVICE = os.getenv("DEVICE", self.DEVICE)
|
||||
self.ASR_DEPLOY_TOPOLOGY = os.getenv(
|
||||
"ASR_DEPLOY_TOPOLOGY",
|
||||
self.ASR_DEPLOY_TOPOLOGY,
|
||||
).strip().lower()
|
||||
|
||||
# 模型缓存路径
|
||||
self.MODELS_DIR = os.getenv("MODELS_DIR", self.MODELS_DIR)
|
||||
self.MODELSCOPE_CACHE = os.getenv("MODELSCOPE_CACHE", self.MODELSCOPE_CACHE)
|
||||
self.MODELSCOPE_PATH = os.getenv("MODELSCOPE_PATH", self.MODELSCOPE_PATH)
|
||||
|
||||
# 给第三方库补齐默认缓存环境变量,允许用户自行覆盖
|
||||
os.environ.setdefault("MODELS_DIR", self.MODELS_DIR)
|
||||
os.environ.setdefault("MODELSCOPE_CACHE", self.MODELSCOPE_CACHE)
|
||||
os.environ.setdefault("MODELSCOPE_PATH", self.MODELSCOPE_PATH)
|
||||
|
||||
# ASR模型配置
|
||||
self.ASR_ENABLE_REALTIME_PUNC = (
|
||||
os.getenv("ASR_ENABLE_REALTIME_PUNC", "true").lower() == "true"
|
||||
)
|
||||
|
||||
# WebSocket缓冲区配置
|
||||
self.WS_MAX_BUFFER_SIZE = int(
|
||||
os.getenv("WS_MAX_BUFFER_SIZE", str(self.WS_MAX_BUFFER_SIZE))
|
||||
)
|
||||
|
||||
# 远场过滤配置
|
||||
self.ASR_ENABLE_NEARFIELD_FILTER = (
|
||||
os.getenv("ASR_ENABLE_NEARFIELD_FILTER", "true").lower() == "true"
|
||||
)
|
||||
self.ASR_NEARFIELD_RMS_THRESHOLD = float(
|
||||
os.getenv(
|
||||
"ASR_NEARFIELD_RMS_THRESHOLD", str(self.ASR_NEARFIELD_RMS_THRESHOLD)
|
||||
)
|
||||
)
|
||||
|
||||
# 音频处理配置
|
||||
# 支持简化格式:纯数字表示MB,或带单位(如 2048MB, 2GB)
|
||||
max_audio_size_str = os.getenv("MAX_AUDIO_SIZE")
|
||||
if max_audio_size_str:
|
||||
self.MAX_AUDIO_SIZE = self._parse_size(max_audio_size_str)
|
||||
|
||||
self.ASR_BATCH_SIZE = int(
|
||||
os.getenv("ASR_BATCH_SIZE", str(self.ASR_BATCH_SIZE))
|
||||
)
|
||||
self.ASR_ENABLE_WORD_TIMESTAMPS = (
|
||||
os.getenv(
|
||||
"ASR_ENABLE_WORD_TIMESTAMPS",
|
||||
str(self.ASR_ENABLE_WORD_TIMESTAMPS),
|
||||
).lower()
|
||||
== "true"
|
||||
)
|
||||
|
||||
self.MAX_SEGMENT_SEC = float(
|
||||
os.getenv("MAX_SEGMENT_SEC", str(self.MAX_SEGMENT_SEC))
|
||||
)
|
||||
|
||||
self.QWEN_VLLM_SHARED_CONCURRENCY = int(
|
||||
os.getenv(
|
||||
"QWEN_VLLM_SHARED_CONCURRENCY",
|
||||
str(self.QWEN_VLLM_SHARED_CONCURRENCY),
|
||||
)
|
||||
)
|
||||
self.QWEN_VLLM_ENFORCE_EAGER = (
|
||||
os.getenv(
|
||||
"QWEN_VLLM_ENFORCE_EAGER",
|
||||
str(self.QWEN_VLLM_ENFORCE_EAGER),
|
||||
).lower()
|
||||
== "true"
|
||||
)
|
||||
self.QWEN_RUST_CPU_WORKERS = int(
|
||||
os.getenv("QWEN_RUST_CPU_WORKERS", str(self.QWEN_RUST_CPU_WORKERS))
|
||||
)
|
||||
self.QWEN_RUST_ASR_CONCURRENCY = int(
|
||||
os.getenv("QWEN_RUST_ASR_CONCURRENCY", str(self.QWEN_RUST_ASR_CONCURRENCY))
|
||||
)
|
||||
self.QWEN_RUST_ALIGN_CONCURRENCY = int(
|
||||
os.getenv("QWEN_RUST_ALIGN_CONCURRENCY", str(self.QWEN_RUST_ALIGN_CONCURRENCY))
|
||||
)
|
||||
self.FUNASR_WORKERS = int(
|
||||
os.getenv("FUNASR_WORKERS", str(self.FUNASR_WORKERS))
|
||||
)
|
||||
|
||||
self.SPEAKER_DB_ENABLED = (
|
||||
os.getenv("SPEAKER_DB_ENABLED", str(self.SPEAKER_DB_ENABLED)).lower()
|
||||
== "true"
|
||||
)
|
||||
self.DB_USER = os.getenv("DB_USER", self.DB_USER)
|
||||
self.DB_PASSWORD = os.getenv("DB_PASSWORD", self.DB_PASSWORD)
|
||||
self.DB_NAME = os.getenv("DB_NAME", self.DB_NAME)
|
||||
self.DB_HOST = os.getenv("DB_HOST", self.DB_HOST)
|
||||
self.DB_PORT = int(os.getenv("DB_PORT", str(self.DB_PORT)))
|
||||
self.DB_POOL_MAX_SIZE = int(
|
||||
os.getenv("DB_POOL_MAX_SIZE", str(self.DB_POOL_MAX_SIZE))
|
||||
)
|
||||
self.SV_MODEL = os.getenv("SV_MODEL", self.SV_MODEL)
|
||||
self.SV_MODEL_REVISION = os.getenv("SV_MODEL_REVISION", self.SV_MODEL_REVISION)
|
||||
self.REALTIME_SV_MODEL = os.getenv("REALTIME_SV_MODEL", self.REALTIME_SV_MODEL)
|
||||
self.REALTIME_SV_MODEL_REVISION = os.getenv(
|
||||
"REALTIME_SV_MODEL_REVISION",
|
||||
self.REALTIME_SV_MODEL_REVISION,
|
||||
)
|
||||
self.SV_THRESHOLD = float(os.getenv("SV_THRESHOLD", str(self.SV_THRESHOLD)))
|
||||
self.REALTIME_MAX_SEGMENT_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_MAX_SEGMENT_SEC",
|
||||
str(self.REALTIME_MAX_SEGMENT_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_MAX_SEGMENT_TAIL_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_MAX_SEGMENT_TAIL_SEC",
|
||||
str(self.REALTIME_MAX_SEGMENT_TAIL_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_FORCE_STABLE_SEGMENT_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_FORCE_STABLE_SEGMENT_SEC",
|
||||
str(self.REALTIME_FORCE_STABLE_SEGMENT_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_FORCE_STABLE_MIN_CHARS = int(
|
||||
os.getenv(
|
||||
"REALTIME_FORCE_STABLE_MIN_CHARS",
|
||||
str(self.REALTIME_FORCE_STABLE_MIN_CHARS),
|
||||
)
|
||||
)
|
||||
self.REALTIME_MIN_PARTIAL_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_MIN_PARTIAL_SEC",
|
||||
str(self.REALTIME_MIN_PARTIAL_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_PARTIAL_EMIT_INTERVAL_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_PARTIAL_EMIT_INTERVAL_SEC",
|
||||
str(self.REALTIME_PARTIAL_EMIT_INTERVAL_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_PARTIAL_WINDOW_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_PARTIAL_WINDOW_SEC",
|
||||
str(self.REALTIME_PARTIAL_WINDOW_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_STREAM_CHUNK_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_STREAM_CHUNK_SEC",
|
||||
str(self.REALTIME_STREAM_CHUNK_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_STREAM_MAX_PENDING_CHUNKS = int(
|
||||
os.getenv(
|
||||
"REALTIME_STREAM_MAX_PENDING_CHUNKS",
|
||||
str(self.REALTIME_STREAM_MAX_PENDING_CHUNKS),
|
||||
)
|
||||
)
|
||||
self.REALTIME_STREAM_WINDOW_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_STREAM_WINDOW_SEC",
|
||||
str(self.REALTIME_STREAM_WINDOW_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_STREAM_STABLE_TAIL_CHARS = int(
|
||||
os.getenv(
|
||||
"REALTIME_STREAM_STABLE_TAIL_CHARS",
|
||||
str(self.REALTIME_STREAM_STABLE_TAIL_CHARS),
|
||||
)
|
||||
)
|
||||
self.REALTIME_STREAM_STABLE_MIN_GROW_CHARS = int(
|
||||
os.getenv(
|
||||
"REALTIME_STREAM_STABLE_MIN_GROW_CHARS",
|
||||
str(self.REALTIME_STREAM_STABLE_MIN_GROW_CHARS),
|
||||
)
|
||||
)
|
||||
self.REALTIME_STREAM_DIVERGENCE_TOLERANCE_CHARS = int(
|
||||
os.getenv(
|
||||
"REALTIME_STREAM_DIVERGENCE_TOLERANCE_CHARS",
|
||||
str(self.REALTIME_STREAM_DIVERGENCE_TOLERANCE_CHARS),
|
||||
)
|
||||
)
|
||||
self.REALTIME_PARTIAL_HOLDBACK_CHARS = int(
|
||||
os.getenv(
|
||||
"REALTIME_PARTIAL_HOLDBACK_CHARS",
|
||||
str(self.REALTIME_PARTIAL_HOLDBACK_CHARS),
|
||||
)
|
||||
)
|
||||
self.REALTIME_LONGFORM_MIN_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_LONGFORM_MIN_SEC",
|
||||
str(self.REALTIME_LONGFORM_MIN_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_LONGFORM_CHUNK_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_LONGFORM_CHUNK_SEC",
|
||||
str(self.REALTIME_LONGFORM_CHUNK_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_LONGFORM_OVERLAP_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_LONGFORM_OVERLAP_SEC",
|
||||
str(self.REALTIME_LONGFORM_OVERLAP_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_VAD_CHECK_INTERVAL_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_VAD_CHECK_INTERVAL_SEC",
|
||||
str(self.REALTIME_VAD_CHECK_INTERVAL_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_VAD_FINALIZE_SILENCE_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_VAD_FINALIZE_SILENCE_SEC",
|
||||
str(self.REALTIME_VAD_FINALIZE_SILENCE_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_FINAL_SEGMENT_SOFT_LIMIT_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_FINAL_SEGMENT_SOFT_LIMIT_SEC",
|
||||
str(self.REALTIME_FINAL_SEGMENT_SOFT_LIMIT_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_FINAL_SEGMENT_HARD_LIMIT_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_FINAL_SEGMENT_HARD_LIMIT_SEC",
|
||||
str(self.REALTIME_FINAL_SEGMENT_HARD_LIMIT_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_ENABLE_DIARIZATION = (
|
||||
os.getenv(
|
||||
"REALTIME_ENABLE_DIARIZATION",
|
||||
str(self.REALTIME_ENABLE_DIARIZATION),
|
||||
).lower()
|
||||
== "true"
|
||||
)
|
||||
self.REALTIME_ENABLE_SEGMENT_REFINE = (
|
||||
os.getenv(
|
||||
"REALTIME_ENABLE_SEGMENT_REFINE",
|
||||
str(self.REALTIME_ENABLE_SEGMENT_REFINE),
|
||||
).lower()
|
||||
== "true"
|
||||
)
|
||||
self.REALTIME_DIARIZATION_MIN_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_DIARIZATION_MIN_SEC",
|
||||
str(self.REALTIME_DIARIZATION_MIN_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_DIARIZATION_LOOKBACK_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_DIARIZATION_LOOKBACK_SEC",
|
||||
str(self.REALTIME_DIARIZATION_LOOKBACK_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_DIARIZATION_WINDOW_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_DIARIZATION_WINDOW_SEC",
|
||||
str(self.REALTIME_DIARIZATION_WINDOW_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_SPEAKER_MIN_SEC = float(
|
||||
os.getenv(
|
||||
"REALTIME_SPEAKER_MIN_SEC",
|
||||
str(self.REALTIME_SPEAKER_MIN_SEC),
|
||||
)
|
||||
)
|
||||
self.REALTIME_SPEAKER_CLUSTER_THRESHOLD = float(
|
||||
os.getenv(
|
||||
"REALTIME_SPEAKER_CLUSTER_THRESHOLD",
|
||||
str(self.REALTIME_SPEAKER_CLUSTER_THRESHOLD),
|
||||
)
|
||||
)
|
||||
self.REALTIME_UNKNOWN_SPK_CLUSTER_THRESHOLD = float(
|
||||
os.getenv(
|
||||
"REALTIME_UNKNOWN_SPK_CLUSTER_THRESHOLD",
|
||||
str(self.REALTIME_UNKNOWN_SPK_CLUSTER_THRESHOLD),
|
||||
)
|
||||
)
|
||||
self.REALTIME_RECENT_UNKNOWN_SPK_THRESHOLD = float(
|
||||
os.getenv(
|
||||
"REALTIME_RECENT_UNKNOWN_SPK_THRESHOLD",
|
||||
str(self.REALTIME_RECENT_UNKNOWN_SPK_THRESHOLD),
|
||||
)
|
||||
)
|
||||
self.REALTIME_SPEAKER_CONFIRM_THRESHOLD = float(
|
||||
os.getenv(
|
||||
"REALTIME_SPEAKER_CONFIRM_THRESHOLD",
|
||||
str(self.REALTIME_SPEAKER_CONFIRM_THRESHOLD),
|
||||
)
|
||||
)
|
||||
self.REALTIME_REGISTRY_MIN_CLUSTER_CONFIDENCE = float(
|
||||
os.getenv(
|
||||
"REALTIME_REGISTRY_MIN_CLUSTER_CONFIDENCE",
|
||||
str(self.REALTIME_REGISTRY_MIN_CLUSTER_CONFIDENCE),
|
||||
)
|
||||
)
|
||||
self.REALTIME_SPEAKER_MAX_SLOTS = int(
|
||||
os.getenv(
|
||||
"REALTIME_SPEAKER_MAX_SLOTS",
|
||||
str(self.REALTIME_SPEAKER_MAX_SLOTS),
|
||||
)
|
||||
)
|
||||
self.REALTIME_SESSION_RESUME_TTL_SEC = int(
|
||||
os.getenv(
|
||||
"REALTIME_SESSION_RESUME_TTL_SEC",
|
||||
str(self.REALTIME_SESSION_RESUME_TTL_SEC),
|
||||
)
|
||||
)
|
||||
self.API_PREFIX = os.getenv("API_PREFIX", self.API_PREFIX)
|
||||
self.TASK_STATE_DIR = os.getenv("TASK_STATE_DIR", self.TASK_STATE_DIR)
|
||||
self.TASK_RETENTION_HOURS = int(
|
||||
os.getenv("TASK_RETENTION_HOURS", str(self.TASK_RETENTION_HOURS))
|
||||
)
|
||||
|
||||
def _parse_size(self, size_str: str) -> int:
|
||||
"""解析带单位的大小字符串
|
||||
|
||||
支持格式:
|
||||
- 纯数字:视为 MB(如 2048 = 2048MB = 2147483648 bytes)
|
||||
- 带单位:如 2GB, 2048MB, 1.5GB
|
||||
"""
|
||||
size_str = size_str.strip().upper()
|
||||
|
||||
# 如果纯数字,视为 MB
|
||||
if size_str.isdigit():
|
||||
return int(size_str) * 1024 * 1024
|
||||
|
||||
# 带单位的处理
|
||||
if size_str.endswith('GB'):
|
||||
return int(float(size_str[:-2]) * 1024 * 1024 * 1024)
|
||||
elif size_str.endswith('MB'):
|
||||
return int(float(size_str[:-2]) * 1024 * 1024)
|
||||
elif size_str.endswith('KB'):
|
||||
return int(float(size_str[:-2]) * 1024)
|
||||
else:
|
||||
# 默认视为字节
|
||||
return int(size_str)
|
||||
|
||||
def _ensure_directories(self):
|
||||
"""确保必需的目录存在"""
|
||||
os.makedirs(self.TEMP_DIR, exist_ok=True)
|
||||
if self.LOG_FILE:
|
||||
os.makedirs(os.path.dirname(self.LOG_FILE), exist_ok=True)
|
||||
os.makedirs(self.MODELS_DIR, exist_ok=True)
|
||||
os.makedirs(self.MODELSCOPE_CACHE, exist_ok=True)
|
||||
os.makedirs(self.MODELSCOPE_PATH, exist_ok=True)
|
||||
os.makedirs(self.DATA_DIR, exist_ok=True)
|
||||
os.makedirs(self.TASK_STATE_DIR, exist_ok=True)
|
||||
|
||||
@property
|
||||
def models_config_path(self) -> str:
|
||||
"""获取模型配置文件的完整路径"""
|
||||
return str(self.BASE_DIR / self.ASR_MODELS_CONFIG)
|
||||
|
||||
@property
|
||||
def docs_url(self) -> Optional[str]:
|
||||
"""获取文档URL"""
|
||||
return "/docs"
|
||||
|
||||
@property
|
||||
def redoc_url(self) -> Optional[str]:
|
||||
"""获取ReDoc URL"""
|
||||
return "/redoc"
|
||||
|
||||
|
||||
# 全局配置实例
|
||||
settings = Settings()
|
||||
|
|
@ -0,0 +1,222 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""PostgreSQL/pgvector storage for registered speaker embeddings."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
from app.core.config import settings
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
try:
|
||||
import asyncpg
|
||||
except ImportError: # pragma: no cover - runtime dependency is installed in Docker images.
|
||||
asyncpg = None # type: ignore[assignment]
|
||||
|
||||
|
||||
class PgSpeakerStorage:
|
||||
"""Small asyncpg wrapper shared by speaker registration and ASR matching."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self.pool: Optional[asyncpg.Pool] = None
|
||||
|
||||
@property
|
||||
def is_enabled(self) -> bool:
|
||||
return bool(settings.SPEAKER_DB_ENABLED)
|
||||
|
||||
@property
|
||||
def is_connected(self) -> bool:
|
||||
return self.pool is not None
|
||||
|
||||
async def _create_database_if_not_exists(self) -> None:
|
||||
system_config = {
|
||||
"user": settings.DB_USER,
|
||||
"password": settings.DB_PASSWORD,
|
||||
"database": "postgres",
|
||||
"host": settings.DB_HOST,
|
||||
"port": settings.DB_PORT,
|
||||
}
|
||||
connection: Optional[asyncpg.Connection] = None
|
||||
try:
|
||||
if asyncpg is None:
|
||||
raise RuntimeError("asyncpg is not installed")
|
||||
connection = await asyncpg.connect(**system_config)
|
||||
exists = await connection.fetchval(
|
||||
"SELECT 1 FROM pg_database WHERE datname = $1",
|
||||
settings.DB_NAME,
|
||||
)
|
||||
if not exists:
|
||||
await connection.execute(f'CREATE DATABASE "{settings.DB_NAME}"')
|
||||
except Exception as exc:
|
||||
logger.warning("尝试自动创建数据库失败,将继续连接业务库: %s", exc)
|
||||
finally:
|
||||
if connection is not None:
|
||||
await connection.close()
|
||||
|
||||
async def connect(self) -> None:
|
||||
if not self.is_enabled:
|
||||
logger.info("声纹数据库未启用,跳过 PostgreSQL 连接")
|
||||
return
|
||||
if asyncpg is None:
|
||||
raise RuntimeError("asyncpg is not installed")
|
||||
if self.pool is not None:
|
||||
return
|
||||
|
||||
await self._create_database_if_not_exists()
|
||||
self.pool = await asyncpg.create_pool(
|
||||
user=settings.DB_USER,
|
||||
password=settings.DB_PASSWORD,
|
||||
database=settings.DB_NAME,
|
||||
host=settings.DB_HOST,
|
||||
port=settings.DB_PORT,
|
||||
min_size=1,
|
||||
max_size=settings.DB_POOL_MAX_SIZE,
|
||||
)
|
||||
async with self.pool.acquire() as connection:
|
||||
await connection.execute("CREATE EXTENSION IF NOT EXISTS vector;")
|
||||
await connection.execute(
|
||||
"""
|
||||
CREATE TABLE IF NOT EXISTS speakers (
|
||||
id SERIAL PRIMARY KEY,
|
||||
name TEXT NOT NULL UNIQUE,
|
||||
user_id TEXT,
|
||||
embedding vector(192),
|
||||
created_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP
|
||||
);
|
||||
"""
|
||||
)
|
||||
await connection.execute(
|
||||
"""
|
||||
DO $$
|
||||
BEGIN
|
||||
IF NOT EXISTS (
|
||||
SELECT 1 FROM information_schema.columns
|
||||
WHERE table_name='speakers' AND column_name='user_id'
|
||||
) THEN
|
||||
ALTER TABLE speakers ADD COLUMN user_id TEXT;
|
||||
END IF;
|
||||
END $$;
|
||||
"""
|
||||
)
|
||||
await connection.execute(
|
||||
"""
|
||||
DO $$
|
||||
BEGIN
|
||||
IF NOT EXISTS (
|
||||
SELECT 1
|
||||
FROM pg_class c
|
||||
JOIN pg_namespace n ON n.oid = c.relnamespace
|
||||
WHERE c.relname = 'speakers_embedding_idx'
|
||||
) THEN
|
||||
CREATE INDEX speakers_embedding_idx
|
||||
ON speakers USING hnsw (embedding vector_cosine_ops)
|
||||
WITH (m = 16, ef_construction = 64);
|
||||
END IF;
|
||||
END $$;
|
||||
"""
|
||||
)
|
||||
logger.info(
|
||||
"声纹数据库已连接: %s:%s/%s",
|
||||
settings.DB_HOST,
|
||||
settings.DB_PORT,
|
||||
settings.DB_NAME,
|
||||
)
|
||||
|
||||
async def close(self) -> None:
|
||||
if self.pool is not None:
|
||||
await self.pool.close()
|
||||
self.pool = None
|
||||
|
||||
def _require_pool(self) -> asyncpg.Pool:
|
||||
if self.pool is None:
|
||||
raise RuntimeError("Speaker database pool is not initialized")
|
||||
return self.pool
|
||||
|
||||
@staticmethod
|
||||
def _embedding_text(embedding: np.ndarray) -> str:
|
||||
return str(np.asarray(embedding, dtype=np.float32).flatten().tolist())
|
||||
|
||||
async def save_speaker(
|
||||
self,
|
||||
name: str,
|
||||
embedding: np.ndarray,
|
||||
user_id: Optional[str] = None,
|
||||
) -> dict[str, Optional[str]]:
|
||||
pool = self._require_pool()
|
||||
async with pool.acquire() as connection:
|
||||
row = await connection.fetchrow(
|
||||
"""
|
||||
INSERT INTO speakers (name, embedding, user_id)
|
||||
VALUES ($1, $2, $3)
|
||||
ON CONFLICT (name) DO UPDATE
|
||||
SET embedding = EXCLUDED.embedding, user_id = EXCLUDED.user_id
|
||||
RETURNING id, name, user_id;
|
||||
""",
|
||||
name,
|
||||
self._embedding_text(embedding),
|
||||
user_id,
|
||||
)
|
||||
return {
|
||||
"id": str(row["id"]) if row is not None else None,
|
||||
"name": row["name"] if row is not None else name,
|
||||
"user_id": row["user_id"] if row is not None else user_id,
|
||||
}
|
||||
|
||||
async def identify_speaker(
|
||||
self,
|
||||
embedding: np.ndarray,
|
||||
threshold: float,
|
||||
) -> dict[str, Optional[str]]:
|
||||
pool = self._require_pool()
|
||||
distance_threshold = 1.0 - float(threshold)
|
||||
async with pool.acquire() as connection:
|
||||
row = await connection.fetchrow(
|
||||
"""
|
||||
SELECT id, name, user_id, (embedding <=> $1::vector) AS distance
|
||||
FROM speakers
|
||||
ORDER BY embedding <=> $1::vector
|
||||
LIMIT 1;
|
||||
""",
|
||||
self._embedding_text(embedding),
|
||||
)
|
||||
if row is not None and float(row["distance"]) < distance_threshold:
|
||||
return {
|
||||
"id": str(row["id"]),
|
||||
"name": row["name"],
|
||||
"user_id": row["user_id"],
|
||||
}
|
||||
return {"id": None, "name": None, "user_id": None}
|
||||
|
||||
async def list_speakers(self) -> list[dict[str, Optional[str]]]:
|
||||
pool = self._require_pool()
|
||||
async with pool.acquire() as connection:
|
||||
rows = await connection.fetch(
|
||||
"SELECT id, name, user_id, created_at FROM speakers ORDER BY id ASC"
|
||||
)
|
||||
return [
|
||||
{
|
||||
"id": str(row["id"]),
|
||||
"name": row["name"],
|
||||
"user_id": row["user_id"],
|
||||
"created_at": row["created_at"].isoformat()
|
||||
if row["created_at"]
|
||||
else None,
|
||||
}
|
||||
for row in rows
|
||||
]
|
||||
|
||||
async def delete_speaker(self, speaker_id: int) -> bool:
|
||||
pool = self._require_pool()
|
||||
async with pool.acquire() as connection:
|
||||
result = await connection.execute(
|
||||
"DELETE FROM speakers WHERE id = $1",
|
||||
speaker_id,
|
||||
)
|
||||
return result != "DELETE 0"
|
||||
|
||||
|
||||
pg_speaker_db = PgSpeakerStorage()
|
||||
|
|
@ -0,0 +1,51 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Centralized device detection utility.
|
||||
|
||||
This module keeps the historic device helpers while delegating hardware
|
||||
probing to ``app.core.accelerator``.
|
||||
"""
|
||||
|
||||
from app.core.accelerator import get_accelerator_info
|
||||
|
||||
|
||||
def detect_device(configured: str = "auto") -> str:
|
||||
"""Resolve a device configuration string to a concrete PyTorch device.
|
||||
|
||||
Priority for ``"auto"``: configured accelerator > detected GPU > CPU.
|
||||
|
||||
Args:
|
||||
configured: Value from ``settings.DEVICE`` or caller override.
|
||||
Accepted: ``"auto"``, ``"cpu"``, ``"cuda:0"``, ``"npu:0"``, etc.
|
||||
|
||||
Returns:
|
||||
A device string ready for ``torch.device()`` / FunASR / ModelScope.
|
||||
"""
|
||||
device = configured.strip().lower()
|
||||
|
||||
if device == "auto":
|
||||
return get_accelerator_info().device
|
||||
|
||||
# Normalize bare "cuda" to "cuda:0"
|
||||
if device == "cuda":
|
||||
return "cuda:0"
|
||||
|
||||
if device == "mps":
|
||||
return "cpu"
|
||||
|
||||
return device
|
||||
|
||||
|
||||
def is_cuda() -> bool:
|
||||
"""True when the active runtime exposes a CUDA-compatible device."""
|
||||
info = get_accelerator_info()
|
||||
return info.available and info.device.startswith("cuda")
|
||||
|
||||
|
||||
def has_gpu() -> bool:
|
||||
"""True when a supported accelerator is available."""
|
||||
return get_accelerator_info().is_gpu
|
||||
|
||||
|
||||
def get_vram_gb() -> float:
|
||||
"""Return usable accelerator memory in GB."""
|
||||
return get_accelerator_info().total_memory_gb
|
||||
|
|
@ -0,0 +1,224 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
统一异常处理模块
|
||||
定义所有自定义异常类和错误处理函数
|
||||
"""
|
||||
|
||||
from datetime import datetime, timezone
|
||||
from fastapi import HTTPException, Request
|
||||
from fastapi.exception_handlers import (
|
||||
http_exception_handler as fastapi_http_exception_handler,
|
||||
request_validation_exception_handler as fastapi_validation_exception_handler,
|
||||
)
|
||||
from fastapi.exceptions import RequestValidationError
|
||||
from fastapi.responses import JSONResponse
|
||||
import logging
|
||||
from typing import Any, Dict, Optional
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def _uses_meeting_legacy_response(request: Request) -> bool:
|
||||
"""Return True for Model-Test-New compatible offline meeting/speaker APIs."""
|
||||
path = request.url.path.rstrip("/")
|
||||
method = request.method.upper()
|
||||
if path.endswith("/asr/transcriptions"):
|
||||
return method == "POST"
|
||||
if "/asr/transcriptions/" in path:
|
||||
return method == "GET"
|
||||
if path.endswith("/speakers"):
|
||||
return method == "POST"
|
||||
return False
|
||||
|
||||
|
||||
def get_iso_timestamp() -> str:
|
||||
"""获取ISO 8601格式的UTC时间戳"""
|
||||
return datetime.now(timezone.utc).strftime("%Y-%m-%dT%H:%M:%SZ")
|
||||
|
||||
|
||||
def create_error_response(
|
||||
error_code: str,
|
||||
message: str,
|
||||
task_id: str = "",
|
||||
details: Optional[Dict[str, Any]] = None,
|
||||
) -> Dict[str, Any]:
|
||||
"""
|
||||
创建标准错误响应格式
|
||||
|
||||
Args:
|
||||
error_code: 错误代码(如 INVALID_PARAMETER)
|
||||
message: 人类可读的错误信息
|
||||
task_id: 任务ID(可选)
|
||||
details: 额外详细信息(可选)
|
||||
|
||||
Returns:
|
||||
标准错误响应字典
|
||||
"""
|
||||
return {
|
||||
"error_code": error_code,
|
||||
"message": message,
|
||||
"task_id": task_id or "",
|
||||
"timestamp": get_iso_timestamp(),
|
||||
"details": details or {},
|
||||
}
|
||||
|
||||
|
||||
def get_http_status_code(status_code: int) -> int:
|
||||
"""Map internal API status code to HTTP status code."""
|
||||
return 500 if status_code >= 50000000 else 400
|
||||
|
||||
|
||||
class APIException(Exception):
|
||||
"""API基础异常类"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
status_code: int,
|
||||
message: str,
|
||||
task_id: str = "",
|
||||
error_code: str = "",
|
||||
details: Optional[Dict[str, Any]] = None,
|
||||
):
|
||||
self.status_code = status_code
|
||||
self.message = message
|
||||
self.task_id = task_id
|
||||
self.error_code = error_code or self._get_error_code(status_code)
|
||||
self.details = details or {}
|
||||
super().__init__(self.message)
|
||||
|
||||
def _get_error_code(self, status_code: int) -> str:
|
||||
"""根据状态码获取错误代码"""
|
||||
code_mapping = {
|
||||
20000000: "SUCCESS",
|
||||
40000000: "DEFAULT_CLIENT_ERROR",
|
||||
40000001: "AUTHENTICATION_FAILED",
|
||||
40000002: "INVALID_MESSAGE",
|
||||
40000003: "INVALID_PARAMETER",
|
||||
40000004: "IDLE_TIMEOUT",
|
||||
40000005: "TOO_MANY_REQUESTS",
|
||||
40000010: "TRIAL_EXPIRED",
|
||||
41010101: "UNSUPPORTED_SAMPLE_RATE",
|
||||
50000000: "DEFAULT_SERVER_ERROR",
|
||||
50000001: "INTERNAL_GRPC_ERROR",
|
||||
}
|
||||
return code_mapping.get(status_code, "UNKNOWN_ERROR")
|
||||
|
||||
def to_dict(self) -> Dict[str, Any]:
|
||||
"""
|
||||
将异常转换为标准错误响应字典
|
||||
|
||||
Returns:
|
||||
标准错误响应字典,包含 error_code, message, task_id, timestamp, details
|
||||
"""
|
||||
return create_error_response(
|
||||
error_code=self.error_code,
|
||||
message=self.message,
|
||||
task_id=self.task_id,
|
||||
details=self.details,
|
||||
)
|
||||
|
||||
|
||||
# 标准异常类
|
||||
class AuthenticationException(APIException):
|
||||
"""身份认证异常"""
|
||||
|
||||
def __init__(self, message: str, task_id: str = "", details: Optional[Dict[str, Any]] = None):
|
||||
super().__init__(40000001, message, task_id, details=details)
|
||||
|
||||
|
||||
class InvalidMessageException(APIException):
|
||||
"""无效消息异常"""
|
||||
|
||||
def __init__(self, message: str, task_id: str = "", details: Optional[Dict[str, Any]] = None):
|
||||
super().__init__(40000002, message, task_id, details=details)
|
||||
|
||||
|
||||
class InvalidParameterException(APIException):
|
||||
"""无效参数异常"""
|
||||
|
||||
def __init__(self, message: str, task_id: str = "", details: Optional[Dict[str, Any]] = None):
|
||||
super().__init__(40000003, message, task_id, details=details)
|
||||
|
||||
|
||||
class UnsupportedSampleRateException(APIException):
|
||||
"""不支持的采样率异常"""
|
||||
|
||||
def __init__(self, message: str, task_id: str = "", details: Optional[Dict[str, Any]] = None):
|
||||
super().__init__(41010101, message, task_id, details=details)
|
||||
|
||||
|
||||
class DefaultServerErrorException(APIException):
|
||||
"""默认服务端错误异常"""
|
||||
|
||||
def __init__(self, message: str, task_id: str = "", details: Optional[Dict[str, Any]] = None):
|
||||
super().__init__(50000000, message, task_id, details=details)
|
||||
|
||||
|
||||
# 异常处理器
|
||||
async def api_exception_handler(request: Request, exc: Exception) -> JSONResponse:
|
||||
"""API异常处理器"""
|
||||
# FastAPI 只会在抛出 APIException 时调用此处理器
|
||||
api_exc = exc if isinstance(exc, APIException) else APIException(50000000, str(exc))
|
||||
logger.error(f"[{api_exc.task_id}] API异常: {api_exc.message}")
|
||||
|
||||
# 使用标准错误格式
|
||||
response_data = api_exc.to_dict()
|
||||
|
||||
# 确定HTTP状态码
|
||||
http_status_code = get_http_status_code(api_exc.status_code)
|
||||
|
||||
return JSONResponse(
|
||||
content=response_data,
|
||||
headers={"task_id": api_exc.task_id} if api_exc.task_id else {},
|
||||
status_code=http_status_code,
|
||||
)
|
||||
|
||||
|
||||
async def http_exception_handler(request: Request, exc: Exception) -> JSONResponse:
|
||||
"""FastAPI HTTPException handler for legacy meeting/speaker endpoints."""
|
||||
http_exc = exc if isinstance(exc, HTTPException) else HTTPException(500, str(exc))
|
||||
if not _uses_meeting_legacy_response(request):
|
||||
return await fastapi_http_exception_handler(request, http_exc)
|
||||
|
||||
detail = http_exc.detail
|
||||
if isinstance(detail, dict):
|
||||
return JSONResponse(
|
||||
status_code=http_exc.status_code,
|
||||
content={
|
||||
"code": detail.get("code", 4001),
|
||||
"message": detail.get("message", "Request failed"),
|
||||
},
|
||||
)
|
||||
return JSONResponse(
|
||||
status_code=http_exc.status_code,
|
||||
content={"code": 4001, "message": str(detail)},
|
||||
)
|
||||
|
||||
|
||||
async def validation_exception_handler(request: Request, exc: Exception) -> JSONResponse:
|
||||
"""FastAPI/Pydantic validation handler for legacy meeting/speaker endpoints."""
|
||||
validation_exc = exc if isinstance(exc, RequestValidationError) else None
|
||||
if validation_exc is None:
|
||||
return JSONResponse(
|
||||
status_code=422,
|
||||
content={"code": 1001, "message": "Invalid request"},
|
||||
)
|
||||
if not _uses_meeting_legacy_response(request):
|
||||
return await fastapi_validation_exception_handler(request, validation_exc)
|
||||
|
||||
errors = validation_exc.errors()
|
||||
message = str(errors[0]["msg"]) if errors else "Invalid request"
|
||||
return JSONResponse(status_code=422, content={"code": 1001, "message": message})
|
||||
|
||||
|
||||
async def general_exception_handler(request: Request, exc: Exception) -> JSONResponse:
|
||||
"""通用异常处理器"""
|
||||
logger.error(f"未处理的异常: {str(exc)}", exc_info=True)
|
||||
|
||||
# 使用标准错误格式
|
||||
response_data = create_error_response(
|
||||
error_code="DEFAULT_SERVER_ERROR",
|
||||
message=f"内部服务错误: {str(exc)}",
|
||||
)
|
||||
|
||||
return JSONResponse(content=response_data, status_code=500)
|
||||
|
|
@ -0,0 +1,185 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
异步执行器模块
|
||||
|
||||
用于将同步的模型推理调用放入线程池执行,避免阻塞事件循环,
|
||||
实现真正的多路并发处理。
|
||||
|
||||
设计要点:
|
||||
1. 使用 ThreadPoolExecutor 而非 ProcessPoolExecutor
|
||||
- 模型已加载在内存中,进程间无法共享
|
||||
- GPU操作会自动释放GIL,线程池足以实现并发
|
||||
|
||||
2. 对于流式生成器,使用 asyncio.Queue 实现异步迭代
|
||||
|
||||
3. 线程池大小根据使用场景配置:
|
||||
- CPU推理:受GIL限制,多线程并发收益有限,但可以让I/O不阻塞
|
||||
- GPU推理:CUDA操作释放GIL,可以实现真正并发
|
||||
"""
|
||||
|
||||
import os
|
||||
import asyncio
|
||||
import logging
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from typing import Callable, TypeVar, Generator, AsyncGenerator, Optional
|
||||
from functools import partial
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# 类型变量
|
||||
T = TypeVar("T")
|
||||
|
||||
# 全局线程池执行器
|
||||
# 默认线程数:max(4, CPU核心数),可通过环境变量覆盖
|
||||
_DEFAULT_WORKERS = max(4, os.cpu_count() or 4)
|
||||
_MAX_WORKERS = int(os.getenv("INFERENCE_THREAD_POOL_SIZE", str(_DEFAULT_WORKERS)))
|
||||
|
||||
_executor: Optional[ThreadPoolExecutor] = None
|
||||
|
||||
|
||||
def get_executor() -> ThreadPoolExecutor:
|
||||
"""获取全局线程池执行器(懒加载)"""
|
||||
global _executor
|
||||
if _executor is None:
|
||||
_executor = ThreadPoolExecutor(
|
||||
max_workers=_MAX_WORKERS,
|
||||
thread_name_prefix="inference_worker"
|
||||
)
|
||||
logger.info(f"推理线程池已创建,最大工作线程数: {_MAX_WORKERS}")
|
||||
return _executor
|
||||
|
||||
|
||||
def shutdown_executor():
|
||||
"""关闭线程池执行器"""
|
||||
global _executor
|
||||
if _executor is not None:
|
||||
_executor.shutdown(wait=True)
|
||||
_executor = None
|
||||
logger.info("推理线程池已关闭")
|
||||
|
||||
|
||||
async def run_sync(func: Callable[..., T], *args, **kwargs) -> T:
|
||||
"""
|
||||
在线程池中执行同步函数,不阻塞事件循环
|
||||
|
||||
Args:
|
||||
func: 同步函数
|
||||
*args: 位置参数
|
||||
**kwargs: 关键字参数
|
||||
|
||||
Returns:
|
||||
函数返回值
|
||||
|
||||
Example:
|
||||
result = await run_sync(model.generate, input=audio_array, cache=cache)
|
||||
"""
|
||||
loop = asyncio.get_running_loop()
|
||||
executor = get_executor()
|
||||
|
||||
# 使用 partial 绑定参数
|
||||
if kwargs:
|
||||
func_with_args = partial(func, *args, **kwargs)
|
||||
else:
|
||||
func_with_args = partial(func, *args) if args else func
|
||||
|
||||
return await loop.run_in_executor(executor, func_with_args)
|
||||
|
||||
|
||||
async def run_sync_generator(
|
||||
generator_func: Callable[..., Generator[T, None, None]],
|
||||
*args,
|
||||
**kwargs
|
||||
) -> AsyncGenerator[T, None]:
|
||||
"""
|
||||
将同步生成器转换为异步生成器,在线程池中执行
|
||||
|
||||
用于流式处理等需要逐步产出结果的场景。
|
||||
|
||||
Args:
|
||||
generator_func: 返回生成器的同步函数
|
||||
*args: 位置参数
|
||||
**kwargs: 关键字参数
|
||||
|
||||
Yields:
|
||||
生成器的每个产出值
|
||||
|
||||
Example:
|
||||
async for chunk in run_sync_generator(model.inference_sft, text, voice, stream=True):
|
||||
await websocket.send_bytes(chunk)
|
||||
"""
|
||||
loop = asyncio.get_running_loop()
|
||||
executor = get_executor()
|
||||
queue: asyncio.Queue = asyncio.Queue()
|
||||
|
||||
# 标记生成器结束的哨兵值
|
||||
_SENTINEL = object()
|
||||
|
||||
def producer():
|
||||
"""在线程中运行生成器,将结果放入队列"""
|
||||
try:
|
||||
gen = generator_func(*args, **kwargs)
|
||||
for item in gen:
|
||||
# 使用 call_soon_threadsafe 安全地将结果放入队列
|
||||
loop.call_soon_threadsafe(queue.put_nowait, item)
|
||||
except BaseException as e:
|
||||
# 发生异常时,记录日志并将异常放入队列
|
||||
logger.error(f"生成器执行异常: {type(e).__name__}: {e}")
|
||||
loop.call_soon_threadsafe(queue.put_nowait, e)
|
||||
finally:
|
||||
# 发送结束标记
|
||||
loop.call_soon_threadsafe(queue.put_nowait, _SENTINEL)
|
||||
|
||||
# 在线程池中启动生产者
|
||||
future = executor.submit(producer)
|
||||
|
||||
try:
|
||||
while True:
|
||||
item = await queue.get()
|
||||
|
||||
if item is _SENTINEL:
|
||||
break
|
||||
|
||||
# 使用 BaseException 捕获所有异常类型(包括 KeyboardInterrupt 等)
|
||||
if isinstance(item, BaseException):
|
||||
raise item
|
||||
|
||||
yield item
|
||||
finally:
|
||||
# 确保检查线程是否有未捕获的异常
|
||||
if future.done():
|
||||
try:
|
||||
# 如果线程已完成,检查是否有异常
|
||||
future.result()
|
||||
except Exception as e:
|
||||
logger.error(f"生成器线程异常: {type(e).__name__}: {e}")
|
||||
elif not future.cancelled():
|
||||
future.cancel()
|
||||
|
||||
|
||||
class AsyncInferenceWrapper:
|
||||
"""
|
||||
异步推理包装器
|
||||
|
||||
将同步的模型推理方法包装为异步方法,方便复用。
|
||||
|
||||
Example:
|
||||
wrapper = AsyncInferenceWrapper(asr_engine.realtime_model)
|
||||
result = await wrapper.generate(input=audio_array, cache=cache)
|
||||
"""
|
||||
|
||||
def __init__(self, model):
|
||||
self._model = model
|
||||
|
||||
async def generate(self, *args, **kwargs):
|
||||
"""异步调用模型的 generate 方法"""
|
||||
return await run_sync(self._model.generate, *args, **kwargs)
|
||||
|
||||
async def inference_sft(self, *args, **kwargs):
|
||||
"""异步流式调用模型的 inference_sft 方法"""
|
||||
async for item in run_sync_generator(self._model.inference_sft, *args, **kwargs):
|
||||
yield item
|
||||
|
||||
async def inference_zero_shot(self, *args, **kwargs):
|
||||
"""异步流式调用模型的 inference_zero_shot 方法"""
|
||||
async for item in run_sync_generator(self._model.inference_zero_shot, *args, **kwargs):
|
||||
yield item
|
||||
|
|
@ -0,0 +1,216 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Rule-based hotword correction for ASR post-processing."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from difflib import SequenceMatcher
|
||||
from typing import Any
|
||||
|
||||
try:
|
||||
from pypinyin import lazy_pinyin
|
||||
except Exception: # pragma: no cover - optional runtime enhancement.
|
||||
lazy_pinyin = None # type: ignore[assignment]
|
||||
|
||||
|
||||
_HOTWORD_PROMPT_LEAK_PATTERNS = (
|
||||
re.compile(r"^\s*Use this context when resolving named entities:\s*", re.IGNORECASE),
|
||||
re.compile(r"^\s*(?:上下文信息[::]?\s*)?热词列表[::]\s*[[\[][^\]]]{0,500}[]\]]\s*[,。,::;;\s]*"),
|
||||
)
|
||||
|
||||
|
||||
def parse_hotwords(hotwords: str | list[dict[str, object]] | None) -> list[dict[str, Any]]:
|
||||
if isinstance(hotwords, list):
|
||||
return _extract_hotword_entries(hotwords)
|
||||
|
||||
raw_text = str(hotwords or "").strip()
|
||||
if not raw_text:
|
||||
return []
|
||||
|
||||
tokens = [part for part in re.split(r"[\s,,;;]+", raw_text) if part]
|
||||
entries: list[dict[str, Any]] = []
|
||||
index = 0
|
||||
order = 0
|
||||
while index < len(tokens):
|
||||
word = tokens[index].strip()
|
||||
if not word:
|
||||
index += 1
|
||||
continue
|
||||
weight = 1.0
|
||||
if index + 1 < len(tokens):
|
||||
try:
|
||||
weight = float(tokens[index + 1])
|
||||
index += 2
|
||||
except ValueError:
|
||||
index += 1
|
||||
else:
|
||||
index += 1
|
||||
entries.append({"text": word, "weight": weight, "order": order})
|
||||
order += 1
|
||||
return entries
|
||||
|
||||
|
||||
def format_hotword_prompt_context(hotwords: str | list[dict[str, object]] | None) -> str:
|
||||
entries = parse_hotwords(hotwords)
|
||||
if not entries:
|
||||
return ""
|
||||
|
||||
unique_words: list[str] = []
|
||||
for entry in entries:
|
||||
word = str(entry["text"]).strip()
|
||||
if word and word not in unique_words:
|
||||
unique_words.append(word)
|
||||
if not unique_words:
|
||||
return ""
|
||||
return f"热词列表:[{', '.join(unique_words)}]"
|
||||
|
||||
|
||||
def strip_hotword_prompt_leakage(text: str) -> str:
|
||||
cleaned = str(text or "")
|
||||
changed = True
|
||||
while changed and cleaned:
|
||||
changed = False
|
||||
for pattern in _HOTWORD_PROMPT_LEAK_PATTERNS:
|
||||
updated, count = pattern.subn("", cleaned, count=1)
|
||||
if count:
|
||||
cleaned = updated
|
||||
changed = True
|
||||
return cleaned.strip()
|
||||
|
||||
|
||||
def _extract_hotword_entries(hotwords: list[dict[str, object]] | None) -> list[dict[str, Any]]:
|
||||
entries: list[dict[str, Any]] = []
|
||||
for index, item in enumerate(hotwords or []):
|
||||
hotword_text = str(item.get("hotword", "")).strip()
|
||||
if not hotword_text:
|
||||
continue
|
||||
try:
|
||||
weight = float(item.get("weight", 1.0))
|
||||
except Exception:
|
||||
weight = 1.0
|
||||
entries.append({"text": hotword_text, "weight": weight, "order": index})
|
||||
return entries
|
||||
|
||||
|
||||
def _normalize_ascii_token(text: str) -> str:
|
||||
return re.sub(r"[^a-z0-9]+", "", str(text or "").lower())
|
||||
|
||||
|
||||
def _common_prefix_length(left: str, right: str) -> int:
|
||||
matched = 0
|
||||
for left_char, right_char in zip(left, right):
|
||||
if left_char != right_char:
|
||||
break
|
||||
matched += 1
|
||||
return matched
|
||||
|
||||
|
||||
def _common_suffix_length(left: str, right: str) -> int:
|
||||
return _common_prefix_length(left[::-1], right[::-1])
|
||||
|
||||
|
||||
def _normalize_cjk_pinyin(text: str) -> tuple[str, ...]:
|
||||
if lazy_pinyin is None:
|
||||
return ()
|
||||
return tuple(part.strip().lower() for part in lazy_pinyin(str(text or ""), errors="ignore") if str(part).strip())
|
||||
|
||||
|
||||
def _replace_ascii_hotwords(text: str, hotword_entries: list[dict[str, Any]]) -> tuple[str, bool, list[str]]:
|
||||
updated_text = str(text or "")
|
||||
changed = False
|
||||
matched_hotwords: list[str] = []
|
||||
ascii_pattern = re.compile(r"[A-Za-z][A-Za-z0-9\s._-]{0,40}")
|
||||
for entry in hotword_entries:
|
||||
hotword = str(entry["text"])
|
||||
if not re.search(r"[A-Za-z]", hotword):
|
||||
continue
|
||||
normalized_hotword = _normalize_ascii_token(hotword)
|
||||
if not normalized_hotword:
|
||||
continue
|
||||
|
||||
def _replace_match(match: re.Match[str]) -> str:
|
||||
nonlocal changed
|
||||
candidate = match.group(0)
|
||||
if _normalize_ascii_token(candidate) == normalized_hotword and candidate != hotword:
|
||||
changed = True
|
||||
if hotword not in matched_hotwords:
|
||||
matched_hotwords.append(hotword)
|
||||
return hotword
|
||||
return candidate
|
||||
|
||||
updated_text = ascii_pattern.sub(_replace_match, updated_text)
|
||||
return updated_text, changed, matched_hotwords
|
||||
|
||||
|
||||
def _score_cjk_candidate(candidate: str, hotword_entry: dict[str, Any]) -> tuple[int, float, int, float, int] | None:
|
||||
hotword = str(hotword_entry["text"])
|
||||
if candidate == hotword or len(candidate) != len(hotword):
|
||||
return None
|
||||
candidate_pinyin = _normalize_cjk_pinyin(candidate)
|
||||
hotword_pinyin = _normalize_cjk_pinyin(hotword)
|
||||
if candidate_pinyin and candidate_pinyin == hotword_pinyin:
|
||||
return (3, float(hotword_entry["weight"]), len(hotword), 1.0, -int(hotword_entry["order"]))
|
||||
if len(hotword) <= 2:
|
||||
return None
|
||||
prefix_length = _common_prefix_length(candidate, hotword)
|
||||
suffix_length = _common_suffix_length(candidate, hotword)
|
||||
similarity = SequenceMatcher(None, candidate, hotword).ratio()
|
||||
if prefix_length >= len(hotword) - 1 or suffix_length >= len(hotword) - 1:
|
||||
return (2, float(hotword_entry["weight"]), prefix_length + suffix_length, similarity, -int(hotword_entry["order"]))
|
||||
if similarity >= 0.67 and prefix_length >= 1 and suffix_length >= 1:
|
||||
return (2, float(hotword_entry["weight"]), prefix_length + suffix_length, similarity, -int(hotword_entry["order"]))
|
||||
return None
|
||||
|
||||
|
||||
def _replace_cjk_hotwords(text: str, hotword_entries: list[dict[str, Any]]) -> tuple[str, bool, list[str]]:
|
||||
updated_text = str(text or "")
|
||||
changed = False
|
||||
matched_hotwords: list[str] = []
|
||||
chinese_entries = [entry for entry in hotword_entries if re.fullmatch(r"[\u4e00-\u9fff]{2,12}", str(entry["text"]))]
|
||||
if not chinese_entries:
|
||||
return updated_text, False, matched_hotwords
|
||||
candidate_lengths = sorted({len(str(entry["text"])) for entry in chinese_entries})
|
||||
token_pattern = re.compile(r"[\u4e00-\u9fff]{2,24}")
|
||||
|
||||
def _replace_match(match: re.Match[str]) -> str:
|
||||
nonlocal changed
|
||||
token = match.group(0)
|
||||
best_choice: tuple[tuple[int, float, int, float, int], int, int, str] | None = None
|
||||
for hotword_length in candidate_lengths:
|
||||
if hotword_length > len(token):
|
||||
continue
|
||||
scoped_entries = [entry for entry in chinese_entries if len(str(entry["text"])) == hotword_length]
|
||||
for index in range(0, len(token) - hotword_length + 1):
|
||||
candidate = token[index:index + hotword_length]
|
||||
for entry in scoped_entries:
|
||||
score = _score_cjk_candidate(candidate, entry)
|
||||
if score is None:
|
||||
continue
|
||||
current_choice = (score, index, hotword_length, str(entry["text"]))
|
||||
if best_choice is None or current_choice > best_choice:
|
||||
best_choice = current_choice
|
||||
if best_choice is None:
|
||||
return token
|
||||
_, begin_index, hotword_length, hotword = best_choice
|
||||
token_chars = list(token)
|
||||
token_chars[begin_index:begin_index + hotword_length] = list(hotword)
|
||||
changed = True
|
||||
if hotword not in matched_hotwords:
|
||||
matched_hotwords.append(hotword)
|
||||
return "".join(token_chars)
|
||||
|
||||
updated_text = token_pattern.sub(_replace_match, updated_text)
|
||||
return updated_text, changed, matched_hotwords
|
||||
|
||||
|
||||
def apply_hotword_rules(text: str, hotwords: str | list[dict[str, object]] | None = None) -> tuple[str, bool, list[str]]:
|
||||
hotword_entries = parse_hotwords(hotwords)
|
||||
if not hotword_entries:
|
||||
return str(text or ""), False, []
|
||||
updated_text, ascii_changed, ascii_matches = _replace_ascii_hotwords(str(text or ""), hotword_entries)
|
||||
updated_text, cjk_changed, cjk_matches = _replace_cjk_hotwords(updated_text, hotword_entries)
|
||||
matched_hotwords: list[str] = []
|
||||
for hotword_text in ascii_matches + cjk_matches:
|
||||
if hotword_text not in matched_hotwords:
|
||||
matched_hotwords.append(hotword_text)
|
||||
return updated_text, ascii_changed or cjk_changed, matched_hotwords
|
||||
|
|
@ -0,0 +1,342 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
日志配置模块
|
||||
统一的日志配置和管理,支持多 Worker 模式
|
||||
"""
|
||||
|
||||
import logging
|
||||
import logging.handlers
|
||||
import sys
|
||||
import os
|
||||
import json
|
||||
from datetime import datetime, timezone
|
||||
from typing import Optional, Dict, Any
|
||||
from pathlib import Path
|
||||
from .config import settings
|
||||
|
||||
|
||||
class StructuredLogFormatter(logging.Formatter):
|
||||
"""结构化JSON日志格式化器
|
||||
|
||||
将日志记录格式化为JSON格式,支持extra字段传递结构化数据。
|
||||
|
||||
输出示例:
|
||||
{
|
||||
"timestamp": "2025-01-31T12:00:00Z",
|
||||
"level": "INFO",
|
||||
"logger": "app.services.asr",
|
||||
"message": "推理完成",
|
||||
"task_id": "xxx",
|
||||
"duration_ms": 1234,
|
||||
"audio_duration_sec": 60,
|
||||
"rtf": 0.02,
|
||||
"model_id": "qwen3-asr-1.7b"
|
||||
}
|
||||
"""
|
||||
|
||||
def __init__(self, include_extra: bool = True):
|
||||
"""
|
||||
Args:
|
||||
include_extra: 是否包含extra字段中的结构化数据
|
||||
"""
|
||||
super().__init__()
|
||||
self.include_extra = include_extra
|
||||
self._reserved_attrs = {
|
||||
'name', 'msg', 'args', 'levelname', 'levelno', 'pathname',
|
||||
'filename', 'module', 'exc_info', 'exc_text', 'stack_info',
|
||||
'lineno', 'funcName', 'created', 'msecs', 'relativeCreated',
|
||||
'thread', 'threadName', 'processName', 'process', 'getMessage',
|
||||
'message', 'asctime'
|
||||
}
|
||||
|
||||
def format(self, record: logging.LogRecord) -> str:
|
||||
"""将日志记录格式化为JSON"""
|
||||
log_data: Dict[str, Any] = {
|
||||
"timestamp": datetime.fromtimestamp(record.created, tz=timezone.utc).strftime("%Y-%m-%dT%H:%M:%S.%f")[:-3] + "Z",
|
||||
"level": record.levelname,
|
||||
"logger": record.name,
|
||||
"message": record.getMessage(),
|
||||
}
|
||||
|
||||
# 添加worker_id(多worker模式下)
|
||||
workers = int(os.getenv("WORKERS", "1"))
|
||||
if workers > 1:
|
||||
log_data["worker_id"] = f"worker-{os.getpid()}"
|
||||
|
||||
# 添加异常信息(如果有)
|
||||
if record.exc_info:
|
||||
exc_type = record.exc_info[0]
|
||||
exc_value = record.exc_info[1]
|
||||
if exc_type and exc_value:
|
||||
log_data["exception"] = {
|
||||
"type": exc_type.__name__,
|
||||
"message": str(exc_value)
|
||||
}
|
||||
|
||||
# 添加extra字段中的结构化数据
|
||||
if self.include_extra:
|
||||
extra_data = self._extract_extra_data(record)
|
||||
if extra_data:
|
||||
log_data.update(extra_data)
|
||||
|
||||
return json.dumps(log_data, ensure_ascii=False, default=str)
|
||||
|
||||
def _extract_extra_data(self, record: logging.LogRecord) -> Dict[str, Any]:
|
||||
"""从日志记录中提取extra数据"""
|
||||
extra_data = {}
|
||||
for key, value in record.__dict__.items():
|
||||
if key not in self._reserved_attrs and not key.startswith('_'):
|
||||
extra_data[key] = value
|
||||
return extra_data
|
||||
|
||||
|
||||
class HybridLogFormatter(logging.Formatter):
|
||||
"""混合日志格式化器
|
||||
|
||||
根据日志内容自动选择格式:
|
||||
- 包含结构化数据(extra字段)的日志使用JSON格式
|
||||
- 普通日志使用文本格式
|
||||
|
||||
这允许在代码中逐步迁移到结构化日志,同时保持可读性。
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
text_format: Optional[str] = None,
|
||||
json_formatter: Optional[StructuredLogFormatter] = None,
|
||||
):
|
||||
super().__init__()
|
||||
self.text_format = text_format or "%(asctime)s - %(name)s - %(levelname)s - %(message)s"
|
||||
self.json_formatter = json_formatter or StructuredLogFormatter()
|
||||
self._reserved_attrs = {
|
||||
'name', 'msg', 'args', 'levelname', 'levelno', 'pathname',
|
||||
'filename', 'module', 'exc_info', 'exc_text', 'stack_info',
|
||||
'lineno', 'funcName', 'created', 'msecs', 'relativeCreated',
|
||||
'thread', 'threadName', 'processName', 'process', 'getMessage',
|
||||
'message', 'asctime'
|
||||
}
|
||||
|
||||
def format(self, record: logging.LogRecord) -> str:
|
||||
"""根据内容选择格式"""
|
||||
# 检查是否有extra数据
|
||||
has_extra = self._has_extra_data(record)
|
||||
|
||||
if has_extra:
|
||||
return self.json_formatter.format(record)
|
||||
else:
|
||||
# 使用文本格式
|
||||
text_formatter = logging.Formatter(self.text_format)
|
||||
return text_formatter.format(record)
|
||||
|
||||
def _has_extra_data(self, record: logging.LogRecord) -> bool:
|
||||
"""检查日志记录是否包含extra数据"""
|
||||
for key in record.__dict__.keys():
|
||||
if key not in self._reserved_attrs and not key.startswith('_'):
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def get_structured_logger(name: str) -> logging.Logger:
|
||||
"""获取支持结构化日志的记录器
|
||||
|
||||
这是一个便捷函数,返回一个配置好的日志记录器,
|
||||
可以直接使用 extra 参数记录结构化数据。
|
||||
|
||||
示例:
|
||||
logger = get_structured_logger(__name__)
|
||||
logger.info(
|
||||
"推理完成",
|
||||
extra={
|
||||
"duration_ms": 1234,
|
||||
"audio_duration_sec": 60,
|
||||
"rtf": 0.02,
|
||||
"model_id": "qwen3-asr-1.7b"
|
||||
}
|
||||
)
|
||||
|
||||
Args:
|
||||
name: 记录器名称
|
||||
|
||||
Returns:
|
||||
配置好的日志记录器
|
||||
"""
|
||||
return logging.getLogger(name)
|
||||
|
||||
|
||||
def log_inference_metrics(
|
||||
logger: logging.Logger,
|
||||
message: str,
|
||||
task_id: Optional[str] = None,
|
||||
duration_ms: Optional[float] = None,
|
||||
audio_duration_sec: Optional[float] = None,
|
||||
model_id: Optional[str] = None,
|
||||
status: str = "success",
|
||||
**kwargs
|
||||
) -> None:
|
||||
"""记录推理性能指标
|
||||
|
||||
这是一个辅助函数,用于统一记录推理性能指标。
|
||||
|
||||
Args:
|
||||
logger: 日志记录器
|
||||
message: 日志消息
|
||||
task_id: 任务ID
|
||||
duration_ms: 推理耗时(毫秒)
|
||||
audio_duration_sec: 音频时长(秒)
|
||||
model_id: 模型ID
|
||||
status: 状态(success/error)
|
||||
**kwargs: 其他结构化数据
|
||||
"""
|
||||
extra: Dict[str, Any] = {
|
||||
"status": status,
|
||||
}
|
||||
|
||||
if task_id:
|
||||
extra["task_id"] = task_id
|
||||
if duration_ms is not None:
|
||||
extra["duration_ms"] = round(duration_ms, 2)
|
||||
if audio_duration_sec is not None:
|
||||
extra["audio_duration_sec"] = round(audio_duration_sec, 2)
|
||||
if model_id:
|
||||
extra["model_id"] = model_id
|
||||
|
||||
# 计算RTF(实时率)
|
||||
if duration_ms is not None and audio_duration_sec is not None and audio_duration_sec > 0:
|
||||
rtf = (duration_ms / 1000) / audio_duration_sec
|
||||
extra["rtf"] = round(rtf, 4)
|
||||
|
||||
# 添加其他数据
|
||||
extra.update(kwargs)
|
||||
|
||||
logger.info(message, extra=extra)
|
||||
|
||||
|
||||
def get_worker_id() -> str:
|
||||
"""获取当前 Worker ID
|
||||
|
||||
Returns:
|
||||
Worker 标识符,格式为 'worker-{pid}' 或 'main'
|
||||
"""
|
||||
# 检查是否在多 worker 模式下
|
||||
workers = int(os.getenv("WORKERS", "1"))
|
||||
if workers > 1:
|
||||
return f"worker-{os.getpid()}"
|
||||
return "main"
|
||||
|
||||
|
||||
def setup_logging(
|
||||
level: Optional[str] = None,
|
||||
log_file: Optional[str] = None,
|
||||
format_string: Optional[str] = None,
|
||||
max_bytes: Optional[int] = None,
|
||||
backup_count: Optional[int] = None,
|
||||
worker_id: Optional[str] = None,
|
||||
use_structured: bool = False,
|
||||
) -> None:
|
||||
"""设置应用日志配置
|
||||
|
||||
Args:
|
||||
level: 日志级别
|
||||
log_file: 日志文件路径
|
||||
format_string: 日志格式字符串
|
||||
max_bytes: 单个日志文件最大大小(字节)
|
||||
backup_count: 保留的备份文件数量
|
||||
worker_id: Worker 标识符(多 Worker 模式下使用)
|
||||
use_structured: 是否使用结构化JSON日志格式
|
||||
"""
|
||||
# 使用传入的参数或配置文件中的设置
|
||||
log_level = level or settings.LOG_LEVEL
|
||||
log_file_path = log_file or settings.LOG_FILE
|
||||
max_file_size = max_bytes or settings.LOG_MAX_BYTES
|
||||
backup_files = backup_count or settings.LOG_BACKUP_COUNT
|
||||
|
||||
# 获取 Worker ID
|
||||
current_worker_id = worker_id or get_worker_id()
|
||||
workers = int(os.getenv("WORKERS", "1"))
|
||||
worker_log_path: Optional[Path] = None
|
||||
|
||||
# 确定日志格式
|
||||
if use_structured:
|
||||
# 使用结构化日志格式
|
||||
formatter: logging.Formatter = StructuredLogFormatter()
|
||||
else:
|
||||
# 使用混合格式(普通日志文本,带extra的JSON)
|
||||
if workers > 1:
|
||||
text_format = format_string or f"%(asctime)s - [{current_worker_id}] - %(name)s - %(levelname)s - %(message)s"
|
||||
else:
|
||||
text_format = format_string or "%(asctime)s - %(name)s - %(levelname)s - %(message)s"
|
||||
formatter = HybridLogFormatter(text_format=text_format)
|
||||
|
||||
# 创建处理器列表
|
||||
stream_handler = logging.StreamHandler(sys.stdout)
|
||||
stream_handler.setFormatter(formatter)
|
||||
handlers: list[logging.Handler] = [stream_handler]
|
||||
|
||||
# 确定日志文件路径
|
||||
if log_file_path:
|
||||
log_path = Path(log_file_path)
|
||||
else:
|
||||
log_path = Path("logs/qwen3-asr.log")
|
||||
|
||||
# 确保日志目录存在
|
||||
log_dir = log_path.parent
|
||||
log_dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
# 多 Worker 模式下,每个 Worker 使用独立的日志文件
|
||||
if workers > 1:
|
||||
# Example: qwen3-asr.log -> qwen3-asr.worker-12345.log
|
||||
worker_log_path = log_dir / f"{log_path.stem}.{current_worker_id}{log_path.suffix}"
|
||||
|
||||
# Worker 专属日志文件
|
||||
worker_file_handler = logging.handlers.RotatingFileHandler(
|
||||
worker_log_path,
|
||||
maxBytes=max_file_size,
|
||||
backupCount=backup_files,
|
||||
encoding="utf-8",
|
||||
)
|
||||
worker_file_handler.setFormatter(formatter)
|
||||
handlers.append(worker_file_handler)
|
||||
|
||||
# 同时也写入主日志文件(汇总所有 Worker 的日志)
|
||||
main_file_handler = logging.handlers.RotatingFileHandler(
|
||||
log_path,
|
||||
maxBytes=max_file_size,
|
||||
backupCount=backup_files,
|
||||
encoding="utf-8",
|
||||
)
|
||||
main_file_handler.setFormatter(formatter)
|
||||
handlers.append(main_file_handler)
|
||||
else:
|
||||
# 单 Worker 模式,只写入主日志文件
|
||||
file_handler = logging.handlers.RotatingFileHandler(
|
||||
log_path,
|
||||
maxBytes=max_file_size,
|
||||
backupCount=backup_files,
|
||||
encoding="utf-8",
|
||||
)
|
||||
file_handler.setFormatter(formatter)
|
||||
handlers.append(file_handler)
|
||||
|
||||
# 配置根日志记录器
|
||||
logging.basicConfig(
|
||||
level=getattr(logging, log_level.upper()),
|
||||
handlers=handlers,
|
||||
force=True, # 强制重新配置
|
||||
)
|
||||
|
||||
# 设置第三方库的日志级别(由LOG_LEVEL控制)
|
||||
third_party_level = getattr(logging, log_level.upper())
|
||||
logging.getLogger("urllib3").setLevel(third_party_level)
|
||||
logging.getLogger("requests").setLevel(third_party_level)
|
||||
logging.getLogger("httpx").setLevel(third_party_level)
|
||||
logging.getLogger("httpcore").setLevel(third_party_level)
|
||||
|
||||
# 始终禁用噪音特别大的库
|
||||
logging.getLogger("numba").setLevel(logging.WARNING)
|
||||
logging.getLogger("numba.core").setLevel(logging.WARNING)
|
||||
logging.getLogger("numba.core.ssa").setLevel(logging.WARNING)
|
||||
|
||||
# 多 Worker 模式下记录启动日志
|
||||
if workers > 1 and worker_log_path:
|
||||
logger = logging.getLogger(__name__)
|
||||
logger.info(f"Worker {current_worker_id} 日志系统已初始化,日志文件: {worker_log_path}")
|
||||
|
|
@ -0,0 +1,173 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
安全相关功能
|
||||
包含鉴权、token验证等安全功能
|
||||
"""
|
||||
|
||||
from typing import Optional
|
||||
from fastapi import Request
|
||||
from .config import settings
|
||||
|
||||
TOKEN_HEADER_NAME = "X-NLS-Token"
|
||||
AUTH_OPTIONAL_PLACEHOLDER = "optional"
|
||||
WEBSOCKET_QUERY_TOKEN_KEYS = ("token", "x_nls_token", "X-NLS-Token")
|
||||
|
||||
|
||||
def normalize_token(token: Optional[str]) -> Optional[str]:
|
||||
"""将 token 归一化为非空字符串或 None。"""
|
||||
if token is None:
|
||||
return None
|
||||
|
||||
normalized = token.strip()
|
||||
return normalized or None
|
||||
|
||||
|
||||
def get_expected_api_key(expected_token: Optional[str] = None) -> Optional[str]:
|
||||
"""获取归一化后的期望 API_KEY。"""
|
||||
if expected_token is not None:
|
||||
return normalize_token(expected_token)
|
||||
return normalize_token(settings.API_KEY)
|
||||
|
||||
|
||||
def mask_sensitive_data(
|
||||
data: str, mask_char: str = "*", keep_prefix: int = 4, keep_suffix: int = 4
|
||||
) -> str:
|
||||
"""遮盖敏感数据
|
||||
|
||||
Args:
|
||||
data: 需要遮盖的数据
|
||||
mask_char: 遮盖字符
|
||||
keep_prefix: 保留前缀字符数
|
||||
keep_suffix: 保留后缀字符数
|
||||
|
||||
Returns:
|
||||
遮盖后的数据
|
||||
"""
|
||||
if not data or len(data) <= keep_prefix + keep_suffix:
|
||||
return data
|
||||
|
||||
prefix = data[:keep_prefix]
|
||||
suffix = data[-keep_suffix:] if keep_suffix > 0 else ""
|
||||
mask_length = len(data) - keep_prefix - keep_suffix
|
||||
mask = mask_char * mask_length
|
||||
|
||||
return f"{prefix}{mask}{suffix}"
|
||||
|
||||
|
||||
def validate_token_value(token: Optional[str], expected_token: Optional[str] = None) -> bool:
|
||||
"""验证访问令牌
|
||||
|
||||
Args:
|
||||
token: 客户端提供的token
|
||||
expected_token: 期望的token值(从环境变量读取),如果为None则鉴权可选
|
||||
|
||||
Returns:
|
||||
bool: 验证结果
|
||||
"""
|
||||
normalized_expected_token = get_expected_api_key(expected_token)
|
||||
if not normalized_expected_token:
|
||||
return True
|
||||
|
||||
normalized_token = normalize_token(token)
|
||||
if not normalized_token:
|
||||
return False
|
||||
|
||||
# 简单的token格式验证(长度检查)
|
||||
if len(normalized_token) < 10:
|
||||
return False
|
||||
|
||||
# 验证token是否匹配
|
||||
if normalized_token != normalized_expected_token:
|
||||
return False
|
||||
|
||||
return True
|
||||
|
||||
|
||||
def extract_header_token(request: Request) -> Optional[str]:
|
||||
"""从标准头部提取 token。"""
|
||||
return normalize_token(request.headers.get(TOKEN_HEADER_NAME))
|
||||
|
||||
|
||||
def extract_bearer_token(request: Request) -> Optional[str]:
|
||||
"""从 Authorization: Bearer 提取 token。"""
|
||||
auth_header = request.headers.get("Authorization")
|
||||
if not auth_header:
|
||||
return None
|
||||
|
||||
scheme, _, value = auth_header.partition(" ")
|
||||
if scheme.lower() != "bearer":
|
||||
return None
|
||||
return normalize_token(value)
|
||||
|
||||
|
||||
def extract_openai_token(request: Request) -> Optional[str]:
|
||||
"""OpenAI 兼容接口鉴权:优先 Bearer,其次 X-NLS-Token。"""
|
||||
return extract_bearer_token(request) or extract_header_token(request)
|
||||
|
||||
|
||||
def extract_websocket_token(websocket) -> Optional[str]:
|
||||
"""从 WebSocket 连接中提取 token。"""
|
||||
if hasattr(websocket, "headers"):
|
||||
token = normalize_token(websocket.headers.get(TOKEN_HEADER_NAME))
|
||||
if token:
|
||||
return token
|
||||
|
||||
if hasattr(websocket, "query_params"):
|
||||
for key in WEBSOCKET_QUERY_TOKEN_KEYS:
|
||||
token = normalize_token(websocket.query_params.get(key))
|
||||
if token:
|
||||
return token
|
||||
|
||||
return None
|
||||
|
||||
|
||||
def _validate_resolved_token(
|
||||
token: Optional[str],
|
||||
missing_message: str,
|
||||
expected_token: Optional[str] = None,
|
||||
) -> tuple[bool, str]:
|
||||
"""统一 token 校验逻辑。"""
|
||||
expected = get_expected_api_key(expected_token)
|
||||
normalized_token = normalize_token(token)
|
||||
|
||||
if not expected:
|
||||
return True, normalized_token or AUTH_OPTIONAL_PLACEHOLDER
|
||||
|
||||
if not normalized_token:
|
||||
return False, missing_message
|
||||
|
||||
if not validate_token_value(normalized_token, expected):
|
||||
masked_token = mask_sensitive_data(normalized_token)
|
||||
return False, f"Gateway:ACCESS_DENIED:The token '{masked_token}' is invalid!"
|
||||
|
||||
return True, normalized_token
|
||||
|
||||
|
||||
def validate_token(request: Request, task_id: str = "") -> tuple[bool, str]:
|
||||
"""验证X-NLS-Token头部"""
|
||||
_ = task_id
|
||||
token = extract_header_token(request)
|
||||
return _validate_resolved_token(token, "缺少X-NLS-Token头部")
|
||||
|
||||
|
||||
def validate_openai_token(request: Request, task_id: str = "") -> tuple[bool, str]:
|
||||
"""验证 OpenAI 兼容接口 token(Bearer/X-NLS-Token)。"""
|
||||
_ = task_id
|
||||
token = extract_openai_token(request)
|
||||
return _validate_resolved_token(token, "缺少Authorization Bearer或X-NLS-Token头部")
|
||||
|
||||
|
||||
def validate_token_websocket(token: str, task_id: str = "") -> tuple[bool, str]:
|
||||
"""验证WebSocket连接中的token"""
|
||||
_ = task_id
|
||||
return _validate_resolved_token(token, "缺少token参数")
|
||||
|
||||
|
||||
def validate_websocket_token(websocket, task_id: str = "") -> tuple[bool, str]:
|
||||
"""验证 WebSocket 连接 token(header/query 参数)。"""
|
||||
_ = task_id
|
||||
token = extract_websocket_token(websocket)
|
||||
return _validate_resolved_token(
|
||||
token,
|
||||
"缺少鉴权信息,请通过 X-NLS-Token header 或 token/x_nls_token 查询参数传入",
|
||||
)
|
||||
|
|
@ -0,0 +1,280 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Persistent task state store for meeting-style offline jobs."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import time
|
||||
from pathlib import Path
|
||||
from threading import RLock
|
||||
from typing import Any, Optional
|
||||
|
||||
from app.core.config import settings
|
||||
|
||||
tasks_db: dict[str, dict[str, Any]] = {}
|
||||
_tasks_lock = RLock()
|
||||
_last_cleanup_at = 0
|
||||
|
||||
|
||||
def _task_state_dir() -> Path:
|
||||
return Path(settings.TASK_STATE_DIR)
|
||||
|
||||
|
||||
def _task_file_path(task_id: str) -> Path:
|
||||
return _task_state_dir() / f"{task_id}.json"
|
||||
|
||||
|
||||
def _task_result_file_path(task_id: str) -> Path:
|
||||
return _task_state_dir() / f"{task_id}.result.json"
|
||||
|
||||
|
||||
def _retention_seconds() -> int:
|
||||
return max(0, int(settings.TASK_RETENTION_HOURS)) * 3600
|
||||
|
||||
|
||||
def _is_task_expired(task_payload: dict[str, Any], now_ts: Optional[int] = None) -> bool:
|
||||
retention_seconds = _retention_seconds()
|
||||
if retention_seconds <= 0:
|
||||
return False
|
||||
current_time = int(now_ts or time.time())
|
||||
base_timestamp = int(task_payload.get("updated_at") or task_payload.get("created_at") or 0)
|
||||
if base_timestamp <= 0:
|
||||
return False
|
||||
return current_time - base_timestamp >= retention_seconds
|
||||
|
||||
|
||||
def _write_json_file(file_path: Path, payload: dict[str, Any]) -> None:
|
||||
file_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
temporary_file_path = file_path.with_suffix(f"{file_path.suffix}.tmp")
|
||||
temporary_file_path.write_text(
|
||||
json.dumps(payload, ensure_ascii=False),
|
||||
encoding="utf-8",
|
||||
)
|
||||
temporary_file_path.replace(file_path)
|
||||
|
||||
|
||||
def _write_task_file(task_id: str, payload: dict[str, Any]) -> None:
|
||||
_write_json_file(_task_file_path(task_id), payload)
|
||||
|
||||
|
||||
def _remove_task_file(task_id: str) -> None:
|
||||
task_file_path = _task_file_path(task_id)
|
||||
if task_file_path.exists():
|
||||
task_file_path.unlink()
|
||||
|
||||
|
||||
def _write_task_result_file(task_id: str, payload: dict[str, Any]) -> None:
|
||||
_write_json_file(_task_result_file_path(task_id), payload)
|
||||
|
||||
|
||||
def _remove_task_result_file(task_id: str) -> None:
|
||||
task_result_file_path = _task_result_file_path(task_id)
|
||||
if task_result_file_path.exists():
|
||||
task_result_file_path.unlink()
|
||||
|
||||
|
||||
def _load_task_payload_from_file(task_file_path: Path) -> Optional[tuple[str, dict[str, Any]]]:
|
||||
try:
|
||||
payload = json.loads(task_file_path.read_text(encoding="utf-8"))
|
||||
except Exception:
|
||||
return None
|
||||
if not isinstance(payload, dict):
|
||||
return None
|
||||
task_id = str(payload.get("task_id") or task_file_path.stem).strip()
|
||||
if not task_id:
|
||||
return None
|
||||
payload["task_id"] = task_id
|
||||
return task_id, payload
|
||||
|
||||
|
||||
def _load_task_result_payload(task_id: str) -> Optional[dict[str, Any]]:
|
||||
task_result_file_path = _task_result_file_path(task_id)
|
||||
if not task_result_file_path.exists():
|
||||
return None
|
||||
try:
|
||||
payload = json.loads(task_result_file_path.read_text(encoding="utf-8"))
|
||||
except Exception:
|
||||
return None
|
||||
if not isinstance(payload, dict):
|
||||
return None
|
||||
return payload
|
||||
|
||||
|
||||
def _split_task_payload(task_id: str, payload: dict[str, Any], *, persist_legacy_result: bool = False) -> tuple[dict[str, Any], bool]:
|
||||
status_payload = dict(payload)
|
||||
has_result = "result" in status_payload
|
||||
result_payload = status_payload.pop("result", None)
|
||||
if has_result:
|
||||
if isinstance(result_payload, dict):
|
||||
_write_task_result_file(task_id, result_payload)
|
||||
elif result_payload is None:
|
||||
_remove_task_result_file(task_id)
|
||||
if persist_legacy_result:
|
||||
_write_task_file(task_id, status_payload)
|
||||
return status_payload, has_result
|
||||
|
||||
|
||||
def _status_file_paths() -> list[Path]:
|
||||
return [
|
||||
task_file_path
|
||||
for task_file_path in _task_state_dir().glob("*.json")
|
||||
if not task_file_path.name.endswith(".result.json")
|
||||
]
|
||||
|
||||
|
||||
def load_tasks_from_disk() -> None:
|
||||
with _tasks_lock:
|
||||
tasks_db.clear()
|
||||
task_directory = _task_state_dir()
|
||||
task_directory.mkdir(parents=True, exist_ok=True)
|
||||
current_time = int(time.time())
|
||||
for task_file_path in _status_file_paths():
|
||||
loaded_item = _load_task_payload_from_file(task_file_path)
|
||||
if loaded_item is None:
|
||||
try:
|
||||
task_file_path.unlink()
|
||||
except Exception:
|
||||
pass
|
||||
continue
|
||||
task_id, payload = loaded_item
|
||||
payload, _ = _split_task_payload(task_id, payload, persist_legacy_result=True)
|
||||
if _is_task_expired(payload, now_ts=current_time):
|
||||
try:
|
||||
task_file_path.unlink()
|
||||
except Exception:
|
||||
pass
|
||||
try:
|
||||
_remove_task_result_file(task_id)
|
||||
except Exception:
|
||||
pass
|
||||
continue
|
||||
tasks_db[task_id] = payload
|
||||
|
||||
|
||||
def cleanup_expired_tasks(force: bool = False) -> None:
|
||||
global _last_cleanup_at
|
||||
current_time = int(time.time())
|
||||
if not force and current_time - _last_cleanup_at < 60:
|
||||
return
|
||||
with _tasks_lock:
|
||||
expired_task_ids = [
|
||||
task_id
|
||||
for task_id, task_payload in tasks_db.items()
|
||||
if _is_task_expired(task_payload, now_ts=current_time)
|
||||
]
|
||||
for task_id in expired_task_ids:
|
||||
tasks_db.pop(task_id, None)
|
||||
try:
|
||||
_remove_task_file(task_id)
|
||||
except Exception:
|
||||
pass
|
||||
try:
|
||||
_remove_task_result_file(task_id)
|
||||
except Exception:
|
||||
pass
|
||||
for task_file_path in _status_file_paths():
|
||||
loaded_item = _load_task_payload_from_file(task_file_path)
|
||||
if loaded_item is None:
|
||||
try:
|
||||
task_file_path.unlink()
|
||||
except Exception:
|
||||
pass
|
||||
continue
|
||||
task_id, payload = loaded_item
|
||||
payload, _ = _split_task_payload(task_id, payload, persist_legacy_result=True)
|
||||
if _is_task_expired(payload, now_ts=current_time):
|
||||
try:
|
||||
task_file_path.unlink()
|
||||
except Exception:
|
||||
pass
|
||||
try:
|
||||
_remove_task_result_file(task_id)
|
||||
except Exception:
|
||||
pass
|
||||
_last_cleanup_at = current_time
|
||||
|
||||
|
||||
def recover_tasks_after_restart() -> None:
|
||||
load_tasks_from_disk()
|
||||
cleanup_expired_tasks(force=True)
|
||||
with _tasks_lock:
|
||||
for task_id, task_payload in list(tasks_db.items()):
|
||||
if str(task_payload.get("status") or "").strip() not in {"queued", "processing"}:
|
||||
continue
|
||||
interrupted_message = "服务已重启,原离线任务已中断,请重新提交。"
|
||||
task_payload.update(
|
||||
{
|
||||
"status": "failed",
|
||||
"stage": "failed",
|
||||
"message": interrupted_message,
|
||||
"error": interrupted_message,
|
||||
"percentage": 100,
|
||||
"updated_at": int(time.time()),
|
||||
}
|
||||
)
|
||||
tasks_db[task_id] = task_payload
|
||||
_write_task_file(task_id, task_payload)
|
||||
|
||||
|
||||
def create_task_record(task_id: str, payload: dict[str, Any]) -> dict[str, Any]:
|
||||
current_time = int(time.time())
|
||||
task_payload = dict(payload)
|
||||
task_payload["task_id"] = task_id
|
||||
task_payload.setdefault("created_at", current_time)
|
||||
task_payload["updated_at"] = current_time
|
||||
status_payload, has_result = _split_task_payload(task_id, task_payload)
|
||||
with _tasks_lock:
|
||||
tasks_db[task_id] = status_payload
|
||||
_write_task_file(task_id, status_payload)
|
||||
response_payload = dict(status_payload)
|
||||
if has_result:
|
||||
response_payload["result"] = _load_task_result_payload(task_id)
|
||||
return response_payload
|
||||
|
||||
|
||||
def get_task_record(task_id: str, *, include_result: bool = False) -> Optional[dict[str, Any]]:
|
||||
with _tasks_lock:
|
||||
task_file_path = _task_file_path(task_id)
|
||||
if task_file_path.exists():
|
||||
loaded_item = _load_task_payload_from_file(task_file_path)
|
||||
if loaded_item is None:
|
||||
return None
|
||||
loaded_task_id, task_payload = loaded_item
|
||||
task_payload, _ = _split_task_payload(
|
||||
loaded_task_id,
|
||||
task_payload,
|
||||
persist_legacy_result=True,
|
||||
)
|
||||
if loaded_task_id != task_id or _is_task_expired(task_payload):
|
||||
return None
|
||||
tasks_db[task_id] = task_payload
|
||||
else:
|
||||
task_payload = tasks_db.get(task_id)
|
||||
if task_payload is None:
|
||||
return None
|
||||
response_payload = dict(task_payload)
|
||||
if include_result:
|
||||
result_payload = _load_task_result_payload(task_id)
|
||||
if result_payload is not None:
|
||||
response_payload["result"] = result_payload
|
||||
return response_payload
|
||||
|
||||
|
||||
def update_task_record(task_id: str, payload: dict[str, Any]) -> dict[str, Any]:
|
||||
current_time = int(time.time())
|
||||
with _tasks_lock:
|
||||
task_payload = dict(tasks_db.get(task_id) or {})
|
||||
task_payload.update(payload)
|
||||
task_payload["task_id"] = task_id
|
||||
task_payload.setdefault("created_at", current_time)
|
||||
task_payload["updated_at"] = current_time
|
||||
status_payload, has_result = _split_task_payload(task_id, task_payload)
|
||||
tasks_db[task_id] = status_payload
|
||||
_write_task_file(task_id, status_payload)
|
||||
response_payload = dict(status_payload)
|
||||
if has_result:
|
||||
response_payload["result"] = _load_task_result_payload(task_id)
|
||||
return response_payload
|
||||
|
||||
|
||||
load_tasks_from_disk()
|
||||
|
|
@ -0,0 +1,199 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Conservative ASR text deduplication and filler cleanup."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
|
||||
from app.core.text_cleanup_lexicon import DISCOURSE_FILLER_TOKENS
|
||||
from app.core.text_cleanup_lexicon import FILLER_TOKENS
|
||||
from app.core.text_cleanup_lexicon import NUMERIC_STUTTER_CHARS
|
||||
from app.core.text_cleanup_lexicon import REPEAT_COLLAPSIBLE_DISCOURSE_TOKENS
|
||||
from app.core.text_cleanup_lexicon import SAFE_DOUBLE_WORDS
|
||||
from app.core.text_cleanup_lexicon import TERMINAL_FILLER_TOKENS
|
||||
|
||||
_PREFIX_STUTTER_CHARS = "这那离超和跟在对把将又还上先后了的"
|
||||
_PREFIX_STUTTER_PATTERN = re.compile(rf"([{re.escape(_PREFIX_STUTTER_CHARS)}])\1(?!\1)([\u4e00-\u9fffA-Za-z]{{1,3}})")
|
||||
_REPEATED_PHRASE_PATTERN = re.compile(r"([\u4e00-\u9fffA-Za-z]{2,4})\1")
|
||||
_WORD_STUTTER_PREFIX_PATTERN = re.compile(r"([\u4e00-\u9fff])\1{1,5}(?=\1[\u4e00-\u9fff])")
|
||||
_LONG_CHAR_REPEAT_PATTERN = re.compile(r"([\u4e00-\u9fff])\1{2,}")
|
||||
_INTERNAL_DOUBLE_CHAR_REPEAT_PATTERN = re.compile(r"(?<=[\u4e00-\u9fff])([\u4e00-\u9fff])\1(?=[\u4e00-\u9fff])")
|
||||
_SHORT_LEADING_STUTTER_TOKEN_PATTERN = re.compile(r"(^|[,。!?;:、,\s])([\u4e00-\u9fff])\2([\u4e00-\u9fff])(?=($|[,。!?;:、,\s]))")
|
||||
_SHORT_CONFIRMATION_STUTTER_PATTERN = re.compile(r"(^|[,。!?;:、,\s])([\u4e00-\u9fff])\2([\u4e00-\u9fff])(?=(是吧|对吧|对吗|对不对))")
|
||||
_REPEATED_SEPARATED_PHRASE_PATTERN = re.compile(r"([\u4e00-\u9fffA-Za-z]{1,6})([,、,\s]+)\1(?:\2\1)*")
|
||||
_REPEATED_SENTENCE_CLAUSE_PATTERN = re.compile(r"([\u4e00-\u9fffA-Za-z0-9]{2,12})([。!?;:]+)(?:\s*\1\2)+")
|
||||
_REPEATED_SHORT_SENTENCE_CLAUSE_PATTERN = re.compile(
|
||||
r"([\u4e00-\u9fff])([。!?;:]+)(?:\s*\1\2){2,}(?:\s*\1)?(?=$|[,。!?;:、,\s])"
|
||||
)
|
||||
_BOUNDARY_OVERLAP_MIN_CHARS = 2
|
||||
_BOUNDARY_OVERLAP_MAX_CHARS = 12
|
||||
_STANDALONE_FILLER_PATTERN = re.compile(rf"(^|[,。!?;:、,\s])({'|'.join(map(re.escape, FILLER_TOKENS))})(?=($|[,。!?;:、,\s]))")
|
||||
_FILLER_ONLY_PATTERN = re.compile(rf"^[\s,。!?;:、,]*(?:{'|'.join(map(re.escape, FILLER_TOKENS))}[\s,。!?;:、,]*)+$")
|
||||
_LEADING_FILLER_PREFIX_PATTERN = re.compile(rf"^(?:{'|'.join(map(re.escape, FILLER_TOKENS))})[,、,\s]*")
|
||||
_INLINE_FILLER_PATTERN = re.compile(r"(?<=[\u4e00-\u9fffA-Za-z0-9])(嗯|呃|啊|(?<!金)额(?!度))(?=[\u4e00-\u9fffA-Za-z0-9])")
|
||||
_REPEATED_DISCOURSE_FILLER_PATTERN = re.compile(
|
||||
rf"({'|'.join(map(re.escape, REPEAT_COLLAPSIBLE_DISCOURSE_TOKENS))})(?:[,、,\s]*\1)+"
|
||||
)
|
||||
_STANDALONE_DISCOURSE_FILLER_PATTERN = re.compile(
|
||||
rf"(^|[,。!?;:、,\s])({'|'.join(map(re.escape, DISCOURSE_FILLER_TOKENS))})(?=($|[,。!?;:、,\s]))"
|
||||
)
|
||||
_BRIDGE_FILLER_PATTERN = re.compile(r"(和|跟)(?:这个|那个)(和|跟)")
|
||||
_REPEATED_TOPIC_WITH_DEICTIC_PATTERN = re.compile(r"([\u4e00-\u9fffA-Za-z]{2,6})(这个|那个)\1(?=[这那])")
|
||||
_TERMINAL_FILLER_PATTERN = re.compile(
|
||||
rf"(?<=[\u4e00-\u9fffA-Za-z0-9%])(?:{'|'.join(map(re.escape, TERMINAL_FILLER_TOKENS))})(?=($|[,。!?;:、,\s]))"
|
||||
)
|
||||
_POST_PUNCT_TERMINAL_FILLER_PATTERN = re.compile(
|
||||
rf"(?<=[。!?;:,、,])(?:{'|'.join(map(re.escape, TERMINAL_FILLER_TOKENS))})(?=($|[,。!?;:、,\s]))"
|
||||
)
|
||||
_CURRENCY_STUTTER_PATTERN = re.compile(r"[¥¥]\s*\d{1,2}\s*[¥¥]\s*(\d{3,})(?=元?|[的档手]|$)")
|
||||
_CURRENCY_SYMBOL_PATTERN = re.compile(r"[¥¥]\s*(\d+(?:\.\d+)?)")
|
||||
_HOUSEHOLD_COLLECTION_GLUE_PATTERN = re.compile(r"(收集到)(\d{5,6})(户(?=的(?:一个)?清单))")
|
||||
_NUMERIC_TOKEN_CHARS = r"0-9零〇○O一幺二两三四五六七八九十百千万亿点"
|
||||
_REPEATED_NUMERIC_CLAUSE_PATTERN = re.compile(
|
||||
rf"(?<![A-Za-z0-9])([{_NUMERIC_TOKEN_CHARS}]{{1,8}})([,。!?;:、,\s]+)(?:\1\2){{2,}}"
|
||||
)
|
||||
|
||||
|
||||
def _is_numeric_like(text: str) -> bool:
|
||||
return bool(text) and all(character.isdigit() or character in "零〇○O一幺二两三四五六七八九十百千万亿点" for character in text)
|
||||
|
||||
|
||||
def _has_meaningful_overlap(text: str) -> bool:
|
||||
return bool(text and any(not character.isspace() and character not in ",。!?;:、,.!?;:" for character in text))
|
||||
|
||||
|
||||
def _collapse_internal_double_char(match: re.Match[str]) -> str:
|
||||
start_index = match.start()
|
||||
source_text = match.string
|
||||
pair_text = source_text[start_index:start_index + 2]
|
||||
if match.group(1) in NUMERIC_STUTTER_CHARS:
|
||||
return pair_text
|
||||
if pair_text in SAFE_DOUBLE_WORDS:
|
||||
return pair_text
|
||||
return match.group(1)
|
||||
|
||||
|
||||
def _remove_filler_words(text: str) -> str:
|
||||
normalized_text = str(text or "").strip()
|
||||
if not normalized_text:
|
||||
return normalized_text
|
||||
if _FILLER_ONLY_PATTERN.fullmatch(normalized_text):
|
||||
return ""
|
||||
compact_text = _LEADING_FILLER_PREFIX_PATTERN.sub("", normalized_text)
|
||||
compact_text = _INLINE_FILLER_PATTERN.sub("", compact_text)
|
||||
compact_text = _BRIDGE_FILLER_PATTERN.sub(lambda match: match.group(1) if match.group(1) == match.group(2) else match.group(2), compact_text)
|
||||
compact_text = _REPEATED_TOPIC_WITH_DEICTIC_PATTERN.sub(lambda match: match.group(1), compact_text)
|
||||
compact_text = _REPEATED_DISCOURSE_FILLER_PATTERN.sub(lambda match: match.group(1), compact_text)
|
||||
compact_text = _STANDALONE_FILLER_PATTERN.sub(lambda match: match.group(1), compact_text)
|
||||
compact_text = _STANDALONE_DISCOURSE_FILLER_PATTERN.sub(lambda match: match.group(1), compact_text)
|
||||
compact_text = _TERMINAL_FILLER_PATTERN.sub("", compact_text)
|
||||
compact_text = _POST_PUNCT_TERMINAL_FILLER_PATTERN.sub("", compact_text)
|
||||
compact_text = re.sub(r"([。!?;:])[。!?;:]+", r"\1", compact_text)
|
||||
compact_text = re.sub(r"([。!?;:])[,、,]+", r"\1", compact_text)
|
||||
compact_text = re.sub(r"[,、,\s]{2,}", ",", compact_text)
|
||||
compact_text = re.sub(r"^[,、,\s]+", "", compact_text)
|
||||
compact_text = re.sub(r"[,、,\s]+([。!?;:])", r"\1", compact_text)
|
||||
compact_text = re.sub(r"[,、,\s]+$", "", compact_text)
|
||||
if not compact_text or re.fullmatch(r"[\s,。!?;:、,]*", compact_text):
|
||||
return ""
|
||||
return compact_text
|
||||
|
||||
|
||||
def _repair_household_collection_count(match: re.Match[str]) -> str:
|
||||
prefix, digits, suffix = match.groups()
|
||||
following_context = match.string[match.end():match.end() + 100]
|
||||
|
||||
# Meeting reports often say "collected N households, estimated M households,
|
||||
# close to 50%". If the glued count has a plausible suffix matching that
|
||||
# ratio, keep the suffix and drop the noisy leading recognition artifact.
|
||||
if "50" in following_context:
|
||||
reference_counts = [
|
||||
int(value)
|
||||
for value in re.findall(r"(?:大概有|约|预计|测算[^,。!?;:]{0,10}?有)(\d{1,4})户", following_context)
|
||||
]
|
||||
for suffix_len in range(min(4, len(digits) - 1), 1, -1):
|
||||
candidate = int(digits[-suffix_len:])
|
||||
if candidate <= 0:
|
||||
continue
|
||||
if any(0.35 <= reference_count / candidate <= 0.65 for reference_count in reference_counts):
|
||||
return f"{prefix}{candidate}{suffix}"
|
||||
|
||||
return match.group(0)
|
||||
|
||||
|
||||
def _repair_numeric_asr_artifacts(text: str) -> str:
|
||||
repaired_text = _CURRENCY_STUTTER_PATTERN.sub(lambda match: f"{match.group(1)}元", text)
|
||||
repaired_text = _CURRENCY_SYMBOL_PATTERN.sub(lambda match: f"{match.group(1)}元", repaired_text)
|
||||
repaired_text = _HOUSEHOLD_COLLECTION_GLUE_PATTERN.sub(_repair_household_collection_count, repaired_text)
|
||||
return repaired_text
|
||||
|
||||
|
||||
def _collapse_repeated_numeric_clauses(text: str) -> str:
|
||||
return _REPEATED_NUMERIC_CLAUSE_PATTERN.sub(lambda match: f"{match.group(1)}{match.group(2)}", text)
|
||||
|
||||
|
||||
def _collapse_repeated_short_sentence_clauses(text: str) -> str:
|
||||
return _REPEATED_SHORT_SENTENCE_CLAUSE_PATTERN.sub(lambda match: f"{match.group(1)}{match.group(2)}", text)
|
||||
|
||||
|
||||
def deduplicate_asr_text(text: str) -> str:
|
||||
normalized_text = str(text or "").strip()
|
||||
if not normalized_text:
|
||||
return normalized_text
|
||||
previous_text = None
|
||||
while previous_text != normalized_text:
|
||||
previous_text = normalized_text
|
||||
normalized_text = _PREFIX_STUTTER_PATTERN.sub(lambda match: f"{match.group(1)}{match.group(2)}", normalized_text)
|
||||
|
||||
def _collapse_repeated_phrase(match: re.Match[str]) -> str:
|
||||
phrase = match.group(1)
|
||||
if _is_numeric_like(phrase):
|
||||
return match.group(0)
|
||||
return phrase
|
||||
|
||||
normalized_text = _REPEATED_PHRASE_PATTERN.sub(_collapse_repeated_phrase, normalized_text)
|
||||
normalized_text = _WORD_STUTTER_PREFIX_PATTERN.sub(lambda match: match.group(0) if match.group(1) in NUMERIC_STUTTER_CHARS else "", normalized_text)
|
||||
normalized_text = _LONG_CHAR_REPEAT_PATTERN.sub(lambda match: match.group(0) if match.group(1) in NUMERIC_STUTTER_CHARS else match.group(1), normalized_text)
|
||||
normalized_text = _INTERNAL_DOUBLE_CHAR_REPEAT_PATTERN.sub(_collapse_internal_double_char, normalized_text)
|
||||
normalized_text = _SHORT_LEADING_STUTTER_TOKEN_PATTERN.sub(lambda match: f"{match.group(1)}{match.group(2)}{match.group(3)}", normalized_text)
|
||||
|
||||
def _collapse_confirmation(match: re.Match[str]) -> str:
|
||||
repeated_pair = f"{match.group(2)}{match.group(2)}"
|
||||
if match.group(2) in NUMERIC_STUTTER_CHARS or repeated_pair in SAFE_DOUBLE_WORDS:
|
||||
return match.group(0)
|
||||
return f"{match.group(1)}{match.group(2)}{match.group(3)}"
|
||||
|
||||
normalized_text = _SHORT_CONFIRMATION_STUTTER_PATTERN.sub(_collapse_confirmation, normalized_text)
|
||||
|
||||
def _collapse_separated(match: re.Match[str]) -> str:
|
||||
phrase = match.group(1)
|
||||
if phrase.isascii() and len(phrase) == 1:
|
||||
return match.group(0)
|
||||
if _is_numeric_like(phrase):
|
||||
return match.group(0)
|
||||
return phrase
|
||||
|
||||
normalized_text = _REPEATED_SEPARATED_PHRASE_PATTERN.sub(_collapse_separated, normalized_text)
|
||||
normalized_text = _REPEATED_SENTENCE_CLAUSE_PATTERN.sub(lambda match: match.group(0) if _is_numeric_like(match.group(1)) else f"{match.group(1)}{match.group(2)}", normalized_text)
|
||||
normalized_text = _collapse_repeated_short_sentence_clauses(normalized_text)
|
||||
normalized_text = _collapse_repeated_numeric_clauses(normalized_text)
|
||||
normalized_text = _remove_filler_words(normalized_text)
|
||||
normalized_text = _repair_numeric_asr_artifacts(normalized_text)
|
||||
return normalized_text
|
||||
|
||||
|
||||
def trim_segment_boundary_overlap(previous_text: str, current_text: str) -> tuple[str, bool]:
|
||||
normalized_previous = str(previous_text or "").strip()
|
||||
normalized_current = str(current_text or "").strip()
|
||||
if not normalized_previous or not normalized_current:
|
||||
return normalized_current, False
|
||||
max_overlap_chars = min(len(normalized_previous), len(normalized_current), _BOUNDARY_OVERLAP_MAX_CHARS)
|
||||
for overlap_chars in range(max_overlap_chars, _BOUNDARY_OVERLAP_MIN_CHARS - 1, -1):
|
||||
overlap_suffix = normalized_previous[-overlap_chars:]
|
||||
overlap_prefix = normalized_current[:overlap_chars]
|
||||
if overlap_suffix != overlap_prefix:
|
||||
continue
|
||||
if not _has_meaningful_overlap(overlap_prefix):
|
||||
continue
|
||||
return normalized_current[overlap_chars:].lstrip(), True
|
||||
return normalized_current, False
|
||||
|
|
@ -0,0 +1,64 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Conservative ASR text cleanup lexicons."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
SAFE_DOUBLE_WORDS = {
|
||||
"哥哥",
|
||||
"叔叔",
|
||||
"爸爸",
|
||||
"妈妈",
|
||||
"奶奶",
|
||||
"爷爷",
|
||||
"姐姐",
|
||||
"弟弟",
|
||||
"妹妹",
|
||||
"伯伯",
|
||||
"姑姑",
|
||||
"舅舅",
|
||||
"星星",
|
||||
"猩猩",
|
||||
}
|
||||
|
||||
NUMERIC_STUTTER_CHARS = set("零〇○O一幺二两三四五六七八九十百千万亿点")
|
||||
|
||||
FILLER_TOKENS = (
|
||||
"啊",
|
||||
"呢",
|
||||
"吧",
|
||||
"哦",
|
||||
"嗯",
|
||||
"呃",
|
||||
"哈",
|
||||
"哇",
|
||||
"呀",
|
||||
"哎",
|
||||
"诶",
|
||||
"欸",
|
||||
"额",
|
||||
)
|
||||
|
||||
DISCOURSE_FILLER_TOKENS = (
|
||||
"那个",
|
||||
"这个",
|
||||
"然后",
|
||||
"所以说",
|
||||
"其实",
|
||||
"那么",
|
||||
)
|
||||
|
||||
REPEAT_COLLAPSIBLE_DISCOURSE_TOKENS = (
|
||||
"那个",
|
||||
"这个",
|
||||
"然后",
|
||||
"就是",
|
||||
"所以",
|
||||
"所以说",
|
||||
"其实",
|
||||
"那么",
|
||||
)
|
||||
|
||||
TERMINAL_FILLER_TOKENS = (
|
||||
"哈",
|
||||
"嗯",
|
||||
)
|
||||
|
|
@ -0,0 +1,8 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
基础设施层 - 提供底层通用功能
|
||||
"""
|
||||
|
||||
from .model_utils import resolve_model_path
|
||||
|
||||
__all__ = ["resolve_model_path"]
|
||||
|
|
@ -0,0 +1,48 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
模型工具模块 - 提供模型路径解析等通用功能
|
||||
"""
|
||||
|
||||
import logging
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from app.core.config import settings
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def resolve_model_path(model_id: Optional[str]) -> str:
|
||||
"""将模型 ID 解析为本地模型路径(如果存在)
|
||||
|
||||
本项目默认模型目录结构:
|
||||
./models/{publisher}/{model_name}/
|
||||
|
||||
如果本地模型存在,返回本地路径;否则返回原始 model_id
|
||||
"""
|
||||
if not model_id:
|
||||
raise ValueError("model_id 不能为空")
|
||||
|
||||
# 项目内扁平化模型根目录
|
||||
local_path = Path(settings.MODELSCOPE_PATH) / model_id
|
||||
|
||||
if local_path.exists() and local_path.is_dir():
|
||||
resolved = str(local_path)
|
||||
logger.info(f"模型 {model_id} 使用本地缓存: {resolved}")
|
||||
return resolved
|
||||
|
||||
# 兼容历史错误配置:MODELSCOPE_CACHE 指向了 models 目录时,
|
||||
# ModelScope 会生成 /models/models/{publisher}/{model_name}。
|
||||
legacy_nested_path = Path(settings.MODELSCOPE_PATH) / "models" / model_id
|
||||
if legacy_nested_path.exists() and legacy_nested_path.is_dir():
|
||||
resolved = str(legacy_nested_path)
|
||||
logger.warning(
|
||||
"模型 %s 命中历史嵌套缓存: %s。建议迁移到 %s",
|
||||
model_id,
|
||||
resolved,
|
||||
local_path,
|
||||
)
|
||||
return resolved
|
||||
|
||||
logger.warning(f"模型 {model_id} 本地缓存不存在,将在运行时下载")
|
||||
return model_id
|
||||
|
|
@ -0,0 +1,283 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
FastAPI应用创建和配置
|
||||
"""
|
||||
|
||||
import warnings
|
||||
import asyncio
|
||||
import os
|
||||
import logging
|
||||
from contextlib import asynccontextmanager
|
||||
from fastapi import FastAPI, HTTPException
|
||||
from fastapi.exceptions import RequestValidationError
|
||||
from fastapi_offline import FastAPIOffline
|
||||
from fastapi.middleware.cors import CORSMiddleware
|
||||
from fastapi.staticfiles import StaticFiles
|
||||
|
||||
from .core.config import settings
|
||||
from .core.exceptions import (
|
||||
APIException,
|
||||
api_exception_handler,
|
||||
general_exception_handler,
|
||||
http_exception_handler,
|
||||
validation_exception_handler,
|
||||
)
|
||||
from .core.logging import setup_logging, get_worker_id
|
||||
from .core.executor import shutdown_executor
|
||||
from .api.v1 import api_router
|
||||
from .utils.boot_events import emit_boot_event
|
||||
|
||||
# 忽略 Pydantic V2 兼容性警告
|
||||
warnings.filterwarnings("ignore", message="Valid config keys have changed in V2")
|
||||
warnings.filterwarnings("ignore", message=".*has conflict with protected namespace.*")
|
||||
warnings.filterwarnings("ignore", category=UserWarning, module="pydantic")
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
async def cleanup_task_state_loop():
|
||||
"""定期清理过期离线任务状态文件。"""
|
||||
while True:
|
||||
await asyncio.sleep(600)
|
||||
try:
|
||||
from .core.task_store import cleanup_expired_tasks
|
||||
|
||||
cleanup_expired_tasks(force=True)
|
||||
except asyncio.CancelledError:
|
||||
raise
|
||||
except Exception as exc:
|
||||
logger.warning("定期清理离线任务状态失败: %s", exc)
|
||||
|
||||
|
||||
def cleanup_temp_directory():
|
||||
"""清理临时目录中的旧文件"""
|
||||
import time
|
||||
temp_dir = settings.TEMP_DIR
|
||||
if not os.path.exists(temp_dir):
|
||||
return
|
||||
|
||||
# 清理超过 1 小时的临时文件
|
||||
max_age_seconds = 3600
|
||||
current_time = time.time()
|
||||
cleaned_count = 0
|
||||
|
||||
try:
|
||||
for filename in os.listdir(temp_dir):
|
||||
filepath = os.path.join(temp_dir, filename)
|
||||
if os.path.isfile(filepath):
|
||||
file_age = current_time - os.path.getmtime(filepath)
|
||||
if file_age > max_age_seconds:
|
||||
try:
|
||||
os.remove(filepath)
|
||||
cleaned_count += 1
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
if cleaned_count > 0:
|
||||
logger.info(f"已清理 {cleaned_count} 个过期临时文件")
|
||||
except Exception as e:
|
||||
logger.warning(f"清理临时目录时出错: {e}")
|
||||
|
||||
|
||||
@asynccontextmanager
|
||||
async def lifespan(app: FastAPI):
|
||||
"""应用生命周期管理"""
|
||||
workers = int(os.getenv("WORKERS", "1"))
|
||||
worker_id = get_worker_id()
|
||||
task_cleanup_task = None
|
||||
|
||||
# 启动时
|
||||
logger.info(f"Worker [{worker_id}] 启动中...")
|
||||
emit_boot_event("phase_start", phase="worker", total=1, message=f"Worker [{worker_id}] 启动中")
|
||||
|
||||
# 清理旧的临时文件(仅主 Worker 执行)
|
||||
if worker_id == 0:
|
||||
cleanup_temp_directory()
|
||||
try:
|
||||
from .core.task_store import recover_tasks_after_restart
|
||||
|
||||
recover_tasks_after_restart()
|
||||
except Exception as exc:
|
||||
logger.warning("恢复离线任务状态失败: %s", exc)
|
||||
task_cleanup_task = asyncio.create_task(cleanup_task_state_loop())
|
||||
|
||||
if settings.SPEAKER_DB_ENABLED:
|
||||
try:
|
||||
from .core.database import pg_speaker_db
|
||||
|
||||
await pg_speaker_db.connect()
|
||||
except Exception as exc:
|
||||
logger.warning(
|
||||
"声纹数据库连接失败,将保留原说话人编号并禁用声纹注册接口: %s",
|
||||
exc,
|
||||
)
|
||||
|
||||
from .utils.model_loader import (
|
||||
preload_models,
|
||||
verify_required_models_integrity,
|
||||
)
|
||||
|
||||
integrity_result = verify_required_models_integrity()
|
||||
if integrity_result["invalid_models"]:
|
||||
emit_boot_event("error", phase="integrity", message="required model integrity check failed")
|
||||
raise RuntimeError("required model integrity check failed")
|
||||
|
||||
logger.info(f"Worker [{worker_id}] 正在加载模型...")
|
||||
preload_result = preload_models()
|
||||
|
||||
asr_results = preload_result.get("asr_models", {})
|
||||
loaded_count = sum(1 for r in asr_results.values() if r.get("loaded"))
|
||||
total_count = len(asr_results)
|
||||
logger.info(f"Worker [{worker_id}] 模型加载完成: {loaded_count}/{total_count}")
|
||||
failed_asr_models = {
|
||||
model_id: status.get("error")
|
||||
for model_id, status in asr_results.items()
|
||||
if not status.get("loaded") and status.get("error")
|
||||
}
|
||||
try:
|
||||
from .services.asr.model_plan import get_active_qwen_model, load_supported_model_ids
|
||||
|
||||
active_qwen_model = get_active_qwen_model(load_supported_model_ids())
|
||||
except Exception as exc:
|
||||
logger.error(f"Worker [{worker_id}] 无法解析当前应启用的 Qwen 模型: {exc}")
|
||||
emit_boot_event("error", phase="preload", message=f"无法解析当前应启用的 Qwen 模型: {exc}")
|
||||
raise
|
||||
|
||||
active_qwen_status = asr_results.get(active_qwen_model, {})
|
||||
if not active_qwen_status.get("loaded"):
|
||||
qwen_error = active_qwen_status.get("error") or "unknown error"
|
||||
logger.error(
|
||||
f"Worker [{worker_id}] Qwen 主模型预加载失败,拒绝启动: {active_qwen_model}, error={qwen_error}"
|
||||
)
|
||||
emit_boot_event(
|
||||
"error",
|
||||
phase="preload",
|
||||
message=f"Qwen 主模型预加载失败,拒绝启动: {active_qwen_model}, error={qwen_error}",
|
||||
)
|
||||
raise RuntimeError(
|
||||
f"required qwen model preload failed: {active_qwen_model}: {qwen_error}"
|
||||
)
|
||||
|
||||
if failed_asr_models:
|
||||
if loaded_count == 0:
|
||||
logger.error(f"Worker [{worker_id}] ASR模型预加载失败详情: {failed_asr_models}")
|
||||
emit_boot_event("error", phase="preload", message=f"ASR模型预加载失败详情: {failed_asr_models}")
|
||||
raise RuntimeError(f"ASR model preload failed: {failed_asr_models}")
|
||||
logger.warning(
|
||||
f"Worker [{worker_id}] 部分ASR模型预加载失败,将以可用模型继续启动: {failed_asr_models}"
|
||||
)
|
||||
emit_boot_event(
|
||||
"warning",
|
||||
phase="preload",
|
||||
message=f"部分ASR模型预加载失败,将以可用模型继续启动: {failed_asr_models}",
|
||||
)
|
||||
|
||||
if settings.SPEAKER_DB_ENABLED:
|
||||
try:
|
||||
from .core.database import pg_speaker_db
|
||||
from .services.speaker_registry import get_speaker_registry_service
|
||||
|
||||
if pg_speaker_db.is_connected:
|
||||
logger.info(f"Worker [{worker_id}] 正在预加载声纹识别模型...")
|
||||
get_speaker_registry_service().ensure_loaded()
|
||||
except Exception as exc:
|
||||
logger.warning("声纹识别模型预加载失败,将在首次请求时重试: %s", exc)
|
||||
|
||||
logger.info(f"Worker [{worker_id}] 已就绪")
|
||||
emit_boot_event("ready", phase="worker", message=f"Worker [{worker_id}] 已就绪")
|
||||
|
||||
yield
|
||||
|
||||
# 关闭时
|
||||
if task_cleanup_task is not None:
|
||||
task_cleanup_task.cancel()
|
||||
try:
|
||||
await task_cleanup_task
|
||||
except asyncio.CancelledError:
|
||||
pass
|
||||
|
||||
if settings.SPEAKER_DB_ENABLED:
|
||||
try:
|
||||
from .core.database import pg_speaker_db
|
||||
|
||||
await pg_speaker_db.close()
|
||||
except Exception as exc:
|
||||
logger.warning("关闭声纹数据库连接时出错: %s", exc)
|
||||
logger.info(f"Worker [{worker_id}] 正在关闭推理线程池...")
|
||||
shutdown_executor()
|
||||
logger.info(f"Worker [{worker_id}] 已关闭")
|
||||
|
||||
|
||||
def create_app() -> FastAPI:
|
||||
"""创建FastAPI应用"""
|
||||
|
||||
# 设置日志
|
||||
setup_logging()
|
||||
|
||||
app = FastAPIOffline(
|
||||
title=settings.APP_NAME,
|
||||
description=settings.APP_DESCRIPTION,
|
||||
version=settings.APP_VERSION,
|
||||
docs_url=settings.docs_url,
|
||||
redoc_url=settings.redoc_url,
|
||||
lifespan=lifespan, # 添加生命周期管理
|
||||
)
|
||||
|
||||
# 添加CORS中间件
|
||||
app.add_middleware(
|
||||
CORSMiddleware,
|
||||
allow_origins=["*"],
|
||||
allow_credentials=True,
|
||||
allow_methods=["*"],
|
||||
allow_headers=["*"],
|
||||
)
|
||||
|
||||
# 注册异常处理器
|
||||
app.add_exception_handler(APIException, api_exception_handler)
|
||||
app.add_exception_handler(HTTPException, http_exception_handler)
|
||||
app.add_exception_handler(RequestValidationError, validation_exception_handler)
|
||||
app.add_exception_handler(Exception, general_exception_handler)
|
||||
|
||||
# 注册静态文件服务(用于临时文件)
|
||||
app.mount("/tmp", StaticFiles(directory=settings.TEMP_DIR), name="temp_files")
|
||||
app.mount(
|
||||
"/test-web",
|
||||
StaticFiles(directory=str(settings.BASE_DIR / "test_web"), html=True),
|
||||
name="test_web",
|
||||
)
|
||||
|
||||
# 注册API路由
|
||||
app.include_router(api_router)
|
||||
|
||||
# 根路径
|
||||
@app.get("/", summary="根路径", description="API服务根路径")
|
||||
async def root():
|
||||
return {
|
||||
"message": settings.APP_NAME,
|
||||
"version": settings.APP_VERSION,
|
||||
"description": settings.APP_DESCRIPTION,
|
||||
"endpoints": {
|
||||
# 阿里云兼容 API
|
||||
"asr": "/stream/v1/asr",
|
||||
"asr_models": "/stream/v1/asr/models",
|
||||
"asr_health": "/stream/v1/asr/health",
|
||||
"ws_asr": "/ws/v1/asr/qwen",
|
||||
"ws_qwen3_asr": "/ws/v1/asr/qwen",
|
||||
# OpenAI 兼容 API
|
||||
"openai_models": "/v1/models",
|
||||
"openai_transcriptions": "/v1/audio/transcriptions",
|
||||
# 独立会议离线 / 声纹管理 API
|
||||
"meeting_files": "/api/v1/files",
|
||||
"meeting_transcriptions": "/api/v1/asr/transcriptions",
|
||||
"speakers": "/api/v1/speakers",
|
||||
"test_web": "/test-web/",
|
||||
# 文档
|
||||
"docs": settings.docs_url or "禁用",
|
||||
},
|
||||
}
|
||||
|
||||
return app
|
||||
|
||||
|
||||
# 创建全局应用实例
|
||||
app = create_app()
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
数据模型模块
|
||||
包含API的请求和响应模型定义
|
||||
"""
|
||||
|
|
@ -0,0 +1,321 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
ASR数据模型
|
||||
定义语音识别相关的请求和响应模型
|
||||
"""
|
||||
|
||||
from typing import Optional, List, Union
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
from .common import (
|
||||
SampleRate,
|
||||
BaseResponse,
|
||||
HealthCheckResponse,
|
||||
ErrorResponse,
|
||||
)
|
||||
|
||||
|
||||
# ============= 请求模型 =============
|
||||
|
||||
|
||||
class ASRQueryParams(BaseModel):
|
||||
"""ASR接口查询参数模型"""
|
||||
|
||||
model: Optional[str] = Field(
|
||||
default=None,
|
||||
description="可选。离线 ASR 模型 ID;不传则使用服务当前默认模型,如 qwen3-asr-0.6b 或 qwen3-asr-1.7b",
|
||||
max_length=128,
|
||||
)
|
||||
|
||||
audio_address: Optional[str] = Field(
|
||||
default=None,
|
||||
description="音频/视频文件地址,支持 HTTP/HTTPS URL、file:// 或服务端本地路径,格式自动识别",
|
||||
max_length=512,
|
||||
)
|
||||
|
||||
sample_rate: Optional[SampleRate] = Field(
|
||||
default=SampleRate.RATE_16000,
|
||||
description=f"音频采样率(Hz)。支持: {', '.join(map(str, SampleRate.get_enums()))}",
|
||||
)
|
||||
|
||||
enable_speaker_diarization: Optional[bool] = Field(
|
||||
default=True,
|
||||
description="是否启用说话人分离。启用后响应会包含 speaker_id",
|
||||
)
|
||||
|
||||
enable_speaker_identification: Optional[bool] = Field(
|
||||
default=True,
|
||||
description="是否匹配已注册声纹库。仅在 enable_speaker_diarization=true 时生效",
|
||||
)
|
||||
|
||||
enable_text_cleanup: Optional[bool] = Field(
|
||||
default=True,
|
||||
description="是否启用文本去重和口头语清理",
|
||||
)
|
||||
|
||||
word_timestamps: Optional[bool] = Field(
|
||||
default=False,
|
||||
description="是否返回字词级时间戳(默认关闭;Qwen CUDA vLLM / CPU Rust 会在启用时自动调用 forced aligner)",
|
||||
)
|
||||
|
||||
vocabulary_id: Optional[str] = Field(
|
||||
default=None,
|
||||
description="热词字符串,格式:热词1 权重1 热词2 权重2(如:阿里巴巴 20 腾讯 15)",
|
||||
max_length=512,
|
||||
)
|
||||
|
||||
|
||||
# ============= 响应模型 =============
|
||||
|
||||
|
||||
class WordToken(BaseModel):
|
||||
"""字词级时间戳信息"""
|
||||
|
||||
text: str = Field(
|
||||
...,
|
||||
description="字词文本",
|
||||
)
|
||||
start_time: float = Field(
|
||||
...,
|
||||
description="开始时间(秒)",
|
||||
)
|
||||
end_time: float = Field(
|
||||
...,
|
||||
description="结束时间(秒)",
|
||||
)
|
||||
|
||||
model_config = {
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"text": "今",
|
||||
"start_time": 0.0,
|
||||
"end_time": 0.15,
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
class ASRSegment(BaseModel):
|
||||
"""ASR 识别分段结果"""
|
||||
|
||||
text: str = Field(
|
||||
...,
|
||||
description="该段识别文本",
|
||||
)
|
||||
start_time: float = Field(
|
||||
...,
|
||||
description="段落开始时间(秒)",
|
||||
)
|
||||
end_time: float = Field(
|
||||
...,
|
||||
description="段落结束时间(秒)",
|
||||
)
|
||||
speaker_id: Optional[str] = Field(
|
||||
default=None,
|
||||
description="说话人ID(如 说话人1),仅启用说话人分离时返回",
|
||||
)
|
||||
word_tokens: Optional[List[WordToken]] = Field(
|
||||
default=None,
|
||||
description="字词级时间戳(仅启用 word_timestamps 且模型支持时返回)",
|
||||
)
|
||||
|
||||
model_config = {
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"text": "今天天气不错。",
|
||||
"start_time": 0.0,
|
||||
"end_time": 2.5,
|
||||
"speaker_id": "说话人1",
|
||||
"word_tokens": [
|
||||
{"text": "今", "start_time": 0.0, "end_time": 0.15},
|
||||
{"text": "天", "start_time": 0.15, "end_time": 0.35},
|
||||
],
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
class ASRSuccessResponse(BaseResponse):
|
||||
"""ASR成功响应模型"""
|
||||
|
||||
result: str = Field(
|
||||
...,
|
||||
description="识别结果文本(完整)",
|
||||
max_length=100000,
|
||||
)
|
||||
|
||||
segments: Optional[List[ASRSegment]] = Field(
|
||||
default=None,
|
||||
description="分段识别结果(含时间戳),仅长音频分段识别时返回",
|
||||
)
|
||||
|
||||
duration: Optional[float] = Field(
|
||||
default=None,
|
||||
description="音频总时长(秒)",
|
||||
)
|
||||
|
||||
model_config = {
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"task_id": "cf7b0c5339244ee29cd4e43fb97f1234",
|
||||
"result": "今天天气不错。明天可能会下雨。",
|
||||
"segments": [
|
||||
{"text": "今天天气不错。", "start_time": 0.0, "end_time": 2.5, "speaker_id": "说话人1"},
|
||||
{"text": "明天可能会下雨。", "start_time": 3.2, "end_time": 5.8, "speaker_id": "说话人2"},
|
||||
],
|
||||
"duration": 5.8,
|
||||
"status": 200,
|
||||
"message": "SUCCESS",
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
class ASRErrorResponse(ErrorResponse):
|
||||
"""ASR错误响应模型"""
|
||||
|
||||
result: str = Field(default="", description="识别结果(错误时为空)")
|
||||
|
||||
model_config = {
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"task_id": "8bae3613dfc54ebfa811a17d8a7a1234",
|
||||
"result": "",
|
||||
"status": 40000001,
|
||||
"message": "Gateway:ACCESS_DENIED:The token 'invalid_token' is invalid!",
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
class ASRHealthCheckResponse(HealthCheckResponse):
|
||||
"""ASR健康检查响应模型"""
|
||||
|
||||
model_config = {
|
||||
"protected_namespaces": (),
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"status": "healthy",
|
||||
"model_loaded": True,
|
||||
"device": "cuda:0",
|
||||
"version": "1.0.0",
|
||||
"message": "ASR service is running normally",
|
||||
"loaded_models": ["qwen3-asr-1.7b"],
|
||||
"memory_usage": {
|
||||
"gpu_memory_used": "2.1GB",
|
||||
"gpu_memory_total": "8.0GB",
|
||||
},
|
||||
"accelerator": {
|
||||
"vendor": "nvidia",
|
||||
"runtime": "cuda",
|
||||
"device": "cuda:0",
|
||||
"device_count": 1,
|
||||
},
|
||||
},
|
||||
},
|
||||
}
|
||||
|
||||
model_loaded: bool = Field(..., description="模型是否已加载")
|
||||
device: str = Field(..., description="推理设备")
|
||||
loaded_models: Optional[List[str]] = Field(default=[], description="已加载的模型列表")
|
||||
memory_usage: Optional[dict] = Field(default=None, description="内存使用情况")
|
||||
accelerator: Optional[dict] = Field(default=None, description="加速器信息")
|
||||
|
||||
|
||||
# ============= 模型相关 =============
|
||||
|
||||
|
||||
class ASRDeclaredEntryInfo(BaseModel):
|
||||
"""声明式 ASR 条目信息,可表示离线模型或 realtime capability。"""
|
||||
|
||||
id: str = Field(..., description="模型id")
|
||||
kind: str = Field(..., description="条目类型:model 或 capability")
|
||||
name: str = Field(..., description="模型名称")
|
||||
engine: str = Field(..., description="引擎类型")
|
||||
description: str = Field(..., description="模型描述")
|
||||
languages: List[str] = Field(..., description="支持的语言列表")
|
||||
default: bool = Field(default=False, description="是否为默认模型")
|
||||
supports_realtime: bool = Field(default=False, description="是否支持实时识别")
|
||||
offline_model: Optional[dict] = Field(default=None, description="离线模型信息")
|
||||
realtime_model: Optional[dict] = Field(default=None, description="实时模型信息")
|
||||
|
||||
model_config = {
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"id": "qwen3-asr-1.7b",
|
||||
"kind": "model",
|
||||
"name": "Qwen3-ASR-1.7B",
|
||||
"engine": "qwen3",
|
||||
"description": "多语言离线语音识别模型",
|
||||
"languages": ["zh", "en"],
|
||||
"default": True,
|
||||
"supports_realtime": True,
|
||||
"offline_model": {
|
||||
"path": "Qwen/Qwen3-ASR-1.7B",
|
||||
"exists": True,
|
||||
},
|
||||
"realtime_model": None,
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
class ASRRuntimeInfo(BaseModel):
|
||||
"""运行时视角的模型加载状态。"""
|
||||
|
||||
loaded_model_ids: List[str] = Field(default_factory=list, description="当前已加载模型 ID 列表")
|
||||
loaded_count: int = Field(..., description="已加载模型数量")
|
||||
default_offline_model_id: Optional[str] = Field(default=None, description="当前默认离线模型 ID")
|
||||
|
||||
model_config = {
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"loaded_model_ids": ["qwen3-asr-1.7b"],
|
||||
"loaded_count": 1,
|
||||
"default_offline_model_id": "qwen3-asr-1.7b",
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
class ASRModelsResponse(BaseModel):
|
||||
"""ASR 模型列表响应,分离声明视角与运行时视角。"""
|
||||
|
||||
declared_entries: List[ASRDeclaredEntryInfo] = Field(..., description="声明的模型与 capability 列表")
|
||||
declared_count: int = Field(..., description="声明条目总数")
|
||||
runtime: ASRRuntimeInfo = Field(..., description="运行时加载状态")
|
||||
|
||||
model_config = {
|
||||
"json_schema_extra": {
|
||||
"example": {
|
||||
"declared_entries": [
|
||||
{
|
||||
"id": "qwen3-asr-1.7b",
|
||||
"kind": "model",
|
||||
"name": "Qwen3-ASR-1.7B",
|
||||
"engine": "qwen3",
|
||||
"description": "多语言离线语音识别模型",
|
||||
"languages": ["zh", "en"],
|
||||
"default": True,
|
||||
"supports_realtime": True,
|
||||
"offline_model": {
|
||||
"path": "Qwen/Qwen3-ASR-1.7B",
|
||||
"exists": True,
|
||||
},
|
||||
"realtime_model": None,
|
||||
}
|
||||
],
|
||||
"declared_count": 2,
|
||||
"runtime": {
|
||||
"loaded_model_ids": ["qwen3-asr-1.7b"],
|
||||
"loaded_count": 1,
|
||||
"default_offline_model_id": "qwen3-asr-1.7b",
|
||||
},
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
# ============= 联合响应类型 =============
|
||||
|
||||
ASRResponse = Union[ASRSuccessResponse, ASRErrorResponse]
|
||||
|
|
@ -0,0 +1,64 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
通用数据模型
|
||||
定义通用的枚举、基础模型等
|
||||
"""
|
||||
|
||||
from pydantic import BaseModel, Field
|
||||
from enum import Enum
|
||||
|
||||
|
||||
class AudioFormat(str, Enum):
|
||||
"""支持的音频格式"""
|
||||
|
||||
PCM = "pcm"
|
||||
WAV = "wav"
|
||||
OPUS = "opus"
|
||||
SPEEX = "speex"
|
||||
AMR = "amr"
|
||||
MP3 = "mp3"
|
||||
AAC = "aac"
|
||||
M4A = "m4a"
|
||||
FLAC = "flac"
|
||||
OGG = "ogg"
|
||||
|
||||
@classmethod
|
||||
def get_enums(cls):
|
||||
return [e.value for e in cls]
|
||||
|
||||
|
||||
class SampleRate(int, Enum):
|
||||
"""支持的采样率"""
|
||||
|
||||
RATE_8000 = 8000
|
||||
RATE_16000 = 16000
|
||||
RATE_22050 = 22050
|
||||
RATE_24000 = 24000
|
||||
|
||||
@classmethod
|
||||
def get_enums(cls):
|
||||
return [e.value for e in cls]
|
||||
|
||||
|
||||
class BaseResponse(BaseModel):
|
||||
"""基础响应模型"""
|
||||
|
||||
task_id: str = Field(..., description="任务ID")
|
||||
status: int = Field(..., description="状态码")
|
||||
message: str = Field(..., description="响应消息")
|
||||
|
||||
|
||||
class HealthCheckResponse(BaseModel):
|
||||
"""健康检查响应模型"""
|
||||
|
||||
status: str = Field(description="服务状态", examples=["healthy"])
|
||||
version: str = Field(description="服务版本", examples=["1.0.0"])
|
||||
message: str = Field(
|
||||
description="状态消息", examples=["Service is running normally"]
|
||||
)
|
||||
|
||||
|
||||
class ErrorResponse(BaseResponse):
|
||||
"""错误响应模型"""
|
||||
|
||||
result: str = Field("", description="结果内容")
|
||||
|
|
@ -0,0 +1,135 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
WebSocket ASR 数据模型 - 阿里云协议
|
||||
"""
|
||||
|
||||
from typing import Optional, Dict, Any, Union, List
|
||||
from pydantic import BaseModel, Field, field_validator
|
||||
import uuid
|
||||
|
||||
|
||||
class AliyunASRWSHeader(BaseModel):
|
||||
"""阿里云WebSocket ASR消息头部"""
|
||||
|
||||
message_id: str = Field(..., description="消息ID,32位唯一ID")
|
||||
task_id: str = Field(..., description="任务ID,32位唯一ID")
|
||||
namespace: str = Field(..., description="命名空间,固定为SpeechTranscriber")
|
||||
name: str = Field(..., description="消息名称")
|
||||
appkey: Optional[str] = Field(None, description="应用密钥")
|
||||
status: Optional[int] = Field(None, description="状态码")
|
||||
status_text: Optional[str] = Field(None, description="状态文本")
|
||||
status_message: Optional[str] = Field(None, description="状态消息")
|
||||
|
||||
@staticmethod
|
||||
def generate_message_id() -> str:
|
||||
"""生成32位消息ID"""
|
||||
return str(uuid.uuid4()).replace("-", "")[:32]
|
||||
|
||||
|
||||
class AliyunStartTranscriptionPayload(BaseModel):
|
||||
"""StartTranscription 消息负载"""
|
||||
|
||||
format: str = Field(default="pcm", description="音频格式: pcm, wav, opus, speex, amr, mp3, aac")
|
||||
sample_rate: int = Field(default=16000, description="音频采样率: 8000/16000")
|
||||
enable_intermediate_result: bool = Field(default=True, description="是否返回中间识别结果")
|
||||
enable_punctuation_prediction: bool = Field(default=True, description="是否在后处理中添加标点")
|
||||
enable_inverse_text_normalization: bool = Field(default=True, description="是否将中文数字转为阿拉伯数字")
|
||||
customization_id: Optional[str] = Field(None, description="自学习模型ID")
|
||||
vocabulary_id: Optional[str] = Field(None, description="定制泛热词ID")
|
||||
max_sentence_silence: int = Field(default=800, ge=200, le=2000, description="语音断句检测阈值(ms)")
|
||||
enable_words: bool = Field(default=False, description="是否开启返回词信息")
|
||||
disfluency: bool = Field(default=False, description="过滤语气词")
|
||||
speech_noise_threshold: Optional[float] = Field(None, ge=-1.0, le=1.0, description="噪音参数阈值")
|
||||
enable_semantic_sentence_detection: bool = Field(default=False, description="是否开启语义断句")
|
||||
|
||||
@field_validator("format")
|
||||
@classmethod
|
||||
def validate_format(cls, v):
|
||||
supported_formats = ["pcm", "wav", "opus", "speex", "amr", "mp3", "aac"]
|
||||
if v.lower() not in supported_formats:
|
||||
raise ValueError(f"不支持的音频格式: {v}")
|
||||
return v.lower()
|
||||
|
||||
@field_validator("sample_rate")
|
||||
@classmethod
|
||||
def validate_sample_rate(cls, v):
|
||||
supported_rates = [8000, 16000]
|
||||
if v not in supported_rates:
|
||||
raise ValueError(f"不支持的采样率: {v}")
|
||||
return v
|
||||
|
||||
|
||||
class AliyunWordInfo(BaseModel):
|
||||
"""词信息"""
|
||||
|
||||
text: str = Field("", description="文本")
|
||||
startTime: int = Field(0, description="词开始时间(ms)")
|
||||
endTime: int = Field(0, description="词结束时间(ms)")
|
||||
|
||||
|
||||
class AliyunTranscriptionResultPayload(BaseModel):
|
||||
"""识别结果负载"""
|
||||
|
||||
session_id: Optional[str] = Field(None, description="会话ID")
|
||||
index: Optional[int] = Field(None, description="句子编号,从1开始递增")
|
||||
time: Optional[int] = Field(None, description="已处理的音频时长(ms)")
|
||||
begin_time: Optional[int] = Field(None, description="句子开始时间(ms)")
|
||||
result: Optional[str] = Field(None, description="识别结果文本")
|
||||
confidence: Optional[float] = Field(None, description="置信度[0.0,1.0]")
|
||||
words: Optional[List[AliyunWordInfo]] = Field(None, description="词信息列表")
|
||||
status: Optional[int] = Field(None, description="状态码")
|
||||
|
||||
|
||||
class AliyunStashResult(BaseModel):
|
||||
"""暂存结果(语义断句)"""
|
||||
|
||||
sentenceId: int = Field(0, description="句子编号")
|
||||
beginTime: int = Field(0, description="句子开始时间(ms)")
|
||||
text: str = Field("", description="转写内容")
|
||||
currentTime: int = Field(0, description="当前处理时间(ms)")
|
||||
|
||||
|
||||
class AliyunASRWSMessage(BaseModel):
|
||||
"""阿里云WebSocket ASR消息"""
|
||||
|
||||
header: AliyunASRWSHeader = Field(..., description="消息头部")
|
||||
payload: Optional[
|
||||
Union[
|
||||
AliyunStartTranscriptionPayload,
|
||||
AliyunTranscriptionResultPayload,
|
||||
Dict[str, Any],
|
||||
]
|
||||
] = Field(None, description="消息负载")
|
||||
|
||||
|
||||
class AliyunASRNamespace:
|
||||
"""阿里云ASR命名空间"""
|
||||
|
||||
SPEECH_TRANSCRIBER = "SpeechTranscriber"
|
||||
|
||||
|
||||
class AliyunASRMessageName:
|
||||
"""阿里云ASR消息名称"""
|
||||
|
||||
START_TRANSCRIPTION = "StartTranscription"
|
||||
STOP_TRANSCRIPTION = "StopTranscription"
|
||||
|
||||
TRANSCRIPTION_STARTED = "TranscriptionStarted"
|
||||
SENTENCE_BEGIN = "SentenceBegin"
|
||||
TRANSCRIPTION_RESULT_CHANGED = "TranscriptionResultChanged"
|
||||
SENTENCE_END = "SentenceEnd"
|
||||
TRANSCRIPTION_COMPLETED = "TranscriptionCompleted"
|
||||
TASK_FAILED = "TaskFailed"
|
||||
|
||||
|
||||
class AliyunASRStatus:
|
||||
"""阿里云ASR状态码"""
|
||||
|
||||
SUCCESS = 20000000
|
||||
TASK_FAILED = 40000000
|
||||
INVALID_PARAMETER = 40000001
|
||||
MESSAGE_INVALID = 40000002
|
||||
AUTHENTICATION_FAILED = 40100005
|
||||
QUOTA_EXCEEDED = 40300016
|
||||
INTERNAL_ERROR = 50000000
|
||||
SERVICE_UNAVAILABLE = 50300018
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
服务层模块
|
||||
包含业务逻辑和模型管理
|
||||
"""
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
ASR服务模块
|
||||
包含语音识别相关的服务和引擎
|
||||
"""
|
||||
|
|
@ -0,0 +1,24 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Audio-related request validation helpers."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Optional
|
||||
|
||||
from ...core.exceptions import InvalidParameterException
|
||||
from ...models.common import SampleRate
|
||||
|
||||
|
||||
SUPPORTED_SAMPLE_RATES = SampleRate.get_enums()
|
||||
|
||||
|
||||
def validate_sample_rate(rate: Optional[int]) -> int:
|
||||
"""Validate input sample rate."""
|
||||
if not rate:
|
||||
return 16000
|
||||
|
||||
if rate not in SUPPORTED_SAMPLE_RATES:
|
||||
raise InvalidParameterException(
|
||||
f"不支持的采样率: {rate}。支持的采样率: {', '.join(map(str, SUPPORTED_SAMPLE_RATES))}"
|
||||
)
|
||||
return rate
|
||||
|
|
@ -0,0 +1,41 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
ASR引擎模块
|
||||
支持多种ASR引擎实现
|
||||
"""
|
||||
|
||||
# 基础类和数据类
|
||||
from .base import (
|
||||
BaseASREngine,
|
||||
RealTimeASREngine,
|
||||
WordToken,
|
||||
ASRSegmentResult,
|
||||
ASRFullResult,
|
||||
ASRRawResult,
|
||||
)
|
||||
|
||||
# 全局模型管理
|
||||
from .global_models import (
|
||||
get_global_vad_model,
|
||||
get_global_punc_model,
|
||||
get_global_punc_realtime_model,
|
||||
get_punc_inference_lock,
|
||||
get_punc_realtime_inference_lock,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
# 基础类
|
||||
"BaseASREngine",
|
||||
"RealTimeASREngine",
|
||||
# 数据类
|
||||
"WordToken",
|
||||
"ASRSegmentResult",
|
||||
"ASRFullResult",
|
||||
"ASRRawResult",
|
||||
# 全局模型管理
|
||||
"get_global_vad_model",
|
||||
"get_global_punc_model",
|
||||
"get_global_punc_realtime_model",
|
||||
"get_punc_inference_lock",
|
||||
"get_punc_realtime_inference_lock",
|
||||
]
|
||||
|
|
@ -0,0 +1,785 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
ASR引擎基础模块
|
||||
包含抽象基类和数据类定义
|
||||
"""
|
||||
|
||||
import time
|
||||
import logging
|
||||
from typing import Optional, Dict, List, Any, Callable
|
||||
from abc import ABC, abstractmethod
|
||||
from dataclasses import dataclass
|
||||
|
||||
from app.core.config import settings
|
||||
from app.core.exceptions import DefaultServerErrorException
|
||||
from app.core.text_cleanup import deduplicate_asr_text
|
||||
from app.core.text_cleanup import trim_segment_boundary_overlap
|
||||
from app.core.hotword_resolver import apply_hotword_rules
|
||||
from app.core.logging import log_inference_metrics
|
||||
from app.utils.audio import get_audio_duration
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def _log_asr_stage_timing(
|
||||
stage: str,
|
||||
duration_ms: float,
|
||||
*,
|
||||
task_id: Optional[str] = None,
|
||||
model_id: Optional[str] = None,
|
||||
audio_duration_sec: Optional[float] = None,
|
||||
**extra: Any,
|
||||
) -> None:
|
||||
"""Record structured timing for one ASR processing stage."""
|
||||
payload: Dict[str, Any] = {
|
||||
"event": "asr_stage_timing",
|
||||
"stage": stage,
|
||||
"duration_ms": round(duration_ms, 2),
|
||||
}
|
||||
if task_id:
|
||||
payload["task_id"] = task_id
|
||||
if model_id:
|
||||
payload["model_id"] = model_id
|
||||
if audio_duration_sec is not None:
|
||||
payload["audio_duration_sec"] = round(audio_duration_sec, 2)
|
||||
if audio_duration_sec > 0:
|
||||
payload["rtf"] = round((duration_ms / 1000) / audio_duration_sec, 4)
|
||||
payload.update(extra)
|
||||
logger.info("ASR阶段耗时", extra=payload)
|
||||
|
||||
|
||||
@dataclass
|
||||
class WordToken:
|
||||
"""字词级时间戳信息"""
|
||||
|
||||
text: str # 字词文本
|
||||
start_time: float # 开始时间(秒)
|
||||
end_time: float # 结束时间(秒)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ASRSegmentResult:
|
||||
"""ASR 分段识别结果"""
|
||||
|
||||
text: str # 该段识别文本
|
||||
start_time: float # 开始时间(秒)
|
||||
end_time: float # 结束时间(秒)
|
||||
speaker_id: Optional[str] = None # 说话人ID(多说话人模式)
|
||||
speaker_name: Optional[str] = None # 已注册声纹命中后的显示名称
|
||||
user_id: Optional[str] = None # 已注册声纹命中后的业务用户编号
|
||||
speaker_embedding: Optional[Any] = None # 片段声纹向量,仅供服务端匹配使用
|
||||
word_tokens: Optional[List[WordToken]] = None # 字词级时间戳(可选)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ASRFullResult:
|
||||
"""ASR 完整识别结果(支持长音频)"""
|
||||
|
||||
text: str # 完整识别文本
|
||||
segments: List[ASRSegmentResult] # 分段结果
|
||||
duration: float # 音频总时长(秒)
|
||||
|
||||
|
||||
@dataclass
|
||||
class ASRRawResult:
|
||||
"""ASR 原始识别结果(包含时间戳)"""
|
||||
|
||||
text: str # 完整识别文本
|
||||
segments: List[ASRSegmentResult] # 分段结果(从 VAD 时间戳解析)
|
||||
|
||||
|
||||
class BaseASREngine(ABC):
|
||||
"""基础ASR引擎抽象基类"""
|
||||
|
||||
@abstractmethod
|
||||
def transcribe_file(
|
||||
self,
|
||||
audio_path: str,
|
||||
hotwords: str = "",
|
||||
enable_punctuation: bool = False,
|
||||
enable_itn: bool = False,
|
||||
enable_vad: bool = False,
|
||||
sample_rate: int = 16000,
|
||||
) -> str:
|
||||
"""转录音频文件"""
|
||||
pass
|
||||
|
||||
@abstractmethod
|
||||
def transcribe_file_with_vad(
|
||||
self,
|
||||
audio_path: str,
|
||||
hotwords: str = "",
|
||||
enable_punctuation: bool = True,
|
||||
enable_itn: bool = True,
|
||||
sample_rate: int = 16000,
|
||||
**kwargs,
|
||||
) -> ASRRawResult:
|
||||
"""使用 VAD 转录音频文件,返回带时间戳分段的结果
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
hotwords: 热词/上下文提示
|
||||
enable_punctuation: 是否启用标点
|
||||
enable_itn: 是否启用 ITN
|
||||
sample_rate: 采样率
|
||||
**kwargs: 额外参数(如 word_timestamps 字词级时间戳)
|
||||
|
||||
Returns:
|
||||
ASRRawResult 包含文本和分段信息
|
||||
"""
|
||||
pass
|
||||
|
||||
def transcribe_long_audio(
|
||||
self,
|
||||
audio_path: str,
|
||||
hotwords: str = "",
|
||||
enable_punctuation: bool = False,
|
||||
enable_itn: bool = False,
|
||||
sample_rate: int = 16000,
|
||||
enable_speaker_diarization: bool = True,
|
||||
enable_speaker_identification: bool = True,
|
||||
enable_text_cleanup: bool = True,
|
||||
word_timestamps: bool = False,
|
||||
timestamp_scale: float = 1.0,
|
||||
task_id: Optional[str] = None,
|
||||
progress_callback: Optional[Callable[[str, str, int, Optional[dict[str, Any]]], None]] = None,
|
||||
) -> ASRFullResult:
|
||||
"""转录长音频文件(自动分段)
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
hotwords: 热词
|
||||
enable_punctuation: 是否启用标点
|
||||
enable_itn: 是否启用 ITN
|
||||
sample_rate: 采样率
|
||||
enable_speaker_diarization: 是否启用说话人分离
|
||||
enable_speaker_identification: 是否提取声纹向量用于匹配已注册声纹库
|
||||
enable_text_cleanup: 是否启用文本去重和口头语清理
|
||||
word_timestamps: 是否返回字词级时间戳(仅部分模型支持)
|
||||
timestamp_scale: Timestamp correction factor from audio normalization.
|
||||
task_id: 任务ID(用于日志追踪)
|
||||
|
||||
Returns:
|
||||
ASRFullResult: 包含完整文本、分段结果和时长的结果
|
||||
"""
|
||||
from app.utils.audio_splitter import AudioSplitter
|
||||
|
||||
# 开始性能计时
|
||||
start_time = time.time()
|
||||
start_perf = time.perf_counter()
|
||||
model_id = getattr(self, 'model_id', 'unknown')
|
||||
stage_timings_ms: Dict[str, float] = {
|
||||
"duration_probe_ms": 0.0,
|
||||
"speaker_diarization_ms": 0.0,
|
||||
"vad_audio_split_ms": 0.0,
|
||||
"asr_inference_ms": 0.0,
|
||||
"speaker_embedding_ms": 0.0,
|
||||
"cleanup_ms": 0.0,
|
||||
"text_cleanup_ms": 0.0,
|
||||
"hotword_resolver_ms": 0.0,
|
||||
}
|
||||
|
||||
task_prefix = f"[{task_id}] " if task_id else ""
|
||||
|
||||
def emit_progress(
|
||||
stage: str,
|
||||
message: str,
|
||||
percentage: int,
|
||||
detail: Optional[dict[str, Any]] = None,
|
||||
) -> None:
|
||||
if progress_callback is None:
|
||||
return
|
||||
try:
|
||||
progress_callback(stage, message, percentage, detail)
|
||||
except Exception as exc:
|
||||
logger.warning("%s进度回调失败: %s", task_prefix, exc)
|
||||
|
||||
logger.info(
|
||||
f"{task_prefix}[transcribe_long_audio] 音频: {audio_path}, "
|
||||
f"speaker_diarization={enable_speaker_diarization}, "
|
||||
f"speaker_identification={enable_speaker_identification}, "
|
||||
f"text_cleanup={enable_text_cleanup}, "
|
||||
f"word_level={word_timestamps}"
|
||||
)
|
||||
|
||||
try:
|
||||
# 获取音频时长
|
||||
duration_started = time.perf_counter()
|
||||
duration = get_audio_duration(audio_path)
|
||||
stage_timings_ms["duration_probe_ms"] = (
|
||||
time.perf_counter() - duration_started
|
||||
) * 1000
|
||||
_log_asr_stage_timing(
|
||||
"duration_probe",
|
||||
stage_timings_ms["duration_probe_ms"],
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
audio_duration_sec=duration,
|
||||
audio_path=audio_path,
|
||||
)
|
||||
logger.info(f"{task_prefix}[transcribe_long_audio] 音频时长: {duration:.2f}秒")
|
||||
emit_progress(
|
||||
"analyzing",
|
||||
f"音频时长 {duration:.1f} 秒,正在进行分割。",
|
||||
15,
|
||||
{"audio_duration_seconds": round(duration, 2)},
|
||||
)
|
||||
|
||||
# 统一使用分段处理
|
||||
speaker_segments = None
|
||||
audio_segments = None
|
||||
|
||||
if enable_speaker_diarization:
|
||||
# 多说话人:使用说话人分离
|
||||
from app.utils.speaker_diarizer import SpeakerDiarizer
|
||||
|
||||
logger.info(f"{task_prefix}使用说话人分离模式")
|
||||
emit_progress(
|
||||
"diarizing",
|
||||
"正在执行说话人分离。",
|
||||
18,
|
||||
{"audio_duration_seconds": round(duration, 2)},
|
||||
)
|
||||
diarizer = SpeakerDiarizer()
|
||||
diarization_started = time.perf_counter()
|
||||
speaker_segments = diarizer.split_audio_by_speakers(audio_path)
|
||||
stage_timings_ms["speaker_diarization_ms"] = (
|
||||
time.perf_counter() - diarization_started
|
||||
) * 1000
|
||||
speaker_audio_sec = sum(
|
||||
float(getattr(seg, "duration_sec", 0.0))
|
||||
for seg in (speaker_segments or [])
|
||||
)
|
||||
_log_asr_stage_timing(
|
||||
"speaker_diarization",
|
||||
stage_timings_ms["speaker_diarization_ms"],
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
audio_duration_sec=duration,
|
||||
segment_count=len(speaker_segments or []),
|
||||
segmented_audio_sec=round(speaker_audio_sec, 2),
|
||||
)
|
||||
|
||||
if not speaker_segments:
|
||||
logger.warning(f"{task_prefix}说话人分离未检测到片段,fallback 到 VAD 分割")
|
||||
|
||||
if not speaker_segments:
|
||||
# 单说话人:使用 VAD 分割
|
||||
logger.info(f"{task_prefix}使用 VAD 分割模式")
|
||||
emit_progress(
|
||||
"splitting",
|
||||
"正在执行 VAD 音频分割。",
|
||||
20,
|
||||
{"audio_duration_seconds": round(duration, 2)},
|
||||
)
|
||||
splitter = AudioSplitter(device=self.device)
|
||||
split_started = time.perf_counter()
|
||||
audio_segments = splitter.split_audio_file(audio_path)
|
||||
stage_timings_ms["vad_audio_split_ms"] = (
|
||||
time.perf_counter() - split_started
|
||||
) * 1000
|
||||
split_audio_sec = sum(
|
||||
float(getattr(seg, "duration_sec", 0.0))
|
||||
for seg in (audio_segments or [])
|
||||
)
|
||||
_log_asr_stage_timing(
|
||||
"vad_audio_split",
|
||||
stage_timings_ms["vad_audio_split_ms"],
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
audio_duration_sec=duration,
|
||||
segment_count=len(audio_segments or []),
|
||||
segmented_audio_sec=round(split_audio_sec, 2),
|
||||
)
|
||||
|
||||
# 选择要处理的片段
|
||||
segments_to_process = speaker_segments if speaker_segments else audio_segments
|
||||
if not segments_to_process:
|
||||
raise DefaultServerErrorException("音频分割失败:未生成任何片段")
|
||||
|
||||
logger.info(f"{task_prefix}音频已分割为 {len(segments_to_process)} 段")
|
||||
total_segments = len(segments_to_process)
|
||||
emit_progress(
|
||||
"transcribing",
|
||||
"开始批量识别。",
|
||||
30,
|
||||
{
|
||||
"segment_total": total_segments,
|
||||
"segment_completed": 0,
|
||||
"audio_duration_seconds": round(duration, 2),
|
||||
},
|
||||
)
|
||||
|
||||
results: List[ASRSegmentResult] = []
|
||||
|
||||
# 使用批处理推理
|
||||
batch_size = settings.ASR_BATCH_SIZE
|
||||
total_batches = (len(segments_to_process) + batch_size - 1) // batch_size
|
||||
logger.info(
|
||||
f"{task_prefix}使用批处理推理,batch_size={batch_size}, "
|
||||
f"word_timestamps={word_timestamps}"
|
||||
)
|
||||
|
||||
for batch_start in range(0, len(segments_to_process), batch_size):
|
||||
batch_end = min(batch_start + batch_size, len(segments_to_process))
|
||||
batch_segments = segments_to_process[batch_start:batch_end]
|
||||
batch_index = batch_start // batch_size + 1
|
||||
|
||||
logger.info(
|
||||
f"{task_prefix}推理批次 "
|
||||
f"{batch_index}/{total_batches}: "
|
||||
f"片段 {batch_start+1}-{batch_end}/{len(segments_to_process)}"
|
||||
)
|
||||
emit_progress(
|
||||
"transcribing",
|
||||
f"识别中:{batch_index}/{total_batches} 批,{batch_start}/{total_segments} 段",
|
||||
min(88, 30 + int((batch_start / max(total_segments, 1)) * 58)),
|
||||
{
|
||||
"segment_total": total_segments,
|
||||
"segment_completed": batch_start,
|
||||
"batch_index": batch_index,
|
||||
"batch_total": total_batches,
|
||||
"audio_duration_seconds": round(duration, 2),
|
||||
},
|
||||
)
|
||||
|
||||
try:
|
||||
# 批量推理,支持时间戳
|
||||
batch_started = time.perf_counter()
|
||||
batch_results = self._transcribe_batch(
|
||||
segments=batch_segments,
|
||||
hotwords=hotwords,
|
||||
enable_punctuation=enable_punctuation,
|
||||
enable_itn=enable_itn,
|
||||
sample_rate=sample_rate,
|
||||
word_timestamps=word_timestamps,
|
||||
)
|
||||
batch_inference_ms = (time.perf_counter() - batch_started) * 1000
|
||||
stage_timings_ms["asr_inference_ms"] += batch_inference_ms
|
||||
batch_audio_sec = sum(
|
||||
float(getattr(seg, "duration_sec", 0.0))
|
||||
for seg in batch_segments
|
||||
)
|
||||
|
||||
valid_batch_results = 0
|
||||
batch_embedding_ms = 0.0
|
||||
for seg, result in zip(batch_segments, batch_results):
|
||||
if result and result.text:
|
||||
valid_batch_results += 1
|
||||
start_sec = float(getattr(seg, "start_sec", 0.0))
|
||||
end_sec = float(getattr(seg, "end_sec", start_sec))
|
||||
speaker_embedding = None
|
||||
if (
|
||||
speaker_segments
|
||||
and settings.SPEAKER_DB_ENABLED
|
||||
and enable_speaker_identification
|
||||
):
|
||||
try:
|
||||
from app.core.database import pg_speaker_db
|
||||
from app.services.speaker_registry import (
|
||||
get_speaker_registry_service,
|
||||
)
|
||||
|
||||
audio_data = getattr(seg, "audio_data", None)
|
||||
if pg_speaker_db.is_connected and audio_data is not None:
|
||||
embedding_started = time.perf_counter()
|
||||
speaker_embedding = (
|
||||
get_speaker_registry_service()
|
||||
.extract_embedding_from_audio(audio_data)
|
||||
)
|
||||
batch_embedding_ms += (
|
||||
time.perf_counter() - embedding_started
|
||||
) * 1000
|
||||
except Exception as exc:
|
||||
logger.warning(
|
||||
"%s提取片段声纹向量失败,保留原说话人编号: %s",
|
||||
task_prefix,
|
||||
exc,
|
||||
)
|
||||
results.append(
|
||||
ASRSegmentResult(
|
||||
text=result.text,
|
||||
start_time=start_sec,
|
||||
end_time=end_sec,
|
||||
speaker_id=getattr(seg, "speaker_id", None),
|
||||
speaker_embedding=speaker_embedding,
|
||||
word_tokens=result.word_tokens if word_timestamps else None,
|
||||
)
|
||||
)
|
||||
stage_timings_ms["speaker_embedding_ms"] += batch_embedding_ms
|
||||
_log_asr_stage_timing(
|
||||
"asr_batch",
|
||||
batch_inference_ms,
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
audio_duration_sec=batch_audio_sec,
|
||||
batch_index=batch_index,
|
||||
batch_total=total_batches,
|
||||
segment_start=batch_start + 1,
|
||||
segment_end=batch_end,
|
||||
segment_total=total_segments,
|
||||
batch_segment_count=len(batch_segments),
|
||||
valid_segment_count=valid_batch_results,
|
||||
speaker_embedding_ms=round(batch_embedding_ms, 2),
|
||||
)
|
||||
|
||||
logger.info(
|
||||
f"{task_prefix}批次推理完成,有效片段: "
|
||||
f"{len([r for r in batch_results if r and r.text])}"
|
||||
)
|
||||
emit_progress(
|
||||
"transcribing",
|
||||
f"识别中:{batch_index}/{total_batches} 批,{batch_end}/{total_segments} 段",
|
||||
min(90, 30 + int((batch_end / max(total_segments, 1)) * 60)),
|
||||
{
|
||||
"segment_total": total_segments,
|
||||
"segment_completed": batch_end,
|
||||
"batch_index": batch_index,
|
||||
"batch_total": total_batches,
|
||||
"audio_duration_seconds": round(duration, 2),
|
||||
},
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"{task_prefix}批次推理失败: {e}, 跳过该批次")
|
||||
emit_progress(
|
||||
"transcribing",
|
||||
f"第 {batch_index}/{total_batches} 批识别失败,已跳过。",
|
||||
min(90, 30 + int((batch_end / max(total_segments, 1)) * 60)),
|
||||
{
|
||||
"segment_total": total_segments,
|
||||
"segment_completed": batch_end,
|
||||
"batch_index": batch_index,
|
||||
"batch_total": total_batches,
|
||||
"error": str(e),
|
||||
},
|
||||
)
|
||||
|
||||
# 清理临时文件(独立清理,避免条件遗漏)
|
||||
try:
|
||||
cleanup_started = time.perf_counter()
|
||||
if speaker_segments:
|
||||
from app.utils.speaker_diarizer import SpeakerDiarizer
|
||||
SpeakerDiarizer.cleanup_segments(speaker_segments)
|
||||
if audio_segments:
|
||||
AudioSplitter.cleanup_segments(audio_segments)
|
||||
stage_timings_ms["cleanup_ms"] = (
|
||||
time.perf_counter() - cleanup_started
|
||||
) * 1000
|
||||
_log_asr_stage_timing(
|
||||
"temp_cleanup",
|
||||
stage_timings_ms["cleanup_ms"],
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
segment_count=len(segments_to_process),
|
||||
)
|
||||
except Exception as e:
|
||||
logger.warning(f"清理临时文件时出错: {e}")
|
||||
|
||||
overlap_trimmed_count = 0
|
||||
if enable_text_cleanup:
|
||||
text_cleanup_started = time.perf_counter()
|
||||
cleaned_results: List[ASRSegmentResult] = []
|
||||
previous_text = ""
|
||||
for seg in results:
|
||||
cleaned_text = deduplicate_asr_text(seg.text)
|
||||
cleaned_text, was_trimmed = trim_segment_boundary_overlap(
|
||||
previous_text,
|
||||
cleaned_text,
|
||||
)
|
||||
if was_trimmed:
|
||||
overlap_trimmed_count += 1
|
||||
if not cleaned_text:
|
||||
continue
|
||||
seg.text = cleaned_text
|
||||
cleaned_results.append(seg)
|
||||
previous_text = cleaned_text
|
||||
|
||||
if len(cleaned_results) != len(results) or overlap_trimmed_count:
|
||||
logger.info(
|
||||
"%s文字去重完成:%s -> %s 段,边界重叠裁剪 %s 次",
|
||||
task_prefix,
|
||||
len(results),
|
||||
len(cleaned_results),
|
||||
overlap_trimmed_count,
|
||||
)
|
||||
results = cleaned_results
|
||||
stage_timings_ms["text_cleanup_ms"] = (
|
||||
time.perf_counter() - text_cleanup_started
|
||||
) * 1000
|
||||
_log_asr_stage_timing(
|
||||
"text_cleanup",
|
||||
stage_timings_ms["text_cleanup_ms"],
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
segment_count=len(results),
|
||||
overlap_trimmed_count=overlap_trimmed_count,
|
||||
cleanup_enabled=enable_text_cleanup,
|
||||
)
|
||||
|
||||
hotword_resolver_started = time.perf_counter()
|
||||
hotword_resolver_applied_count = 0
|
||||
matched_hotwords: list[str] = []
|
||||
if hotwords:
|
||||
for seg in results:
|
||||
resolved_text, was_applied, matched = apply_hotword_rules(
|
||||
seg.text,
|
||||
hotwords,
|
||||
)
|
||||
if resolved_text:
|
||||
seg.text = resolved_text
|
||||
if was_applied:
|
||||
hotword_resolver_applied_count += 1
|
||||
for hotword_text in matched:
|
||||
if hotword_text not in matched_hotwords:
|
||||
matched_hotwords.append(hotword_text)
|
||||
if hotwords:
|
||||
stage_timings_ms["hotword_resolver_ms"] = (
|
||||
time.perf_counter() - hotword_resolver_started
|
||||
) * 1000
|
||||
_log_asr_stage_timing(
|
||||
"hotword_resolver",
|
||||
stage_timings_ms["hotword_resolver_ms"],
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
segment_count=len(results),
|
||||
applied_segment_count=hotword_resolver_applied_count,
|
||||
matched_hotwords=matched_hotwords,
|
||||
)
|
||||
if hotword_resolver_applied_count:
|
||||
logger.info(
|
||||
"%s热词纠偏完成:命中 %s 段,热词=%s",
|
||||
task_prefix,
|
||||
hotword_resolver_applied_count,
|
||||
matched_hotwords,
|
||||
)
|
||||
all_texts = [seg.text for seg in results]
|
||||
full_text = "\n".join(all_texts)
|
||||
emit_progress(
|
||||
"finalizing",
|
||||
"分段识别完成,正在整理文本。",
|
||||
92,
|
||||
{
|
||||
"segment_total": len(segments_to_process),
|
||||
"segment_completed": len(segments_to_process),
|
||||
"valid_segment_count": len(results),
|
||||
"text_cleanup_enabled": enable_text_cleanup,
|
||||
"overlap_trimmed_count": overlap_trimmed_count,
|
||||
"audio_duration_seconds": round(duration, 2),
|
||||
},
|
||||
)
|
||||
|
||||
logger.info(
|
||||
f"长音频识别完成,共 {len(results)} 个有效分段,"
|
||||
f"总字符数: {len(full_text)}"
|
||||
)
|
||||
|
||||
# 计算性能指标
|
||||
total_duration_ms = (time.time() - start_time) * 1000
|
||||
total_perf_ms = (time.perf_counter() - start_perf) * 1000
|
||||
|
||||
if timestamp_scale != 1.0:
|
||||
for seg in results:
|
||||
seg.start_time *= timestamp_scale
|
||||
seg.end_time *= timestamp_scale
|
||||
if seg.word_tokens:
|
||||
for word_token in seg.word_tokens:
|
||||
word_token.start_time *= timestamp_scale
|
||||
word_token.end_time *= timestamp_scale
|
||||
duration *= timestamp_scale
|
||||
logger.info(
|
||||
f"{task_prefix}Timestamp scaling applied: scale={timestamp_scale:.6f}"
|
||||
)
|
||||
|
||||
_log_asr_stage_timing(
|
||||
"asr_total",
|
||||
total_perf_ms,
|
||||
task_id=task_id,
|
||||
model_id=model_id,
|
||||
audio_duration_sec=duration,
|
||||
segment_count=len(results),
|
||||
total_segment_count=len(segments_to_process),
|
||||
**{key: round(value, 2) for key, value in stage_timings_ms.items()},
|
||||
)
|
||||
log_inference_metrics(
|
||||
logger=logger,
|
||||
message="长音频识别完成",
|
||||
task_id=task_id,
|
||||
duration_ms=total_duration_ms,
|
||||
audio_duration_sec=duration,
|
||||
model_id=model_id,
|
||||
status="success",
|
||||
segments_count=len(results),
|
||||
batch_size=settings.ASR_BATCH_SIZE,
|
||||
event="asr_inference_metrics",
|
||||
**{key: round(value, 2) for key, value in stage_timings_ms.items()},
|
||||
enable_speaker_diarization=enable_speaker_diarization,
|
||||
enable_speaker_identification=enable_speaker_identification,
|
||||
enable_text_cleanup=enable_text_cleanup,
|
||||
word_timestamps=word_timestamps,
|
||||
)
|
||||
|
||||
return ASRFullResult(
|
||||
text=full_text,
|
||||
segments=results,
|
||||
duration=duration,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
# 计算失败时的性能指标
|
||||
total_duration_ms = (time.time() - start_time) * 1000
|
||||
try:
|
||||
duration = get_audio_duration(audio_path)
|
||||
except Exception:
|
||||
duration = 0
|
||||
|
||||
log_inference_metrics(
|
||||
logger=logger,
|
||||
message="长音频识别失败",
|
||||
task_id=task_id,
|
||||
duration_ms=total_duration_ms,
|
||||
audio_duration_sec=duration,
|
||||
model_id=model_id,
|
||||
status="error",
|
||||
error=str(e),
|
||||
)
|
||||
|
||||
logger.error(f"长音频识别失败: {e}")
|
||||
raise DefaultServerErrorException(f"长音频识别失败: {str(e)}")
|
||||
|
||||
@abstractmethod
|
||||
def is_model_loaded(self) -> bool:
|
||||
"""检查模型是否已加载"""
|
||||
pass
|
||||
|
||||
@property
|
||||
@abstractmethod
|
||||
def device(self) -> str:
|
||||
"""获取设备信息"""
|
||||
pass
|
||||
|
||||
@property
|
||||
@abstractmethod
|
||||
def supports_realtime(self) -> bool:
|
||||
"""是否支持实时识别"""
|
||||
pass
|
||||
|
||||
def _transcribe_batch(
|
||||
self,
|
||||
segments: List[Any],
|
||||
hotwords: str = "",
|
||||
enable_punctuation: bool = False,
|
||||
enable_itn: bool = False,
|
||||
sample_rate: int = 16000,
|
||||
word_timestamps: bool = False,
|
||||
) -> List[ASRSegmentResult]:
|
||||
"""批量推理多个音频片段
|
||||
|
||||
Args:
|
||||
segments: 音频片段列表(每个片段需要有 temp_file 属性)
|
||||
hotwords: 热词
|
||||
enable_punctuation: 是否启用标点
|
||||
enable_itn: 是否启用 ITN
|
||||
sample_rate: 采样率
|
||||
word_timestamps: 是否返回字词级时间戳
|
||||
|
||||
Returns:
|
||||
ASRSegmentResult 列表,与输入片段一一对应
|
||||
"""
|
||||
# 默认实现:逐个推理(子类可以重写实现真正的批处理)
|
||||
results = []
|
||||
for idx, seg in enumerate(segments):
|
||||
try:
|
||||
if not seg.temp_file:
|
||||
logger.warning(f"批处理片段 {idx + 1} 临时文件不存在,跳过")
|
||||
results.append(ASRSegmentResult(text="", start_time=0.0, end_time=0.0))
|
||||
continue
|
||||
|
||||
if word_timestamps:
|
||||
# 需要时间戳:使用 transcribe_file_with_vad
|
||||
raw_result = self.transcribe_file_with_vad(
|
||||
audio_path=seg.temp_file,
|
||||
hotwords=hotwords,
|
||||
enable_punctuation=enable_punctuation,
|
||||
enable_itn=enable_itn,
|
||||
sample_rate=sample_rate,
|
||||
word_timestamps=True,
|
||||
)
|
||||
if raw_result.segments:
|
||||
result_seg = raw_result.segments[0]
|
||||
results.append(
|
||||
ASRSegmentResult(
|
||||
text=result_seg.text,
|
||||
start_time=seg.start_sec,
|
||||
end_time=seg.end_sec,
|
||||
speaker_id=getattr(seg, 'speaker_id', None),
|
||||
word_tokens=result_seg.word_tokens,
|
||||
)
|
||||
)
|
||||
else:
|
||||
results.append(
|
||||
ASRSegmentResult(
|
||||
text=raw_result.text,
|
||||
start_time=seg.start_sec,
|
||||
end_time=seg.end_sec,
|
||||
speaker_id=getattr(seg, 'speaker_id', None),
|
||||
)
|
||||
)
|
||||
else:
|
||||
# 不需要时间戳:使用 transcribe_file
|
||||
text = self.transcribe_file(
|
||||
audio_path=seg.temp_file,
|
||||
hotwords=hotwords,
|
||||
enable_punctuation=enable_punctuation,
|
||||
enable_itn=enable_itn,
|
||||
enable_vad=False,
|
||||
sample_rate=sample_rate,
|
||||
)
|
||||
results.append(
|
||||
ASRSegmentResult(
|
||||
text=text or "",
|
||||
start_time=seg.start_sec,
|
||||
end_time=seg.end_sec,
|
||||
speaker_id=getattr(seg, 'speaker_id', None),
|
||||
)
|
||||
)
|
||||
except Exception as e:
|
||||
logger.error(f"批处理片段 {idx + 1} 推理失败: {e}")
|
||||
results.append(
|
||||
ASRSegmentResult(
|
||||
text="",
|
||||
start_time=getattr(seg, 'start_sec', 0.0),
|
||||
end_time=getattr(seg, 'end_sec', 0.0),
|
||||
speaker_id=getattr(seg, 'speaker_id', None),
|
||||
)
|
||||
)
|
||||
|
||||
return results
|
||||
|
||||
@staticmethod
|
||||
def _detect_device(device: str = "auto") -> str:
|
||||
"""检测可用设备"""
|
||||
from app.core.device import detect_device
|
||||
|
||||
return detect_device(device)
|
||||
|
||||
|
||||
class RealTimeASREngine(BaseASREngine):
|
||||
"""实时ASR引擎抽象基类"""
|
||||
|
||||
@property
|
||||
def supports_realtime(self) -> bool:
|
||||
"""支持实时识别"""
|
||||
return True
|
||||
|
||||
@abstractmethod
|
||||
def transcribe_websocket(
|
||||
self,
|
||||
audio_chunk: bytes,
|
||||
cache: Optional[Dict] = None,
|
||||
is_final: bool = False,
|
||||
**kwargs,
|
||||
) -> str:
|
||||
"""WebSocket流式语音识别"""
|
||||
pass
|
||||
|
|
@ -0,0 +1,141 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
全局VAD/PUNC模型管理模块
|
||||
提供线程安全的全局模型实例管理
|
||||
"""
|
||||
|
||||
import logging
|
||||
import threading
|
||||
from funasr import AutoModel
|
||||
|
||||
from app.core.config import settings
|
||||
from app.infrastructure import resolve_model_path
|
||||
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
# 全局语音活动检测(VAD)模型缓存(避免重复加载)
|
||||
_global_vad_model = None
|
||||
_vad_model_lock = threading.Lock()
|
||||
_vad_inference_lock = threading.Lock() # 推理互斥锁,防止并发状态混乱
|
||||
|
||||
# 全局标点符号模型缓存(避免重复加载)
|
||||
_global_punc_model = None
|
||||
_punc_model_lock = threading.Lock()
|
||||
_punc_inference_lock = threading.Lock() # 推理互斥锁,防止并发状态混乱
|
||||
|
||||
# 全局实时标点符号模型缓存(避免重复加载)
|
||||
_global_punc_realtime_model = None
|
||||
_punc_realtime_model_lock = threading.Lock()
|
||||
_punc_realtime_inference_lock = threading.Lock() # 推理互斥锁,防止并发状态混乱
|
||||
|
||||
|
||||
def _resolve_device(device: str) -> str:
|
||||
"""解析设备字符串,将 auto 转换为实际的设备"""
|
||||
from app.core.device import detect_device
|
||||
|
||||
return detect_device(device)
|
||||
|
||||
|
||||
def get_global_vad_model(device: str):
|
||||
"""获取全局语音活动检测(VAD)模型实例(线程安全,双重检查锁定)"""
|
||||
global _global_vad_model
|
||||
|
||||
if _global_vad_model is None:
|
||||
with _vad_model_lock:
|
||||
if _global_vad_model is None:
|
||||
try:
|
||||
# 解析模型路径:优先使用本地缓存
|
||||
resolved_vad_path = resolve_model_path(settings.VAD_MODEL)
|
||||
logger.info(f"正在加载全局语音活动检测(VAD)模型: {resolved_vad_path}")
|
||||
|
||||
# 解析 auto 设备
|
||||
resolved_device = _resolve_device(device)
|
||||
|
||||
_global_vad_model = AutoModel(
|
||||
model=resolved_vad_path,
|
||||
device=resolved_device,
|
||||
speech_noise_thres=0.6, # VAD 语音噪声阈值(FunASR默认0.6,设为0.7稍微严格一些,分段更碎)
|
||||
**settings.FUNASR_AUTOMODEL_KWARGS,
|
||||
)
|
||||
logger.info("全局语音活动检测(VAD)模型加载成功 (speech_noise_thres=0.6)")
|
||||
except Exception as e:
|
||||
logger.error(f"全局语音活动检测(VAD)模型加载失败: {str(e)}")
|
||||
_global_vad_model = None
|
||||
raise
|
||||
|
||||
return _global_vad_model
|
||||
|
||||
|
||||
def get_vad_inference_lock():
|
||||
"""获取VAD模型推理锁(线程安全)"""
|
||||
return _vad_inference_lock
|
||||
|
||||
|
||||
def get_global_punc_model(device: str):
|
||||
"""获取全局标点符号模型实例(离线版,线程安全,双重检查锁定)"""
|
||||
global _global_punc_model
|
||||
|
||||
if _global_punc_model is None:
|
||||
with _punc_model_lock:
|
||||
if _global_punc_model is None:
|
||||
try:
|
||||
# 解析模型路径:优先使用本地缓存
|
||||
resolved_punc_path = resolve_model_path(settings.PUNC_MODEL)
|
||||
logger.info(f"正在加载全局标点符号模型(离线): {resolved_punc_path}")
|
||||
|
||||
# 解析 auto 设备
|
||||
resolved_device = _resolve_device(device)
|
||||
|
||||
_global_punc_model = AutoModel(
|
||||
model=resolved_punc_path,
|
||||
device=resolved_device,
|
||||
**settings.FUNASR_AUTOMODEL_KWARGS,
|
||||
)
|
||||
logger.info("全局标点符号模型(离线)加载成功")
|
||||
except Exception as e:
|
||||
logger.error(f"全局标点符号模型(离线)加载失败: {str(e)}")
|
||||
_global_punc_model = None
|
||||
raise
|
||||
|
||||
return _global_punc_model
|
||||
|
||||
|
||||
def get_punc_inference_lock():
|
||||
"""获取PUNC模型推理锁(线程安全)"""
|
||||
return _punc_inference_lock
|
||||
|
||||
|
||||
def get_global_punc_realtime_model(device: str):
|
||||
"""获取全局实时标点符号模型实例(线程安全,双重检查锁定)"""
|
||||
global _global_punc_realtime_model
|
||||
|
||||
if _global_punc_realtime_model is None:
|
||||
with _punc_realtime_model_lock:
|
||||
if _global_punc_realtime_model is None:
|
||||
try:
|
||||
# 解析模型路径:优先使用本地缓存
|
||||
resolved_punc_realtime_path = resolve_model_path(settings.PUNC_REALTIME_MODEL)
|
||||
logger.info(f"正在加载全局标点符号模型(实时): {resolved_punc_realtime_path}")
|
||||
|
||||
# 解析 auto 设备
|
||||
resolved_device = _resolve_device(device)
|
||||
|
||||
_global_punc_realtime_model = AutoModel(
|
||||
model=resolved_punc_realtime_path,
|
||||
device=resolved_device,
|
||||
**settings.FUNASR_AUTOMODEL_KWARGS,
|
||||
)
|
||||
logger.info("全局标点符号模型(实时)加载成功")
|
||||
except Exception as e:
|
||||
logger.error(f"全局标点符号模型(实时)加载失败: {str(e)}")
|
||||
_global_punc_realtime_model = None
|
||||
raise
|
||||
|
||||
return _global_punc_realtime_model
|
||||
|
||||
|
||||
def get_punc_realtime_inference_lock():
|
||||
"""获取实时PUNC模型推理锁(线程安全)"""
|
||||
return _punc_realtime_inference_lock
|
||||
|
|
@ -0,0 +1,5 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
模型实现模块
|
||||
包含需要本地代码的自定义模型实现
|
||||
"""
|
||||
|
|
@ -0,0 +1,215 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""ASR model metadata and engine factory."""
|
||||
|
||||
import json
|
||||
import threading
|
||||
import logging
|
||||
from typing import Dict, Any, Optional, List
|
||||
from pathlib import Path
|
||||
|
||||
from typing import Callable
|
||||
from ...core.config import settings
|
||||
from ...core.exceptions import DefaultServerErrorException, InvalidParameterException
|
||||
from .engines import BaseASREngine
|
||||
from .model_plan import get_default_model_id
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# 引擎注册表(使用Any避免循环导入问题)
|
||||
_ENGINE_REGISTRY: Dict[str, Callable[[Any], BaseASREngine]] = {}
|
||||
|
||||
|
||||
def _supports_qwen_realtime_on_device(configured_device: str) -> bool:
|
||||
"""Resolve whether Qwen realtime mode is available on the active device."""
|
||||
from app.core.device import detect_device
|
||||
from app.core.accelerator import get_accelerator_info
|
||||
from .qwenasr_rust import is_qwenasr_rust_available
|
||||
|
||||
device = detect_device(configured_device)
|
||||
accelerator = get_accelerator_info()
|
||||
if accelerator.is_gpu and device.startswith("cuda"):
|
||||
return True
|
||||
if device == "cpu":
|
||||
return is_qwenasr_rust_available()
|
||||
return False
|
||||
|
||||
|
||||
def register_engine(engine_type: str, factory: Callable[[Any], BaseASREngine]):
|
||||
"""注册ASR引擎工厂函数"""
|
||||
_ENGINE_REGISTRY[engine_type] = factory
|
||||
logger.info(f"注册引擎类型: {engine_type}")
|
||||
|
||||
|
||||
class DeclaredEntryConfig:
|
||||
"""声明条目配置,可表示模型或 capability。"""
|
||||
|
||||
def __init__(self, model_id: str, config: Dict[str, Any]):
|
||||
self.model_id = model_id
|
||||
self.name = config["name"]
|
||||
self.kind = config.get("kind", "model")
|
||||
self.engine = config["engine"]
|
||||
self.description = config.get("description", "")
|
||||
self.languages = config.get("languages", [])
|
||||
self.supports_realtime = config.get("supports_realtime", False)
|
||||
|
||||
# 模型路径结构
|
||||
self.models = config.get("models", {})
|
||||
self.offline_model_path = self.models.get("offline")
|
||||
self.realtime_model_path = self.models.get("realtime")
|
||||
|
||||
# 额外参数(如 trust_remote_code 等)
|
||||
self.extra_kwargs = config.get("extra_kwargs", {})
|
||||
|
||||
@property
|
||||
def has_offline_model(self) -> bool:
|
||||
"""是否有离线模型"""
|
||||
return bool(self.offline_model_path)
|
||||
|
||||
@property
|
||||
def has_realtime_model(self) -> bool:
|
||||
"""是否有实时模型"""
|
||||
return bool(self.realtime_model_path)
|
||||
|
||||
class ModelManager:
|
||||
"""Static model metadata plus engine construction."""
|
||||
|
||||
def __init__(self):
|
||||
self._declared_entry_configs: Dict[str, DeclaredEntryConfig] = {}
|
||||
self._default_model_id: Optional[str] = None
|
||||
self._load_models_config()
|
||||
|
||||
def _load_models_config(self) -> None:
|
||||
"""加载模型配置文件"""
|
||||
models_file = Path(settings.models_config_path)
|
||||
if not models_file.exists():
|
||||
raise DefaultServerErrorException("models.json 配置文件不存在")
|
||||
|
||||
try:
|
||||
with open(models_file, "r", encoding="utf-8") as f:
|
||||
config = json.load(f)
|
||||
|
||||
for model_id, model_config in config["models"].items():
|
||||
self._declared_entry_configs[model_id] = DeclaredEntryConfig(model_id, model_config)
|
||||
self._default_model_id = get_default_model_id(
|
||||
all_model_ids=list(self._declared_entry_configs.keys()),
|
||||
)
|
||||
|
||||
if not self._default_model_id and self._declared_entry_configs:
|
||||
self._default_model_id = list(self._declared_entry_configs.keys())[0]
|
||||
|
||||
except (json.JSONDecodeError, KeyError) as e:
|
||||
raise DefaultServerErrorException(f"模型配置文件格式错误: {str(e)}")
|
||||
|
||||
def get_declared_entry_config(self, model_id: Optional[str] = None) -> DeclaredEntryConfig:
|
||||
"""获取声明条目配置。"""
|
||||
if model_id is None:
|
||||
model_id = self._default_model_id
|
||||
|
||||
if not model_id:
|
||||
raise InvalidParameterException("未指定模型且没有默认模型")
|
||||
|
||||
if model_id not in self._declared_entry_configs:
|
||||
available_models = ", ".join(self._declared_entry_configs.keys())
|
||||
raise InvalidParameterException(
|
||||
f"未知的模型: {model_id},可用模型: {available_models}"
|
||||
)
|
||||
|
||||
return self._declared_entry_configs[model_id]
|
||||
|
||||
def list_declared_entries(self) -> List[Dict[str, Any]]:
|
||||
"""列出声明的模型与 capability 元数据。"""
|
||||
entries = []
|
||||
for model_id, config in self._declared_entry_configs.items():
|
||||
offline_path_exists = False
|
||||
realtime_path_exists = False
|
||||
|
||||
if config.offline_model_path:
|
||||
offline_model_path = (
|
||||
Path(settings.MODELSCOPE_PATH) / config.offline_model_path
|
||||
)
|
||||
offline_path_exists = offline_model_path.exists()
|
||||
|
||||
if config.realtime_model_path:
|
||||
realtime_model_path = (
|
||||
Path(settings.MODELSCOPE_PATH) / config.realtime_model_path
|
||||
)
|
||||
realtime_path_exists = realtime_model_path.exists()
|
||||
|
||||
supports_realtime = config.supports_realtime
|
||||
if config.engine == "qwen3":
|
||||
supports_realtime = _supports_qwen_realtime_on_device(settings.DEVICE)
|
||||
|
||||
entries.append(
|
||||
{
|
||||
"id": model_id,
|
||||
"kind": config.kind,
|
||||
"name": config.name,
|
||||
"engine": config.engine,
|
||||
"description": config.description,
|
||||
"languages": config.languages,
|
||||
"default": model_id == self._default_model_id,
|
||||
"supports_realtime": supports_realtime,
|
||||
"offline_model": (
|
||||
{
|
||||
"path": config.offline_model_path,
|
||||
"exists": offline_path_exists,
|
||||
}
|
||||
if config.offline_model_path
|
||||
else None
|
||||
),
|
||||
"realtime_model": (
|
||||
{
|
||||
"path": config.realtime_model_path,
|
||||
"exists": realtime_path_exists,
|
||||
}
|
||||
if config.realtime_model_path
|
||||
else None
|
||||
),
|
||||
}
|
||||
)
|
||||
|
||||
return entries
|
||||
|
||||
def _create_engine(self, config: DeclaredEntryConfig) -> BaseASREngine:
|
||||
"""创建ASR引擎实例"""
|
||||
engine_type = config.engine.lower()
|
||||
factory = _ENGINE_REGISTRY.get(engine_type)
|
||||
if not factory:
|
||||
raise InvalidParameterException(
|
||||
f"不支持的引擎类型: {config.engine}"
|
||||
)
|
||||
return factory(config)
|
||||
|
||||
def create_engine(self, model_id: Optional[str] = None) -> BaseASREngine:
|
||||
"""Create a fresh engine instance."""
|
||||
config = self.get_declared_entry_config(model_id)
|
||||
return self._create_engine(config)
|
||||
|
||||
# 全局模型管理器实例
|
||||
_model_manager: Optional[ModelManager] = None
|
||||
_model_manager_lock = threading.Lock()
|
||||
|
||||
|
||||
def get_model_manager() -> ModelManager:
|
||||
"""获取全局模型管理器实例(线程安全)"""
|
||||
global _model_manager
|
||||
if _model_manager is None:
|
||||
with _model_manager_lock:
|
||||
if _model_manager is None:
|
||||
_model_manager = ModelManager()
|
||||
return _model_manager
|
||||
|
||||
|
||||
# 注册内置引擎
|
||||
def _register_builtin_engines():
|
||||
"""注册内置的ASR引擎"""
|
||||
try:
|
||||
from .qwen3_engine import Qwen3ASREngine # noqa: F401
|
||||
from .qwen3_engine import _register_qwen3_engine
|
||||
_register_qwen3_engine(register_engine, DeclaredEntryConfig)
|
||||
except ImportError as e:
|
||||
logger.warning(f"Qwen3引擎不可用: {e}")
|
||||
|
||||
|
||||
# 模块加载时自动注册内置引擎
|
||||
_register_builtin_engines()
|
||||
|
|
@ -0,0 +1,230 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Shared capability-to-model asset definitions."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import Literal, Optional
|
||||
|
||||
from app.core.config import settings
|
||||
from app.services.asr.manager import get_model_manager
|
||||
from app.services.asr.model_plan import (
|
||||
get_active_qwen_model,
|
||||
load_supported_model_ids,
|
||||
)
|
||||
|
||||
|
||||
ModelSource = Literal["modelscope"]
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ModelAsset:
|
||||
source: ModelSource
|
||||
model_id: str
|
||||
description: str
|
||||
revision: Optional[str] = None
|
||||
required_patterns: tuple[str, ...] = ()
|
||||
alternative_required_patterns: tuple[tuple[str, ...], ...] = ()
|
||||
min_total_size_bytes: int = 0
|
||||
|
||||
|
||||
_VAD_ASSETS = (
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id=settings.VAD_MODEL,
|
||||
description="VAD",
|
||||
revision="v2.0.2",
|
||||
required_patterns=("configuration.json", "config.yaml", "model.pb"),
|
||||
min_total_size_bytes=1_000_000,
|
||||
),
|
||||
)
|
||||
|
||||
_DIARIZATION_ASSETS = (
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id="iic/speech_campplus_speaker-diarization_common",
|
||||
description="CAM++ Diarization",
|
||||
required_patterns=(
|
||||
"configuration.json",
|
||||
"config.yaml",
|
||||
"onnx/asd.onnx",
|
||||
"onnx/face_recog_ir101.onnx",
|
||||
"onnx/fqa.onnx",
|
||||
"onnx/version-RFB-320.onnx",
|
||||
),
|
||||
min_total_size_bytes=50_000_000,
|
||||
),
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id=settings.SV_MODEL,
|
||||
description="Configured Speaker Verification",
|
||||
required_patterns=("configuration.json", "config.yaml", "campplus_cn_common.bin"),
|
||||
min_total_size_bytes=10_000_000,
|
||||
),
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id=settings.REALTIME_SV_MODEL,
|
||||
description="Realtime Speaker Verification",
|
||||
required_patterns=("configuration.json",),
|
||||
min_total_size_bytes=10_000_000,
|
||||
),
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id="damo/speech_campplus_sv_zh-cn_16k-common",
|
||||
description="CAM++ Speaker Verification",
|
||||
required_patterns=("configuration.json", "config.yaml", "campplus_cn_common.bin"),
|
||||
min_total_size_bytes=10_000_000,
|
||||
),
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id="damo/speech_campplus-transformer_scl_zh-cn_16k-common",
|
||||
description="CAM++ Transformer",
|
||||
required_patterns=("configuration.json", "campplus_cn_encoder.pt", "transformer_backend.pt"),
|
||||
min_total_size_bytes=10_000_000,
|
||||
),
|
||||
)
|
||||
|
||||
def get_download_modelscope_assets() -> list[ModelAsset]:
|
||||
"""Return the full static ModelScope export set used by predownload/export."""
|
||||
return _dedupe_assets([
|
||||
*_VAD_ASSETS,
|
||||
*_DIARIZATION_ASSETS,
|
||||
])
|
||||
|
||||
|
||||
def get_runtime_required_modelscope_assets(
|
||||
*,
|
||||
include_realtime_punc: bool,
|
||||
) -> list[ModelAsset]:
|
||||
"""Return ModelScope assets required by the current runtime plan."""
|
||||
_ = include_realtime_punc
|
||||
return _dedupe_assets([*_VAD_ASSETS, *_DIARIZATION_ASSETS])
|
||||
|
||||
|
||||
def _dedupe_assets(assets: list[ModelAsset]) -> list[ModelAsset]:
|
||||
deduped: list[ModelAsset] = []
|
||||
seen: set[tuple[str, str]] = set()
|
||||
for asset in assets:
|
||||
key = (asset.source, asset.model_id)
|
||||
if key in seen:
|
||||
continue
|
||||
seen.add(key)
|
||||
deduped.append(asset)
|
||||
return deduped
|
||||
|
||||
|
||||
def get_camplusplus_replacement_paths(cache_dir: str) -> dict[str, str]:
|
||||
"""Return the CAM++ offline replacement map for local cache paths."""
|
||||
return {
|
||||
"damo/speech_campplus_sv_zh-cn_16k-common": f"{cache_dir}/damo/speech_campplus_sv_zh-cn_16k-common",
|
||||
"iic/speech_campplus_sv_zh-cn_16k-common": f"{cache_dir}/iic/speech_campplus_sv_zh-cn_16k-common",
|
||||
"damo/speech_campplus-transformer_scl_zh-cn_16k-common": f"{cache_dir}/damo/speech_campplus-transformer_scl_zh-cn_16k-common",
|
||||
"damo/speech_campplus-transformer_scl_zh-cn-16k-common": f"{cache_dir}/damo/speech_campplus-transformer_scl_zh-cn-16k-common",
|
||||
"damo/speech_fsmn_vad_zh-cn-16k-common-pytorch": f"{cache_dir}/damo/speech_fsmn_vad_zh-cn-16k-common-pytorch",
|
||||
}
|
||||
|
||||
|
||||
_QWEN_MODELSCOPE_MODEL_IDS = {
|
||||
"Qwen/Qwen3-ASR-0.6B": "Qwen/Qwen3-ASR-0.6B",
|
||||
"Qwen/Qwen3-ASR-1.7B": "Qwen/Qwen3-ASR-1.7B",
|
||||
"Qwen/Qwen3-ForcedAligner-0.6B": "Qwen/Qwen3-ForcedAligner-0.6B",
|
||||
}
|
||||
|
||||
|
||||
def get_qwen_modelscope_model_id(model_id: str) -> Optional[str]:
|
||||
"""Map runtime Qwen model ID to the corresponding ModelScope model ID.
|
||||
|
||||
Returns:
|
||||
ModelScope model ID if available, None otherwise.
|
||||
"""
|
||||
return _QWEN_MODELSCOPE_MODEL_IDS.get(model_id)
|
||||
|
||||
|
||||
def get_enabled_qwen_modelscope_assets(
|
||||
*,
|
||||
include_forced_aligner: bool = True,
|
||||
) -> list[ModelAsset]:
|
||||
"""Return ModelScope assets required by the runtime Qwen plan."""
|
||||
manager = get_model_manager()
|
||||
assets: list[ModelAsset] = []
|
||||
model_id = get_active_qwen_model()
|
||||
model_config = manager.get_declared_entry_config(model_id)
|
||||
offline_model = model_config.offline_model_path
|
||||
if offline_model:
|
||||
ms_model_id = get_qwen_modelscope_model_id(offline_model)
|
||||
if ms_model_id:
|
||||
assets.append(
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id=ms_model_id,
|
||||
description=f"{model_config.name} Offline (ModelScope)",
|
||||
required_patterns=("config.json",),
|
||||
alternative_required_patterns=(
|
||||
("model.safetensors",),
|
||||
("model-*.safetensors",),
|
||||
),
|
||||
min_total_size_bytes=500_000_000,
|
||||
)
|
||||
)
|
||||
forced_aligner = str(model_config.extra_kwargs.get("forced_aligner_path") or "").strip()
|
||||
if forced_aligner and include_forced_aligner:
|
||||
ms_aligner_id = get_qwen_modelscope_model_id(forced_aligner)
|
||||
if ms_aligner_id:
|
||||
assets.append(
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id=ms_aligner_id,
|
||||
description=f"{model_config.name} Forced Aligner (ModelScope)",
|
||||
required_patterns=("config.json", "model.safetensors"),
|
||||
min_total_size_bytes=500_000_000,
|
||||
)
|
||||
)
|
||||
return assets
|
||||
|
||||
|
||||
def get_all_qwen_modelscope_assets(
|
||||
*,
|
||||
include_forced_aligner: bool = True,
|
||||
) -> list[ModelAsset]:
|
||||
"""Return all declared Qwen ModelScope assets for offline bundles."""
|
||||
manager = get_model_manager()
|
||||
assets: list[ModelAsset] = []
|
||||
seen_model_ids: set[str] = set()
|
||||
|
||||
for model_id in sorted(load_supported_model_ids()):
|
||||
if not model_id.startswith("qwen3-asr-"):
|
||||
continue
|
||||
model_config = manager.get_declared_entry_config(model_id)
|
||||
offline_model = model_config.offline_model_path
|
||||
if offline_model:
|
||||
ms_model_id = get_qwen_modelscope_model_id(offline_model)
|
||||
if ms_model_id and ms_model_id not in seen_model_ids:
|
||||
seen_model_ids.add(ms_model_id)
|
||||
assets.append(
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id=ms_model_id,
|
||||
description=f"{model_config.name} Offline (ModelScope)",
|
||||
required_patterns=("config.json",),
|
||||
alternative_required_patterns=(
|
||||
("model.safetensors",),
|
||||
("model-*.safetensors",),
|
||||
),
|
||||
min_total_size_bytes=500_000_000,
|
||||
)
|
||||
)
|
||||
forced_aligner = str(model_config.extra_kwargs.get("forced_aligner_path") or "").strip()
|
||||
if forced_aligner and include_forced_aligner:
|
||||
ms_aligner_id = get_qwen_modelscope_model_id(forced_aligner)
|
||||
if ms_aligner_id and ms_aligner_id not in seen_model_ids:
|
||||
seen_model_ids.add(ms_aligner_id)
|
||||
assets.append(
|
||||
ModelAsset(
|
||||
source="modelscope",
|
||||
model_id=ms_aligner_id,
|
||||
description="Qwen3 Forced Aligner (ModelScope)",
|
||||
required_patterns=("config.json", "model.safetensors"),
|
||||
min_total_size_bytes=500_000_000,
|
||||
)
|
||||
)
|
||||
return assets
|
||||
|
|
@ -0,0 +1,105 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Single-source deployment model planning."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
import platform
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from app.core.config import settings
|
||||
|
||||
QWEN_MODEL_OVERRIDE_ENV = "QWEN3_ASR_MODEL"
|
||||
_QWEN_MODEL_ALIASES = {
|
||||
"qwen3-asr-0.6b": "qwen3-asr-0.6b",
|
||||
"0.6b": "qwen3-asr-0.6b",
|
||||
"0.6": "qwen3-asr-0.6b",
|
||||
"qwen/qwen3-asr-0.6b": "qwen3-asr-0.6b",
|
||||
"qwen3-asr-1.7b": "qwen3-asr-1.7b",
|
||||
"1.7b": "qwen3-asr-1.7b",
|
||||
"1.7": "qwen3-asr-1.7b",
|
||||
"qwen/qwen3-asr-1.7b": "qwen3-asr-1.7b",
|
||||
}
|
||||
|
||||
|
||||
def load_supported_model_ids() -> list[str]:
|
||||
"""Load declared model ids from models.json."""
|
||||
models_file = Path(settings.models_config_path)
|
||||
if not models_file.exists():
|
||||
return []
|
||||
|
||||
with open(models_file, "r", encoding="utf-8") as f:
|
||||
config = json.load(f)
|
||||
|
||||
return list(config.get("models", {}).keys())
|
||||
|
||||
|
||||
def get_qwen_model_override() -> Optional[str]:
|
||||
"""Return the explicit Qwen model override from the environment."""
|
||||
raw_value = (os.getenv(QWEN_MODEL_OVERRIDE_ENV) or "").strip()
|
||||
if not raw_value:
|
||||
return None
|
||||
|
||||
normalized = _QWEN_MODEL_ALIASES.get(raw_value.lower(), raw_value)
|
||||
return normalized
|
||||
|
||||
|
||||
def detect_qwen_model_by_vram(all_model_ids: Optional[list[str]] = None) -> Optional[str]:
|
||||
"""Pick the active Qwen model for the current machine."""
|
||||
from app.core.accelerator import get_accelerator_info
|
||||
from app.core.device import detect_device, get_vram_gb
|
||||
from app.services.asr.qwenasr_rust import is_qwenasr_rust_available
|
||||
|
||||
model_ids = all_model_ids or load_supported_model_ids()
|
||||
override_model = get_qwen_model_override()
|
||||
if override_model:
|
||||
return override_model if override_model in model_ids else None
|
||||
|
||||
resolved_device = detect_device(settings.DEVICE)
|
||||
accelerator = get_accelerator_info()
|
||||
|
||||
# macOS defaults to the lighter Rust CPU path unless QWEN3_ASR_MODEL is set.
|
||||
if platform.system() == "Darwin":
|
||||
return "qwen3-asr-0.6b" if is_qwenasr_rust_available() and "qwen3-asr-0.6b" in model_ids else None
|
||||
|
||||
if resolved_device == "cpu" or not accelerator.is_gpu:
|
||||
return "qwen3-asr-0.6b" if is_qwenasr_rust_available() and "qwen3-asr-0.6b" in model_ids else None
|
||||
|
||||
vram = get_vram_gb()
|
||||
preferred = "qwen3-asr-1.7b" if vram >= 32 else "qwen3-asr-0.6b"
|
||||
if preferred in model_ids:
|
||||
return preferred
|
||||
|
||||
fallback = "qwen3-asr-0.6b" if preferred == "qwen3-asr-1.7b" else "qwen3-asr-1.7b"
|
||||
return fallback if fallback in model_ids else None
|
||||
|
||||
|
||||
def get_active_qwen_model(all_model_ids: Optional[list[str]] = None) -> str:
|
||||
"""Return the required Qwen model for the current machine."""
|
||||
model_ids = all_model_ids or load_supported_model_ids()
|
||||
qwen_model = detect_qwen_model_by_vram(model_ids)
|
||||
if not qwen_model:
|
||||
override_model = get_qwen_model_override()
|
||||
if override_model:
|
||||
available_qwen_models = ", ".join(
|
||||
model_id for model_id in model_ids if model_id.startswith("qwen")
|
||||
)
|
||||
raise RuntimeError(
|
||||
f"{QWEN_MODEL_OVERRIDE_ENV}={override_model} 不在可用 Qwen3-ASR 模型中: "
|
||||
f"{available_qwen_models}"
|
||||
)
|
||||
raise RuntimeError("当前环境未找到可运行的 Qwen3-ASR 模型")
|
||||
return qwen_model
|
||||
|
||||
|
||||
def get_runtime_model_ids(all_model_ids: Optional[list[str]] = None) -> list[str]:
|
||||
"""Return the runtime model/capability plan for the current machine."""
|
||||
model_ids = all_model_ids or load_supported_model_ids()
|
||||
return [get_active_qwen_model(model_ids)]
|
||||
|
||||
|
||||
def get_default_model_id(all_model_ids: Optional[list[str]] = None) -> str:
|
||||
"""Return the single default offline model for API/UI selection."""
|
||||
return get_active_qwen_model(all_model_ids)
|
||||
|
|
@ -0,0 +1,93 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Offline/realtime model selection helpers."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import List, Optional
|
||||
|
||||
from ...core.exceptions import InvalidParameterException
|
||||
from .manager import get_model_manager
|
||||
from .model_plan import (
|
||||
get_active_qwen_model,
|
||||
get_default_model_id,
|
||||
get_runtime_model_ids,
|
||||
)
|
||||
|
||||
|
||||
def get_active_qwen_model_id() -> str:
|
||||
"""Return the currently active Qwen model id."""
|
||||
active_qwen_model = get_active_qwen_model()
|
||||
return active_qwen_model or "qwen3-asr-0.6b"
|
||||
|
||||
|
||||
def get_offline_model_ids() -> List[str]:
|
||||
"""Return enabled offline-capable models for docs and APIs."""
|
||||
manager = get_model_manager()
|
||||
runtime_models = get_runtime_model_ids()
|
||||
|
||||
def sort_key(model_id: str) -> tuple[int, str]:
|
||||
if model_id.startswith("qwen"):
|
||||
return (0, model_id)
|
||||
return (1, model_id)
|
||||
|
||||
offline_models = [
|
||||
model_id
|
||||
for model_id in runtime_models
|
||||
if manager.get_declared_entry_config(model_id).has_offline_model
|
||||
]
|
||||
return sorted(offline_models, key=sort_key)
|
||||
|
||||
|
||||
def get_default_offline_model_id() -> str:
|
||||
"""Return the default offline-capable model."""
|
||||
default_model = get_default_model_id()
|
||||
if default_model:
|
||||
try:
|
||||
if get_model_manager().get_declared_entry_config(default_model).has_offline_model:
|
||||
return default_model
|
||||
except InvalidParameterException:
|
||||
pass
|
||||
return get_active_qwen_model_id()
|
||||
|
||||
|
||||
def validate_offline_model_id(model_id: Optional[str]) -> str:
|
||||
"""Validate offline-capable model ids for REST transcription requests."""
|
||||
available_models = get_offline_model_ids()
|
||||
|
||||
if not model_id or not model_id.strip():
|
||||
return get_default_offline_model_id()
|
||||
|
||||
requested_model = model_id.strip()
|
||||
if requested_model.lower() == "qwen3-asr":
|
||||
active_qwen_model = get_active_qwen_model_id()
|
||||
if active_qwen_model.startswith("qwen") and active_qwen_model in available_models:
|
||||
return active_qwen_model
|
||||
raise InvalidParameterException("当前环境未启用 Qwen3-ASR 模型")
|
||||
|
||||
if requested_model not in available_models:
|
||||
raise InvalidParameterException(
|
||||
f"不支持的离线模型ID: {requested_model}。可用模型: {', '.join(available_models)}"
|
||||
)
|
||||
|
||||
return requested_model
|
||||
|
||||
|
||||
def validate_realtime_model_id(model_id: Optional[str]) -> str:
|
||||
"""Validate realtime-capable model ids for websocket protocols."""
|
||||
available_models = get_offline_model_ids()
|
||||
|
||||
if not model_id:
|
||||
return get_default_offline_model_id()
|
||||
|
||||
if model_id.lower() == "qwen3-asr":
|
||||
active_qwen_model = get_active_qwen_model_id()
|
||||
if active_qwen_model.startswith("qwen") and active_qwen_model in available_models:
|
||||
return active_qwen_model
|
||||
raise InvalidParameterException("当前环境未启用 Qwen3-ASR 模型")
|
||||
|
||||
if model_id not in available_models:
|
||||
raise InvalidParameterException(
|
||||
f"不支持的模型ID: {model_id}。可用模型: {', '.join(available_models)}"
|
||||
)
|
||||
|
||||
return model_id
|
||||
|
|
@ -0,0 +1,70 @@
|
|||
{
|
||||
"models": {
|
||||
"qwen3-asr-1.7b": {
|
||||
"name": "Qwen3-ASR-1.7B",
|
||||
"kind": "model",
|
||||
"engine": "qwen3",
|
||||
"description": "Qwen3-ASR 1.7B,支持52种语言和方言;CUDA 使用 vLLM,CPU/macOS 使用 QwenASR Rust backend",
|
||||
"languages": [
|
||||
"zh",
|
||||
"en",
|
||||
"yue",
|
||||
"ja",
|
||||
"ko",
|
||||
"ar",
|
||||
"de",
|
||||
"es",
|
||||
"fr",
|
||||
"pt",
|
||||
"id",
|
||||
"it",
|
||||
"ru",
|
||||
"th",
|
||||
"vi"
|
||||
],
|
||||
"default": true,
|
||||
"supports_realtime": true,
|
||||
"models": {
|
||||
"offline": "Qwen/Qwen3-ASR-1.7B"
|
||||
},
|
||||
"extra_kwargs": {
|
||||
"max_model_len": 16384,
|
||||
"forced_aligner_path": "Qwen/Qwen3-ForcedAligner-0.6B",
|
||||
"max_inference_batch_size": 16
|
||||
}
|
||||
},
|
||||
"qwen3-asr-0.6b": {
|
||||
"name": "Qwen3-ASR-0.6B",
|
||||
"kind": "model",
|
||||
"engine": "qwen3",
|
||||
"description": "Qwen3-ASR 0.6B,轻量版支持52种语言和方言;CUDA 使用 vLLM,CPU/macOS 使用 QwenASR Rust backend",
|
||||
"languages": [
|
||||
"zh",
|
||||
"en",
|
||||
"yue",
|
||||
"ja",
|
||||
"ko",
|
||||
"ar",
|
||||
"de",
|
||||
"es",
|
||||
"fr",
|
||||
"pt",
|
||||
"id",
|
||||
"it",
|
||||
"ru",
|
||||
"th",
|
||||
"vi"
|
||||
],
|
||||
"default": false,
|
||||
"supports_realtime": true,
|
||||
"models": {
|
||||
"offline": "Qwen/Qwen3-ASR-0.6B"
|
||||
},
|
||||
"extra_kwargs": {
|
||||
"max_model_len": 16384,
|
||||
"forced_aligner_path": "Qwen/Qwen3-ForcedAligner-0.6B",
|
||||
"max_inference_batch_size": 16
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
|
@ -0,0 +1,137 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Shared offline transcription workflow."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
import logging
|
||||
from typing import Any, Callable, Optional
|
||||
|
||||
from fastapi import Request
|
||||
|
||||
from app.models.common import SampleRate
|
||||
from app.services.asr.engines import ASRFullResult
|
||||
from app.services.asr.model_selection import validate_offline_model_id
|
||||
from app.services.asr.runtime import OfflineASRRequest, get_runtime_router
|
||||
from app.services.audio import get_audio_service
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class PreparedAudio:
|
||||
normalized_path: str
|
||||
duration: float
|
||||
original_path: str
|
||||
timestamp_scale: float = 1.0
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class OfflineTranscriptionOptions:
|
||||
model_id: Optional[str] = None
|
||||
sample_rate: int = 16000
|
||||
hotwords: str = ""
|
||||
enable_speaker_diarization: bool = True
|
||||
enable_speaker_identification: bool = True
|
||||
enable_text_cleanup: bool = True
|
||||
word_timestamps: bool = False
|
||||
task_id: Optional[str] = None
|
||||
progress_callback: Optional[
|
||||
Callable[[str, str, int, Optional[dict[str, Any]]], None]
|
||||
] = None
|
||||
|
||||
|
||||
class OfflineTranscriptionService:
|
||||
"""Prepare audio and run the active offline ASR model."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._audio_service = get_audio_service()
|
||||
|
||||
async def prepare_from_request(
|
||||
self,
|
||||
*,
|
||||
request: Request,
|
||||
audio_address: Optional[str],
|
||||
task_id: str,
|
||||
sample_rate: int,
|
||||
) -> PreparedAudio:
|
||||
audio = await self._audio_service.process_from_request(
|
||||
request=request,
|
||||
audio_address=audio_address,
|
||||
task_id=task_id,
|
||||
sample_rate=sample_rate,
|
||||
)
|
||||
return PreparedAudio(
|
||||
normalized_path=audio.normalized_path,
|
||||
duration=audio.duration,
|
||||
original_path=audio.original_path,
|
||||
timestamp_scale=audio.timestamp_scale,
|
||||
)
|
||||
|
||||
async def prepare_upload(
|
||||
self,
|
||||
*,
|
||||
audio_data: bytes,
|
||||
filename: Optional[str],
|
||||
task_id: str,
|
||||
sample_rate: int,
|
||||
) -> PreparedAudio:
|
||||
audio = await self._audio_service.process_upload_file(
|
||||
audio_data=audio_data,
|
||||
filename=filename,
|
||||
task_id=task_id,
|
||||
sample_rate=sample_rate,
|
||||
)
|
||||
return PreparedAudio(
|
||||
normalized_path=audio.normalized_path,
|
||||
duration=audio.duration,
|
||||
original_path=audio.original_path,
|
||||
timestamp_scale=audio.timestamp_scale,
|
||||
)
|
||||
|
||||
async def transcribe(
|
||||
self,
|
||||
prepared_audio: PreparedAudio,
|
||||
options: OfflineTranscriptionOptions,
|
||||
) -> ASRFullResult:
|
||||
model_id = validate_offline_model_id(options.model_id)
|
||||
logger.info(
|
||||
"ASR model resolved: requested=%s, resolved=%s",
|
||||
options.model_id,
|
||||
model_id,
|
||||
)
|
||||
return await get_runtime_router().run_offline(
|
||||
OfflineASRRequest(
|
||||
model_id=model_id,
|
||||
audio_path=prepared_audio.normalized_path,
|
||||
hotwords=options.hotwords,
|
||||
enable_punctuation=True,
|
||||
enable_itn=True,
|
||||
sample_rate=options.sample_rate or int(SampleRate.RATE_16000),
|
||||
enable_speaker_diarization=options.enable_speaker_diarization,
|
||||
enable_speaker_identification=options.enable_speaker_identification,
|
||||
enable_text_cleanup=options.enable_text_cleanup,
|
||||
word_timestamps=options.word_timestamps,
|
||||
timestamp_scale=prepared_audio.timestamp_scale,
|
||||
task_id=options.task_id,
|
||||
progress_callback=options.progress_callback,
|
||||
)
|
||||
)
|
||||
|
||||
def cleanup(self, prepared_audio: Optional[PreparedAudio]) -> None:
|
||||
if prepared_audio is None:
|
||||
return
|
||||
self._audio_service.cleanup(
|
||||
prepared_audio.original_path,
|
||||
prepared_audio.normalized_path,
|
||||
)
|
||||
|
||||
|
||||
_offline_transcription_service: Optional[OfflineTranscriptionService] = None
|
||||
|
||||
|
||||
def get_offline_transcription_service() -> OfflineTranscriptionService:
|
||||
global _offline_transcription_service
|
||||
if _offline_transcription_service is None:
|
||||
_offline_transcription_service = OfflineTranscriptionService()
|
||||
return _offline_transcription_service
|
||||
|
|
@ -0,0 +1,693 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Qwen3-ASR engine with official vLLM and vendored Rust backends."""
|
||||
|
||||
import logging
|
||||
import os
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from typing import Optional, List, Any
|
||||
from dataclasses import dataclass
|
||||
|
||||
import torch
|
||||
import numpy as np
|
||||
|
||||
from app.core.accelerator import get_accelerator_info
|
||||
from app.core.device import get_vram_gb
|
||||
from app.core.hotword_resolver import format_hotword_prompt_context
|
||||
from .engines import BaseASREngine, ASRRawResult, ASRSegmentResult, WordToken
|
||||
from .qwenasr_rust import (
|
||||
QwenASRRustRuntime,
|
||||
is_qwenasr_rust_available,
|
||||
resolve_qwenasr_model_path,
|
||||
)
|
||||
from .qwen3_vllm import Qwen3VLLMBackend, is_vllm_available
|
||||
from ...core.exceptions import DefaultServerErrorException
|
||||
from ...core.config import settings
|
||||
from ...utils.text_processing import normalize_asr_text
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def _resolve_tensor_parallel_size() -> int:
|
||||
topology = (os.getenv("ASR_ACTIVE_TOPOLOGY") or os.getenv("ASR_DEPLOY_TOPOLOGY") or "isolated").strip().lower()
|
||||
if topology != "sharded":
|
||||
return 1
|
||||
|
||||
visible = (
|
||||
os.getenv("ASR_VISIBLE_DEVICES")
|
||||
or os.getenv("CUDA_VISIBLE_DEVICES")
|
||||
or os.getenv("METAX_VISIBLE_DEVICES")
|
||||
or os.getenv("MACA_VISIBLE_DEVICES")
|
||||
or os.getenv("MX_VISIBLE_DEVICES")
|
||||
or os.getenv("ILUVATAR_VISIBLE_DEVICES")
|
||||
or os.getenv("IX_VISIBLE_DEVICES")
|
||||
or os.getenv("MTHREADS_VISIBLE_DEVICES")
|
||||
or os.getenv("MUSA_VISIBLE_DEVICES")
|
||||
or ""
|
||||
).strip()
|
||||
if not visible or visible.lower() in {"all", "none", "void"}:
|
||||
return 1
|
||||
|
||||
count = len([part for part in visible.split(",") if part.strip()])
|
||||
return count if count > 1 else 1
|
||||
|
||||
|
||||
def calculate_gpu_memory_utilization(model_path: str) -> float:
|
||||
"""Calculate vLLM GPU memory utilization for the active model.
|
||||
|
||||
vLLM uses this ratio as an allocation budget, not just model weights.
|
||||
Keep the observed requirement slightly above the bare minimum so KV cache
|
||||
and profiling have enough room.
|
||||
"""
|
||||
# Check environment variable override first
|
||||
env_override = os.getenv("QWEN_GPU_MEMORY_UTILIZATION")
|
||||
if env_override:
|
||||
try:
|
||||
value = float(env_override)
|
||||
if 0.0 < value <= 1.0:
|
||||
logger.info(f"Using environment override: gpu_memory_utilization={value}")
|
||||
return value
|
||||
else:
|
||||
logger.warning(f"Invalid QWEN_GPU_MEMORY_UTILIZATION={env_override}, must be 0.0-1.0")
|
||||
except ValueError:
|
||||
logger.warning(f"Invalid QWEN_GPU_MEMORY_UTILIZATION={env_override}, not a float")
|
||||
|
||||
model_memory_profiles = {
|
||||
"0.6B": 8,
|
||||
"1.7B": 12.0,
|
||||
}
|
||||
|
||||
if "0.6B" in model_path:
|
||||
model_size = "0.6B"
|
||||
else:
|
||||
model_size = "1.7B"
|
||||
required_memory_gb = model_memory_profiles[model_size]
|
||||
|
||||
try:
|
||||
accelerator = get_accelerator_info()
|
||||
total_vram_gb = get_vram_gb()
|
||||
if not accelerator.is_gpu or total_vram_gb <= 0:
|
||||
logger.warning("Accelerator memory unavailable, using fallback gpu_memory_utilization=0.5")
|
||||
return 0.5
|
||||
|
||||
utilization = max(required_memory_gb / total_vram_gb, 0.25)
|
||||
utilization = min(utilization, 0.95)
|
||||
|
||||
logger.info(
|
||||
"GPU memory calculation: vendor=%s, model=%s, requires=%.1fGB, total_vram=%.1fGB, utilization=%.2f",
|
||||
accelerator.vendor,
|
||||
model_size,
|
||||
required_memory_gb,
|
||||
total_vram_gb,
|
||||
utilization,
|
||||
)
|
||||
|
||||
if utilization >= 0.90:
|
||||
logger.warning(
|
||||
"VRAM may be insufficient: %.1fGB available, %.1fGB required. Consider using smaller model.",
|
||||
total_vram_gb,
|
||||
required_memory_gb,
|
||||
)
|
||||
|
||||
return round(utilization, 2)
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"Failed to detect VRAM: {e}, using fallback gpu_memory_utilization=0.5")
|
||||
return 0.5
|
||||
|
||||
|
||||
def _handle_asr_error(operation: str):
|
||||
"""统一错误处理装饰器"""
|
||||
def decorator(func):
|
||||
def wrapper(*args, **kwargs):
|
||||
try:
|
||||
return func(*args, **kwargs)
|
||||
except Exception as e:
|
||||
logger.error(f"{operation} 失败: {e}")
|
||||
raise DefaultServerErrorException(f"{operation} 失败: {e}")
|
||||
return wrapper
|
||||
return decorator
|
||||
|
||||
|
||||
@dataclass
|
||||
class Qwen3StreamingState:
|
||||
internal_state: Any
|
||||
chunk_size_sec: float = 1.2
|
||||
unfixed_chunk_num: int = 2
|
||||
unfixed_token_num: int = 5
|
||||
max_new_tokens: int = 32
|
||||
language: Optional[str] = None
|
||||
chunk_count: int = 0
|
||||
last_text: str = ""
|
||||
last_language: str = ""
|
||||
|
||||
|
||||
class Qwen3ASREngine(BaseASREngine):
|
||||
model: Any
|
||||
|
||||
@property
|
||||
def supports_realtime(self) -> bool:
|
||||
return self._backend in {"vllm", "rust"}
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
model_path: str = "Qwen/Qwen3-ASR-1.7B",
|
||||
device: str = "auto",
|
||||
forced_aligner_path: Optional[str] = None,
|
||||
max_inference_batch_size: int = 32,
|
||||
max_new_tokens: int = 1024,
|
||||
max_model_len: Optional[int] = None,
|
||||
**_kwargs,
|
||||
):
|
||||
"""Initialize Qwen3-ASR engine
|
||||
|
||||
CUDA -> official vLLM backend
|
||||
CPU/macOS -> QwenASR Rust backend
|
||||
"""
|
||||
from app.core.device import detect_device
|
||||
|
||||
model_id = _kwargs.pop("model_id", None)
|
||||
if model_id:
|
||||
model_path = model_id
|
||||
|
||||
self._device = detect_device(device)
|
||||
self._accelerator = get_accelerator_info()
|
||||
self.model_id = model_path
|
||||
self.model_path = model_path
|
||||
self._backend = self._select_backend()
|
||||
self._forced_aligner_path = forced_aligner_path
|
||||
self._rust_num_threads = 0
|
||||
self._rust_verbosity = 0
|
||||
self._rust_batch_runtimes: list[QwenASRRustRuntime] = []
|
||||
|
||||
try:
|
||||
if self._backend == "vllm":
|
||||
self.model = self._load_vllm(
|
||||
model_path, forced_aligner_path,
|
||||
max_inference_batch_size, max_new_tokens, max_model_len,
|
||||
)
|
||||
elif self._backend == "rust":
|
||||
self.model = self._load_rust_backend(model_path, forced_aligner_path)
|
||||
self._warmup_forced_aligner()
|
||||
logger.info("Qwen3-ASR model loaded successfully with backend=%s", self._backend)
|
||||
except Exception as e:
|
||||
logger.error(f"Failed to load Qwen3-ASR model: {e}")
|
||||
raise DefaultServerErrorException(f"Failed to load Qwen3-ASR model: {e}")
|
||||
|
||||
def _select_backend(self) -> str:
|
||||
if self._accelerator.is_gpu and self._device.startswith("cuda"):
|
||||
if not is_vllm_available():
|
||||
raise DefaultServerErrorException(
|
||||
"Current Python environment is missing vLLM with Qwen3 forced aligner support. "
|
||||
f"accelerator={self._accelerator.vendor}. "
|
||||
"For NVIDIA run ./scripts/sync_gpu_env.sh; for MetaX run ./scripts/sync_metax_env.sh; "
|
||||
"for Iluvatar or Moore Threads prefer the official vendor vLLM Docker image fused with this project."
|
||||
)
|
||||
return "vllm"
|
||||
if self._device == "cpu" and is_qwenasr_rust_available():
|
||||
return "rust"
|
||||
raise DefaultServerErrorException(
|
||||
f"Qwen3-ASR is not available on accelerator '{self._accelerator.vendor}' "
|
||||
f"device '{self._device}'. Supported backends are vendor-compatible vLLM "
|
||||
"GPU runtimes and CPU QwenASR Rust."
|
||||
)
|
||||
|
||||
def _load_rust_backend(
|
||||
self,
|
||||
model_path: str,
|
||||
forced_aligner_path: Optional[str],
|
||||
) -> QwenASRRustRuntime:
|
||||
logger.info("Loading Qwen3-ASR (QwenASR Rust): %s, device=%s", model_path, self._device)
|
||||
|
||||
num_threads = 0 if settings.QWEN_RUST_CPU_WORKERS <= 1 else 1
|
||||
if settings.QWEN_RUST_CPU_WORKERS > 1:
|
||||
logger.info(
|
||||
"Using fixed QwenASR CPU thread count for multi-runtime mode: num_threads=%s workers=%s",
|
||||
num_threads,
|
||||
settings.QWEN_RUST_CPU_WORKERS,
|
||||
)
|
||||
self._rust_num_threads = num_threads
|
||||
self._rust_verbosity = 0
|
||||
return QwenASRRustRuntime(
|
||||
model_path=model_path,
|
||||
forced_aligner_path=forced_aligner_path,
|
||||
num_threads=num_threads,
|
||||
verbosity=0,
|
||||
)
|
||||
|
||||
def _get_rust_batch_runtimes(self, worker_count: int) -> list[QwenASRRustRuntime]:
|
||||
if worker_count <= 1:
|
||||
return [self.model]
|
||||
|
||||
if not self._rust_batch_runtimes:
|
||||
self._rust_batch_runtimes = [self.model]
|
||||
|
||||
while len(self._rust_batch_runtimes) < worker_count:
|
||||
self._rust_batch_runtimes.append(
|
||||
QwenASRRustRuntime(
|
||||
model_path=self.model_path,
|
||||
forced_aligner_path=self._forced_aligner_path,
|
||||
num_threads=self._rust_num_threads,
|
||||
verbosity=self._rust_verbosity,
|
||||
)
|
||||
)
|
||||
|
||||
return self._rust_batch_runtimes[:worker_count]
|
||||
|
||||
def _get_rust_stage_concurrency(self, configured: int, segment_count: int) -> int:
|
||||
target = configured if configured > 0 else settings.QWEN_RUST_CPU_WORKERS
|
||||
return max(1, min(target, segment_count))
|
||||
|
||||
def _get_rust_asr_concurrency(self, segment_count: int) -> int:
|
||||
return self._get_rust_stage_concurrency(
|
||||
settings.QWEN_RUST_ASR_CONCURRENCY,
|
||||
segment_count,
|
||||
)
|
||||
|
||||
def _get_rust_align_concurrency(self, segment_count: int) -> int:
|
||||
return self._get_rust_stage_concurrency(
|
||||
settings.QWEN_RUST_ALIGN_CONCURRENCY,
|
||||
segment_count,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _build_hotword_prompt_context(hotwords: str) -> str:
|
||||
return format_hotword_prompt_context(hotwords)
|
||||
|
||||
def _rust_transcribe_text_segment(
|
||||
self,
|
||||
runtime: QwenASRRustRuntime,
|
||||
seg: Any,
|
||||
hotwords: str,
|
||||
enable_punctuation: bool,
|
||||
enable_itn: bool,
|
||||
sample_rate: int,
|
||||
) -> str:
|
||||
_ = (hotwords, enable_punctuation, sample_rate)
|
||||
text = runtime.transcribe_file(seg.temp_file) or ""
|
||||
return normalize_asr_text(text, enable_itn=enable_itn)
|
||||
|
||||
def _rust_align_word_tokens(
|
||||
self,
|
||||
runtime: QwenASRRustRuntime,
|
||||
seg: Any,
|
||||
text: str,
|
||||
language: Optional[str] = None,
|
||||
) -> list[WordToken]:
|
||||
return [
|
||||
WordToken(
|
||||
text=str(item["text"]),
|
||||
start_time=round(float(item["start_ms"]) / 1000.0, 3),
|
||||
end_time=round(float(item["end_ms"]) / 1000.0, 3),
|
||||
)
|
||||
for item in runtime.align_transcript(
|
||||
audio_path=seg.temp_file,
|
||||
text=text,
|
||||
language=language,
|
||||
)
|
||||
]
|
||||
|
||||
def _run_rust_asr_stage(
|
||||
self,
|
||||
valid_segments: List[tuple[int, Any]],
|
||||
hotwords: str,
|
||||
enable_punctuation: bool,
|
||||
enable_itn: bool,
|
||||
sample_rate: int,
|
||||
) -> dict[int, str]:
|
||||
if not valid_segments:
|
||||
return {}
|
||||
|
||||
worker_count = self._get_rust_asr_concurrency(len(valid_segments))
|
||||
runtimes = self._get_rust_batch_runtimes(worker_count)
|
||||
output: dict[int, str] = {}
|
||||
for batch_start in range(0, len(valid_segments), worker_count):
|
||||
chunk = valid_segments[batch_start:batch_start + worker_count]
|
||||
chunk_runtimes = runtimes[:len(chunk)]
|
||||
with ThreadPoolExecutor(max_workers=len(chunk)) as executor:
|
||||
futures = [
|
||||
executor.submit(
|
||||
self._rust_transcribe_text_segment,
|
||||
runtime,
|
||||
seg,
|
||||
hotwords,
|
||||
enable_punctuation,
|
||||
enable_itn,
|
||||
sample_rate,
|
||||
)
|
||||
for runtime, (_idx, seg) in zip(chunk_runtimes, chunk)
|
||||
]
|
||||
for (idx, _seg), future in zip(chunk, futures):
|
||||
output[idx] = future.result()
|
||||
|
||||
return output
|
||||
|
||||
def _run_rust_align_stage(
|
||||
self,
|
||||
valid_segments: List[tuple[int, Any]],
|
||||
texts: dict[int, str],
|
||||
language: Optional[str] = None,
|
||||
) -> dict[int, list[WordToken]]:
|
||||
if not valid_segments:
|
||||
return {}
|
||||
|
||||
align_inputs = [(idx, seg, texts.get(idx, "")) for idx, seg in valid_segments if texts.get(idx, "").strip()]
|
||||
worker_count = self._get_rust_align_concurrency(len(valid_segments))
|
||||
runtimes = self._get_rust_batch_runtimes(worker_count)
|
||||
output: dict[int, list[WordToken]] = {}
|
||||
|
||||
if not align_inputs:
|
||||
return output
|
||||
|
||||
for batch_start in range(0, len(align_inputs), worker_count):
|
||||
chunk = align_inputs[batch_start:batch_start + worker_count]
|
||||
chunk_runtimes = runtimes[:len(chunk)]
|
||||
with ThreadPoolExecutor(max_workers=len(chunk)) as executor:
|
||||
futures = [
|
||||
executor.submit(
|
||||
self._rust_align_word_tokens,
|
||||
runtime,
|
||||
seg,
|
||||
text,
|
||||
language,
|
||||
)
|
||||
for runtime, (_idx, seg, text) in zip(chunk_runtimes, chunk)
|
||||
]
|
||||
for (idx, _seg, _text), future in zip(chunk, futures):
|
||||
output[idx] = future.result()
|
||||
|
||||
return output
|
||||
|
||||
def _warmup_forced_aligner(self) -> None:
|
||||
if not self._forced_aligner_path:
|
||||
return
|
||||
if not settings.ASR_ENABLE_WORD_TIMESTAMPS:
|
||||
return
|
||||
if self._backend == "vllm":
|
||||
self.model.ensure_forced_aligner_loaded()
|
||||
|
||||
def _load_vllm(
|
||||
self, model_path: str, forced_aligner_path: Optional[str],
|
||||
max_inference_batch_size: int, max_new_tokens: int,
|
||||
max_model_len: Optional[int],
|
||||
) -> Qwen3VLLMBackend:
|
||||
"""Load model via official vLLM backend (CUDA only)."""
|
||||
resolved_model_path = str(resolve_qwenasr_model_path(model_path))
|
||||
resolved_forced_aligner_path = None
|
||||
if forced_aligner_path:
|
||||
resolved_forced_aligner_path = str(resolve_qwenasr_model_path(forced_aligner_path))
|
||||
gpu_memory_utilization = calculate_gpu_memory_utilization(model_path)
|
||||
tensor_parallel_size = _resolve_tensor_parallel_size()
|
||||
logger.info(
|
||||
f"Loading Qwen3-ASR (official vLLM): {resolved_model_path}, "
|
||||
f"device={self._device}, gpu_memory_utilization={gpu_memory_utilization}, "
|
||||
f"enforce_eager={settings.QWEN_VLLM_ENFORCE_EAGER}, "
|
||||
f"tensor_parallel_size={tensor_parallel_size}"
|
||||
)
|
||||
return Qwen3VLLMBackend(
|
||||
model_path=resolved_model_path,
|
||||
forced_aligner_path=resolved_forced_aligner_path,
|
||||
gpu_memory_utilization=gpu_memory_utilization,
|
||||
max_inference_batch_size=max_inference_batch_size,
|
||||
max_new_tokens=max_new_tokens,
|
||||
enforce_eager=settings.QWEN_VLLM_ENFORCE_EAGER,
|
||||
max_model_len=max_model_len,
|
||||
tensor_parallel_size=tensor_parallel_size,
|
||||
)
|
||||
|
||||
@_handle_asr_error("转写")
|
||||
def transcribe_file(
|
||||
self,
|
||||
audio_path: str,
|
||||
hotwords: str = "",
|
||||
enable_punctuation: bool = True,
|
||||
enable_itn: bool = True,
|
||||
enable_vad: bool = False,
|
||||
sample_rate: int = 16000,
|
||||
) -> str:
|
||||
if self._backend == "rust":
|
||||
text = self.model.transcribe_file(audio_path)
|
||||
return normalize_asr_text(text, enable_itn=enable_itn)
|
||||
if self._backend == "vllm":
|
||||
return self.model.transcribe_text(
|
||||
audio_path,
|
||||
context=self._build_hotword_prompt_context(hotwords),
|
||||
enable_itn=enable_itn,
|
||||
)
|
||||
raise DefaultServerErrorException(f"Qwen3 backend={self._backend} does not support offline transcription")
|
||||
|
||||
@_handle_asr_error("VAD 转写")
|
||||
def transcribe_file_with_vad(
|
||||
self,
|
||||
audio_path: str,
|
||||
hotwords: str = "",
|
||||
enable_punctuation: bool = True,
|
||||
enable_itn: bool = True,
|
||||
sample_rate: int = 16000,
|
||||
**kwargs,
|
||||
) -> ASRRawResult:
|
||||
if self._backend == "rust":
|
||||
text = self.transcribe_file(
|
||||
audio_path=audio_path,
|
||||
hotwords=hotwords,
|
||||
enable_punctuation=enable_punctuation,
|
||||
enable_itn=enable_itn,
|
||||
sample_rate=sample_rate,
|
||||
)
|
||||
if kwargs.get("word_timestamps", False):
|
||||
word_tokens = [
|
||||
WordToken(
|
||||
text=str(item["text"]),
|
||||
start_time=round(float(item["start_ms"]) / 1000.0, 3),
|
||||
end_time=round(float(item["end_ms"]) / 1000.0, 3),
|
||||
)
|
||||
for item in self.model.align_transcript(
|
||||
audio_path=audio_path,
|
||||
text=text,
|
||||
language=kwargs.get("language"),
|
||||
)
|
||||
]
|
||||
if word_tokens:
|
||||
return ASRRawResult(
|
||||
text=text,
|
||||
segments=[
|
||||
ASRSegmentResult(
|
||||
text=text,
|
||||
start_time=word_tokens[0].start_time,
|
||||
end_time=word_tokens[-1].end_time,
|
||||
word_tokens=word_tokens,
|
||||
)
|
||||
],
|
||||
)
|
||||
return ASRRawResult(
|
||||
text=text,
|
||||
segments=[ASRSegmentResult(text=text, start_time=0.0, end_time=0.0)] if text else [],
|
||||
)
|
||||
if self._backend == "vllm":
|
||||
return self.model.transcribe_raw(
|
||||
audio_path=audio_path,
|
||||
context=self._build_hotword_prompt_context(hotwords),
|
||||
language=kwargs.get("language"),
|
||||
word_timestamps=kwargs.get("word_timestamps", False),
|
||||
enable_itn=enable_itn,
|
||||
)
|
||||
|
||||
raise DefaultServerErrorException(
|
||||
f"Qwen3 backend={self._backend} does not support VAD transcription"
|
||||
)
|
||||
|
||||
@_handle_asr_error("批量推理")
|
||||
def _transcribe_batch(
|
||||
self,
|
||||
segments: List[Any],
|
||||
hotwords: str = "",
|
||||
enable_punctuation: bool = False,
|
||||
enable_itn: bool = False,
|
||||
sample_rate: int = 16000,
|
||||
word_timestamps: bool = False,
|
||||
) -> List[ASRSegmentResult]:
|
||||
output = [ASRSegmentResult(text="", start_time=0.0, end_time=0.0) for _ in segments]
|
||||
|
||||
valid: List[tuple[int, Any]] = []
|
||||
for idx, seg in enumerate(segments):
|
||||
temp_file = getattr(seg, "temp_file", None)
|
||||
if temp_file and os.path.exists(temp_file):
|
||||
valid.append((idx, seg))
|
||||
else:
|
||||
logger.warning(f"Qwen3 批处理片段无效或文件不存在: segment={idx + 1}, file={temp_file}")
|
||||
|
||||
if not valid:
|
||||
return output
|
||||
|
||||
if self._backend == "rust":
|
||||
texts = self._run_rust_asr_stage(
|
||||
valid_segments=valid,
|
||||
hotwords=hotwords,
|
||||
enable_punctuation=enable_punctuation,
|
||||
enable_itn=enable_itn,
|
||||
sample_rate=sample_rate,
|
||||
)
|
||||
|
||||
word_tokens_by_idx: dict[int, list[WordToken]] = {}
|
||||
if word_timestamps:
|
||||
word_tokens_by_idx = self._run_rust_align_stage(
|
||||
valid_segments=valid,
|
||||
texts=texts,
|
||||
)
|
||||
|
||||
for idx, seg in valid:
|
||||
text = texts.get(idx, "")
|
||||
output[idx] = ASRSegmentResult(
|
||||
text=text,
|
||||
start_time=seg.start_sec,
|
||||
end_time=seg.end_sec,
|
||||
speaker_id=getattr(seg, "speaker_id", None),
|
||||
word_tokens=word_tokens_by_idx.get(idx) or None,
|
||||
)
|
||||
return output
|
||||
|
||||
if self._backend == "vllm":
|
||||
vllm_results = self.model.transcribe_batch(
|
||||
[seg.temp_file for _, seg in valid],
|
||||
context=self._build_hotword_prompt_context(hotwords),
|
||||
word_timestamps=word_timestamps,
|
||||
enable_itn=enable_itn,
|
||||
)
|
||||
for (idx, seg), result in zip(valid, vllm_results):
|
||||
output[idx] = ASRSegmentResult(
|
||||
text=result.text,
|
||||
start_time=round(seg.start_sec, 2),
|
||||
end_time=round(seg.end_sec, 2),
|
||||
speaker_id=getattr(seg, "speaker_id", None),
|
||||
word_tokens=result.word_tokens if word_timestamps else None,
|
||||
)
|
||||
return output
|
||||
|
||||
raise DefaultServerErrorException(
|
||||
f"Qwen3 backend={self._backend} does not support batch transcription"
|
||||
)
|
||||
|
||||
@_handle_asr_error("初始化流式状态")
|
||||
def init_streaming_state(self, context: str = "", language: Optional[str] = None, **kwargs) -> Qwen3StreamingState:
|
||||
if self._backend not in {"vllm", "rust"}:
|
||||
raise DefaultServerErrorException(
|
||||
f"Qwen3 backend={self._backend} does not support realtime streaming"
|
||||
)
|
||||
if self._backend == "rust":
|
||||
if context:
|
||||
logger.debug("QwenASR Rust backend ignores streaming context hints")
|
||||
chunk_size_sec = float(kwargs.get("chunk_size_sec", 1.2))
|
||||
unfixed_chunk_num = int(kwargs.get("unfixed_chunk_num", 2))
|
||||
unfixed_token_num = int(kwargs.get("unfixed_token_num", 5))
|
||||
max_new_tokens = int(kwargs.get("max_new_tokens", 32))
|
||||
stream_handle = self.model.create_stream(
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
rollback_tokens=unfixed_token_num,
|
||||
max_new_tokens=max_new_tokens,
|
||||
language=language,
|
||||
)
|
||||
return Qwen3StreamingState(
|
||||
internal_state=stream_handle,
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
unfixed_token_num=unfixed_token_num,
|
||||
max_new_tokens=max_new_tokens,
|
||||
language=language,
|
||||
chunk_count=0,
|
||||
last_text="",
|
||||
last_language=language or "",
|
||||
)
|
||||
if self._backend == "vllm":
|
||||
streaming_state = self.model.init_streaming_state(context=context, language=language, **kwargs)
|
||||
return Qwen3StreamingState(
|
||||
internal_state=streaming_state,
|
||||
chunk_size_sec=float(kwargs.get("chunk_size_sec", 1.2)),
|
||||
unfixed_chunk_num=int(kwargs.get("unfixed_chunk_num", 2)),
|
||||
unfixed_token_num=int(kwargs.get("unfixed_token_num", 5)),
|
||||
max_new_tokens=int(kwargs.get("max_new_tokens", 32)),
|
||||
language=language,
|
||||
chunk_count=int(getattr(streaming_state, "chunk_id", 0)),
|
||||
last_text=str(getattr(streaming_state, "text", "") or ""),
|
||||
last_language=str(getattr(streaming_state, "language", "") or ""),
|
||||
)
|
||||
|
||||
raise DefaultServerErrorException(
|
||||
f"Qwen3 backend={self._backend} does not support realtime streaming"
|
||||
)
|
||||
|
||||
@_handle_asr_error("流式识别")
|
||||
def streaming_transcribe(self, pcm16k: np.ndarray, state: Qwen3StreamingState) -> Qwen3StreamingState:
|
||||
if self._backend not in {"vllm", "rust"}:
|
||||
raise DefaultServerErrorException(
|
||||
f"Qwen3 backend={self._backend} does not support realtime streaming"
|
||||
)
|
||||
pcm = pcm16k.astype(np.float32) / (32768.0 if pcm16k.dtype == np.int16 else 1.0)
|
||||
if self._backend == "rust":
|
||||
text = self.model.push_stream(
|
||||
stream=state.internal_state,
|
||||
samples=pcm,
|
||||
chunk_size_sec=state.chunk_size_sec,
|
||||
unfixed_chunk_num=state.unfixed_chunk_num,
|
||||
rollback_tokens=state.unfixed_token_num,
|
||||
max_new_tokens=state.max_new_tokens,
|
||||
language=state.language,
|
||||
)
|
||||
state.chunk_count += 1
|
||||
state.last_text = text
|
||||
state.last_language = state.language or ""
|
||||
return state
|
||||
|
||||
streaming_state = self.model.feed_stream(pcm, state.internal_state)
|
||||
state.internal_state = streaming_state
|
||||
state.chunk_count = int(getattr(streaming_state, "chunk_id", state.chunk_count))
|
||||
state.last_text = str(getattr(streaming_state, "text", "") or "")
|
||||
state.last_language = str(getattr(streaming_state, "language", "") or "")
|
||||
return state
|
||||
|
||||
@_handle_asr_error("结束流式识别")
|
||||
def finish_streaming_transcribe(self, state: Qwen3StreamingState) -> Qwen3StreamingState:
|
||||
if self._backend not in {"vllm", "rust"}:
|
||||
raise DefaultServerErrorException(
|
||||
f"Qwen3 backend={self._backend} does not support realtime streaming"
|
||||
)
|
||||
if self._backend == "rust":
|
||||
text = self.model.finish_stream(
|
||||
stream=state.internal_state,
|
||||
chunk_size_sec=state.chunk_size_sec,
|
||||
unfixed_chunk_num=state.unfixed_chunk_num,
|
||||
rollback_tokens=state.unfixed_token_num,
|
||||
max_new_tokens=state.max_new_tokens,
|
||||
language=state.language,
|
||||
)
|
||||
state.last_text = text
|
||||
state.last_language = state.language or ""
|
||||
return state
|
||||
|
||||
streaming_state = self.model.finish_stream(state.internal_state)
|
||||
state.internal_state = streaming_state
|
||||
state.chunk_count = int(getattr(streaming_state, "chunk_id", state.chunk_count))
|
||||
state.last_text = str(getattr(streaming_state, "text", "") or "")
|
||||
state.last_language = str(getattr(streaming_state, "language", "") or "")
|
||||
return state
|
||||
|
||||
def is_model_loaded(self) -> bool:
|
||||
return self.model is not None
|
||||
|
||||
@property
|
||||
def backend(self) -> str:
|
||||
return self._backend
|
||||
|
||||
@property
|
||||
def device(self) -> str:
|
||||
return self._device
|
||||
|
||||
|
||||
def _register_qwen3_engine(register_func, _declared_entry_cls):
|
||||
from app.core.config import settings
|
||||
|
||||
def _create(config):
|
||||
extra = {k: v for k, v in config.extra_kwargs.items() if v is not None}
|
||||
model_id = config.models.get("offline")
|
||||
return Qwen3ASREngine(model_path=model_id, device=settings.DEVICE, **extra)
|
||||
|
||||
register_func("qwen3", _create)
|
||||
|
|
@ -0,0 +1,527 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Official vLLM adapter for CUDA Qwen3-ASR."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import importlib
|
||||
import importlib.util
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
import threading
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any, Optional
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
|
||||
from app.core.hotword_resolver import strip_hotword_prompt_leakage
|
||||
from app.utils.text_processing import normalize_asr_text
|
||||
|
||||
from .engines import ASRRawResult, ASRSegmentResult, WordToken
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_DEFAULT_SAMPLE_RATE = 16000
|
||||
_LANGUAGE_ALIASES = {
|
||||
"zh": "Chinese",
|
||||
"zh-cn": "Chinese",
|
||||
"zh-hans": "Chinese",
|
||||
"zh-hant": "Chinese",
|
||||
"cn": "Chinese",
|
||||
"en": "English",
|
||||
"en-us": "English",
|
||||
"en-gb": "English",
|
||||
"ja": "Japanese",
|
||||
"jp": "Japanese",
|
||||
"ko": "Korean",
|
||||
"yue": "Cantonese",
|
||||
"fr": "French",
|
||||
"de": "German",
|
||||
"es": "Spanish",
|
||||
"ru": "Russian",
|
||||
}
|
||||
_PROMPT_LEAK_PATTERNS = (
|
||||
re.compile(r"^\s*Transcribe the speech accurately\.\s*", re.IGNORECASE),
|
||||
re.compile(r"^\s*Transcribe the speech in [A-Za-z\s-]+\.\s*", re.IGNORECASE),
|
||||
)
|
||||
|
||||
|
||||
def is_vllm_available() -> bool:
|
||||
"""Return True when the official vLLM runtime is installed."""
|
||||
return importlib.util.find_spec("vllm") is not None
|
||||
|
||||
|
||||
def _normalize_language_name(language: Optional[str]) -> Optional[str]:
|
||||
if not language:
|
||||
return None
|
||||
normalized = language.strip()
|
||||
if not normalized:
|
||||
return None
|
||||
alias = _LANGUAGE_ALIASES.get(normalized.lower())
|
||||
if alias:
|
||||
return alias
|
||||
if " " in normalized:
|
||||
return " ".join(part.capitalize() for part in normalized.split())
|
||||
return normalized.capitalize()
|
||||
|
||||
|
||||
def _load_audio(audio_path: str) -> np.ndarray:
|
||||
audio, _sample_rate = librosa.load(audio_path, sr=_DEFAULT_SAMPLE_RATE, mono=True)
|
||||
return audio.astype(np.float32)
|
||||
|
||||
|
||||
def _build_chat_prompt(context: str = "", language: Optional[str] = None) -> str:
|
||||
instructions: list[str] = []
|
||||
if language:
|
||||
instructions.append(f"Transcribe the speech in {language}.")
|
||||
else:
|
||||
instructions.append("Transcribe the speech accurately.")
|
||||
if context.strip():
|
||||
instructions.append(context.strip())
|
||||
system_text = " ".join(instructions).strip()
|
||||
return (
|
||||
f"<|im_start|>system\n{system_text}<|im_end|>\n"
|
||||
"<|im_start|>user\n<|audio_start|><|audio_pad|><|audio_end|><|im_end|>\n"
|
||||
"<|im_start|>assistant\n"
|
||||
)
|
||||
|
||||
|
||||
def _build_alignment_prompt(tokens: list[str]) -> str:
|
||||
body = "<timestamp><timestamp>".join(tokens) + "<timestamp><timestamp>"
|
||||
return f"<|audio_start|><|audio_pad|><|audio_end|>{body}"
|
||||
|
||||
|
||||
def _strip_prompt_leakage(text: str) -> str:
|
||||
cleaned = text or ""
|
||||
changed = True
|
||||
while changed and cleaned:
|
||||
changed = False
|
||||
for pattern in _PROMPT_LEAK_PATTERNS:
|
||||
updated, count = pattern.subn("", cleaned, count=1)
|
||||
if count:
|
||||
cleaned = updated
|
||||
changed = True
|
||||
return strip_hotword_prompt_leakage(cleaned)
|
||||
|
||||
|
||||
def _sanitize_detected_language(detected: str, fallback: Optional[str]) -> str:
|
||||
candidate = (detected or "").strip()
|
||||
if not candidate:
|
||||
return fallback or ""
|
||||
|
||||
candidate = re.sub(r"^[^\w]+", "", candidate)
|
||||
match = re.search(r"language\s+([A-Za-z][A-Za-z\s-]*)$", candidate, re.IGNORECASE)
|
||||
if match:
|
||||
candidate = match.group(1).strip()
|
||||
|
||||
normalized = _normalize_language_name(candidate)
|
||||
return normalized or (fallback or "")
|
||||
|
||||
|
||||
def _parse_asr_output(raw_text: str, language: Optional[str]) -> tuple[str, str]:
|
||||
text = (raw_text or "").strip()
|
||||
if "<asr_text>" in text:
|
||||
left, right = text.split("<asr_text>", 1)
|
||||
detected = _sanitize_detected_language(left.strip(), language)
|
||||
return detected, _strip_prompt_leakage(right.strip())
|
||||
return (language or ""), _strip_prompt_leakage(text)
|
||||
|
||||
|
||||
def _split_alignment_units(text: str) -> list[str]:
|
||||
if not text:
|
||||
return []
|
||||
|
||||
# Mixed Chinese/English transcripts should not fall back to whitespace-only
|
||||
# tokenization, otherwise a long CJK sentence with a single embedded English
|
||||
# word can collapse into one giant alignment unit.
|
||||
token_pattern = re.compile(
|
||||
r"[\u4e00-\u9fff]" # CJK ideographs, align per character
|
||||
r"|[A-Za-z0-9]+(?:['._+-][A-Za-z0-9]+)*" # Latin / alnum words
|
||||
r"|[^\w\s]", # punctuation and symbols
|
||||
re.UNICODE,
|
||||
)
|
||||
return token_pattern.findall(text)
|
||||
|
||||
|
||||
def _resolve_forced_aligner_gpu_memory_utilization(primary_utilization: float) -> float:
|
||||
override = (os.getenv("QWEN_FORCE_ALIGNER_GPU_MEMORY_UTILIZATION") or "").strip()
|
||||
if override:
|
||||
try:
|
||||
value = float(override)
|
||||
if 0.0 < value <= 1.0:
|
||||
return value
|
||||
except ValueError:
|
||||
logger.warning(
|
||||
"Invalid QWEN_FORCE_ALIGNER_GPU_MEMORY_UTILIZATION=%s, ignoring override",
|
||||
override,
|
||||
)
|
||||
|
||||
return primary_utilization
|
||||
|
||||
|
||||
@dataclass
|
||||
class _GeneratedTranscript:
|
||||
text: str
|
||||
language: str
|
||||
|
||||
|
||||
@dataclass
|
||||
class VLLMRealtimeState:
|
||||
prompt_raw: str
|
||||
language: str
|
||||
chunk_size_sec: float
|
||||
unfixed_chunk_num: int
|
||||
unfixed_token_num: int
|
||||
max_new_tokens: int
|
||||
chunk_id: int = 0
|
||||
text: str = ""
|
||||
raw_decoded: str = ""
|
||||
audio_buffer: np.ndarray = field(default_factory=lambda: np.array([], dtype=np.float32))
|
||||
audio_accum: np.ndarray = field(default_factory=lambda: np.array([], dtype=np.float32))
|
||||
|
||||
|
||||
class Qwen3VLLMBackend:
|
||||
"""Thin adapter over official vLLM APIs for Qwen3-ASR."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
model_path: str,
|
||||
forced_aligner_path: Optional[str],
|
||||
gpu_memory_utilization: float,
|
||||
max_inference_batch_size: int,
|
||||
max_new_tokens: int,
|
||||
enforce_eager: bool = True,
|
||||
max_model_len: Optional[int] = None,
|
||||
tensor_parallel_size: int = 1,
|
||||
) -> None:
|
||||
try:
|
||||
vllm_module = importlib.import_module("vllm")
|
||||
transformers_module = importlib.import_module("transformers")
|
||||
except ImportError as exc:
|
||||
raise RuntimeError(
|
||||
"CUDA Qwen3-ASR now requires official vLLM with Qwen3 forced aligner support. "
|
||||
"Install it with: pip install 'vllm[audio]==0.19.0'"
|
||||
) from exc
|
||||
|
||||
self._llm_cls = getattr(vllm_module, "LLM")
|
||||
self._sampling_params_cls = getattr(vllm_module, "SamplingParams")
|
||||
self._tokenizer = getattr(transformers_module, "AutoTokenizer").from_pretrained(
|
||||
model_path,
|
||||
trust_remote_code=True,
|
||||
)
|
||||
|
||||
llm_kwargs: dict[str, Any] = {
|
||||
"model": model_path,
|
||||
"gpu_memory_utilization": gpu_memory_utilization,
|
||||
"enforce_eager": enforce_eager,
|
||||
"trust_remote_code": True,
|
||||
}
|
||||
if max_model_len is not None:
|
||||
llm_kwargs["max_model_len"] = max_model_len
|
||||
if tensor_parallel_size > 1:
|
||||
llm_kwargs["tensor_parallel_size"] = tensor_parallel_size
|
||||
|
||||
self._llm = self._llm_cls(**llm_kwargs)
|
||||
self._sampling_params = self._sampling_params_cls(
|
||||
temperature=0.01,
|
||||
max_tokens=max_new_tokens,
|
||||
)
|
||||
self._max_inference_batch_size = max_inference_batch_size
|
||||
self._gpu_memory_utilization = gpu_memory_utilization
|
||||
self._enforce_eager = enforce_eager
|
||||
self._tensor_parallel_size = tensor_parallel_size
|
||||
self._forced_aligner_path = forced_aligner_path
|
||||
self._forced_aligner: Any | None = None
|
||||
self._timestamp_token_id: int | None = None
|
||||
self._timestamp_segment_time: float | None = None
|
||||
# Share one backend instance across multiple offline tasks, but serialize
|
||||
# direct vLLM engine calls to avoid cross-request state corruption/hangs.
|
||||
self._engine_lock = threading.RLock()
|
||||
|
||||
def _get_forced_aligner_gpu_memory_utilization(self) -> float:
|
||||
configured = _resolve_forced_aligner_gpu_memory_utilization(self._gpu_memory_utilization)
|
||||
logger.info(
|
||||
"Resolved forced aligner gpu_memory_utilization=%s (primary=%s)",
|
||||
configured,
|
||||
self._gpu_memory_utilization,
|
||||
)
|
||||
return configured
|
||||
|
||||
def _get_forced_aligner(self) -> Any:
|
||||
if not self._forced_aligner_path:
|
||||
raise RuntimeError("word_timestamps requires a configured forced aligner model")
|
||||
|
||||
if self._forced_aligner is None:
|
||||
forced_aligner_gpu_memory_utilization = self._get_forced_aligner_gpu_memory_utilization()
|
||||
logger.info(
|
||||
"Loading Qwen3 forced aligner via official vLLM: %s (gpu_memory_utilization=%s)",
|
||||
self._forced_aligner_path,
|
||||
forced_aligner_gpu_memory_utilization,
|
||||
)
|
||||
self._forced_aligner = self._llm_cls(
|
||||
model=self._forced_aligner_path,
|
||||
runner="pooling",
|
||||
enforce_eager=self._enforce_eager,
|
||||
gpu_memory_utilization=forced_aligner_gpu_memory_utilization,
|
||||
tensor_parallel_size=self._tensor_parallel_size,
|
||||
trust_remote_code=True,
|
||||
hf_overrides={
|
||||
"architectures": ["Qwen3ASRForcedAlignerForTokenClassification"],
|
||||
},
|
||||
)
|
||||
llm_engine = getattr(self._forced_aligner, "llm_engine", None)
|
||||
if llm_engine is None:
|
||||
raise RuntimeError("Forced aligner did not expose a vLLM engine instance")
|
||||
config = llm_engine.vllm_config.model_config.hf_config
|
||||
self._timestamp_token_id = int(config.timestamp_token_id)
|
||||
self._timestamp_segment_time = float(config.timestamp_segment_time)
|
||||
|
||||
return self._forced_aligner
|
||||
|
||||
def ensure_forced_aligner_loaded(self) -> None:
|
||||
if self._forced_aligner_path:
|
||||
self._get_forced_aligner()
|
||||
|
||||
def _run_generate(
|
||||
self,
|
||||
audio_items: list[tuple[np.ndarray, str, Optional[str]]],
|
||||
) -> list[_GeneratedTranscript]:
|
||||
prompts: list[dict[str, Any]] = []
|
||||
for audio, context, language in audio_items:
|
||||
prompts.append(
|
||||
{
|
||||
"prompt": _build_chat_prompt(context=context, language=_normalize_language_name(language)),
|
||||
"multi_modal_data": {"audio": [audio]},
|
||||
}
|
||||
)
|
||||
|
||||
with self._engine_lock:
|
||||
outputs = self._llm.generate(
|
||||
prompts,
|
||||
sampling_params=self._sampling_params,
|
||||
use_tqdm=False,
|
||||
)
|
||||
|
||||
transcripts: list[_GeneratedTranscript] = []
|
||||
for output, (_audio, _context, language) in zip(outputs, audio_items):
|
||||
raw_text = str(output.outputs[0].text if output.outputs else "")
|
||||
parsed_language, parsed_text = _parse_asr_output(raw_text, _normalize_language_name(language))
|
||||
transcripts.append(_GeneratedTranscript(text=parsed_text, language=parsed_language))
|
||||
return transcripts
|
||||
|
||||
def transcribe_text(
|
||||
self,
|
||||
audio_path: str,
|
||||
context: str = "",
|
||||
language: Optional[str] = None,
|
||||
enable_itn: bool = False,
|
||||
) -> str:
|
||||
transcript = self._run_generate([(_load_audio(audio_path), context, language)])[0]
|
||||
return normalize_asr_text(transcript.text, enable_itn=enable_itn)
|
||||
|
||||
def transcribe_raw(
|
||||
self,
|
||||
audio_path: str,
|
||||
context: str = "",
|
||||
language: Optional[str] = None,
|
||||
word_timestamps: bool = False,
|
||||
enable_itn: bool = False,
|
||||
) -> ASRRawResult:
|
||||
audio = _load_audio(audio_path)
|
||||
transcript = self._run_generate([(audio, context, language)])[0]
|
||||
text = normalize_asr_text(transcript.text, enable_itn=enable_itn)
|
||||
if not word_timestamps:
|
||||
return ASRRawResult(
|
||||
text=text,
|
||||
segments=[ASRSegmentResult(text=text, start_time=0.0, end_time=0.0)] if text else [],
|
||||
)
|
||||
|
||||
aligned = self.align_transcript(audio_path=audio_path, text=text, language=language, audio=audio)
|
||||
word_tokens = [
|
||||
WordToken(
|
||||
text=str(item["text"]),
|
||||
start_time=round(float(item["start_ms"]) / 1000.0, 3),
|
||||
end_time=round(float(item["end_ms"]) / 1000.0, 3),
|
||||
)
|
||||
for item in aligned
|
||||
]
|
||||
if not word_tokens:
|
||||
return ASRRawResult(
|
||||
text=text,
|
||||
segments=[ASRSegmentResult(text=text, start_time=0.0, end_time=0.0)] if text else [],
|
||||
)
|
||||
return ASRRawResult(
|
||||
text=text,
|
||||
segments=[
|
||||
ASRSegmentResult(
|
||||
text=text,
|
||||
start_time=word_tokens[0].start_time,
|
||||
end_time=word_tokens[-1].end_time,
|
||||
word_tokens=word_tokens,
|
||||
)
|
||||
],
|
||||
)
|
||||
|
||||
def transcribe_batch(
|
||||
self,
|
||||
audio_paths: list[str],
|
||||
context: str = "",
|
||||
language: Optional[str] = None,
|
||||
word_timestamps: bool = False,
|
||||
enable_itn: bool = False,
|
||||
) -> list[ASRSegmentResult]:
|
||||
audios = [_load_audio(path) for path in audio_paths]
|
||||
results: list[ASRSegmentResult] = []
|
||||
for start in range(0, len(audios), self._max_inference_batch_size):
|
||||
chunk = audios[start:start + self._max_inference_batch_size]
|
||||
transcripts = self._run_generate([(audio, context, language) for audio in chunk])
|
||||
for audio_path, audio, transcript in zip(audio_paths[start:start + len(chunk)], chunk, transcripts):
|
||||
text = normalize_asr_text(transcript.text, enable_itn=enable_itn)
|
||||
if not word_timestamps:
|
||||
results.append(ASRSegmentResult(text=text, start_time=0.0, end_time=0.0))
|
||||
continue
|
||||
aligned = self.align_transcript(
|
||||
audio_path=audio_path,
|
||||
text=text,
|
||||
language=language,
|
||||
audio=audio,
|
||||
)
|
||||
word_tokens = [
|
||||
WordToken(
|
||||
text=str(item["text"]),
|
||||
start_time=round(float(item["start_ms"]) / 1000.0, 3),
|
||||
end_time=round(float(item["end_ms"]) / 1000.0, 3),
|
||||
)
|
||||
for item in aligned
|
||||
]
|
||||
results.append(
|
||||
ASRSegmentResult(
|
||||
text=text,
|
||||
start_time=word_tokens[0].start_time if word_tokens else 0.0,
|
||||
end_time=word_tokens[-1].end_time if word_tokens else 0.0,
|
||||
word_tokens=word_tokens or None,
|
||||
)
|
||||
)
|
||||
return results
|
||||
|
||||
def align_transcript(
|
||||
self,
|
||||
audio_path: str,
|
||||
text: str,
|
||||
language: Optional[str] = None,
|
||||
audio: Optional[np.ndarray] = None,
|
||||
) -> list[dict[str, float | str]]:
|
||||
tokens = _split_alignment_units(text)
|
||||
if not tokens:
|
||||
return []
|
||||
|
||||
aligner = self._get_forced_aligner()
|
||||
prompt = _build_alignment_prompt(tokens)
|
||||
audio_array = audio if audio is not None else _load_audio(audio_path)
|
||||
with self._engine_lock:
|
||||
outputs = aligner.encode(
|
||||
[{"prompt": prompt, "multi_modal_data": {"audio": audio_array}}],
|
||||
pooling_task="token_classify",
|
||||
)
|
||||
output = outputs[0]
|
||||
logits = output.outputs.data
|
||||
predictions = logits.argmax(dim=-1) if hasattr(logits, "argmax") else np.argmax(logits, axis=-1)
|
||||
ts_predictions = [
|
||||
float(pred.item() if hasattr(pred, "item") else pred) * float(self._timestamp_segment_time or 0.0)
|
||||
for tid, pred in zip(output.prompt_token_ids, predictions)
|
||||
if int(tid) == int(self._timestamp_token_id or -1)
|
||||
]
|
||||
|
||||
expected_timestamps = len(tokens) * 2
|
||||
if len(ts_predictions) < expected_timestamps:
|
||||
raise RuntimeError(
|
||||
"Forced aligner returned fewer timestamp predictions than expected: "
|
||||
f"expected={expected_timestamps}, got={len(ts_predictions)}, tokens={len(tokens)}"
|
||||
)
|
||||
|
||||
aligned: list[dict[str, float | str]] = []
|
||||
for index, token in enumerate(tokens):
|
||||
start_ms = ts_predictions[index * 2]
|
||||
end_ms = ts_predictions[index * 2 + 1]
|
||||
if end_ms < start_ms:
|
||||
logger.warning(
|
||||
"Forced aligner produced reversed timestamps for token=%r: start_ms=%s end_ms=%s",
|
||||
token,
|
||||
start_ms,
|
||||
end_ms,
|
||||
)
|
||||
start_ms, end_ms = end_ms, start_ms
|
||||
aligned.append({"text": token, "start_ms": start_ms, "end_ms": end_ms})
|
||||
return aligned
|
||||
|
||||
def init_streaming_state(
|
||||
self,
|
||||
*,
|
||||
context: str = "",
|
||||
language: Optional[str] = None,
|
||||
chunk_size_sec: float = 1.2,
|
||||
unfixed_chunk_num: int = 2,
|
||||
unfixed_token_num: int = 5,
|
||||
max_new_tokens: int = 32,
|
||||
) -> VLLMRealtimeState:
|
||||
normalized_language = _normalize_language_name(language) or ""
|
||||
return VLLMRealtimeState(
|
||||
prompt_raw=_build_chat_prompt(context=context, language=normalized_language or None),
|
||||
language=normalized_language,
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
unfixed_token_num=unfixed_token_num,
|
||||
max_new_tokens=max_new_tokens,
|
||||
audio_buffer=np.array([], dtype=np.float32),
|
||||
audio_accum=np.array([], dtype=np.float32),
|
||||
)
|
||||
|
||||
def _decode_stream(self, state: VLLMRealtimeState) -> VLLMRealtimeState:
|
||||
prefix = ""
|
||||
if state.chunk_id >= state.unfixed_chunk_num and state.raw_decoded:
|
||||
token_ids = self._tokenizer.encode(state.raw_decoded, add_special_tokens=False)
|
||||
rollback = token_ids[-state.unfixed_token_num:] if state.unfixed_token_num > 0 else []
|
||||
if rollback:
|
||||
prefix = self._tokenizer.decode(rollback, skip_special_tokens=False).replace("\ufffd", "")
|
||||
|
||||
with self._engine_lock:
|
||||
output = self._llm.generate(
|
||||
[
|
||||
{
|
||||
"prompt": state.prompt_raw + prefix,
|
||||
"multi_modal_data": {"audio": [state.audio_accum]},
|
||||
}
|
||||
],
|
||||
sampling_params=self._sampling_params_cls(
|
||||
temperature=0.01,
|
||||
max_tokens=state.max_new_tokens,
|
||||
),
|
||||
use_tqdm=False,
|
||||
)[0]
|
||||
generated = str(output.outputs[0].text if output.outputs else "")
|
||||
parsed_language, parsed_text = _parse_asr_output(prefix + generated, state.language or None)
|
||||
state.raw_decoded = prefix + generated
|
||||
state.text = parsed_text
|
||||
state.language = parsed_language or state.language
|
||||
state.chunk_id += 1
|
||||
return state
|
||||
|
||||
def feed_stream(self, pcm: np.ndarray, state: VLLMRealtimeState) -> VLLMRealtimeState:
|
||||
state.audio_buffer = np.concatenate([state.audio_buffer, pcm.astype(np.float32)])
|
||||
segment_size = int(max(state.chunk_size_sec, 0.1) * _DEFAULT_SAMPLE_RATE)
|
||||
while len(state.audio_buffer) >= segment_size:
|
||||
segment = state.audio_buffer[:segment_size].copy()
|
||||
state.audio_buffer = state.audio_buffer[segment_size:]
|
||||
state.audio_accum = np.concatenate([state.audio_accum, segment])
|
||||
state = self._decode_stream(state)
|
||||
return state
|
||||
|
||||
def finish_stream(self, state: VLLMRealtimeState) -> VLLMRealtimeState:
|
||||
if len(state.audio_buffer) > 0:
|
||||
state.audio_accum = np.concatenate([state.audio_accum, state.audio_buffer])
|
||||
state.audio_buffer = np.array([], dtype=np.float32)
|
||||
state = self._decode_stream(state)
|
||||
elif state.chunk_id == 0 and len(state.audio_accum) > 0:
|
||||
state = self._decode_stream(state)
|
||||
return state
|
||||
|
|
@ -0,0 +1,564 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""QwenASR Rust FFI wrapper for CPU inference."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import ctypes
|
||||
import json
|
||||
import logging
|
||||
import os
|
||||
import platform
|
||||
import re
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
|
||||
from app.core.config import settings
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_SHARED_LIBRARY: Optional[ctypes.CDLL] = None
|
||||
|
||||
_LANGUAGE_MAP = {
|
||||
"": "",
|
||||
"auto": "",
|
||||
"zh": "Chinese",
|
||||
"zh-cn": "Chinese",
|
||||
"yue": "Chinese",
|
||||
"en": "English",
|
||||
"ja": "Japanese",
|
||||
"ko": "Korean",
|
||||
"de": "German",
|
||||
"es": "Spanish",
|
||||
"fr": "French",
|
||||
"it": "Italian",
|
||||
"pt": "Portuguese",
|
||||
"ru": "Russian",
|
||||
"ar": "Arabic",
|
||||
"th": "Thai",
|
||||
"vi": "Vietnamese",
|
||||
"id": "Indonesian",
|
||||
}
|
||||
|
||||
|
||||
def _shared_library_filename() -> str:
|
||||
if sys.platform == "darwin":
|
||||
return "libqwen_asr.dylib"
|
||||
if sys.platform == "win32":
|
||||
return "qwen_asr.dll"
|
||||
return "libqwen_asr.so"
|
||||
|
||||
|
||||
def _repo_root() -> Path:
|
||||
return Path(__file__).resolve().parents[3]
|
||||
|
||||
|
||||
def _candidate_library_paths() -> list[Path]:
|
||||
filename = _shared_library_filename()
|
||||
candidates: list[Path] = []
|
||||
|
||||
env_path = (os.getenv("QWENASR_LIBRARY_PATH") or "").strip()
|
||||
if env_path:
|
||||
candidate = Path(env_path).expanduser()
|
||||
if candidate.is_dir():
|
||||
candidates.append(candidate / filename)
|
||||
else:
|
||||
candidates.append(candidate)
|
||||
|
||||
repo_root = _repo_root()
|
||||
candidates.extend(
|
||||
[
|
||||
repo_root / "vendor" / "qwenasr" / "target" / "release" / filename,
|
||||
repo_root / "vendor" / "qwenasr" / "target" / "debug" / filename,
|
||||
Path("/opt/qwenasr/lib") / filename,
|
||||
Path("/usr/local/lib") / filename,
|
||||
]
|
||||
)
|
||||
|
||||
return candidates
|
||||
|
||||
|
||||
def resolve_qwenasr_library_path() -> Optional[Path]:
|
||||
for candidate in _candidate_library_paths():
|
||||
if candidate.exists():
|
||||
return candidate.resolve()
|
||||
return None
|
||||
|
||||
|
||||
def is_qwenasr_rust_available() -> bool:
|
||||
return resolve_qwenasr_library_path() is not None
|
||||
|
||||
|
||||
def validate_qwenasr_cpu_features() -> None:
|
||||
if platform.machine().lower() not in {"amd64", "x86_64"}:
|
||||
return
|
||||
|
||||
flags = _read_linux_cpu_flags()
|
||||
if not flags:
|
||||
return
|
||||
|
||||
missing = [flag for flag in ("avx2", "fma") if flag not in flags]
|
||||
if missing:
|
||||
raise RuntimeError(
|
||||
"QwenASR Rust backend requires x86_64 CPU features: avx2, fma. "
|
||||
f"Missing: {', '.join(missing)}. Use a newer CPU host or rebuild the "
|
||||
"Rust backend with scalar x86 kernels."
|
||||
)
|
||||
|
||||
|
||||
def pick_cpu_qwen_model(all_available_models: list[str]) -> Optional[str]:
|
||||
for model_id in ["qwen3-asr-0.6b", "qwen3-asr-1.7b"]:
|
||||
if model_id in all_available_models:
|
||||
return model_id
|
||||
return None
|
||||
|
||||
|
||||
def _read_linux_cpu_flags() -> set[str]:
|
||||
cpuinfo = Path("/proc/cpuinfo")
|
||||
if not cpuinfo.exists():
|
||||
return set()
|
||||
|
||||
flags: set[str] = set()
|
||||
for line in cpuinfo.read_text(encoding="utf-8", errors="ignore").splitlines():
|
||||
key, _, value = line.partition(":")
|
||||
if key.strip().lower() in {"flags", "features"}:
|
||||
flags.update(value.strip().lower().split())
|
||||
if flags:
|
||||
break
|
||||
return flags
|
||||
|
||||
|
||||
def _resolve_modelscope_dir(model_ref: str, cache_root: Path) -> Optional[Path]:
|
||||
if "/" not in model_ref:
|
||||
return None
|
||||
base_dir = cache_root / model_ref
|
||||
if base_dir.exists() and base_dir.is_dir():
|
||||
return base_dir.resolve()
|
||||
return None
|
||||
|
||||
|
||||
def _append_unique_path(paths: list[Path], path: Path) -> None:
|
||||
if path not in paths:
|
||||
paths.append(path)
|
||||
|
||||
|
||||
def resolve_qwenasr_model_path(model_ref_or_path: str) -> Path:
|
||||
raw_path = Path(model_ref_or_path).expanduser()
|
||||
if raw_path.exists():
|
||||
return raw_path.resolve()
|
||||
|
||||
modelscope_cache_roots: list[Path] = []
|
||||
ms_cache = (os.getenv("MODELSCOPE_CACHE") or "").strip()
|
||||
if ms_cache:
|
||||
cache_root = Path(ms_cache).expanduser()
|
||||
_append_unique_path(modelscope_cache_roots, cache_root)
|
||||
|
||||
# 兼容旧目录结构,允许外部仍传入 models/modelscope
|
||||
legacy_cache_root = cache_root / "hub" / "models"
|
||||
if legacy_cache_root.exists():
|
||||
_append_unique_path(modelscope_cache_roots, legacy_cache_root)
|
||||
|
||||
default_ms_cache_root = Path(settings.MODELSCOPE_PATH).expanduser()
|
||||
_append_unique_path(modelscope_cache_roots, default_ms_cache_root)
|
||||
|
||||
for cache_root in modelscope_cache_roots:
|
||||
ms_dir = _resolve_modelscope_dir(model_ref_or_path, cache_root)
|
||||
if ms_dir is not None:
|
||||
return ms_dir
|
||||
|
||||
raise FileNotFoundError(
|
||||
f"QwenASR model path not found for '{model_ref_or_path}'. "
|
||||
f"Checked direct path and ModelScope caches at: "
|
||||
f"{', '.join(str(path) for path in modelscope_cache_roots)}."
|
||||
)
|
||||
|
||||
|
||||
def _bind_ffi_signatures(lib: ctypes.CDLL) -> None:
|
||||
lib.qwen_asr_load_model.argtypes = [ctypes.c_char_p, ctypes.c_int, ctypes.c_int]
|
||||
lib.qwen_asr_load_model.restype = ctypes.c_void_p
|
||||
|
||||
lib.qwen_asr_transcribe_file.argtypes = [ctypes.c_void_p, ctypes.c_char_p]
|
||||
lib.qwen_asr_transcribe_file.restype = ctypes.c_void_p
|
||||
|
||||
lib.qwen_asr_force_align_file.argtypes = [
|
||||
ctypes.c_void_p,
|
||||
ctypes.c_char_p,
|
||||
ctypes.c_char_p,
|
||||
ctypes.c_char_p,
|
||||
]
|
||||
lib.qwen_asr_force_align_file.restype = ctypes.c_void_p
|
||||
|
||||
lib.qwen_asr_set_language.argtypes = [ctypes.c_void_p, ctypes.c_char_p]
|
||||
lib.qwen_asr_set_language.restype = ctypes.c_int
|
||||
|
||||
lib.qwen_asr_free_string.argtypes = [ctypes.c_void_p]
|
||||
lib.qwen_asr_free_string.restype = None
|
||||
|
||||
lib.qwen_asr_free.argtypes = [ctypes.c_void_p]
|
||||
lib.qwen_asr_free.restype = None
|
||||
|
||||
lib.qwen_asr_stream_new.argtypes = []
|
||||
lib.qwen_asr_stream_new.restype = ctypes.c_void_p
|
||||
|
||||
lib.qwen_asr_stream_free.argtypes = [ctypes.c_void_p]
|
||||
lib.qwen_asr_stream_free.restype = None
|
||||
|
||||
lib.qwen_asr_stream_push.argtypes = [
|
||||
ctypes.c_void_p,
|
||||
ctypes.c_void_p,
|
||||
ctypes.POINTER(ctypes.c_float),
|
||||
ctypes.c_int,
|
||||
ctypes.c_int,
|
||||
]
|
||||
lib.qwen_asr_stream_push.restype = ctypes.c_void_p
|
||||
|
||||
lib.qwen_asr_stream_get_result.argtypes = [ctypes.c_void_p]
|
||||
lib.qwen_asr_stream_get_result.restype = ctypes.c_void_p
|
||||
|
||||
lib.qwen_asr_stream_set_chunk_sec.argtypes = [ctypes.c_void_p, ctypes.c_float]
|
||||
lib.qwen_asr_stream_set_chunk_sec.restype = None
|
||||
|
||||
lib.qwen_asr_stream_set_rollback.argtypes = [ctypes.c_void_p, ctypes.c_int]
|
||||
lib.qwen_asr_stream_set_rollback.restype = None
|
||||
|
||||
lib.qwen_asr_stream_set_unfixed_chunks.argtypes = [ctypes.c_void_p, ctypes.c_int]
|
||||
lib.qwen_asr_stream_set_unfixed_chunks.restype = None
|
||||
|
||||
lib.qwen_asr_stream_set_max_new_tokens.argtypes = [ctypes.c_void_p, ctypes.c_int]
|
||||
lib.qwen_asr_stream_set_max_new_tokens.restype = None
|
||||
|
||||
lib.qwen_asr_stream_set_past_text.argtypes = [ctypes.c_void_p, ctypes.c_int]
|
||||
lib.qwen_asr_stream_set_past_text.restype = None
|
||||
|
||||
|
||||
def load_qwenasr_library() -> ctypes.CDLL:
|
||||
global _SHARED_LIBRARY
|
||||
|
||||
if _SHARED_LIBRARY is not None:
|
||||
return _SHARED_LIBRARY
|
||||
|
||||
library_path = resolve_qwenasr_library_path()
|
||||
if library_path is None:
|
||||
searched = ", ".join(str(path) for path in _candidate_library_paths())
|
||||
raise FileNotFoundError(
|
||||
"QwenASR shared library not found. "
|
||||
f"Checked: {searched}"
|
||||
)
|
||||
|
||||
logger.info("Loading QwenASR Rust library from %s", library_path)
|
||||
library = ctypes.CDLL(str(library_path))
|
||||
_bind_ffi_signatures(library)
|
||||
_SHARED_LIBRARY = library
|
||||
return library
|
||||
|
||||
|
||||
def normalize_qwen_language(language: Optional[str]) -> str:
|
||||
if language is None:
|
||||
return ""
|
||||
return _LANGUAGE_MAP.get(language.strip().lower(), language.strip())
|
||||
|
||||
|
||||
def guess_alignment_language(text: str, language: Optional[str] = None) -> str:
|
||||
normalized = normalize_qwen_language(language)
|
||||
if normalized:
|
||||
return normalized
|
||||
if re.search(r"[\u4e00-\u9fff]", text):
|
||||
return "Chinese"
|
||||
if re.search(r"[\u3040-\u30ff]", text):
|
||||
return "Japanese"
|
||||
if re.search(r"[\uac00-\ud7af]", text):
|
||||
return "Korean"
|
||||
return "English"
|
||||
|
||||
|
||||
def _decode_and_free_string(lib: ctypes.CDLL, raw_ptr: ctypes.c_void_p) -> Optional[str]:
|
||||
if not raw_ptr:
|
||||
return None
|
||||
|
||||
try:
|
||||
value = ctypes.cast(raw_ptr, ctypes.c_char_p).value
|
||||
if value is None:
|
||||
return None
|
||||
return value.decode("utf-8")
|
||||
finally:
|
||||
lib.qwen_asr_free_string(raw_ptr)
|
||||
|
||||
|
||||
class QwenASRRustStreamHandle:
|
||||
"""Owns a Rust streaming state pointer."""
|
||||
|
||||
def __init__(self, lib: ctypes.CDLL, handle: ctypes.c_void_p):
|
||||
self._lib = lib
|
||||
self.handle = handle
|
||||
self.accumulated_text = ""
|
||||
|
||||
def close(self) -> None:
|
||||
if self.handle:
|
||||
self._lib.qwen_asr_stream_free(self.handle)
|
||||
self.handle = ctypes.c_void_p()
|
||||
|
||||
def __del__(self) -> None:
|
||||
try:
|
||||
self.close()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
class QwenASRRustBackend:
|
||||
"""Thin Python wrapper around the QwenASR C API."""
|
||||
|
||||
def __init__(self, model_path: str, num_threads: int = 0, verbosity: int = 0):
|
||||
validate_qwenasr_cpu_features()
|
||||
self._lib = load_qwenasr_library()
|
||||
self.model_dir = resolve_qwenasr_model_path(model_path)
|
||||
self._engine = self._lib.qwen_asr_load_model(
|
||||
str(self.model_dir).encode("utf-8"),
|
||||
num_threads,
|
||||
verbosity,
|
||||
)
|
||||
if not self._engine:
|
||||
raise RuntimeError(f"Failed to load QwenASR model from '{self.model_dir}'")
|
||||
|
||||
def close(self) -> None:
|
||||
if self._engine:
|
||||
self._lib.qwen_asr_free(self._engine)
|
||||
self._engine = ctypes.c_void_p()
|
||||
|
||||
def __del__(self) -> None:
|
||||
try:
|
||||
self.close()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def _set_language(self, language: Optional[str]) -> None:
|
||||
normalized = normalize_qwen_language(language)
|
||||
status = self._lib.qwen_asr_set_language(
|
||||
self._engine,
|
||||
normalized.encode("utf-8"),
|
||||
)
|
||||
if status != 0 and normalized:
|
||||
logger.warning("QwenASR rejected language hint: %s", normalized)
|
||||
|
||||
def _configure_stream(
|
||||
self,
|
||||
*,
|
||||
chunk_size_sec: float,
|
||||
unfixed_chunk_num: int,
|
||||
rollback_tokens: int,
|
||||
max_new_tokens: int,
|
||||
past_text: bool,
|
||||
) -> None:
|
||||
self._lib.qwen_asr_stream_set_chunk_sec(self._engine, ctypes.c_float(chunk_size_sec))
|
||||
self._lib.qwen_asr_stream_set_unfixed_chunks(self._engine, int(unfixed_chunk_num))
|
||||
self._lib.qwen_asr_stream_set_rollback(self._engine, int(rollback_tokens))
|
||||
self._lib.qwen_asr_stream_set_max_new_tokens(self._engine, int(max_new_tokens))
|
||||
self._lib.qwen_asr_stream_set_past_text(self._engine, 1 if past_text else 0)
|
||||
|
||||
def transcribe_file(self, audio_path: str, language: Optional[str] = None) -> str:
|
||||
self._set_language(language)
|
||||
raw_ptr = self._lib.qwen_asr_transcribe_file(
|
||||
self._engine,
|
||||
audio_path.encode("utf-8"),
|
||||
)
|
||||
text = _decode_and_free_string(self._lib, raw_ptr)
|
||||
if text is None:
|
||||
raise RuntimeError(f"QwenASR failed to transcribe '{audio_path}'")
|
||||
return text
|
||||
|
||||
def force_align_file(
|
||||
self,
|
||||
audio_path: str,
|
||||
text: str,
|
||||
language: Optional[str] = None,
|
||||
) -> list[dict[str, float | str]]:
|
||||
normalized_language = normalize_qwen_language(language) or "English"
|
||||
raw_ptr = self._lib.qwen_asr_force_align_file(
|
||||
self._engine,
|
||||
audio_path.encode("utf-8"),
|
||||
text.encode("utf-8"),
|
||||
normalized_language.encode("utf-8"),
|
||||
)
|
||||
payload = _decode_and_free_string(self._lib, raw_ptr)
|
||||
if payload is None:
|
||||
raise RuntimeError(f"QwenASR failed to force align '{audio_path}'")
|
||||
|
||||
items = json.loads(payload)
|
||||
if not isinstance(items, list):
|
||||
raise RuntimeError("QwenASR force alignment returned invalid payload")
|
||||
return [
|
||||
{
|
||||
"text": str(item.get("text", "")),
|
||||
"start_ms": float(item.get("start_ms", 0.0)),
|
||||
"end_ms": float(item.get("end_ms", 0.0)),
|
||||
}
|
||||
for item in items
|
||||
if isinstance(item, dict) and str(item.get("text", "")).strip()
|
||||
]
|
||||
|
||||
def create_stream(
|
||||
self,
|
||||
*,
|
||||
chunk_size_sec: float = 1.2,
|
||||
unfixed_chunk_num: int = 2,
|
||||
rollback_tokens: int = 5,
|
||||
max_new_tokens: int = 32,
|
||||
language: Optional[str] = None,
|
||||
) -> QwenASRRustStreamHandle:
|
||||
handle = self._lib.qwen_asr_stream_new()
|
||||
if not handle:
|
||||
raise RuntimeError("QwenASR failed to create stream state")
|
||||
|
||||
self._configure_stream(
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
rollback_tokens=rollback_tokens,
|
||||
max_new_tokens=max_new_tokens,
|
||||
past_text=True,
|
||||
)
|
||||
self._set_language(language)
|
||||
return QwenASRRustStreamHandle(self._lib, handle)
|
||||
|
||||
def push_stream(
|
||||
self,
|
||||
stream: QwenASRRustStreamHandle,
|
||||
samples: np.ndarray,
|
||||
*,
|
||||
chunk_size_sec: float,
|
||||
unfixed_chunk_num: int,
|
||||
rollback_tokens: int,
|
||||
max_new_tokens: int,
|
||||
language: Optional[str],
|
||||
finalize: bool = False,
|
||||
) -> str:
|
||||
self._configure_stream(
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
rollback_tokens=rollback_tokens,
|
||||
max_new_tokens=max_new_tokens,
|
||||
past_text=True,
|
||||
)
|
||||
self._set_language(language)
|
||||
|
||||
pcm = np.ascontiguousarray(samples, dtype=np.float32)
|
||||
pointer = (
|
||||
pcm.ctypes.data_as(ctypes.POINTER(ctypes.c_float))
|
||||
if len(pcm) > 0
|
||||
else None
|
||||
)
|
||||
delta_ptr = self._lib.qwen_asr_stream_push(
|
||||
self._engine,
|
||||
stream.handle,
|
||||
pointer,
|
||||
len(pcm),
|
||||
1 if finalize else 0,
|
||||
)
|
||||
delta_text = _decode_and_free_string(self._lib, delta_ptr) or ""
|
||||
stream.accumulated_text += delta_text
|
||||
return stream.accumulated_text
|
||||
|
||||
|
||||
class QwenASRRustRuntime:
|
||||
"""Higher-level Rust runtime bundle for ASR + aligner + streaming."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
model_path: str,
|
||||
*,
|
||||
forced_aligner_path: Optional[str] = None,
|
||||
num_threads: int = 0,
|
||||
verbosity: int = 0,
|
||||
) -> None:
|
||||
self._asr = QwenASRRustBackend(
|
||||
model_path=model_path,
|
||||
num_threads=num_threads,
|
||||
verbosity=verbosity,
|
||||
)
|
||||
self._aligner: Optional[QwenASRRustBackend] = None
|
||||
if forced_aligner_path:
|
||||
self._aligner = QwenASRRustBackend(
|
||||
model_path=forced_aligner_path,
|
||||
num_threads=num_threads,
|
||||
verbosity=verbosity,
|
||||
)
|
||||
|
||||
def transcribe_file(self, audio_path: str, language: Optional[str] = None) -> str:
|
||||
return self._asr.transcribe_file(audio_path=audio_path, language=language)
|
||||
|
||||
def align_transcript(
|
||||
self,
|
||||
audio_path: str,
|
||||
text: str,
|
||||
language: Optional[str] = None,
|
||||
) -> list[dict[str, float | str]]:
|
||||
transcript = text.strip()
|
||||
if not transcript:
|
||||
return []
|
||||
if self._aligner is None:
|
||||
raise RuntimeError("Forced alignment requires a configured aligner model")
|
||||
return self._aligner.force_align_file(
|
||||
audio_path=audio_path,
|
||||
text=transcript,
|
||||
language=guess_alignment_language(transcript, language),
|
||||
)
|
||||
|
||||
def create_stream(
|
||||
self,
|
||||
*,
|
||||
chunk_size_sec: float = 1.2,
|
||||
unfixed_chunk_num: int = 2,
|
||||
rollback_tokens: int = 5,
|
||||
max_new_tokens: int = 32,
|
||||
language: Optional[str] = None,
|
||||
) -> QwenASRRustStreamHandle:
|
||||
return self._asr.create_stream(
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
rollback_tokens=rollback_tokens,
|
||||
max_new_tokens=max_new_tokens,
|
||||
language=language,
|
||||
)
|
||||
|
||||
def push_stream(
|
||||
self,
|
||||
stream: QwenASRRustStreamHandle,
|
||||
samples: np.ndarray,
|
||||
*,
|
||||
chunk_size_sec: float,
|
||||
unfixed_chunk_num: int,
|
||||
rollback_tokens: int,
|
||||
max_new_tokens: int,
|
||||
language: Optional[str],
|
||||
) -> str:
|
||||
return self._asr.push_stream(
|
||||
stream=stream,
|
||||
samples=samples,
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
rollback_tokens=rollback_tokens,
|
||||
max_new_tokens=max_new_tokens,
|
||||
language=language,
|
||||
finalize=False,
|
||||
)
|
||||
|
||||
def finish_stream(
|
||||
self,
|
||||
stream: QwenASRRustStreamHandle,
|
||||
*,
|
||||
chunk_size_sec: float,
|
||||
unfixed_chunk_num: int,
|
||||
rollback_tokens: int,
|
||||
max_new_tokens: int,
|
||||
language: Optional[str],
|
||||
) -> str:
|
||||
return self._asr.push_stream(
|
||||
stream=stream,
|
||||
samples=np.array([], dtype=np.float32),
|
||||
chunk_size_sec=chunk_size_sec,
|
||||
unfixed_chunk_num=unfixed_chunk_num,
|
||||
rollback_tokens=rollback_tokens,
|
||||
max_new_tokens=max_new_tokens,
|
||||
language=language,
|
||||
finalize=True,
|
||||
)
|
||||
|
|
@ -0,0 +1,16 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""ASR runtime routing and pooling layer."""
|
||||
|
||||
from .router import (
|
||||
OfflineASRRequest,
|
||||
RuntimeEngineLease,
|
||||
RuntimeRouter,
|
||||
get_runtime_router,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
"OfflineASRRequest",
|
||||
"RuntimeEngineLease",
|
||||
"RuntimeRouter",
|
||||
"get_runtime_router",
|
||||
]
|
||||
|
|
@ -0,0 +1,48 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Small async pool for per-request ASR engines."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import threading
|
||||
from dataclasses import dataclass
|
||||
from typing import Callable, Generic, Optional, TypeVar
|
||||
|
||||
T = TypeVar("T")
|
||||
|
||||
|
||||
@dataclass
|
||||
class _PoolState(Generic[T]):
|
||||
queue: asyncio.Queue[T]
|
||||
|
||||
|
||||
class LocalEnginePool(Generic[T]):
|
||||
"""Fixed-size lazy engine pool backed by ``asyncio.Queue``."""
|
||||
|
||||
def __init__(self, size: int, factory: Callable[[], T]):
|
||||
self._size = max(1, size)
|
||||
self._factory = factory
|
||||
self._state: Optional[_PoolState[T]] = None
|
||||
self._init_lock = threading.Lock()
|
||||
|
||||
def _ensure_state(self) -> _PoolState[T]:
|
||||
if self._state is not None:
|
||||
return self._state
|
||||
|
||||
with self._init_lock:
|
||||
if self._state is None:
|
||||
self._state = _PoolState(queue=asyncio.Queue(maxsize=self._size))
|
||||
for _ in range(self._size):
|
||||
self._state.queue.put_nowait(self._factory())
|
||||
return self._state
|
||||
|
||||
def warmup(self) -> None:
|
||||
self._ensure_state()
|
||||
|
||||
async def acquire(self) -> T:
|
||||
state = self._ensure_state()
|
||||
return await state.queue.get()
|
||||
|
||||
async def release(self, engine: T) -> None:
|
||||
state = self._ensure_state()
|
||||
await state.queue.put(engine)
|
||||
|
|
@ -0,0 +1,241 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Runtime router for pooled ASR execution."""
|
||||
|
||||
from __future__ import annotations
|
||||
import asyncio
|
||||
import threading
|
||||
from dataclasses import dataclass
|
||||
from enum import Enum
|
||||
from typing import Awaitable, Callable, Optional
|
||||
|
||||
import torch
|
||||
|
||||
from app.core.accelerator import get_accelerator_info
|
||||
from app.core.config import settings
|
||||
from app.core.device import detect_device
|
||||
from app.core.executor import run_sync
|
||||
from app.services.asr.engines import ASRFullResult, BaseASREngine
|
||||
from app.services.asr.manager import get_model_manager
|
||||
from app.services.asr.qwenasr_rust import is_qwenasr_rust_available
|
||||
from .local_pool import LocalEnginePool
|
||||
|
||||
|
||||
class RuntimeFamily(str, Enum):
|
||||
QWEN_VLLM = "qwen_vllm"
|
||||
QWEN_RUST_CPU = "qwen_rust_cpu"
|
||||
|
||||
|
||||
@dataclass
|
||||
class OfflineASRRequest:
|
||||
model_id: str
|
||||
audio_path: str
|
||||
hotwords: str = ""
|
||||
enable_punctuation: bool = True
|
||||
enable_itn: bool = True
|
||||
sample_rate: int = 16000
|
||||
enable_speaker_diarization: bool = True
|
||||
enable_speaker_identification: bool = True
|
||||
enable_text_cleanup: bool = True
|
||||
word_timestamps: bool = False
|
||||
timestamp_scale: float = 1.0
|
||||
task_id: Optional[str] = None
|
||||
progress_callback: Optional[Callable[[str, str, int, Optional[dict[str, object]]], None]] = None
|
||||
|
||||
|
||||
class RuntimeEngineLease:
|
||||
"""Lifecycle wrapper around a pooled engine instance."""
|
||||
|
||||
def __init__(self, engine: BaseASREngine, release_callback: Callable[[], None | Awaitable[None]]):
|
||||
self.engine = engine
|
||||
self._release_callback = release_callback
|
||||
self._closed = False
|
||||
|
||||
async def close(self) -> None:
|
||||
if self._closed:
|
||||
return
|
||||
self._closed = True
|
||||
result = self._release_callback()
|
||||
if asyncio.iscoroutine(result):
|
||||
await result
|
||||
|
||||
async def __aenter__(self) -> BaseASREngine:
|
||||
return self.engine
|
||||
|
||||
async def __aexit__(self, exc_type, exc, tb) -> None:
|
||||
await self.close()
|
||||
|
||||
|
||||
class RuntimeRouter:
|
||||
"""Central backend router for all ASR entrypoints."""
|
||||
|
||||
def __init__(self):
|
||||
self._manager = get_model_manager()
|
||||
self._pools: dict[tuple[RuntimeFamily, str], LocalEnginePool[BaseASREngine]] = {}
|
||||
self._shared_engines: dict[tuple[RuntimeFamily, str], BaseASREngine] = {}
|
||||
self._shared_limits: dict[tuple[RuntimeFamily, str], asyncio.Semaphore] = {}
|
||||
self._pool_lock = threading.Lock()
|
||||
self._loaded_model_ids: set[str] = set()
|
||||
|
||||
def resolve_model_id(self, model_id: Optional[str]) -> str:
|
||||
if model_id:
|
||||
return model_id
|
||||
config = self._manager.get_declared_entry_config()
|
||||
return config.model_id
|
||||
|
||||
def _resolve_family(self, model_id: str) -> RuntimeFamily:
|
||||
device = detect_device(settings.DEVICE)
|
||||
accelerator = get_accelerator_info()
|
||||
if model_id.startswith("qwen3-asr-"):
|
||||
if accelerator.is_gpu and device.startswith("cuda"):
|
||||
return RuntimeFamily.QWEN_VLLM
|
||||
if device == "cpu" and is_qwenasr_rust_available():
|
||||
return RuntimeFamily.QWEN_RUST_CPU
|
||||
raise RuntimeError(
|
||||
"Qwen3-ASR is not available on "
|
||||
f"accelerator='{accelerator.vendor}' device='{device}'"
|
||||
)
|
||||
raise RuntimeError(f"Unsupported runtime model: {model_id}")
|
||||
|
||||
def _pool_size_for_family(self, family: RuntimeFamily) -> int:
|
||||
if family == RuntimeFamily.QWEN_VLLM:
|
||||
return 1
|
||||
return settings.QWEN_RUST_CPU_WORKERS
|
||||
|
||||
def _create_pool(self, family: RuntimeFamily, model_id: str) -> LocalEnginePool[BaseASREngine]:
|
||||
pool_key = (family, model_id)
|
||||
existing = self._pools.get(pool_key)
|
||||
if existing is not None:
|
||||
return existing
|
||||
|
||||
with self._pool_lock:
|
||||
existing = self._pools.get(pool_key)
|
||||
if existing is not None:
|
||||
return existing
|
||||
pool = LocalEnginePool(
|
||||
size=self._pool_size_for_family(family),
|
||||
factory=lambda: self._manager.create_engine(model_id),
|
||||
)
|
||||
self._pools[pool_key] = pool
|
||||
self._loaded_model_ids.add(model_id)
|
||||
return pool
|
||||
|
||||
def _get_shared_engine(self, family: RuntimeFamily, model_id: str) -> tuple[BaseASREngine, asyncio.Semaphore]:
|
||||
runtime_key = (family, model_id)
|
||||
engine = self._shared_engines.get(runtime_key)
|
||||
semaphore = self._shared_limits.get(runtime_key)
|
||||
if engine is not None and semaphore is not None:
|
||||
return engine, semaphore
|
||||
|
||||
with self._pool_lock:
|
||||
engine = self._shared_engines.get(runtime_key)
|
||||
semaphore = self._shared_limits.get(runtime_key)
|
||||
if engine is None:
|
||||
engine = self._manager.create_engine(model_id)
|
||||
self._shared_engines[runtime_key] = engine
|
||||
self._loaded_model_ids.add(model_id)
|
||||
if semaphore is None:
|
||||
shared_concurrency = max(1, int(settings.QWEN_VLLM_SHARED_CONCURRENCY))
|
||||
semaphore = asyncio.Semaphore(shared_concurrency)
|
||||
self._shared_limits[runtime_key] = semaphore
|
||||
return engine, semaphore
|
||||
|
||||
def warmup_model(self, model_id: Optional[str] = None) -> None:
|
||||
resolved_model_id = self.resolve_model_id(model_id)
|
||||
family = self._resolve_family(resolved_model_id)
|
||||
if family == RuntimeFamily.QWEN_VLLM:
|
||||
self._get_shared_engine(family, resolved_model_id)
|
||||
return
|
||||
pool = self._create_pool(family, resolved_model_id)
|
||||
pool.warmup()
|
||||
|
||||
def get_loaded_model_ids(self) -> list[str]:
|
||||
return sorted(self._loaded_model_ids)
|
||||
|
||||
def get_memory_usage(self) -> dict[str, object]:
|
||||
memory_info: dict[str, object] = {
|
||||
"model_list": self.get_loaded_model_ids(),
|
||||
"loaded_count": len(self._loaded_model_ids),
|
||||
}
|
||||
|
||||
accelerator = get_accelerator_info()
|
||||
memory_info["accelerator"] = accelerator.as_dict()
|
||||
|
||||
if accelerator.is_gpu and torch.cuda.is_available():
|
||||
memory_info["gpu_memory"] = {
|
||||
"allocated": f"{torch.cuda.memory_allocated() / 1024**3:.2f}GB",
|
||||
"cached": f"{torch.cuda.memory_reserved() / 1024**3:.2f}GB",
|
||||
"max_allocated": f"{torch.cuda.max_memory_allocated() / 1024**3:.2f}GB",
|
||||
}
|
||||
|
||||
return memory_info
|
||||
|
||||
async def acquire_engine(self, model_id: Optional[str] = None) -> RuntimeEngineLease:
|
||||
resolved_model_id = self.resolve_model_id(model_id)
|
||||
family = self._resolve_family(resolved_model_id)
|
||||
if family == RuntimeFamily.QWEN_VLLM:
|
||||
engine, semaphore = self._get_shared_engine(family, resolved_model_id)
|
||||
await semaphore.acquire()
|
||||
return RuntimeEngineLease(
|
||||
engine=engine,
|
||||
release_callback=semaphore.release,
|
||||
)
|
||||
pool = self._create_pool(family, resolved_model_id)
|
||||
engine = await pool.acquire()
|
||||
return RuntimeEngineLease(
|
||||
engine=engine,
|
||||
release_callback=lambda: pool.release(engine),
|
||||
)
|
||||
|
||||
async def run_offline(self, request: OfflineASRRequest) -> ASRFullResult:
|
||||
async with await self.acquire_engine(request.model_id) as engine:
|
||||
result = await run_sync(
|
||||
engine.transcribe_long_audio,
|
||||
audio_path=request.audio_path,
|
||||
hotwords=request.hotwords,
|
||||
enable_punctuation=request.enable_punctuation,
|
||||
enable_itn=request.enable_itn,
|
||||
sample_rate=request.sample_rate,
|
||||
enable_speaker_diarization=request.enable_speaker_diarization,
|
||||
enable_speaker_identification=request.enable_speaker_identification,
|
||||
enable_text_cleanup=request.enable_text_cleanup,
|
||||
word_timestamps=request.word_timestamps,
|
||||
timestamp_scale=request.timestamp_scale,
|
||||
task_id=request.task_id,
|
||||
progress_callback=request.progress_callback,
|
||||
)
|
||||
if (
|
||||
request.enable_speaker_diarization
|
||||
and request.enable_speaker_identification
|
||||
and settings.SPEAKER_DB_ENABLED
|
||||
):
|
||||
try:
|
||||
from app.services.speaker_registry import get_speaker_registry_service
|
||||
|
||||
if request.progress_callback is not None:
|
||||
request.progress_callback(
|
||||
"speaker_matching",
|
||||
"正在匹配已注册声纹库。",
|
||||
94,
|
||||
None,
|
||||
)
|
||||
result = await get_speaker_registry_service().apply_registered_speakers(
|
||||
result,
|
||||
threshold=settings.SV_THRESHOLD,
|
||||
)
|
||||
except Exception:
|
||||
# 数据库/声纹匹配失败不影响原有 ASR 输出,仍保留 CAM++ 的局部说话人编号。
|
||||
pass
|
||||
return result
|
||||
|
||||
|
||||
_runtime_router: Optional[RuntimeRouter] = None
|
||||
_runtime_router_lock = threading.Lock()
|
||||
|
||||
|
||||
def get_runtime_router() -> RuntimeRouter:
|
||||
global _runtime_router
|
||||
if _runtime_router is None:
|
||||
with _runtime_router_lock:
|
||||
if _runtime_router is None:
|
||||
_runtime_router = RuntimeRouter()
|
||||
return _runtime_router
|
||||
|
|
@ -0,0 +1,10 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
音频处理服务模块
|
||||
|
||||
提供统一的音频处理服务层,封装音频下载、格式转换、归一化等功能。
|
||||
"""
|
||||
|
||||
from .audio_service import AudioProcessingService, get_audio_service
|
||||
|
||||
__all__ = ["AudioProcessingService", "get_audio_service"]
|
||||
|
|
@ -0,0 +1,234 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
音频处理服务
|
||||
|
||||
封装音频处理逻辑,提供统一的音频下载、格式转换、归一化等服务。
|
||||
API层应该通过此服务层处理音频,而不是直接调用 utils/audio.py 中的函数。
|
||||
"""
|
||||
|
||||
import logging
|
||||
import threading
|
||||
from dataclasses import dataclass
|
||||
from typing import Optional
|
||||
from fastapi import Request
|
||||
|
||||
from ...core.config import settings
|
||||
from ...core.exceptions import InvalidMessageException
|
||||
from ...utils.audio import (
|
||||
download_audio_from_url,
|
||||
save_audio_to_temp_file,
|
||||
normalize_audio_for_asr,
|
||||
get_audio_duration,
|
||||
cleanup_temp_file,
|
||||
get_audio_file_suffix,
|
||||
)
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class AudioProcessingResult:
|
||||
normalized_path: str
|
||||
duration: float
|
||||
original_path: str
|
||||
timestamp_scale: float = 1.0
|
||||
|
||||
|
||||
class AudioProcessingService:
|
||||
"""音频处理服务
|
||||
|
||||
提供统一的音频处理接口,包括:
|
||||
1. 从URL下载音频
|
||||
2. 处理上传的音频文件
|
||||
3. 音频格式转换和归一化
|
||||
4. 临时文件管理
|
||||
"""
|
||||
|
||||
async def process_from_request(
|
||||
self,
|
||||
request: Request,
|
||||
audio_address: Optional[str] = None,
|
||||
task_id: Optional[str] = None,
|
||||
sample_rate: Optional[int] = None,
|
||||
) -> AudioProcessingResult:
|
||||
"""从请求中处理音频
|
||||
|
||||
支持两种方式:
|
||||
1. 请求体上传:从请求体读取二进制音频/视频数据
|
||||
2. URL下载:通过 audio_address 参数指定音频/视频 URL
|
||||
|
||||
当请求体和 audio_address 同时存在时,优先使用请求体,
|
||||
并忽略 audio_address。
|
||||
|
||||
Args:
|
||||
request: FastAPI请求对象
|
||||
audio_address: 音频文件URL(可选)
|
||||
task_id: 任务ID,用于日志记录(可选)
|
||||
sample_rate: 目标采样率(可选,默认16000)
|
||||
|
||||
Returns:
|
||||
Processed audio path, duration, original path, and timestamp metadata.
|
||||
|
||||
Raises:
|
||||
InvalidMessageException: 音频数据为空或文件太大
|
||||
InvalidParameterException: URL无效或下载失败
|
||||
"""
|
||||
task_id = task_id or "unknown"
|
||||
target_sr = sample_rate or 16000
|
||||
|
||||
# 优先读取请求体;若请求体为空,再回退到 audio_address。
|
||||
# 注意:对于 FastAPI 已经解析过 form/multipart 的请求,
|
||||
# 再次读取 body 可能抛出 "Stream consumed"。
|
||||
try:
|
||||
uploaded_data = await request.body()
|
||||
except RuntimeError as exc:
|
||||
if "Stream consumed" in str(exc):
|
||||
logger.info(f"[{task_id}] 请求体已被上游读取,跳过 request.body() 回退逻辑")
|
||||
uploaded_data = b""
|
||||
else:
|
||||
raise
|
||||
|
||||
if uploaded_data:
|
||||
if audio_address:
|
||||
logger.info(f"[{task_id}] 检测到同时提供上传内容和 audio_address,已忽略 audio_address")
|
||||
return self._process_audio_bytes(
|
||||
audio_data=uploaded_data,
|
||||
filename=None,
|
||||
task_id=task_id,
|
||||
target_sr=target_sr,
|
||||
)
|
||||
|
||||
if audio_address:
|
||||
logger.info(f"[{task_id}] 开始从URL下载音频: {audio_address}")
|
||||
audio_data = download_audio_from_url(audio_address)
|
||||
logger.info(
|
||||
f"[{task_id}] 音频下载完成,大小: {len(audio_data) / 1024 / 1024:.2f}MB"
|
||||
)
|
||||
return self._process_audio_bytes(
|
||||
audio_data=audio_data,
|
||||
filename=audio_address,
|
||||
task_id=task_id,
|
||||
target_sr=target_sr,
|
||||
)
|
||||
|
||||
raise InvalidMessageException("音频数据为空", task_id)
|
||||
|
||||
async def process_upload_file(
|
||||
self,
|
||||
audio_data: bytes,
|
||||
filename: Optional[str] = None,
|
||||
task_id: Optional[str] = None,
|
||||
sample_rate: Optional[int] = None,
|
||||
) -> AudioProcessingResult:
|
||||
"""处理上传的音频文件
|
||||
|
||||
Args:
|
||||
audio_data: 音频二进制数据
|
||||
filename: 原始文件名(用于检测格式,可选)
|
||||
task_id: 任务ID,用于日志记录(可选)
|
||||
sample_rate: 目标采样率(可选,默认16000)
|
||||
|
||||
Returns:
|
||||
Processed audio path, duration, original path, and timestamp metadata.
|
||||
|
||||
Raises:
|
||||
InvalidMessageException: 音频数据为空或文件太大
|
||||
"""
|
||||
task_id = task_id or "unknown"
|
||||
target_sr = sample_rate or 16000
|
||||
return self._process_audio_bytes(
|
||||
audio_data=audio_data,
|
||||
filename=filename,
|
||||
task_id=task_id,
|
||||
target_sr=target_sr,
|
||||
)
|
||||
|
||||
def _process_audio_bytes(
|
||||
self,
|
||||
*,
|
||||
audio_data: bytes,
|
||||
filename: Optional[str],
|
||||
task_id: str,
|
||||
target_sr: int,
|
||||
) -> AudioProcessingResult:
|
||||
"""Persist, normalize, and measure audio bytes."""
|
||||
audio_path = None
|
||||
normalized_audio_path = None
|
||||
|
||||
try:
|
||||
if not audio_data:
|
||||
raise InvalidMessageException("音频数据为空", task_id)
|
||||
|
||||
file_size = len(audio_data)
|
||||
logger.info(f"[{task_id}] 音频文件大小: {file_size / 1024 / 1024:.2f}MB")
|
||||
|
||||
# 检查文件大小
|
||||
if file_size > settings.MAX_AUDIO_SIZE:
|
||||
max_mb = settings.MAX_AUDIO_SIZE // 1024 // 1024
|
||||
raise InvalidMessageException(
|
||||
f"音频文件太大,最大支持{max_mb}MB", task_id
|
||||
)
|
||||
|
||||
file_suffix = get_audio_file_suffix(
|
||||
audio_address=filename,
|
||||
audio_data=audio_data,
|
||||
)
|
||||
logger.info(f"[{task_id}] 识别文件格式: {file_suffix}")
|
||||
audio_path = save_audio_to_temp_file(audio_data, file_suffix)
|
||||
logger.info(f"[{task_id}] 临时文件: {audio_path}")
|
||||
|
||||
logger.info(f"[{task_id}] 开始音频格式转换...")
|
||||
normalized_audio = normalize_audio_for_asr(audio_path, target_sr)
|
||||
normalized_audio_path = normalized_audio.path
|
||||
logger.info(f"[{task_id}] 音频格式转换完成: {normalized_audio_path}")
|
||||
|
||||
decoded_duration = get_audio_duration(normalized_audio_path)
|
||||
audio_duration = decoded_duration * normalized_audio.timestamp_scale
|
||||
logger.info(f"[{task_id}] 音频时长: {audio_duration:.1f}s")
|
||||
|
||||
return AudioProcessingResult(
|
||||
normalized_path=normalized_audio_path,
|
||||
duration=audio_duration,
|
||||
original_path=audio_path,
|
||||
timestamp_scale=normalized_audio.timestamp_scale,
|
||||
)
|
||||
|
||||
except Exception:
|
||||
if audio_path:
|
||||
cleanup_temp_file(audio_path)
|
||||
if normalized_audio_path and normalized_audio_path != audio_path:
|
||||
cleanup_temp_file(normalized_audio_path)
|
||||
raise
|
||||
|
||||
def cleanup(
|
||||
self, audio_path: Optional[str], normalized_path: Optional[str] = None
|
||||
) -> None:
|
||||
"""清理临时文件
|
||||
|
||||
Args:
|
||||
audio_path: 原始音频文件路径
|
||||
normalized_path: 归一化后的音频文件路径(可选)
|
||||
"""
|
||||
if audio_path:
|
||||
cleanup_temp_file(audio_path)
|
||||
if normalized_path and normalized_path != audio_path:
|
||||
cleanup_temp_file(normalized_path)
|
||||
|
||||
|
||||
# 全局服务实例(单例模式)
|
||||
_audio_service: Optional[AudioProcessingService] = None
|
||||
_audio_service_lock = threading.Lock()
|
||||
|
||||
|
||||
def get_audio_service() -> AudioProcessingService:
|
||||
"""获取音频处理服务实例(线程安全的单例)
|
||||
|
||||
Returns:
|
||||
AudioProcessingService: 音频处理服务实例
|
||||
"""
|
||||
global _audio_service
|
||||
if _audio_service is None:
|
||||
with _audio_service_lock:
|
||||
if _audio_service is None:
|
||||
_audio_service = AudioProcessingService()
|
||||
return _audio_service
|
||||
File diff suppressed because it is too large
Load Diff
|
|
@ -0,0 +1,640 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""FunASR-style realtime speaker chunking and clustering."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import re
|
||||
from collections import defaultdict
|
||||
from typing import Any, Dict, List, Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
import scipy.linalg
|
||||
import sklearn.metrics.pairwise
|
||||
from sklearn.cluster._kmeans import k_means
|
||||
|
||||
from app.core.config import settings
|
||||
from app.core.executor import run_sync
|
||||
from app.services.speaker_registry import get_speaker_registry_service
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
class RealtimeSpeakerClusterer:
|
||||
"""Sentence-level speaker attribution using chunk embeddings and session clustering."""
|
||||
|
||||
FUNASR_SMOOTH_MINDUR_SEC = 0.7
|
||||
_FAST_ATTACH_MAX_SEC = 1.6
|
||||
_REGISTRY_MATCH_MIN_SEC = 2.4
|
||||
|
||||
def _is_generic_speaker_name(self, value: Any) -> bool:
|
||||
text = str(value or "").strip()
|
||||
return bool(re.fullmatch(r"Speaker\d+", text))
|
||||
|
||||
def _has_named_identity(self, record: Optional[Dict[str, Any]]) -> bool:
|
||||
if not record:
|
||||
return False
|
||||
return bool(
|
||||
record.get("registry_speaker_id")
|
||||
or record.get("user_id")
|
||||
or (
|
||||
record.get("speaker_name")
|
||||
and not self._is_generic_speaker_name(record.get("speaker_name"))
|
||||
)
|
||||
)
|
||||
|
||||
def _normalize_embedding(self, embedding: np.ndarray) -> np.ndarray:
|
||||
emb = np.asarray(embedding, dtype=np.float32).reshape(-1)
|
||||
norm = max(float(np.linalg.norm(emb)), 1e-12)
|
||||
return (emb / norm).astype(np.float32)
|
||||
|
||||
@staticmethod
|
||||
def _coerce_cluster_index(value: Any, fallback: int) -> int:
|
||||
try:
|
||||
if value is None:
|
||||
return int(fallback)
|
||||
return int(value)
|
||||
except (TypeError, ValueError):
|
||||
return int(fallback)
|
||||
|
||||
def _match_existing_speaker(
|
||||
self,
|
||||
speaker_records: List[Dict[str, Any]],
|
||||
mean_embedding: np.ndarray,
|
||||
) -> Optional[Dict[str, Any]]:
|
||||
if not speaker_records:
|
||||
return None
|
||||
|
||||
best_record: Optional[Dict[str, Any]] = None
|
||||
best_score = -1.0
|
||||
for record in speaker_records:
|
||||
record_embedding = record.get("embedding")
|
||||
if record_embedding is None:
|
||||
continue
|
||||
score = float(np.dot(self._normalize_embedding(record_embedding), mean_embedding))
|
||||
if score > best_score:
|
||||
best_score = score
|
||||
best_record = record
|
||||
|
||||
if best_record is None:
|
||||
return None
|
||||
|
||||
base_threshold = max(
|
||||
float(getattr(settings, "REALTIME_UNKNOWN_SPK_CLUSTER_THRESHOLD", 0.58) or 0.58),
|
||||
0.3,
|
||||
)
|
||||
has_named_identity = bool(
|
||||
best_record.get("registry_speaker_id")
|
||||
or best_record.get("user_id")
|
||||
or (
|
||||
best_record.get("speaker_name")
|
||||
and not self._is_generic_speaker_name(best_record.get("speaker_name"))
|
||||
)
|
||||
)
|
||||
threshold = max(base_threshold, 0.62 if has_named_identity else 0.72)
|
||||
if best_score < threshold:
|
||||
return None
|
||||
|
||||
matched = dict(best_record)
|
||||
matched["_match_score"] = best_score
|
||||
return matched
|
||||
|
||||
def _next_generic_speaker_id(
|
||||
self,
|
||||
speaker_records: List[Dict[str, Any]],
|
||||
) -> str:
|
||||
seen: set[int] = set()
|
||||
for record in speaker_records:
|
||||
for value in (
|
||||
record.get("speaker_id"),
|
||||
record.get("speaker_name"),
|
||||
):
|
||||
text = str(value or "").strip()
|
||||
match = re.fullmatch(r"Speaker(\d+)", text)
|
||||
if match:
|
||||
seen.add(int(match.group(1)))
|
||||
next_index = max(seen, default=0) + 1
|
||||
return f"Speaker{next_index:02d}"
|
||||
|
||||
def _is_mixed_speaker_segment(
|
||||
self,
|
||||
speaker_records: List[Dict[str, Any]],
|
||||
current_chunks: List[Dict[str, Any]],
|
||||
) -> bool:
|
||||
if len(current_chunks) < 2 or len(speaker_records) < 2:
|
||||
return False
|
||||
assigned_labels: List[str] = []
|
||||
for chunk in current_chunks:
|
||||
embedding = chunk.get("embedding")
|
||||
if embedding is None:
|
||||
continue
|
||||
matched = self._match_existing_speaker(
|
||||
speaker_records,
|
||||
self._normalize_embedding(np.asarray(embedding, dtype=np.float32)),
|
||||
)
|
||||
if not matched:
|
||||
continue
|
||||
label = str(
|
||||
matched.get("registry_speaker_id")
|
||||
or matched.get("speaker_name")
|
||||
or matched.get("speaker_id")
|
||||
or ""
|
||||
).strip()
|
||||
if label:
|
||||
assigned_labels.append(label)
|
||||
if len(assigned_labels) < 2:
|
||||
return False
|
||||
return len(set(assigned_labels)) >= 2
|
||||
|
||||
def _correct_labels(self, labels: np.ndarray) -> np.ndarray:
|
||||
labels_id = 0
|
||||
id2id: dict[int, int] = {}
|
||||
new_labels: list[int] = []
|
||||
for label in labels.tolist():
|
||||
label = int(label)
|
||||
if label not in id2id:
|
||||
id2id[label] = labels_id
|
||||
labels_id += 1
|
||||
new_labels.append(id2id[label])
|
||||
return np.asarray(new_labels, dtype=np.int32)
|
||||
|
||||
def _spectral_cluster(self, X: np.ndarray, oracle_num: Optional[int] = None) -> np.ndarray:
|
||||
sim_mat = sklearn.metrics.pairwise.cosine_similarity(X, X)
|
||||
A = sim_mat.copy()
|
||||
pval = 0.022
|
||||
if A.shape[0] * pval < 6:
|
||||
pval = 6.0 / A.shape[0]
|
||||
n_elems = int((1 - pval) * A.shape[0])
|
||||
for i in range(A.shape[0]):
|
||||
low_indexes = np.argsort(A[i, :])[:n_elems]
|
||||
A[i, low_indexes] = 0
|
||||
A = 0.5 * (A + A.T)
|
||||
A[np.diag_indices(A.shape[0])] = 0
|
||||
D = np.diag(np.sum(np.abs(A), axis=1))
|
||||
L = D - A
|
||||
lambdas, eig_vecs = scipy.linalg.eigh(L)
|
||||
if oracle_num is not None:
|
||||
num_spk = max(int(oracle_num), 1)
|
||||
else:
|
||||
min_num_spks = 1
|
||||
max_num_spks = min(15, max(1, X.shape[0] - 1))
|
||||
eig_slice = lambdas[min_num_spks - 1 : max_num_spks + 1]
|
||||
gap_list = [float(eig_slice[i + 1]) - float(eig_slice[i]) for i in range(len(eig_slice) - 1)]
|
||||
num_spk = int(np.argmax(gap_list)) + min_num_spks if gap_list else 1
|
||||
emb = eig_vecs[:, : max(num_spk, 1)]
|
||||
_, labels, _ = k_means(emb, max(num_spk, 1))
|
||||
return np.asarray(labels, dtype=np.int32)
|
||||
|
||||
def _merge_by_cos(self, labels: np.ndarray, embs: np.ndarray, cos_thr: float) -> np.ndarray:
|
||||
labels = np.asarray(labels, dtype=np.int32).copy()
|
||||
while True:
|
||||
spk_num = int(labels.max()) + 1
|
||||
if spk_num <= 1:
|
||||
break
|
||||
centers = []
|
||||
for i in range(spk_num):
|
||||
spk_emb = embs[labels == i].mean(0)
|
||||
centers.append(spk_emb)
|
||||
centers = np.stack(centers, axis=0)
|
||||
norm_centers = centers / np.linalg.norm(centers, axis=1, keepdims=True)
|
||||
affinity = np.matmul(norm_centers, norm_centers.T)
|
||||
affinity = np.triu(affinity, 1)
|
||||
spks = np.unravel_index(np.argmax(affinity), affinity.shape)
|
||||
if float(affinity[spks]) < cos_thr:
|
||||
break
|
||||
for i in range(len(labels)):
|
||||
if labels[i] == spks[1]:
|
||||
labels[i] = spks[0]
|
||||
elif labels[i] > spks[1]:
|
||||
labels[i] -= 1
|
||||
return self._correct_labels(labels)
|
||||
|
||||
def _cluster_embeddings(self, X: np.ndarray, oracle_num: Optional[int] = None) -> np.ndarray:
|
||||
if X.shape[0] < 20:
|
||||
labels = np.zeros(X.shape[0], dtype=np.int32)
|
||||
else:
|
||||
labels = self._spectral_cluster(X, oracle_num=oracle_num)
|
||||
return self._merge_by_cos(labels, X, cos_thr=0.78 if oracle_num is None else 1.0)
|
||||
|
||||
def build_sv_chunks(
|
||||
self,
|
||||
audio: np.ndarray,
|
||||
*,
|
||||
segment_start_ms: int = 0,
|
||||
) -> List[Dict[str, Any]]:
|
||||
audio = np.asarray(audio, dtype=np.float32).flatten()
|
||||
if audio.size == 0:
|
||||
return []
|
||||
sample_rate = 16000
|
||||
chunk_len = int(1.5 * sample_rate)
|
||||
chunk_shift = int(0.75 * sample_rate)
|
||||
chunks: List[Dict[str, Any]] = []
|
||||
last_chunk_end = 0
|
||||
for chunk_start in range(0, audio.shape[0], chunk_shift):
|
||||
chunk_end = min(chunk_start + chunk_len, audio.shape[0])
|
||||
if chunk_end <= last_chunk_end:
|
||||
break
|
||||
actual_start = max(0, chunk_end - chunk_len)
|
||||
actual_end = chunk_end
|
||||
last_chunk_end = actual_end
|
||||
chunk_audio = np.asarray(audio[actual_start:actual_end], dtype=np.float32)
|
||||
if chunk_audio.shape[0] < chunk_len:
|
||||
chunk_audio = np.pad(chunk_audio, (0, chunk_len - chunk_audio.shape[0]), "constant")
|
||||
chunks.append(
|
||||
{
|
||||
"start_ms": int(segment_start_ms + actual_start / 16.0),
|
||||
"end_ms": int(segment_start_ms + actual_end / 16.0),
|
||||
"audio": chunk_audio,
|
||||
}
|
||||
)
|
||||
return chunks
|
||||
|
||||
async def extract_chunk_embeddings(
|
||||
self,
|
||||
audio: np.ndarray,
|
||||
*,
|
||||
segment_start_ms: int = 0,
|
||||
) -> List[Dict[str, Any]]:
|
||||
chunk_items = self.build_sv_chunks(audio, segment_start_ms=segment_start_ms)
|
||||
if not chunk_items:
|
||||
chunk_items = [
|
||||
{
|
||||
"start_ms": int(segment_start_ms),
|
||||
"end_ms": int(segment_start_ms + np.asarray(audio, dtype=np.float32).size / 16.0),
|
||||
"audio": np.asarray(audio, dtype=np.float32),
|
||||
}
|
||||
]
|
||||
|
||||
registry = get_speaker_registry_service()
|
||||
results: List[Dict[str, Any]] = []
|
||||
for item in chunk_items:
|
||||
embedding = await run_sync(
|
||||
registry.extract_embedding_from_audio,
|
||||
item["audio"],
|
||||
16000,
|
||||
model_id=settings.REALTIME_SV_MODEL,
|
||||
model_revision=settings.REALTIME_SV_MODEL_REVISION or None,
|
||||
)
|
||||
results.append(
|
||||
{
|
||||
"start_ms": int(item["start_ms"]),
|
||||
"end_ms": int(item["end_ms"]),
|
||||
"embedding": self._normalize_embedding(np.asarray(embedding, dtype=np.float32)),
|
||||
}
|
||||
)
|
||||
return results
|
||||
|
||||
async def extract_registry_embedding(self, audio: np.ndarray) -> Optional[np.ndarray]:
|
||||
audio_array = np.asarray(audio, dtype=np.float32).flatten()
|
||||
if audio_array.size == 0:
|
||||
return None
|
||||
try:
|
||||
registry = get_speaker_registry_service()
|
||||
embedding = await run_sync(
|
||||
registry.extract_embedding_from_audio,
|
||||
audio_array,
|
||||
16000,
|
||||
)
|
||||
return self._normalize_embedding(np.asarray(embedding, dtype=np.float32))
|
||||
except Exception as exc:
|
||||
logger.warning("Realtime registry speaker embedding failed: %s", exc)
|
||||
return None
|
||||
|
||||
def _flatten_chunk_records(
|
||||
self,
|
||||
records: List[Dict[str, Any]],
|
||||
) -> Tuple[List[Dict[str, Any]], np.ndarray]:
|
||||
flat_chunks: List[Dict[str, Any]] = []
|
||||
flat_embeddings: List[np.ndarray] = []
|
||||
for record_idx, record in enumerate(records):
|
||||
chunk_entries = record.get("chunks") or []
|
||||
if not chunk_entries:
|
||||
embeddings = record.get("embeddings") or []
|
||||
if not embeddings and record.get("embedding") is not None:
|
||||
embeddings = [record["embedding"]]
|
||||
start_ms = int(record.get("start_ms", 0))
|
||||
end_ms = int(record.get("end_ms", start_ms))
|
||||
for embedding in embeddings:
|
||||
chunk_entries.append(
|
||||
{
|
||||
"start_ms": start_ms,
|
||||
"end_ms": end_ms,
|
||||
"embedding": embedding,
|
||||
}
|
||||
)
|
||||
for chunk in chunk_entries:
|
||||
emb = self._normalize_embedding(np.asarray(chunk["embedding"], dtype=np.float32))
|
||||
flat_chunks.append(
|
||||
{
|
||||
"record_index": record_idx,
|
||||
"start_ms": int(chunk.get("start_ms", record.get("start_ms", 0))),
|
||||
"end_ms": int(chunk.get("end_ms", record.get("end_ms", 0))),
|
||||
}
|
||||
)
|
||||
flat_embeddings.append(emb)
|
||||
if not flat_embeddings:
|
||||
return [], np.zeros((0, 0), dtype=np.float32)
|
||||
return flat_chunks, np.stack(flat_embeddings, axis=0).astype(np.float32)
|
||||
|
||||
def _merge_seque(self, distribute_res: List[List[float]]) -> List[List[float]]:
|
||||
if not distribute_res:
|
||||
return []
|
||||
res = [distribute_res[0][:]]
|
||||
for item in distribute_res[1:]:
|
||||
if item[2] != res[-1][2] or item[0] > res[-1][1]:
|
||||
res.append(item[:])
|
||||
else:
|
||||
res[-1][1] = item[1]
|
||||
return res
|
||||
|
||||
def _smooth_timeline(
|
||||
self,
|
||||
res: List[List[float]],
|
||||
mindur: float = FUNASR_SMOOTH_MINDUR_SEC,
|
||||
) -> List[List[float]]:
|
||||
if len(res) < 2:
|
||||
return res
|
||||
for item in res:
|
||||
item[0] = round(float(item[0]), 2)
|
||||
item[1] = round(float(item[1]), 2)
|
||||
for idx in range(len(res)):
|
||||
if res[idx][1] - res[idx][0] < mindur:
|
||||
if idx == 0:
|
||||
res[idx][2] = res[idx + 1][2]
|
||||
elif idx == len(res) - 1:
|
||||
res[idx][2] = res[idx - 1][2]
|
||||
elif res[idx][0] - res[idx - 1][1] <= res[idx + 1][0] - res[idx][1]:
|
||||
res[idx][2] = res[idx - 1][2]
|
||||
else:
|
||||
res[idx][2] = res[idx + 1][2]
|
||||
return self._merge_seque(res)
|
||||
|
||||
def _postprocess_timeline(
|
||||
self,
|
||||
flat_chunks: List[Dict[str, Any]],
|
||||
labels: np.ndarray,
|
||||
embeddings: np.ndarray,
|
||||
) -> List[Dict[str, Any]]:
|
||||
assert len(flat_chunks) == len(labels)
|
||||
labels = self._correct_labels(labels)
|
||||
distribute_res = [
|
||||
[
|
||||
float(chunk["start_ms"]) / 1000.0,
|
||||
float(chunk["end_ms"]) / 1000.0,
|
||||
int(labels[idx]),
|
||||
]
|
||||
for idx, chunk in enumerate(flat_chunks)
|
||||
]
|
||||
distribute_res = self._merge_seque(distribute_res)
|
||||
|
||||
def is_overlapped(t1: float, t2: float) -> bool:
|
||||
return t1 > t2 + 1e-4
|
||||
|
||||
for idx in range(1, len(distribute_res)):
|
||||
if is_overlapped(distribute_res[idx - 1][1], distribute_res[idx][0]):
|
||||
pivot = (distribute_res[idx][0] + distribute_res[idx - 1][1]) / 2.0
|
||||
distribute_res[idx][0] = pivot
|
||||
distribute_res[idx - 1][1] = pivot
|
||||
|
||||
distribute_res = self._smooth_timeline(distribute_res)
|
||||
return [
|
||||
{
|
||||
"start_ms": int(round(item[0] * 1000.0)),
|
||||
"end_ms": int(round(item[1] * 1000.0)),
|
||||
"cluster_index": int(item[2]),
|
||||
}
|
||||
for item in distribute_res
|
||||
]
|
||||
|
||||
def _pick_segment_cluster(
|
||||
self,
|
||||
cluster_ranges: List[Dict[str, Any]],
|
||||
*,
|
||||
segment_start_ms: int,
|
||||
segment_end_ms: int,
|
||||
) -> int:
|
||||
overlaps: Dict[int, int] = defaultdict(int)
|
||||
for item in cluster_ranges:
|
||||
overlap = min(segment_end_ms, int(item["end_ms"])) - max(segment_start_ms, int(item["start_ms"]))
|
||||
if overlap > 0:
|
||||
overlaps[int(item["cluster_index"])] += int(overlap)
|
||||
if overlaps:
|
||||
return max(overlaps.items(), key=lambda kv: (kv[1], -kv[0]))[0]
|
||||
|
||||
centers = [
|
||||
item for item in cluster_ranges
|
||||
if int(item["start_ms"]) <= segment_end_ms and int(item["end_ms"]) >= segment_start_ms
|
||||
]
|
||||
if centers:
|
||||
return int(centers[0]["cluster_index"])
|
||||
return 0
|
||||
|
||||
def cluster_records_with_ranges(
|
||||
self,
|
||||
records: List[Dict[str, Any]],
|
||||
) -> Tuple[List[Dict[str, Any]], List[int], List[Dict[str, Any]]]:
|
||||
flat_chunks, X = self._flatten_chunk_records(records)
|
||||
if X.size == 0:
|
||||
return [], [], []
|
||||
|
||||
labels = self._cluster_embeddings(X, oracle_num=None)
|
||||
cluster_ranges = self._postprocess_timeline(flat_chunks, labels, X)
|
||||
|
||||
cluster_ids = sorted({int(item["cluster_index"]) for item in cluster_ranges})
|
||||
if not cluster_ids:
|
||||
cluster_ids = sorted({int(label) for label in labels.tolist()})
|
||||
|
||||
clusters: List[Dict[str, Any]] = []
|
||||
for cluster_idx in cluster_ids:
|
||||
member_mask = labels == int(cluster_idx)
|
||||
member_embeddings = X[member_mask]
|
||||
centroid = self._normalize_embedding(member_embeddings.mean(0))
|
||||
record_refs = []
|
||||
seen_record_indices = set()
|
||||
for emb_idx, chunk in enumerate(flat_chunks):
|
||||
record_idx = int(chunk["record_index"])
|
||||
if not member_mask[emb_idx] or record_idx in seen_record_indices:
|
||||
continue
|
||||
seen_record_indices.add(record_idx)
|
||||
record_refs.append(records[record_idx])
|
||||
clusters.append(
|
||||
{
|
||||
"centroid": centroid,
|
||||
"count": int(member_mask.sum()),
|
||||
"record_refs": record_refs,
|
||||
}
|
||||
)
|
||||
|
||||
record_to_labels: List[List[int]] = [[] for _ in records]
|
||||
for emb_idx, chunk in enumerate(flat_chunks):
|
||||
record_to_labels[int(chunk["record_index"])].append(int(labels[emb_idx]))
|
||||
|
||||
record_assignments: List[int] = []
|
||||
for record, local_assignments in zip(records, record_to_labels):
|
||||
if local_assignments:
|
||||
cluster_idx = self._pick_segment_cluster(
|
||||
cluster_ranges,
|
||||
segment_start_ms=int(record.get("start_ms", 0)),
|
||||
segment_end_ms=int(record.get("end_ms", record.get("start_ms", 0))),
|
||||
)
|
||||
record_assignments.append(cluster_idx)
|
||||
else:
|
||||
record_assignments.append(-1)
|
||||
|
||||
return clusters, record_assignments, cluster_ranges
|
||||
|
||||
def cluster_records(
|
||||
self,
|
||||
records: List[Dict[str, Any]],
|
||||
) -> Tuple[List[Dict[str, Any]], List[int]]:
|
||||
clusters, record_assignments, _ = self.cluster_records_with_ranges(records)
|
||||
return clusters, record_assignments
|
||||
|
||||
async def resolve_segment_speaker(
|
||||
self,
|
||||
speaker_records: List[Dict[str, Any]],
|
||||
audio: np.ndarray,
|
||||
*,
|
||||
segment_start_ms: int,
|
||||
segment_end_ms: int,
|
||||
enable_registry_match: bool,
|
||||
speaker_threshold: Optional[float],
|
||||
) -> Optional[Dict[str, Any]]:
|
||||
duration_sec = float(len(audio)) / 16000.0
|
||||
last_record = speaker_records[-1] if speaker_records else None
|
||||
if duration_sec < self._FAST_ATTACH_MAX_SEC and speaker_records:
|
||||
if self._has_named_identity(last_record):
|
||||
speaker_id = last_record.get("registry_speaker_id") or last_record.get("speaker_id") or "Speaker01"
|
||||
speaker_name = last_record.get("speaker_name") or speaker_id
|
||||
return {
|
||||
"speaker_id": speaker_id,
|
||||
"speaker_name": speaker_name,
|
||||
"user_id": last_record.get("user_id"),
|
||||
"registry_speaker_id": last_record.get("registry_speaker_id"),
|
||||
"speaker_confidence": 0.0,
|
||||
"speaker_strategy": "short_attach",
|
||||
"_cluster_index": last_record.get("cluster_index"),
|
||||
"_embedding": last_record.get("embedding"),
|
||||
"_chunk_embeddings": last_record.get("embeddings") or [],
|
||||
"_chunks": last_record.get("chunks") or [],
|
||||
}
|
||||
|
||||
current_chunks = await self.extract_chunk_embeddings(
|
||||
np.asarray(audio, dtype=np.float32),
|
||||
segment_start_ms=segment_start_ms,
|
||||
)
|
||||
if not current_chunks:
|
||||
if speaker_records:
|
||||
if self._has_named_identity(last_record):
|
||||
speaker_id = last_record.get("registry_speaker_id") or last_record.get("speaker_id") or "Speaker01"
|
||||
speaker_name = last_record.get("speaker_name") or speaker_id
|
||||
return {
|
||||
"speaker_id": speaker_id,
|
||||
"speaker_name": speaker_name,
|
||||
"user_id": last_record.get("user_id"),
|
||||
"registry_speaker_id": last_record.get("registry_speaker_id"),
|
||||
"speaker_confidence": 0.0,
|
||||
"speaker_strategy": "embedding_attach",
|
||||
"_cluster_index": last_record.get("cluster_index"),
|
||||
"_embedding": last_record.get("embedding"),
|
||||
"_chunk_embeddings": last_record.get("embeddings") or [],
|
||||
"_chunks": last_record.get("chunks") or [],
|
||||
}
|
||||
return None
|
||||
|
||||
mean_embedding = self._normalize_embedding(
|
||||
np.mean(np.stack([chunk["embedding"] for chunk in current_chunks], axis=0), axis=0)
|
||||
)
|
||||
if duration_sec >= 4.0 and self._is_mixed_speaker_segment(speaker_records, current_chunks):
|
||||
return {
|
||||
"speaker_id": -1,
|
||||
"speaker_name": "",
|
||||
"user_id": None,
|
||||
"registry_speaker_id": None,
|
||||
"speaker_confidence": 0.0,
|
||||
"speaker_strategy": "mixed_segment",
|
||||
"_cluster_index": None,
|
||||
"_embedding": mean_embedding,
|
||||
"_chunk_embeddings": [np.asarray(chunk["embedding"], dtype=np.float32) for chunk in current_chunks],
|
||||
"_chunks": current_chunks,
|
||||
}
|
||||
matched_record = self._match_existing_speaker(speaker_records, mean_embedding)
|
||||
speaker_id = self._next_generic_speaker_id(speaker_records)
|
||||
speaker_name = speaker_id
|
||||
user_id = None
|
||||
registry_speaker_id = None
|
||||
strategy = "new_speaker"
|
||||
cluster_index = max(
|
||||
[
|
||||
int(record.get("cluster_index", -1))
|
||||
for record in speaker_records
|
||||
if record.get("cluster_index") is not None
|
||||
] or [-1]
|
||||
) + 1
|
||||
confidence = 0.0
|
||||
|
||||
if matched_record is not None:
|
||||
speaker_id = (
|
||||
matched_record.get("registry_speaker_id")
|
||||
or matched_record.get("speaker_id")
|
||||
or speaker_id
|
||||
)
|
||||
speaker_name = matched_record.get("speaker_name") or speaker_id
|
||||
user_id = matched_record.get("user_id")
|
||||
registry_speaker_id = matched_record.get("registry_speaker_id")
|
||||
cluster_index = self._coerce_cluster_index(
|
||||
matched_record.get("cluster_index"),
|
||||
cluster_index,
|
||||
)
|
||||
confidence = float(matched_record.get("_match_score", 0.0))
|
||||
strategy = "embedding_match"
|
||||
|
||||
if (
|
||||
not registry_speaker_id
|
||||
and enable_registry_match
|
||||
and duration_sec >= self._REGISTRY_MATCH_MIN_SEC
|
||||
and (
|
||||
matched_record is None
|
||||
or confidence >= max(float(getattr(settings, "REALTIME_SPEAKER_CONFIRM_THRESHOLD", 0.62) or 0.62), 0.7)
|
||||
)
|
||||
):
|
||||
# Realtime clustering can use a dedicated fast model, while the
|
||||
# registry stores embeddings from the registration model. Match the
|
||||
# registry in its own embedding space instead of comparing vectors
|
||||
# extracted by a different model.
|
||||
registry_embedding = await self.extract_registry_embedding(audio)
|
||||
if registry_embedding is not None:
|
||||
matched = await get_speaker_registry_service().identify_embedding(
|
||||
registry_embedding,
|
||||
threshold=speaker_threshold,
|
||||
)
|
||||
if matched.get("name"):
|
||||
speaker_id = matched.get("speaker_id") or speaker_id
|
||||
speaker_name = matched.get("name") or speaker_name
|
||||
user_id = matched.get("user_id")
|
||||
registry_speaker_id = matched.get("speaker_id")
|
||||
strategy = "registry_match"
|
||||
|
||||
return {
|
||||
"speaker_id": speaker_id,
|
||||
"speaker_name": speaker_name,
|
||||
"user_id": user_id,
|
||||
"registry_speaker_id": registry_speaker_id,
|
||||
"speaker_confidence": round(confidence, 4),
|
||||
"speaker_strategy": strategy,
|
||||
"_cluster_index": self._coerce_cluster_index(cluster_index, 0),
|
||||
"_embedding": mean_embedding,
|
||||
"_chunk_embeddings": [np.asarray(chunk["embedding"], dtype=np.float32) for chunk in current_chunks],
|
||||
"_chunks": current_chunks,
|
||||
"_matched_existing": matched_record is not None,
|
||||
}
|
||||
|
||||
|
||||
_realtime_speaker_clusterer: Optional[RealtimeSpeakerClusterer] = None
|
||||
|
||||
|
||||
def get_realtime_speaker_clusterer() -> RealtimeSpeakerClusterer:
|
||||
global _realtime_speaker_clusterer
|
||||
if _realtime_speaker_clusterer is None:
|
||||
_realtime_speaker_clusterer = RealtimeSpeakerClusterer()
|
||||
return _realtime_speaker_clusterer
|
||||
|
|
@ -0,0 +1,250 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Speaker embedding extraction, registration, and database identification."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import logging
|
||||
import os
|
||||
import tempfile
|
||||
import threading
|
||||
from typing import Any, Optional
|
||||
|
||||
import librosa
|
||||
import numpy as np
|
||||
import soundfile as sf
|
||||
import torch
|
||||
|
||||
from app.core.config import settings
|
||||
from app.core.database import pg_speaker_db
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def _normalize_embedding(embedding: np.ndarray) -> np.ndarray:
|
||||
array = np.asarray(embedding, dtype=np.float32).flatten()
|
||||
norm = float(np.linalg.norm(array))
|
||||
if norm < 1e-12:
|
||||
return array
|
||||
return array / norm
|
||||
|
||||
|
||||
class SpeakerRegistryService:
|
||||
"""Owns speaker embedding models and pgvector lookups."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._pipelines: dict[tuple[str, str], Any] = {}
|
||||
self._lock = threading.Lock()
|
||||
self._inference_lock = threading.BoundedSemaphore(1)
|
||||
|
||||
def _device(self) -> str:
|
||||
from app.core.device import detect_device
|
||||
|
||||
return detect_device(settings.DEVICE)
|
||||
|
||||
def _get_pipeline(
|
||||
self,
|
||||
model_id: Optional[str] = None,
|
||||
model_revision: Optional[str] = None,
|
||||
) -> Any:
|
||||
effective_model_id = model_id or settings.SV_MODEL
|
||||
effective_revision = model_revision if model_revision is not None else settings.SV_MODEL_REVISION
|
||||
cache_key = (effective_model_id, effective_revision or "")
|
||||
cached = self._pipelines.get(cache_key)
|
||||
if cached is not None:
|
||||
return cached
|
||||
with self._lock:
|
||||
cached = self._pipelines.get(cache_key)
|
||||
if cached is not None:
|
||||
return cached
|
||||
from modelscope.pipelines import pipeline
|
||||
from modelscope.utils.constant import Tasks
|
||||
|
||||
from app.infrastructure.model_utils import resolve_model_path
|
||||
|
||||
model_path = resolve_model_path(effective_model_id)
|
||||
device = self._device()
|
||||
kwargs: dict[str, Any] = {
|
||||
"task": Tasks.speaker_verification,
|
||||
"model": model_path,
|
||||
"device": device,
|
||||
}
|
||||
if effective_revision:
|
||||
kwargs["model_revision"] = effective_revision
|
||||
logger.info("正在加载声纹识别模型: %s, device=%s", model_path, device)
|
||||
pipeline_instance = pipeline(**kwargs)
|
||||
if hasattr(pipeline_instance, "device_name"):
|
||||
pipeline_instance.device_name = device
|
||||
model = getattr(pipeline_instance, "model", None)
|
||||
if model is not None and hasattr(model, "to"):
|
||||
pipeline_instance.model = model.to(device)
|
||||
logger.info("声纹识别模型加载成功")
|
||||
self._pipelines[cache_key] = pipeline_instance
|
||||
return pipeline_instance
|
||||
|
||||
def ensure_loaded(self) -> None:
|
||||
"""Eagerly initialize the speaker verification pipeline at startup."""
|
||||
self._get_pipeline()
|
||||
|
||||
def extract_embedding_from_audio(
|
||||
self,
|
||||
audio_data: np.ndarray,
|
||||
sample_rate: int = 16000,
|
||||
*,
|
||||
model_id: Optional[str] = None,
|
||||
model_revision: Optional[str] = None,
|
||||
) -> np.ndarray:
|
||||
audio = np.asarray(audio_data, dtype=np.float32).flatten()
|
||||
if audio.size == 0:
|
||||
raise ValueError("empty audio")
|
||||
if sample_rate != 16000:
|
||||
audio = librosa.resample(audio, orig_sr=sample_rate, target_sr=16000)
|
||||
pipeline_instance = self._get_pipeline(model_id=model_id, model_revision=model_revision)
|
||||
model = getattr(pipeline_instance, "model", None)
|
||||
if model is None:
|
||||
raise RuntimeError("speaker verification model is not initialized")
|
||||
device = getattr(pipeline_instance, "device_name", self._device())
|
||||
with self._inference_lock:
|
||||
with torch.no_grad():
|
||||
embeddings = model(torch.as_tensor(audio[None, :]).to(device))
|
||||
if isinstance(embeddings, torch.Tensor):
|
||||
embedding = embeddings.detach().cpu().numpy()[0]
|
||||
else:
|
||||
embedding = np.asarray(embeddings, dtype=np.float32)[0]
|
||||
return _normalize_embedding(embedding)
|
||||
|
||||
def extract_embedding_from_file(self, file_path: str) -> np.ndarray:
|
||||
audio_data, sample_rate = librosa.load(file_path, sr=16000, mono=True)
|
||||
return self.extract_embedding_from_audio(audio_data, int(sample_rate))
|
||||
|
||||
async def register_file(
|
||||
self,
|
||||
*,
|
||||
name: str,
|
||||
file_path: str,
|
||||
user_id: Optional[str] = None,
|
||||
) -> dict[str, Optional[str]]:
|
||||
if not pg_speaker_db.is_connected:
|
||||
raise RuntimeError("Speaker database is not connected")
|
||||
loop = asyncio.get_running_loop()
|
||||
embedding = await loop.run_in_executor(
|
||||
None,
|
||||
self.extract_embedding_from_file,
|
||||
file_path,
|
||||
)
|
||||
speaker = await pg_speaker_db.save_speaker(name, embedding, user_id=user_id)
|
||||
return {
|
||||
"speaker_id": speaker.get("id"),
|
||||
"name": speaker.get("name") or name,
|
||||
"user_id": speaker.get("user_id"),
|
||||
"speaker_model": "CampPlus",
|
||||
}
|
||||
|
||||
async def identify_embedding(
|
||||
self,
|
||||
embedding: np.ndarray,
|
||||
threshold: Optional[float] = None,
|
||||
) -> dict[str, Optional[str]]:
|
||||
if not pg_speaker_db.is_connected:
|
||||
return {"speaker_id": None, "name": None, "user_id": None}
|
||||
speaker = await pg_speaker_db.identify_speaker(
|
||||
_normalize_embedding(embedding),
|
||||
threshold if threshold is not None else settings.SV_THRESHOLD,
|
||||
)
|
||||
return {
|
||||
"speaker_id": speaker.get("id"),
|
||||
"name": speaker.get("name"),
|
||||
"user_id": speaker.get("user_id"),
|
||||
"speaker_model": "CampPlus",
|
||||
}
|
||||
|
||||
async def identify_file(
|
||||
self,
|
||||
*,
|
||||
file_path: str,
|
||||
threshold: Optional[float] = None,
|
||||
) -> dict[str, Optional[str]]:
|
||||
loop = asyncio.get_running_loop()
|
||||
embedding = await loop.run_in_executor(
|
||||
None,
|
||||
self.extract_embedding_from_file,
|
||||
file_path,
|
||||
)
|
||||
return await self.identify_embedding(embedding, threshold=threshold)
|
||||
|
||||
async def apply_registered_speakers(
|
||||
self,
|
||||
result: Any,
|
||||
threshold: Optional[float] = None,
|
||||
) -> Any:
|
||||
if not pg_speaker_db.is_connected:
|
||||
return result
|
||||
|
||||
cache: dict[str, dict[str, Optional[str]]] = {}
|
||||
for segment in getattr(result, "segments", []) or []:
|
||||
embedding = getattr(segment, "speaker_embedding", None)
|
||||
local_speaker_id = getattr(segment, "speaker_id", None)
|
||||
if embedding is None or not local_speaker_id:
|
||||
continue
|
||||
if local_speaker_id not in cache:
|
||||
matched_candidate = await self.identify_embedding(
|
||||
np.asarray(embedding, dtype=np.float32),
|
||||
threshold=threshold,
|
||||
)
|
||||
if matched_candidate.get("name"):
|
||||
cache[local_speaker_id] = matched_candidate
|
||||
else:
|
||||
continue
|
||||
matched = cache[local_speaker_id]
|
||||
if matched.get("name"):
|
||||
segment.speaker_id = matched.get("speaker_id") or segment.speaker_id
|
||||
segment.speaker_name = matched.get("name")
|
||||
segment.user_id = matched.get("user_id")
|
||||
return result
|
||||
|
||||
async def list_speakers(self) -> list[dict[str, Optional[str]]]:
|
||||
return await pg_speaker_db.list_speakers()
|
||||
|
||||
async def delete_speaker(self, speaker_id: str) -> bool:
|
||||
if not speaker_id.isdigit():
|
||||
return False
|
||||
return await pg_speaker_db.delete_speaker(int(speaker_id))
|
||||
|
||||
@staticmethod
|
||||
async def save_upload_to_temp(content: bytes, suffix: str = ".wav") -> str:
|
||||
fd, path = tempfile.mkstemp(prefix="speaker_", suffix=suffix, dir=settings.TEMP_DIR)
|
||||
try:
|
||||
with os.fdopen(fd, "wb") as file_obj:
|
||||
file_obj.write(content)
|
||||
except Exception:
|
||||
os.close(fd)
|
||||
raise
|
||||
return path
|
||||
|
||||
@staticmethod
|
||||
def cleanup_file(path: Optional[str]) -> None:
|
||||
if path and os.path.exists(path):
|
||||
try:
|
||||
os.remove(path)
|
||||
except Exception as exc:
|
||||
logger.warning("清理临时声纹文件失败 %s: %s", path, exc)
|
||||
|
||||
@staticmethod
|
||||
def save_audio_array_to_temp(audio_data: np.ndarray, sample_rate: int = 16000) -> str:
|
||||
fd, path = tempfile.mkstemp(prefix="speaker_array_", suffix=".wav", dir=settings.TEMP_DIR)
|
||||
os.close(fd)
|
||||
sf.write(path, np.asarray(audio_data, dtype=np.float32), sample_rate)
|
||||
return path
|
||||
|
||||
|
||||
_speaker_registry_service: Optional[SpeakerRegistryService] = None
|
||||
_speaker_registry_lock = threading.Lock()
|
||||
|
||||
|
||||
def get_speaker_registry_service() -> SpeakerRegistryService:
|
||||
global _speaker_registry_service
|
||||
if _speaker_registry_service is None:
|
||||
with _speaker_registry_lock:
|
||||
if _speaker_registry_service is None:
|
||||
_speaker_registry_service = SpeakerRegistryService()
|
||||
return _speaker_registry_service
|
||||
|
|
@ -0,0 +1,24 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
工具模块
|
||||
包含通用工具函数和辅助功能
|
||||
"""
|
||||
|
||||
from .common import generate_task_id, validate_text_input, parse_language_code
|
||||
from .audio import save_audio_array, load_audio_file, generate_temp_audio_path, cleanup_temp_file
|
||||
from .text_processing import apply_itn_to_text, normalize_asr_text
|
||||
|
||||
__all__ = [
|
||||
# 通用工具函数
|
||||
"generate_task_id",
|
||||
"validate_text_input",
|
||||
"parse_language_code",
|
||||
# 音频工具函数
|
||||
"save_audio_array",
|
||||
"load_audio_file",
|
||||
"generate_temp_audio_path",
|
||||
"cleanup_temp_file",
|
||||
# ITN(逆文本标准化)功能 - 基于itntext
|
||||
"apply_itn_to_text",
|
||||
"normalize_asr_text",
|
||||
]
|
||||
|
|
@ -0,0 +1,528 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
统一音频处理工具
|
||||
ASR音频处理功能
|
||||
"""
|
||||
|
||||
import os
|
||||
import tempfile
|
||||
import requests
|
||||
import librosa
|
||||
import soundfile as sf
|
||||
import numpy as np
|
||||
import subprocess
|
||||
import logging
|
||||
from dataclasses import dataclass
|
||||
from typing import Tuple, Optional
|
||||
from io import BytesIO
|
||||
from urllib.parse import unquote, urlparse
|
||||
|
||||
from ..core.config import settings
|
||||
from ..core.exceptions import (
|
||||
InvalidParameterException,
|
||||
InvalidMessageException,
|
||||
DefaultServerErrorException,
|
||||
)
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class NormalizedAudio:
|
||||
path: str
|
||||
timestamp_scale: float = 1.0
|
||||
|
||||
|
||||
def download_audio_from_url(url: str, max_size: Optional[int] = None) -> bytes:
|
||||
"""从 URL 或服务端本地路径读取音频文件
|
||||
|
||||
Args:
|
||||
url: 音频文件 URL、本地路径或 file:// 路径
|
||||
max_size: 最大文件大小限制
|
||||
|
||||
Returns:
|
||||
音频文件的二进制数据
|
||||
|
||||
Raises:
|
||||
InvalidParameterException: URL无效或下载失败
|
||||
InvalidMessageException: 文件太大
|
||||
"""
|
||||
if not url:
|
||||
raise InvalidParameterException("URL不能为空")
|
||||
|
||||
max_file_size = max_size or settings.MAX_AUDIO_SIZE
|
||||
parsed = urlparse(url)
|
||||
|
||||
if parsed.scheme in {"", "file"}:
|
||||
local_path = os.path.expanduser(unquote(parsed.path) if parsed.scheme == "file" else url)
|
||||
if not os.path.isfile(local_path):
|
||||
raise InvalidParameterException(f"本地音频文件不存在: {local_path}")
|
||||
file_size = os.path.getsize(local_path)
|
||||
if file_size > max_file_size:
|
||||
max_size_mb = max_file_size // 1024 // 1024
|
||||
raise InvalidMessageException(f"音频文件太大,最大支持{max_size_mb}MB")
|
||||
with open(local_path, "rb") as file_obj:
|
||||
return file_obj.read()
|
||||
|
||||
try:
|
||||
response = requests.get(url, timeout=30, stream=True)
|
||||
response.raise_for_status()
|
||||
|
||||
# 检查Content-Length头
|
||||
content_length = response.headers.get("content-length")
|
||||
if content_length and int(content_length) > max_file_size:
|
||||
max_size_mb = max_file_size // 1024 // 1024
|
||||
raise InvalidMessageException(f"音频文件太大,最大支持{max_size_mb}MB")
|
||||
|
||||
# 分块下载并检查大小
|
||||
audio_data = BytesIO()
|
||||
downloaded_size = 0
|
||||
|
||||
for chunk in response.iter_content(chunk_size=8192):
|
||||
downloaded_size += len(chunk)
|
||||
if downloaded_size > max_file_size:
|
||||
max_size_mb = max_file_size // 1024 // 1024
|
||||
raise InvalidMessageException(f"音频文件太大,最大支持{max_size_mb}MB")
|
||||
audio_data.write(chunk)
|
||||
|
||||
return audio_data.getvalue()
|
||||
|
||||
except requests.RequestException as e:
|
||||
raise InvalidParameterException(f"下载音频文件失败: {str(e)}")
|
||||
|
||||
|
||||
def save_audio_to_temp_file(audio_data: bytes, suffix: str = ".wav") -> str:
|
||||
"""保存音频数据到临时文件
|
||||
|
||||
Args:
|
||||
audio_data: 音频二进制数据
|
||||
suffix: 文件后缀
|
||||
|
||||
Returns:
|
||||
临时文件路径
|
||||
|
||||
Raises:
|
||||
AudioProcessingException: 保存失败
|
||||
"""
|
||||
try:
|
||||
with tempfile.NamedTemporaryFile(
|
||||
delete=False, suffix=suffix, dir=settings.TEMP_DIR
|
||||
) as temp_file:
|
||||
temp_file.write(audio_data)
|
||||
return temp_file.name
|
||||
except Exception as e:
|
||||
raise DefaultServerErrorException(f"保存音频文件失败: {str(e)}")
|
||||
|
||||
|
||||
def cleanup_temp_file(file_path: str) -> None:
|
||||
"""清理临时文件
|
||||
|
||||
Args:
|
||||
file_path: 文件路径
|
||||
"""
|
||||
try:
|
||||
if file_path and os.path.exists(file_path):
|
||||
os.remove(file_path)
|
||||
except Exception:
|
||||
# 静默忽略清理错误
|
||||
pass
|
||||
|
||||
|
||||
def load_audio_file(audio_path: str, target_sr: int = 16000) -> Tuple[np.ndarray, int]:
|
||||
"""加载音频文件并转换为指定采样率
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
target_sr: 目标采样率
|
||||
|
||||
Returns:
|
||||
(audio_data, sample_rate): 音频数据和采样率
|
||||
|
||||
Raises:
|
||||
AudioProcessingException: 加载失败
|
||||
"""
|
||||
try:
|
||||
# 使用librosa加载音频
|
||||
audio_data, sr = librosa.load(audio_path, sr=target_sr)
|
||||
return audio_data, int(sr)
|
||||
except Exception as e:
|
||||
raise DefaultServerErrorException(f"加载音频文件失败: {str(e)}")
|
||||
|
||||
|
||||
def get_audio_duration(audio_path: str) -> float:
|
||||
"""获取音频文件时长
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
|
||||
Returns:
|
||||
音频时长(秒)
|
||||
|
||||
Raises:
|
||||
AudioProcessingException: 获取时长失败
|
||||
"""
|
||||
try:
|
||||
# Load audio and get duration
|
||||
y, sr = librosa.load(audio_path, sr=None)
|
||||
duration = librosa.get_duration(y=y, sr=sr)
|
||||
return duration
|
||||
except Exception as e:
|
||||
raise DefaultServerErrorException(f"获取音频时长失败: {str(e)}")
|
||||
|
||||
|
||||
def get_container_duration(audio_path: str) -> Optional[float]:
|
||||
"""通过 ffprobe 获取音频容器的 metadata 时长
|
||||
|
||||
对于 m4a/AAC 等压缩格式,容器记录的时长可能与实际解码样本数不一致
|
||||
(常见于 m3u8/ts 分片合并的音频)。返回 None 表示获取失败。
|
||||
"""
|
||||
try:
|
||||
result = subprocess.run(
|
||||
["ffprobe", "-v", "error", "-show_entries", "format=duration",
|
||||
"-of", "default=noprint_wrappers=1:nokey=1", audio_path],
|
||||
capture_output=True, text=True, timeout=10,
|
||||
)
|
||||
if result.returncode == 0 and result.stdout.strip():
|
||||
return float(result.stdout.strip())
|
||||
except Exception as e:
|
||||
logger.debug(f"ffprobe 获取容器时长失败: {e}")
|
||||
return None
|
||||
|
||||
|
||||
def get_timestamp_scale(original_audio_path: str, decoded_duration: float) -> float:
|
||||
"""计算时间戳缩放系数
|
||||
|
||||
对比容器 metadata 时长与解码后实际时长,返回缩放系数。
|
||||
用于修正 m4a/AAC 等格式中容器时长与解码时长不一致的问题。
|
||||
|
||||
Args:
|
||||
original_audio_path: 原始音频文件路径(转换前)
|
||||
decoded_duration: 解码后的实际音频时长(秒)
|
||||
|
||||
Returns:
|
||||
缩放系数(容器时长 / 解码时长),无差异时返回 1.0
|
||||
"""
|
||||
container_duration = get_container_duration(original_audio_path)
|
||||
if container_duration is None or decoded_duration <= 0:
|
||||
return 1.0
|
||||
|
||||
scale = container_duration / decoded_duration
|
||||
if abs(scale - 1.0) < 0.001:
|
||||
# 差异 < 0.1%,忽略
|
||||
return 1.0
|
||||
|
||||
logger.info(
|
||||
f"检测到容器/解码时长不一致: container={container_duration:.3f}s, "
|
||||
f"decoded={decoded_duration:.3f}s, scale={scale:.6f}"
|
||||
)
|
||||
return scale
|
||||
|
||||
|
||||
def resample_audio_array(
|
||||
audio_array: np.ndarray,
|
||||
original_sr: int,
|
||||
target_sr: int,
|
||||
) -> np.ndarray:
|
||||
"""重采样音频数组
|
||||
|
||||
Args:
|
||||
audio_array: 原始音频数据
|
||||
original_sr: 原始采样率
|
||||
target_sr: 目标采样率
|
||||
|
||||
Returns:
|
||||
重采样后的音频数据
|
||||
"""
|
||||
if original_sr == target_sr:
|
||||
return audio_array
|
||||
|
||||
try:
|
||||
# 确保是1D数组用于librosa重采样
|
||||
if audio_array.ndim > 1:
|
||||
# 如果是多声道,取第一个声道
|
||||
if audio_array.shape[0] > audio_array.shape[1]:
|
||||
audio_1d = audio_array[0, :]
|
||||
else:
|
||||
audio_1d = (
|
||||
audio_array[:, 0]
|
||||
if audio_array.shape[1] > 1
|
||||
else audio_array.flatten()
|
||||
)
|
||||
else:
|
||||
audio_1d = audio_array
|
||||
|
||||
# 使用librosa进行重采样
|
||||
resampled = librosa.resample(audio_1d, orig_sr=original_sr, target_sr=target_sr)
|
||||
|
||||
logger.info(f"音频重采样: {original_sr}Hz -> {target_sr}Hz")
|
||||
return resampled
|
||||
|
||||
except Exception as e:
|
||||
logger.warning(f"音频重采样失败: {str(e)},使用原始音频")
|
||||
return audio_array
|
||||
|
||||
|
||||
def adjust_audio_volume(audio_array: np.ndarray, volume: int) -> np.ndarray:
|
||||
"""调节音频音量
|
||||
|
||||
Args:
|
||||
audio_array: 音频数据数组
|
||||
volume: 音量值,范围0~100,50为原始音量
|
||||
|
||||
Returns:
|
||||
调节后的音频数据
|
||||
"""
|
||||
if int(volume) == 50:
|
||||
return audio_array
|
||||
|
||||
if volume < 0 or volume > 100:
|
||||
logger.warning(f"音量值{volume}超出范围[0,100],使用默认值50")
|
||||
volume = 50
|
||||
|
||||
# 将音量值转换为倍数 (0-100 -> 0-2.0)
|
||||
volume_factor = volume / 50.0
|
||||
|
||||
# 应用音量调节
|
||||
adjusted_audio = audio_array * volume_factor
|
||||
|
||||
# 防止削波,如果音量过大导致超过范围,进行归一化
|
||||
max_val = np.max(np.abs(adjusted_audio))
|
||||
if max_val > 1.0:
|
||||
adjusted_audio = adjusted_audio / max_val
|
||||
logger.info(f"音量调节后进行归一化,最大值: {max_val:.3f}")
|
||||
|
||||
logger.info(f"音频音量已调节: {volume}/100 (倍数: {volume_factor:.2f})")
|
||||
return adjusted_audio
|
||||
|
||||
|
||||
def save_audio_array(
|
||||
audio_array: np.ndarray,
|
||||
output_path: str,
|
||||
sample_rate: int = 22050,
|
||||
format: str = "wav",
|
||||
original_sr: Optional[int] = None,
|
||||
volume: int = 50,
|
||||
) -> str:
|
||||
"""保存音频数组到文件
|
||||
|
||||
Args:
|
||||
audio_array: 音频数据数组
|
||||
output_path: 输出文件路径
|
||||
sample_rate: 目标采样率
|
||||
format: 音频格式
|
||||
original_sr: 原始采样率(用于重采样)
|
||||
volume: 音量值,范围0~100,默认50
|
||||
|
||||
Returns:
|
||||
保存的文件路径
|
||||
|
||||
Raises:
|
||||
AudioProcessingException: 保存失败
|
||||
"""
|
||||
try:
|
||||
# 如果指定了原始采样率且与目标采样率不同,进行重采样
|
||||
if original_sr and original_sr != sample_rate:
|
||||
audio_array = resample_audio_array(audio_array, original_sr, sample_rate)
|
||||
|
||||
# 调节音频音量
|
||||
audio_array = adjust_audio_volume(audio_array, volume)
|
||||
|
||||
# 确保音频数据是float32格式
|
||||
if audio_array.dtype != np.float32:
|
||||
audio_array = audio_array.astype(np.float32)
|
||||
|
||||
# 确保音频数据在正确的范围内
|
||||
if np.max(np.abs(audio_array)) > 1.0:
|
||||
audio_array = audio_array / np.max(np.abs(audio_array))
|
||||
|
||||
# 确保是2D张量 (channels, samples)
|
||||
if audio_array.ndim == 1:
|
||||
audio_array = audio_array[np.newaxis, :] # 添加通道维度
|
||||
elif audio_array.ndim > 2:
|
||||
audio_array = audio_array.squeeze()
|
||||
if audio_array.ndim == 1:
|
||||
audio_array = audio_array[np.newaxis, :]
|
||||
|
||||
# 根据格式选择保存方法
|
||||
if format.lower() == "wav":
|
||||
sf.write(output_path, audio_array.T, sample_rate, format="WAV")
|
||||
else:
|
||||
# 使用soundfile保存其他格式
|
||||
# 确保音频数据是单声道
|
||||
if audio_array.shape[0] > 1:
|
||||
audio_array = np.mean(audio_array, axis=0)
|
||||
|
||||
sf.write(output_path, audio_array.T, sample_rate, format=format.upper())
|
||||
|
||||
return output_path
|
||||
|
||||
except Exception as e:
|
||||
raise DefaultServerErrorException(f"保存音频文件失败: {str(e)}")
|
||||
|
||||
|
||||
def convert_audio_to_wav(
|
||||
input_path: str, output_path: Optional[str] = None, target_sr: int = 16000
|
||||
) -> str:
|
||||
"""转换音频文件为WAV格式
|
||||
|
||||
Args:
|
||||
input_path: 输入文件路径
|
||||
output_path: 输出文件路径(可选)
|
||||
target_sr: 目标采样率,默认16000Hz
|
||||
|
||||
Returns:
|
||||
转换后的文件路径
|
||||
|
||||
Raises:
|
||||
AudioProcessingException: 转换失败
|
||||
"""
|
||||
if not output_path:
|
||||
output_path = input_path.rsplit(".", 1)[0] + ".wav"
|
||||
|
||||
try:
|
||||
# 使用librosa加载并重采样
|
||||
audio_data, _ = librosa.load(input_path, sr=target_sr)
|
||||
sf.write(output_path, audio_data, target_sr, format="WAV")
|
||||
return output_path
|
||||
|
||||
except Exception as e:
|
||||
# 尝试使用ffmpeg转换
|
||||
try:
|
||||
subprocess.run(
|
||||
[
|
||||
"ffmpeg",
|
||||
"-f", "s16le",
|
||||
"-ar", str(target_sr),
|
||||
"-ac", "1",
|
||||
"-i", input_path,
|
||||
"-acodec", "pcm_s16le",
|
||||
output_path,
|
||||
"-y",
|
||||
],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
)
|
||||
return output_path
|
||||
except (subprocess.CalledProcessError, FileNotFoundError):
|
||||
raise DefaultServerErrorException(f"音频格式转换失败: {str(e)}")
|
||||
|
||||
|
||||
def normalize_audio_for_asr(audio_path: str, target_sr: int = 16000) -> NormalizedAudio:
|
||||
"""Normalize audio and return explicit timestamp metadata.
|
||||
|
||||
Args:
|
||||
audio_path: 输入音频文件路径
|
||||
target_sr: 目标采样率,默认16000Hz
|
||||
|
||||
Returns:
|
||||
Normalized audio path and timestamp scale metadata.
|
||||
"""
|
||||
try:
|
||||
# 检查文件扩展名
|
||||
file_ext = os.path.splitext(audio_path)[1].lower()
|
||||
|
||||
# 如果已经是WAV格式且采样率正确,直接返回
|
||||
if file_ext == ".wav":
|
||||
# 检查采样率
|
||||
_, sr = librosa.load(audio_path, sr=None)
|
||||
if sr == target_sr:
|
||||
return NormalizedAudio(path=audio_path)
|
||||
|
||||
# 转换为标准WAV格式
|
||||
normalized_path = convert_audio_to_wav(audio_path, target_sr=target_sr)
|
||||
logger.debug(f"音频文件已标准化: {audio_path} -> {normalized_path}")
|
||||
|
||||
timestamp_scale = 1.0
|
||||
if normalized_path != audio_path:
|
||||
decoded_duration = get_audio_duration(normalized_path)
|
||||
timestamp_scale = get_timestamp_scale(audio_path, decoded_duration)
|
||||
|
||||
return NormalizedAudio(path=normalized_path, timestamp_scale=timestamp_scale)
|
||||
|
||||
except Exception as e:
|
||||
raise DefaultServerErrorException(f"音频标准化失败: {str(e)}")
|
||||
|
||||
|
||||
def generate_temp_audio_path(prefix: str = "audio", suffix: str = ".wav") -> str:
|
||||
"""生成临时音频文件路径
|
||||
|
||||
Args:
|
||||
prefix: 文件名前缀
|
||||
suffix: 文件后缀
|
||||
|
||||
Returns:
|
||||
临时文件路径
|
||||
"""
|
||||
import time
|
||||
|
||||
timestamp = int(time.time())
|
||||
filename = f"{prefix}_{timestamp}_{os.getpid()}{suffix}"
|
||||
return os.path.join(settings.TEMP_DIR, filename)
|
||||
|
||||
|
||||
def detect_audio_format_from_bytes(data: bytes) -> str:
|
||||
"""通过文件头(magic bytes)检测音频格式
|
||||
|
||||
Args:
|
||||
data: 音频文件的前几个字节
|
||||
|
||||
Returns:
|
||||
文件后缀(包含点号)
|
||||
"""
|
||||
if len(data) < 12:
|
||||
return ".wav"
|
||||
|
||||
# 检查常见音频格式的文件头
|
||||
if data[:4] == b"RIFF" and data[8:12] == b"WAVE":
|
||||
return ".wav"
|
||||
elif data[:3] == b"ID3" or (data[0:2] == b"\xff\xfb") or (data[0:2] == b"\xff\xfa"):
|
||||
return ".mp3"
|
||||
elif data[:4] == b"fLaC":
|
||||
return ".flac"
|
||||
elif data[:4] == b"OggS":
|
||||
return ".ogg"
|
||||
elif data[4:8] == b"ftyp":
|
||||
# M4A/AAC/MP4/MOV 容器
|
||||
return ".mp4"
|
||||
elif data[:4] == b"\x1aE\xdf\xa3":
|
||||
# WebM/MKV
|
||||
return ".webm"
|
||||
|
||||
# 默认为 wav,librosa 会自动处理
|
||||
return ".wav"
|
||||
|
||||
|
||||
def get_audio_file_suffix(
|
||||
audio_address: Optional[str] = None, audio_data: Optional[bytes] = None
|
||||
) -> str:
|
||||
"""自动识别音频文件后缀
|
||||
|
||||
Args:
|
||||
audio_address: 音频文件URL(可选)
|
||||
audio_data: 音频二进制数据(可选,用于检测文件头)
|
||||
|
||||
Returns:
|
||||
文件后缀(包含点号)
|
||||
"""
|
||||
if audio_address:
|
||||
# 从URL中提取扩展名
|
||||
parsed = urlparse(audio_address)
|
||||
path = unquote(parsed.path)
|
||||
|
||||
# 获取扩展名
|
||||
ext = os.path.splitext(path)[1].lower()
|
||||
if ext and ext in [
|
||||
".wav", ".mp3", ".flac", ".ogg", ".m4a", ".aac", ".pcm", ".webm",
|
||||
".mp4", ".mpeg", ".mpga", ".mov", ".mkv", ".avi",
|
||||
]:
|
||||
return ext
|
||||
|
||||
# 无法识别扩展名,默认为 .wav
|
||||
return ".wav"
|
||||
|
||||
elif audio_data:
|
||||
# 通过文件头检测格式
|
||||
return detect_audio_format_from_bytes(audio_data[:12])
|
||||
|
||||
else:
|
||||
# 默认为 .wav
|
||||
return ".wav"
|
||||
|
|
@ -0,0 +1,64 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
音频过滤工具 - 用于流式ASR的近场/远场声音检测
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
import logging
|
||||
from typing import Tuple, Dict
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def calculate_rms_energy(audio_array: np.ndarray) -> float:
|
||||
"""计算音频RMS能量
|
||||
|
||||
Args:
|
||||
audio_array: float32音频数组,范围-1.0到1.0
|
||||
|
||||
Returns:
|
||||
RMS能量值
|
||||
"""
|
||||
if len(audio_array) == 0:
|
||||
return 0.0
|
||||
return float(np.sqrt(np.mean(audio_array ** 2)))
|
||||
|
||||
|
||||
def is_nearfield_voice(
|
||||
audio_array: np.ndarray,
|
||||
sample_rate: int = 16000, # noqa: ARG001
|
||||
rms_threshold: float = 0.01,
|
||||
enable_filter: bool = True,
|
||||
) -> Tuple[bool, Dict]:
|
||||
"""判断是否为近场有效声音(仅基于RMS能量)
|
||||
|
||||
Args:
|
||||
audio_array: float32音频数组,范围-1.0到1.0
|
||||
sample_rate: 采样率(保留用于兼容性)
|
||||
rms_threshold: RMS能量阈值
|
||||
enable_filter: 是否启用过滤(开关)
|
||||
|
||||
Returns:
|
||||
(is_nearfield, metrics): 是否近场声音 + 检测指标详情
|
||||
"""
|
||||
if not enable_filter:
|
||||
return True, {'enabled': False}
|
||||
|
||||
if len(audio_array) == 0:
|
||||
return False, {'error': 'empty_array'}
|
||||
|
||||
# 计算RMS能量
|
||||
rms_energy = calculate_rms_energy(audio_array)
|
||||
|
||||
# 仅使用RMS能量判断
|
||||
is_nearfield = rms_energy >= rms_threshold
|
||||
|
||||
metrics = {
|
||||
'rms_energy': round(rms_energy, 6),
|
||||
'is_nearfield': is_nearfield,
|
||||
'thresholds': {
|
||||
'rms': rms_threshold,
|
||||
}
|
||||
}
|
||||
|
||||
return is_nearfield, metrics
|
||||
|
|
@ -0,0 +1,439 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
音频分割模块
|
||||
基于 VAD 的智能音频分割,支持长音频分段识别
|
||||
"""
|
||||
|
||||
import logging
|
||||
import numpy as np
|
||||
import librosa
|
||||
import soundfile as sf
|
||||
import tempfile
|
||||
import os
|
||||
import time
|
||||
from typing import List, Tuple, Optional
|
||||
from dataclasses import dataclass
|
||||
|
||||
from ..core.config import settings
|
||||
from ..core.exceptions import DefaultServerErrorException
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
|
||||
def _log_audio_split_timing(stage: str, duration_ms: float, **extra) -> None:
|
||||
payload = {
|
||||
"event": "audio_split_timing",
|
||||
"stage": stage,
|
||||
"duration_ms": round(duration_ms, 2),
|
||||
}
|
||||
payload.update(extra)
|
||||
logger.info("音频分割阶段耗时", extra=payload)
|
||||
|
||||
|
||||
@dataclass
|
||||
class AudioSegment:
|
||||
"""音频片段信息"""
|
||||
|
||||
start_ms: int # 开始时间(毫秒)
|
||||
end_ms: int # 结束时间(毫秒)
|
||||
audio_data: Optional[np.ndarray] = None # 音频数据
|
||||
temp_file: Optional[str] = None # 临时文件路径
|
||||
speaker_id: Optional[str] = None # 说话人ID(多说话人模式)
|
||||
|
||||
@property
|
||||
def start_sec(self) -> float:
|
||||
"""开始时间(秒)"""
|
||||
return self.start_ms / 1000.0
|
||||
|
||||
@property
|
||||
def end_sec(self) -> float:
|
||||
"""结束时间(秒)"""
|
||||
return self.end_ms / 1000.0
|
||||
|
||||
@property
|
||||
def duration_ms(self) -> int:
|
||||
"""时长(毫秒)"""
|
||||
return self.end_ms - self.start_ms
|
||||
|
||||
@property
|
||||
def duration_sec(self) -> float:
|
||||
"""时长(秒)"""
|
||||
return self.duration_ms / 1000.0
|
||||
|
||||
|
||||
class AudioSplitter:
|
||||
"""音频分割器
|
||||
|
||||
使用 VAD 模型检测语音边界,智能分割长音频
|
||||
"""
|
||||
|
||||
# 默认配置
|
||||
DEFAULT_MIN_SEGMENT_SEC = 1.0 # 每段最小时长(秒)
|
||||
DEFAULT_SAMPLE_RATE = 16000 # 默认采样率
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
min_segment_sec: float = DEFAULT_MIN_SEGMENT_SEC,
|
||||
device: str = "auto",
|
||||
):
|
||||
"""初始化音频分割器
|
||||
|
||||
Args:
|
||||
min_segment_sec: 每段最小时长(秒)
|
||||
device: 计算设备("cuda", "cpu", "auto")
|
||||
"""
|
||||
split_trigger_sec = settings.MAX_SEGMENT_SEC
|
||||
|
||||
self.split_trigger_sec = split_trigger_sec
|
||||
self.min_segment_sec = min_segment_sec
|
||||
self.split_trigger_ms = int(split_trigger_sec * 1000)
|
||||
self.min_segment_ms = int(min_segment_sec * 1000)
|
||||
self.device = device
|
||||
|
||||
def get_vad_segments(
|
||||
self, audio_path: str
|
||||
) -> List[Tuple[int, int]]:
|
||||
"""使用 VAD 模型获取语音段
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
|
||||
Returns:
|
||||
语音段列表,每个元素为 (start_ms, end_ms)
|
||||
"""
|
||||
try:
|
||||
from ..services.asr.engines import get_global_vad_model
|
||||
|
||||
logger.info("开始 VAD 语音段检测...")
|
||||
vad_model = get_global_vad_model(self.device)
|
||||
if vad_model is None:
|
||||
raise DefaultServerErrorException("VAD 模型未加载")
|
||||
|
||||
# 调用 VAD 模型
|
||||
vad_started = time.perf_counter()
|
||||
result = vad_model.generate(input=audio_path, cache={})
|
||||
vad_duration_ms = (time.perf_counter() - vad_started) * 1000
|
||||
|
||||
if not result or len(result) == 0:
|
||||
_log_audio_split_timing(
|
||||
"vad_generate",
|
||||
vad_duration_ms,
|
||||
audio_path=audio_path,
|
||||
vad_segment_count=0,
|
||||
)
|
||||
logger.warning("VAD 未检测到语音段")
|
||||
return []
|
||||
|
||||
# 解析 VAD 结果
|
||||
# FunASR VAD 返回格式: [[start_ms, end_ms], [start_ms, end_ms], ...]
|
||||
vad_segments = result[0].get("value", [])
|
||||
|
||||
if not vad_segments:
|
||||
_log_audio_split_timing(
|
||||
"vad_generate",
|
||||
vad_duration_ms,
|
||||
audio_path=audio_path,
|
||||
vad_segment_count=0,
|
||||
)
|
||||
logger.warning("VAD 结果为空")
|
||||
return []
|
||||
|
||||
_log_audio_split_timing(
|
||||
"vad_generate",
|
||||
vad_duration_ms,
|
||||
audio_path=audio_path,
|
||||
vad_segment_count=len(vad_segments),
|
||||
)
|
||||
logger.info(f"VAD 检测到 {len(vad_segments)} 个语音段")
|
||||
logger.info(
|
||||
"开始按 VAD 边界重分段 "
|
||||
f"(split_trigger={self.split_trigger_sec}s, min_segment={self.min_segment_sec}s)..."
|
||||
)
|
||||
return [(int(seg[0]), int(seg[1])) for seg in vad_segments]
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"VAD 检测失败: {e}")
|
||||
raise DefaultServerErrorException(f"VAD 检测失败: {str(e)}")
|
||||
|
||||
def merge_segments_greedy(
|
||||
self, vad_segments: List[Tuple[int, int]], total_duration_ms: int
|
||||
) -> List[Tuple[int, int]]:
|
||||
"""按 VAD 结果重分段
|
||||
|
||||
策略:
|
||||
1. 默认保留 VAD 原始边界,避免将整段连续语音合并成超长片段
|
||||
2. 仅对短片段(< min_segment_ms)做邻段合并
|
||||
3. 对重叠片段进行边界修正,避免重复音频
|
||||
|
||||
Args:
|
||||
vad_segments: VAD 检测到的语音段列表 [(start_ms, end_ms), ...]
|
||||
total_duration_ms: 音频总时长(毫秒)
|
||||
|
||||
Returns:
|
||||
合并后的段列表 [(start_ms, end_ms), ...]
|
||||
"""
|
||||
if not vad_segments:
|
||||
# 没有 VAD 段,返回整个音频(按最大时长切分)
|
||||
return self._split_by_fixed_duration(total_duration_ms)
|
||||
|
||||
# 按时间排序并修正边界(防止越界、重叠)
|
||||
sorted_vad = sorted(vad_segments, key=lambda x: x[0])
|
||||
normalized: List[Tuple[int, int]] = []
|
||||
for raw_start, raw_end in sorted_vad:
|
||||
start_ms = max(0, int(raw_start))
|
||||
end_ms = min(total_duration_ms, int(raw_end))
|
||||
if end_ms <= start_ms:
|
||||
continue
|
||||
|
||||
if not normalized:
|
||||
normalized.append((start_ms, end_ms))
|
||||
continue
|
||||
|
||||
last_end = normalized[-1][1]
|
||||
# 有重叠时,优先保持边界,避免与上一段重复采样
|
||||
if start_ms < last_end:
|
||||
start_ms = last_end
|
||||
|
||||
if end_ms > start_ms:
|
||||
normalized.append((start_ms, end_ms))
|
||||
|
||||
if not normalized:
|
||||
return self._split_by_fixed_duration(total_duration_ms)
|
||||
|
||||
merged = list(normalized)
|
||||
|
||||
# 只处理短片段:与相邻片段合并(不基于静音间隙)
|
||||
idx = 0
|
||||
while idx < len(merged):
|
||||
start_ms, end_ms = merged[idx]
|
||||
duration = end_ms - start_ms
|
||||
|
||||
if duration >= self.min_segment_ms or len(merged) == 1:
|
||||
idx += 1
|
||||
continue
|
||||
|
||||
if idx == 0:
|
||||
# 首段过短:并入后段
|
||||
next_end = merged[idx + 1][1]
|
||||
merged[idx + 1] = (start_ms, next_end)
|
||||
del merged[idx]
|
||||
continue
|
||||
|
||||
if idx == len(merged) - 1:
|
||||
# 尾段过短:并入前段
|
||||
prev_start, _ = merged[idx - 1]
|
||||
merged[idx - 1] = (prev_start, end_ms)
|
||||
del merged[idx]
|
||||
idx = max(0, idx - 1)
|
||||
continue
|
||||
|
||||
# 中间短段:优先并入时长更短的一侧,避免单段过长
|
||||
prev_start = merged[idx - 1][0]
|
||||
next_end = merged[idx + 1][1]
|
||||
merged_with_prev_duration = end_ms - prev_start
|
||||
merged_with_next_duration = next_end - start_ms
|
||||
|
||||
if merged_with_prev_duration <= merged_with_next_duration:
|
||||
merged[idx - 1] = (prev_start, end_ms)
|
||||
del merged[idx]
|
||||
idx = max(0, idx - 1)
|
||||
else:
|
||||
merged[idx + 1] = (start_ms, next_end)
|
||||
del merged[idx]
|
||||
|
||||
return merged
|
||||
|
||||
def _split_by_fixed_duration(self, total_duration_ms: int) -> List[Tuple[int, int]]:
|
||||
"""按固定时长切分(无 VAD 时的 fallback)
|
||||
|
||||
Args:
|
||||
total_duration_ms: 音频总时长(毫秒)
|
||||
|
||||
Returns:
|
||||
切分后的段列表
|
||||
"""
|
||||
segments = []
|
||||
current = 0
|
||||
while current < total_duration_ms:
|
||||
end = min(current + self.split_trigger_ms, total_duration_ms)
|
||||
if end - current >= self.min_segment_ms:
|
||||
segments.append((current, end))
|
||||
current = end
|
||||
return segments
|
||||
|
||||
def split_audio_file(
|
||||
self,
|
||||
audio_path: str,
|
||||
output_dir: Optional[str] = None,
|
||||
) -> List[AudioSegment]:
|
||||
"""分割音频文件
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
output_dir: 输出目录(可选,默认使用临时目录)
|
||||
|
||||
Returns:
|
||||
音频片段列表
|
||||
"""
|
||||
try:
|
||||
total_started = time.perf_counter()
|
||||
# 加载音频
|
||||
load_started = time.perf_counter()
|
||||
audio_data, sr = librosa.load(audio_path, sr=self.DEFAULT_SAMPLE_RATE)
|
||||
load_audio_ms = (time.perf_counter() - load_started) * 1000
|
||||
total_duration_ms = int(len(audio_data) / sr * 1000)
|
||||
audio_duration_sec = total_duration_ms / 1000
|
||||
|
||||
logger.info(f"音频总时长: {audio_duration_sec:.2f}秒")
|
||||
_log_audio_split_timing(
|
||||
"load_audio",
|
||||
load_audio_ms,
|
||||
audio_path=audio_path,
|
||||
audio_duration_sec=round(audio_duration_sec, 2),
|
||||
sample_rate=sr,
|
||||
)
|
||||
|
||||
# 检查是否需要分割
|
||||
if total_duration_ms <= self.split_trigger_ms:
|
||||
logger.info("音频时长在限制内,无需分割")
|
||||
total_duration_ms_for_log = (time.perf_counter() - total_started) * 1000
|
||||
_log_audio_split_timing(
|
||||
"split_total",
|
||||
total_duration_ms_for_log,
|
||||
audio_path=audio_path,
|
||||
audio_duration_sec=round(audio_duration_sec, 2),
|
||||
output_segment_count=1,
|
||||
need_split=False,
|
||||
load_audio_ms=round(load_audio_ms, 2),
|
||||
vad_ms=0,
|
||||
merge_ms=0,
|
||||
write_segments_ms=0,
|
||||
)
|
||||
return [
|
||||
AudioSegment(
|
||||
start_ms=0,
|
||||
end_ms=total_duration_ms,
|
||||
audio_data=audio_data,
|
||||
temp_file=audio_path,
|
||||
)
|
||||
]
|
||||
|
||||
# 获取 VAD 段
|
||||
vad_started = time.perf_counter()
|
||||
vad_segments = self.get_vad_segments(audio_path)
|
||||
vad_ms = (time.perf_counter() - vad_started) * 1000
|
||||
|
||||
# 贪婪合并
|
||||
merge_started = time.perf_counter()
|
||||
merged_segments = self.merge_segments_greedy(vad_segments, total_duration_ms)
|
||||
merge_ms = (time.perf_counter() - merge_started) * 1000
|
||||
logger.info(f"重分段完成: 原始VAD={len(vad_segments)}, 输出={len(merged_segments)}")
|
||||
_log_audio_split_timing(
|
||||
"merge_segments",
|
||||
merge_ms,
|
||||
audio_path=audio_path,
|
||||
vad_segment_count=len(vad_segments),
|
||||
output_segment_count=len(merged_segments),
|
||||
audio_duration_sec=round(audio_duration_sec, 2),
|
||||
)
|
||||
|
||||
# 切分音频并保存到临时文件
|
||||
logger.info("开始切分音频并保存临时文件...")
|
||||
output_dir = output_dir or settings.TEMP_DIR
|
||||
os.makedirs(output_dir, exist_ok=True)
|
||||
|
||||
audio_segments = []
|
||||
write_started = time.perf_counter()
|
||||
for idx, (start_ms, end_ms) in enumerate(merged_segments):
|
||||
# 计算采样点范围
|
||||
start_sample = int(start_ms / 1000 * sr)
|
||||
end_sample = int(end_ms / 1000 * sr)
|
||||
|
||||
# 提取音频片段
|
||||
segment_data = audio_data[start_sample:end_sample]
|
||||
|
||||
# 保存到临时文件
|
||||
temp_file = tempfile.NamedTemporaryFile(
|
||||
delete=False,
|
||||
suffix=".wav",
|
||||
dir=output_dir,
|
||||
prefix=f"segment_{idx:03d}_",
|
||||
)
|
||||
temp_path = temp_file.name
|
||||
temp_file.close()
|
||||
|
||||
sf.write(temp_path, segment_data, sr)
|
||||
|
||||
segment = AudioSegment(
|
||||
start_ms=start_ms,
|
||||
end_ms=end_ms,
|
||||
audio_data=segment_data,
|
||||
temp_file=temp_path,
|
||||
)
|
||||
audio_segments.append(segment)
|
||||
|
||||
logger.debug(
|
||||
f"分段 {idx + 1}/{len(merged_segments)}: "
|
||||
f"{start_ms / 1000:.2f}s - {end_ms / 1000:.2f}s "
|
||||
f"(时长: {segment.duration_sec:.2f}s)"
|
||||
)
|
||||
|
||||
write_segments_ms = (time.perf_counter() - write_started) * 1000
|
||||
logger.info(f"音频切分完成,共 {len(audio_segments)} 个分段")
|
||||
_log_audio_split_timing(
|
||||
"write_segments",
|
||||
write_segments_ms,
|
||||
audio_path=audio_path,
|
||||
output_dir=output_dir,
|
||||
output_segment_count=len(audio_segments),
|
||||
audio_duration_sec=round(audio_duration_sec, 2),
|
||||
)
|
||||
total_ms = (time.perf_counter() - total_started) * 1000
|
||||
_log_audio_split_timing(
|
||||
"split_total",
|
||||
total_ms,
|
||||
audio_path=audio_path,
|
||||
audio_duration_sec=round(audio_duration_sec, 2),
|
||||
output_segment_count=len(audio_segments),
|
||||
need_split=True,
|
||||
load_audio_ms=round(load_audio_ms, 2),
|
||||
vad_ms=round(vad_ms, 2),
|
||||
merge_ms=round(merge_ms, 2),
|
||||
write_segments_ms=round(write_segments_ms, 2),
|
||||
)
|
||||
return audio_segments
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"音频分割失败: {e}")
|
||||
raise DefaultServerErrorException(f"音频分割失败: {str(e)}")
|
||||
|
||||
@staticmethod
|
||||
def cleanup_segments(segments: List[AudioSegment]) -> None:
|
||||
"""清理临时文件
|
||||
|
||||
Args:
|
||||
segments: 音频片段列表
|
||||
"""
|
||||
for segment in segments:
|
||||
if segment.temp_file and os.path.exists(segment.temp_file):
|
||||
try:
|
||||
os.remove(segment.temp_file)
|
||||
except Exception as e:
|
||||
logger.warning(f"清理临时文件失败: {segment.temp_file}, {e}")
|
||||
|
||||
|
||||
def split_long_audio(
|
||||
audio_path: str,
|
||||
device: str = "auto",
|
||||
) -> List[AudioSegment]:
|
||||
"""分割长音频的便捷函数
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
device: 计算设备
|
||||
|
||||
Returns:
|
||||
音频片段列表
|
||||
"""
|
||||
splitter = AudioSplitter(device=device)
|
||||
return splitter.split_audio_file(audio_path)
|
||||
|
|
@ -0,0 +1,28 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""Structured startup events for the optional terminal dashboard."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
from typing import Any
|
||||
|
||||
_BOOT_EVENT_PREFIX = "__FUNASR_BOOT__"
|
||||
|
||||
|
||||
def boot_events_enabled() -> bool:
|
||||
return (os.getenv("FUNASR_BOOT_EVENTS") or "").strip() == "1"
|
||||
|
||||
|
||||
def emit_boot_event(event: str, **payload: Any) -> None:
|
||||
if not boot_events_enabled():
|
||||
return
|
||||
|
||||
data = {"event": event, **payload}
|
||||
sys.stdout.write(_BOOT_EVENT_PREFIX + json.dumps(data, ensure_ascii=False) + "\n")
|
||||
sys.stdout.flush()
|
||||
|
||||
|
||||
def get_boot_event_prefix() -> str:
|
||||
return _BOOT_EVENT_PREFIX
|
||||
|
|
@ -0,0 +1,90 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
通用工具函数
|
||||
包含任务ID生成、参数验证等通用功能
|
||||
"""
|
||||
|
||||
import uuid
|
||||
import hashlib
|
||||
import time
|
||||
import re
|
||||
from typing import Optional
|
||||
|
||||
|
||||
def generate_task_id(prefix: str = "") -> str:
|
||||
"""生成唯一的任务ID
|
||||
|
||||
Args:
|
||||
prefix: 任务ID前缀
|
||||
|
||||
Returns:
|
||||
生成的任务ID
|
||||
"""
|
||||
timestamp = str(int(time.time() * 1000))
|
||||
random_id = str(uuid.uuid4()).replace("-", "")
|
||||
combined = timestamp + random_id
|
||||
|
||||
# 使用MD5哈希生成32位字符串
|
||||
task_id = hashlib.md5(combined.encode()).hexdigest()
|
||||
|
||||
if prefix:
|
||||
return f"{prefix}_{task_id}"
|
||||
return task_id
|
||||
|
||||
|
||||
def validate_text_input(text: str, max_length: int = 10000) -> tuple[bool, str]:
|
||||
"""验证输入文本
|
||||
|
||||
Args:
|
||||
text: 待验证的文本
|
||||
max_length: 最大长度限制
|
||||
|
||||
Returns:
|
||||
(is_valid, message): 验证结果和消息
|
||||
"""
|
||||
if not text or not text.strip():
|
||||
return False, "文本内容不能为空"
|
||||
|
||||
text = text.strip()
|
||||
|
||||
if len(text) > max_length:
|
||||
return False, f"文本长度超过限制,最大支持{max_length}个字符"
|
||||
|
||||
# 检查是否包含有效字符
|
||||
if not re.search(r"[\u4e00-\u9fff\w\s]", text):
|
||||
return False, "文本内容无效,请输入有效的中文、英文或数字"
|
||||
|
||||
return True, "验证通过"
|
||||
|
||||
|
||||
def parse_language_code(lang_code: Optional[str]) -> str:
|
||||
"""解析语言代码
|
||||
|
||||
Args:
|
||||
lang_code: 语言代码(如 zh, zh-cn, en, ja等)
|
||||
|
||||
Returns:
|
||||
标准化的语言代码
|
||||
"""
|
||||
if not lang_code:
|
||||
return "zh" # 默认中文
|
||||
|
||||
lang_code = lang_code.lower().strip()
|
||||
|
||||
# 语言代码映射
|
||||
lang_mapping = {
|
||||
"zh": "zh",
|
||||
"zh-cn": "zh",
|
||||
"zh-tw": "zh",
|
||||
"zh-hk": "zh",
|
||||
"en": "en",
|
||||
"en-us": "en",
|
||||
"en-gb": "en",
|
||||
"ja": "jp",
|
||||
"jp": "jp",
|
||||
"ko": "kr",
|
||||
"kr": "kr",
|
||||
"yue": "yue", # 粤语
|
||||
}
|
||||
|
||||
return lang_mapping.get(lang_code, "zh")
|
||||
|
|
@ -0,0 +1,296 @@
|
|||
#!/usr/bin/env python3
|
||||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
模型预下载脚本
|
||||
统一从 ModelScope 预下载所有运行所需模型
|
||||
"""
|
||||
|
||||
import argparse
|
||||
import json
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
from modelscope.hub.snapshot_download import snapshot_download as ms_snapshot_download
|
||||
from app.core.config import settings
|
||||
from app.services.asr.model_capabilities import (
|
||||
get_all_qwen_modelscope_assets,
|
||||
get_camplusplus_replacement_paths,
|
||||
get_download_modelscope_assets,
|
||||
)
|
||||
|
||||
|
||||
def _get_qwen_modelscope_assets():
|
||||
"""Return all declared ModelScope Qwen assets for offline deployment."""
|
||||
assets = get_all_qwen_modelscope_assets()
|
||||
if not assets:
|
||||
print("当前部署计划未启用 Qwen3-ASR,跳过 Qwen 模型下载")
|
||||
return []
|
||||
|
||||
print("离线部署模式:下载全部已声明 Qwen 模型(含 forced aligner)")
|
||||
return assets
|
||||
|
||||
def _get_cache_path(model_id: str, source: str = "modelscope") -> Path:
|
||||
"""获取模型缓存路径"""
|
||||
_ = source
|
||||
return Path(settings.MODELSCOPE_PATH) / model_id
|
||||
|
||||
|
||||
def check_model_exists(model_id: str, source: str = "modelscope") -> tuple[bool, str]:
|
||||
"""检查模型是否已存在于本地缓存"""
|
||||
try:
|
||||
model_path = _get_cache_path(model_id, source)
|
||||
|
||||
if model_path.exists() and model_path.is_dir():
|
||||
if any(model_path.iterdir()):
|
||||
return True, str(model_path)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
return False, ""
|
||||
|
||||
|
||||
def check_all_models() -> list[tuple[str, str, str, Optional[str]]]:
|
||||
"""检查所有模型是否存在
|
||||
|
||||
Returns:
|
||||
缺失的模型列表,每个元素为 (model_id, description, source, revision)
|
||||
"""
|
||||
missing = []
|
||||
ms_assets = get_download_modelscope_assets()
|
||||
qwen_assets = _get_qwen_modelscope_assets()
|
||||
|
||||
for asset in ms_assets:
|
||||
exists, _ = check_model_exists(asset.model_id, source="modelscope")
|
||||
if not exists:
|
||||
missing.append((asset.model_id, asset.description, "modelscope", asset.revision))
|
||||
|
||||
for asset in qwen_assets:
|
||||
exists, _ = check_model_exists(asset.model_id, source="modelscope")
|
||||
if not exists:
|
||||
missing.append((asset.model_id, asset.description, "modelscope", asset.revision))
|
||||
|
||||
return missing
|
||||
|
||||
|
||||
def fix_camplusplus_config() -> bool:
|
||||
"""修复 CAM++ 配置文件,将模型ID替换为本地路径(用于离线环境)
|
||||
|
||||
修复 issue #15: 离线环境下 CAM++ 模型会尝试从 modelscope.cn 获取依赖模型配置
|
||||
|
||||
Returns:
|
||||
是否修复成功
|
||||
"""
|
||||
try:
|
||||
cache_dir = Path(settings.MODELSCOPE_PATH)
|
||||
config_file = cache_dir / "iic/speech_campplus_speaker-diarization_common/configuration.json"
|
||||
|
||||
if not config_file.exists():
|
||||
return False
|
||||
|
||||
# 读取配置文件
|
||||
with open(config_file, 'r', encoding='utf-8') as f:
|
||||
config = json.load(f)
|
||||
|
||||
# 需要替换的模型ID -> 本地路径映射
|
||||
replacements = get_camplusplus_replacement_paths(str(cache_dir))
|
||||
|
||||
# 检查是否需要修改
|
||||
modified = False
|
||||
if "model" in config:
|
||||
for key in ["speaker_model", "change_locator", "vad_model"]:
|
||||
if key in config["model"]:
|
||||
old_value = config["model"][key]
|
||||
if old_value in replacements:
|
||||
new_value = replacements[old_value]
|
||||
# 检查本地路径是否存在
|
||||
if Path(new_value).exists():
|
||||
config["model"][key] = new_value
|
||||
modified = True
|
||||
|
||||
# 写回配置文件
|
||||
if modified:
|
||||
with open(config_file, 'w', encoding='utf-8') as f:
|
||||
json.dump(config, f, indent=4, ensure_ascii=False)
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
except Exception as e:
|
||||
print(f"⚠️ 修复 CAM++ 配置文件失败: {e}")
|
||||
return False
|
||||
|
||||
|
||||
def download_models(
|
||||
auto_mode: bool = False,
|
||||
export_dir: Optional[str] = None,
|
||||
) -> bool:
|
||||
"""下载所有需要的模型
|
||||
|
||||
Args:
|
||||
auto_mode: 如果为True,表示自动模式(从start.py调用),会简化输出
|
||||
export_dir: 如果指定,将下载的模型导出到该目录(用于离线部署)
|
||||
|
||||
Returns:
|
||||
是否全部下载成功
|
||||
"""
|
||||
import shutil
|
||||
|
||||
# 检查缺失的模型
|
||||
missing = check_all_models()
|
||||
ms_assets = get_download_modelscope_assets()
|
||||
qwen_assets = _get_qwen_modelscope_assets()
|
||||
|
||||
export_path = Path(export_dir) if export_dir else None
|
||||
|
||||
if not missing:
|
||||
if not auto_mode:
|
||||
print("✅ 所有模型已存在,无需下载")
|
||||
if not export_path:
|
||||
return True
|
||||
|
||||
ms_cache_dir = Path(settings.MODELSCOPE_CACHE)
|
||||
if auto_mode:
|
||||
print(f"📦 检测到 {len(missing)} 个模型需要下载...")
|
||||
else:
|
||||
print("=" * 60)
|
||||
print("Qwen3-ASR 模型预下载")
|
||||
print("=" * 60)
|
||||
print(f"ModelScope 缓存: {ms_cache_dir}")
|
||||
print(f"待下载模型: {len(missing)} 个")
|
||||
print("=" * 60)
|
||||
|
||||
failed = []
|
||||
downloaded = []
|
||||
|
||||
# 下载 ModelScope 模型 (Paraformer)
|
||||
ms_missing = [(mid, desc, rev) for mid, desc, src, rev in missing if src == "modelscope"]
|
||||
if ms_missing:
|
||||
if not auto_mode:
|
||||
print("\n📦 开始下载 ModelScope 模型 (Paraformer)...")
|
||||
print("-" * 60)
|
||||
|
||||
for i, (model_id, desc, revision) in enumerate(ms_missing, 1):
|
||||
if not auto_mode:
|
||||
print(f"\n[{i}/{len(ms_missing)}] {desc}")
|
||||
print(f" 模型ID: {model_id}")
|
||||
if revision:
|
||||
print(f" 版本: {revision}")
|
||||
print(f" 📥 开始下载...", end="")
|
||||
|
||||
try:
|
||||
local_dir = _get_cache_path(model_id, "modelscope")
|
||||
local_dir.parent.mkdir(parents=True, exist_ok=True)
|
||||
# 传递版本参数,如果指定了版本
|
||||
if revision:
|
||||
path = ms_snapshot_download(
|
||||
model_id,
|
||||
revision=revision,
|
||||
cache_dir=str(ms_cache_dir),
|
||||
local_dir=str(local_dir),
|
||||
)
|
||||
else:
|
||||
path = ms_snapshot_download(
|
||||
model_id,
|
||||
cache_dir=str(ms_cache_dir),
|
||||
local_dir=str(local_dir),
|
||||
)
|
||||
if not auto_mode:
|
||||
print(f" ✅ 完成: {path}")
|
||||
downloaded.append((model_id, "modelscope", path))
|
||||
except Exception as e:
|
||||
if not auto_mode:
|
||||
print(f" ❌ 失败: {e}")
|
||||
failed.append((model_id, str(e)))
|
||||
|
||||
# 修复 CAM++ 配置文件(用于离线环境)
|
||||
if not auto_mode:
|
||||
print("\n🔧 修复 CAM++ 配置文件...")
|
||||
if fix_camplusplus_config():
|
||||
if not auto_mode:
|
||||
print(" ✅ CAM++ 配置已修复(离线环境可用)")
|
||||
else:
|
||||
if not auto_mode:
|
||||
print(" ℹ️ 无需修复或配置文件不存在")
|
||||
|
||||
# 导出模式:复制模型到扁平化的 models/ 根目录
|
||||
if export_path and not failed:
|
||||
if not auto_mode:
|
||||
print(f"\n📦 导出模型到: {export_path}")
|
||||
|
||||
# 收集所有需要导出的模型
|
||||
all_models = []
|
||||
for asset in ms_assets:
|
||||
all_models.append((asset.model_id, "modelscope"))
|
||||
for asset in qwen_assets:
|
||||
all_models.append((asset.model_id, "modelscope"))
|
||||
|
||||
exported = 0
|
||||
for model_entry in all_models:
|
||||
if len(model_entry) == 3:
|
||||
model_id, source, actual_model_id = model_entry
|
||||
else:
|
||||
model_id, source = model_entry
|
||||
actual_model_id = model_id
|
||||
cache_path = _get_cache_path(actual_model_id, source)
|
||||
if cache_path.exists():
|
||||
rel_path = cache_path.relative_to(Path(settings.MODELSCOPE_PATH))
|
||||
target_dir = export_path / rel_path
|
||||
|
||||
target_dir.parent.mkdir(parents=True, exist_ok=True)
|
||||
if not auto_mode:
|
||||
print(f" 📂 {model_id}", end="")
|
||||
try:
|
||||
shutil.copytree(cache_path, target_dir, dirs_exist_ok=True)
|
||||
exported += 1
|
||||
if not auto_mode:
|
||||
print(" ✅")
|
||||
except Exception as e:
|
||||
if not auto_mode:
|
||||
print(f" ❌ {e}")
|
||||
|
||||
if not auto_mode:
|
||||
print(f"\n✅ 已导出 {exported} 个模型到 models/")
|
||||
|
||||
if not auto_mode:
|
||||
print("\n" + "=" * 60)
|
||||
print("📊 下载统计:")
|
||||
print(f" ✅ 已下载: {len(downloaded)} 个")
|
||||
print(f" ❌ 失败: {len(failed)} 个")
|
||||
print("=" * 60)
|
||||
|
||||
if failed:
|
||||
print(f"\n失败的模型:")
|
||||
for model_id, err in failed:
|
||||
print(f" - {model_id}: {err}")
|
||||
return False
|
||||
else:
|
||||
print("\n✅ 所有模型准备就绪!")
|
||||
print("=" * 60)
|
||||
|
||||
return len(failed) == 0
|
||||
|
||||
|
||||
def main() -> int:
|
||||
"""CLI entrypoint for model download and export."""
|
||||
parser = argparse.ArgumentParser(description="Download or export Qwen3-ASR models")
|
||||
parser.add_argument(
|
||||
"--export-dir",
|
||||
default=None,
|
||||
help="Optional export directory for offline deployment packaging",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--auto-mode",
|
||||
action="store_true",
|
||||
help="Reduce output for startup/bootstrap usage",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
success = download_models(
|
||||
auto_mode=args.auto_mode,
|
||||
export_dir=args.export_dir,
|
||||
)
|
||||
return 0 if success else 1
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
|
|
@ -0,0 +1,520 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
模型预加载工具
|
||||
在应用启动时预加载所有需要的模型,避免首次请求时的延迟
|
||||
"""
|
||||
|
||||
import logging
|
||||
import os
|
||||
import sys
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
try:
|
||||
from rich.console import Console
|
||||
except ImportError:
|
||||
Console = None
|
||||
|
||||
from .boot_events import emit_boot_event
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_PRELOAD_QUIET_LOGGERS = (
|
||||
"root",
|
||||
"vllm",
|
||||
"app.infrastructure.model_utils",
|
||||
"app.services.asr.engines.global_models",
|
||||
"app.services.asr.qwen3_engine",
|
||||
"app.utils.speaker_diarizer",
|
||||
)
|
||||
|
||||
|
||||
class _ProgressNoiseFilter(logging.Filter):
|
||||
def filter(self, record: logging.LogRecord) -> bool:
|
||||
if record.levelno >= logging.WARNING:
|
||||
return True
|
||||
return not any(
|
||||
record.name == prefix or record.name.startswith(f"{prefix}.")
|
||||
for prefix in _PRELOAD_QUIET_LOGGERS
|
||||
)
|
||||
|
||||
|
||||
class _StartupProgress:
|
||||
def __init__(self, title: str, total: int):
|
||||
self._title = title
|
||||
self._total = max(total, 1)
|
||||
self._enabled = bool(
|
||||
Console is not None
|
||||
and sys.stderr.isatty()
|
||||
)
|
||||
self._console: Any = None
|
||||
self._filter = _ProgressNoiseFilter()
|
||||
self._handlers: list[logging.Handler] = []
|
||||
self._current_step = 1
|
||||
self._last_description: str | None = None
|
||||
|
||||
def __enter__(self) -> "_StartupProgress":
|
||||
emit_boot_event(
|
||||
"phase_start",
|
||||
phase=self._title,
|
||||
total=self._total,
|
||||
message=self._title,
|
||||
)
|
||||
if not self._enabled or Console is None:
|
||||
return self
|
||||
self._console = Console(stderr=True)
|
||||
root_logger = logging.getLogger()
|
||||
self._handlers = list(root_logger.handlers)
|
||||
for handler in self._handlers:
|
||||
handler.addFilter(self._filter)
|
||||
return self
|
||||
|
||||
def __exit__(self, exc_type, exc, tb) -> None:
|
||||
for handler in self._handlers:
|
||||
handler.removeFilter(self._filter)
|
||||
self._handlers.clear()
|
||||
|
||||
def update(self, description: str) -> None:
|
||||
emit_boot_event(
|
||||
"step_start",
|
||||
phase=self._title,
|
||||
step=self._current_step,
|
||||
total=self._total,
|
||||
message=description,
|
||||
)
|
||||
if self._console is None:
|
||||
return
|
||||
if description == self._last_description:
|
||||
return
|
||||
self._last_description = description
|
||||
self._console.print(
|
||||
f"[bold cyan][startup {self._current_step}/{self._total}][/bold cyan] {description}",
|
||||
highlight=False,
|
||||
)
|
||||
|
||||
def advance(self, description: str) -> None:
|
||||
emit_boot_event(
|
||||
"step_done",
|
||||
phase=self._title,
|
||||
step=self._current_step,
|
||||
total=self._total,
|
||||
message=description,
|
||||
)
|
||||
self._last_description = description
|
||||
self._current_step = min(self._current_step + 1, self._total)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ModelIntegritySpec:
|
||||
description: str
|
||||
path: Path
|
||||
required_patterns: tuple[str, ...]
|
||||
alternative_required_patterns: tuple[tuple[str, ...], ...] = ()
|
||||
min_total_size_bytes: int = 0
|
||||
|
||||
|
||||
def _format_bytes(num_bytes: int) -> str:
|
||||
value = float(num_bytes)
|
||||
units = ["B", "KB", "MB", "GB", "TB"]
|
||||
for unit in units:
|
||||
if value < 1024.0 or unit == units[-1]:
|
||||
return f"{value:.1f}{unit}"
|
||||
value /= 1024.0
|
||||
return f"{num_bytes}B"
|
||||
|
||||
|
||||
def _find_pattern_matches(root: Path, pattern: str) -> list[Path]:
|
||||
return [path for path in root.glob(pattern) if path.is_file()]
|
||||
|
||||
|
||||
def _find_missing_patterns(root: Path, patterns: tuple[str, ...]) -> list[str]:
|
||||
return [pattern for pattern in patterns if not _find_pattern_matches(root, pattern)]
|
||||
|
||||
|
||||
def _format_alternative_patterns(pattern_groups: tuple[tuple[str, ...], ...]) -> str:
|
||||
return " OR ".join(" + ".join(group) for group in pattern_groups)
|
||||
|
||||
|
||||
def _check_model_integrity_spec(spec: ModelIntegritySpec) -> dict[str, Any]:
|
||||
if not spec.path.exists() or not spec.path.is_dir():
|
||||
return {
|
||||
"description": spec.description,
|
||||
"path": str(spec.path),
|
||||
"ok": False,
|
||||
"missing_patterns": [
|
||||
*spec.required_patterns,
|
||||
*(
|
||||
[_format_alternative_patterns(spec.alternative_required_patterns)]
|
||||
if spec.alternative_required_patterns
|
||||
else []
|
||||
),
|
||||
],
|
||||
"total_size_bytes": 0,
|
||||
"reason": "directory_missing",
|
||||
}
|
||||
|
||||
files = [path for path in spec.path.rglob("*") if path.is_file()]
|
||||
total_size_bytes = sum(path.stat().st_size for path in files)
|
||||
|
||||
missing_patterns = _find_missing_patterns(spec.path, spec.required_patterns)
|
||||
if not missing_patterns and spec.alternative_required_patterns:
|
||||
alternative_missing_patterns = [
|
||||
_find_missing_patterns(spec.path, group)
|
||||
for group in spec.alternative_required_patterns
|
||||
]
|
||||
if all(alternative_missing_patterns):
|
||||
missing_patterns = [
|
||||
_format_alternative_patterns(spec.alternative_required_patterns)
|
||||
]
|
||||
|
||||
if missing_patterns:
|
||||
return {
|
||||
"description": spec.description,
|
||||
"path": str(spec.path),
|
||||
"ok": False,
|
||||
"missing_patterns": missing_patterns,
|
||||
"total_size_bytes": total_size_bytes,
|
||||
"reason": "required_files_missing",
|
||||
}
|
||||
|
||||
if total_size_bytes < spec.min_total_size_bytes:
|
||||
return {
|
||||
"description": spec.description,
|
||||
"path": str(spec.path),
|
||||
"ok": False,
|
||||
"missing_patterns": [],
|
||||
"total_size_bytes": total_size_bytes,
|
||||
"reason": "directory_too_small",
|
||||
}
|
||||
|
||||
return {
|
||||
"description": spec.description,
|
||||
"path": str(spec.path),
|
||||
"ok": True,
|
||||
"missing_patterns": [],
|
||||
"total_size_bytes": total_size_bytes,
|
||||
"reason": "ok",
|
||||
}
|
||||
|
||||
|
||||
def _build_modelscope_spec(
|
||||
model_id: str,
|
||||
description: str,
|
||||
required_patterns: tuple[str, ...],
|
||||
*,
|
||||
min_total_size_bytes: int,
|
||||
alternative_required_patterns: tuple[tuple[str, ...], ...] = (),
|
||||
) -> ModelIntegritySpec:
|
||||
from ..core.config import settings
|
||||
|
||||
return ModelIntegritySpec(
|
||||
description=description,
|
||||
path=Path(settings.MODELSCOPE_PATH) / model_id,
|
||||
required_patterns=required_patterns,
|
||||
alternative_required_patterns=alternative_required_patterns,
|
||||
min_total_size_bytes=min_total_size_bytes,
|
||||
)
|
||||
|
||||
|
||||
def _convert_ms_patterns(
|
||||
patterns: tuple[str, ...],
|
||||
) -> tuple[str, ...]:
|
||||
return tuple(p.replace("snapshots/*/", "") for p in patterns)
|
||||
|
||||
|
||||
def _build_qwen_spec(
|
||||
model_id: str,
|
||||
description: str,
|
||||
required_patterns: tuple[str, ...],
|
||||
*,
|
||||
min_total_size_bytes: int,
|
||||
alternative_required_patterns: tuple[tuple[str, ...], ...] = (),
|
||||
) -> ModelIntegritySpec:
|
||||
from ..core.config import settings
|
||||
ms_path = Path(settings.MODELSCOPE_PATH) / model_id
|
||||
ms_required = _convert_ms_patterns(required_patterns)
|
||||
ms_alternative = tuple(
|
||||
_convert_ms_patterns(group)
|
||||
for group in alternative_required_patterns
|
||||
)
|
||||
return ModelIntegritySpec(
|
||||
description=description,
|
||||
path=ms_path,
|
||||
required_patterns=ms_required,
|
||||
alternative_required_patterns=ms_alternative,
|
||||
min_total_size_bytes=min_total_size_bytes,
|
||||
)
|
||||
|
||||
|
||||
def _should_check_qwen_forced_aligner(
|
||||
resolved_device: str,
|
||||
using_cpu_qwen_rust: bool,
|
||||
) -> bool:
|
||||
"""Return True when startup integrity should require Qwen forced aligner files."""
|
||||
from ..core.config import settings
|
||||
|
||||
_ = (resolved_device, using_cpu_qwen_rust)
|
||||
return settings.ASR_ENABLE_WORD_TIMESTAMPS
|
||||
|
||||
|
||||
def _build_required_model_integrity_specs() -> list[ModelIntegritySpec]:
|
||||
from ..core.config import settings
|
||||
from ..core.device import detect_device
|
||||
from ..services.asr.manager import get_model_manager
|
||||
from ..services.asr.model_capabilities import (
|
||||
get_enabled_qwen_modelscope_assets,
|
||||
get_runtime_required_modelscope_assets,
|
||||
)
|
||||
from ..services.asr.model_plan import get_runtime_model_ids
|
||||
from ..services.asr.qwenasr_rust import is_qwenasr_rust_available
|
||||
manager = get_model_manager()
|
||||
model_ids = [item["id"] for item in manager.list_declared_entries()]
|
||||
runtime_models = get_runtime_model_ids(model_ids)
|
||||
resolved_device = detect_device(settings.DEVICE)
|
||||
using_cpu_qwen_rust = (
|
||||
resolved_device == "cpu" and is_qwenasr_rust_available()
|
||||
)
|
||||
specs: list[ModelIntegritySpec] = []
|
||||
|
||||
for asset in get_runtime_required_modelscope_assets(
|
||||
include_realtime_punc=settings.ASR_ENABLE_REALTIME_PUNC,
|
||||
):
|
||||
specs.append(
|
||||
_build_modelscope_spec(
|
||||
asset.model_id,
|
||||
asset.description,
|
||||
asset.required_patterns,
|
||||
alternative_required_patterns=asset.alternative_required_patterns,
|
||||
min_total_size_bytes=asset.min_total_size_bytes,
|
||||
)
|
||||
)
|
||||
|
||||
for asset in get_enabled_qwen_modelscope_assets(
|
||||
include_forced_aligner=_should_check_qwen_forced_aligner(
|
||||
resolved_device=resolved_device,
|
||||
using_cpu_qwen_rust=using_cpu_qwen_rust,
|
||||
),
|
||||
):
|
||||
specs.append(
|
||||
_build_qwen_spec(
|
||||
asset.model_id,
|
||||
asset.description,
|
||||
asset.required_patterns,
|
||||
alternative_required_patterns=asset.alternative_required_patterns,
|
||||
min_total_size_bytes=asset.min_total_size_bytes,
|
||||
)
|
||||
)
|
||||
|
||||
return specs
|
||||
|
||||
|
||||
def verify_required_models_integrity(use_logger: bool = True) -> dict[str, Any]:
|
||||
output = logger.info if use_logger else print
|
||||
specs = _build_required_model_integrity_specs()
|
||||
total = len(specs)
|
||||
results: list[dict[str, Any]] = []
|
||||
invalid: list[dict[str, Any]] = []
|
||||
|
||||
if not use_logger:
|
||||
output("=" * 60)
|
||||
output(f"🔍 开始检查运行时模型完整性,共 {total} 个")
|
||||
output("=" * 60)
|
||||
for index, spec in enumerate(specs, start=1):
|
||||
output(f"[{index}/{total}] 检查 {spec.description}")
|
||||
result = _check_model_integrity_spec(spec)
|
||||
results.append(result)
|
||||
if result["ok"]:
|
||||
output(
|
||||
f" ✅ OK size={_format_bytes(result['total_size_bytes'])} "
|
||||
f"path={result['path']}"
|
||||
)
|
||||
continue
|
||||
invalid.append(result)
|
||||
if result["reason"] == "directory_missing":
|
||||
output(f" ❌ FAIL directory_missing path={result['path']}")
|
||||
elif result["reason"] == "required_files_missing":
|
||||
output(
|
||||
f" ❌ FAIL missing={', '.join(result['missing_patterns'])} "
|
||||
f"size={_format_bytes(result['total_size_bytes'])} path={result['path']}"
|
||||
)
|
||||
else:
|
||||
output(
|
||||
f" ❌ FAIL size_too_small size={_format_bytes(result['total_size_bytes'])} "
|
||||
f"path={result['path']}"
|
||||
)
|
||||
output("=" * 60)
|
||||
output(f"模型完整性检查完成: total={total} ok={total - len(invalid)} failed={len(invalid)}")
|
||||
output("=" * 60)
|
||||
return {
|
||||
"total": total,
|
||||
"results": results,
|
||||
"invalid_models": invalid,
|
||||
}
|
||||
|
||||
logger.info("开始检查运行时模型完整性: total=%s", total)
|
||||
with _StartupProgress("检查运行时模型完整性", total) as progress:
|
||||
for spec in specs:
|
||||
progress.update(f"检查 {spec.description}")
|
||||
result = _check_model_integrity_spec(spec)
|
||||
results.append(result)
|
||||
if not result["ok"]:
|
||||
invalid.append(result)
|
||||
if result["reason"] == "directory_missing":
|
||||
logger.error("模型完整性检查失败: %s, reason=directory_missing, path=%s", spec.description, result["path"])
|
||||
elif result["reason"] == "required_files_missing":
|
||||
logger.error(
|
||||
"模型完整性检查失败: %s, reason=required_files_missing, missing=%s, size=%s, path=%s",
|
||||
spec.description,
|
||||
", ".join(result["missing_patterns"]),
|
||||
_format_bytes(result["total_size_bytes"]),
|
||||
result["path"],
|
||||
)
|
||||
else:
|
||||
logger.error(
|
||||
"模型完整性检查失败: %s, reason=directory_too_small, size=%s, path=%s",
|
||||
spec.description,
|
||||
_format_bytes(result["total_size_bytes"]),
|
||||
result["path"],
|
||||
)
|
||||
progress.advance(f"检查完成 {spec.description}")
|
||||
|
||||
logger.info(
|
||||
"模型完整性检查完成: total=%s ok=%s failed=%s",
|
||||
total,
|
||||
total - len(invalid),
|
||||
len(invalid),
|
||||
)
|
||||
|
||||
return {
|
||||
"total": total,
|
||||
"results": results,
|
||||
"invalid_models": invalid,
|
||||
}
|
||||
def preload_models() -> dict[str, Any]:
|
||||
"""
|
||||
预加载所有需要的模型(根据 ENABLE_* 配置过滤)
|
||||
|
||||
Returns:
|
||||
dict: 包含加载状态的字典
|
||||
"""
|
||||
# 修复 CAM++ 配置文件(用于离线环境)
|
||||
try:
|
||||
from .download_models import fix_camplusplus_config
|
||||
fix_camplusplus_config()
|
||||
except Exception:
|
||||
pass # 修复失败不影响启动
|
||||
|
||||
result: dict[str, Any] = {
|
||||
"asr_models": {}, # 所有ASR模型加载状态
|
||||
"vad_model": {"loaded": False, "error": None},
|
||||
"speaker_diarization_model": {"loaded": False, "error": None},
|
||||
}
|
||||
|
||||
from ..core.config import settings
|
||||
from ..core.device import detect_device
|
||||
|
||||
# 初始化变量,避免未绑定错误
|
||||
asr_device = detect_device(settings.DEVICE)
|
||||
model_manager = None
|
||||
|
||||
# 1. 预加载所有配置的ASR模型(根据 ENABLE_* 配置过滤)
|
||||
model_ids: list[str] = []
|
||||
model_manager = None
|
||||
|
||||
try:
|
||||
from ..services.asr.manager import get_model_manager
|
||||
from ..services.asr.model_plan import get_runtime_model_ids
|
||||
from ..services.asr.runtime import get_runtime_router
|
||||
|
||||
model_manager = get_model_manager()
|
||||
runtime_router = get_runtime_router()
|
||||
|
||||
# 获取所有模型配置
|
||||
all_models = model_manager.list_declared_entries()
|
||||
model_ids = [m["id"] for m in all_models]
|
||||
|
||||
models_to_load = get_runtime_model_ids(model_ids)
|
||||
|
||||
if not models_to_load:
|
||||
logger.warning("⚠️ 当前环境未解析出可运行的 ASR 模型")
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"❌ 获取模型管理器失败: {e}")
|
||||
models_to_load = []
|
||||
runtime_router = None
|
||||
|
||||
total_steps = len(models_to_load) + 2
|
||||
|
||||
logger.info(
|
||||
"开始预加载模型: declared=%s runtime=%s models=%s",
|
||||
len(model_ids) if model_manager else 0,
|
||||
len(models_to_load),
|
||||
", ".join(models_to_load) if models_to_load else "(无)",
|
||||
)
|
||||
|
||||
with _StartupProgress("预加载模型", total_steps) as progress:
|
||||
for model_id in models_to_load:
|
||||
result["asr_models"][model_id] = {"loaded": False, "error": None}
|
||||
progress.update(f"加载 ASR 模型 {model_id}")
|
||||
try:
|
||||
if runtime_router is None:
|
||||
raise RuntimeError("runtime router unavailable")
|
||||
runtime_router.warmup_model(model_id)
|
||||
result["asr_models"][model_id]["loaded"] = True
|
||||
except Exception as e:
|
||||
result["asr_models"][model_id]["error"] = str(e)
|
||||
logger.error("ASR模型预加载失败: %s, error=%s", model_id, e)
|
||||
progress.advance(f"已完成 ASR 模型 {model_id}")
|
||||
|
||||
# 2. 预加载语音活动检测模型(VAD)
|
||||
progress.update("加载语音活动检测模型(VAD)")
|
||||
try:
|
||||
from ..services.asr.engines import get_global_vad_model
|
||||
|
||||
vad_model = get_global_vad_model(asr_device)
|
||||
if vad_model:
|
||||
result["vad_model"]["loaded"] = True
|
||||
else:
|
||||
result["vad_model"]["error"] = "语音活动检测模型(VAD)加载后返回None"
|
||||
except Exception as e:
|
||||
result["vad_model"]["error"] = str(e)
|
||||
logger.error("语音活动检测模型(VAD)加载失败: %s", e)
|
||||
progress.advance("已完成语音活动检测模型(VAD)")
|
||||
|
||||
# 5. 预加载说话人分离模型 (CAM++) - 必需模型,始终加载
|
||||
progress.update("加载说话人分离模型(CAM++)")
|
||||
try:
|
||||
from ..utils.speaker_diarizer import get_global_diarization_pipeline
|
||||
|
||||
diarization_pipeline = get_global_diarization_pipeline()
|
||||
if diarization_pipeline:
|
||||
result["speaker_diarization_model"]["loaded"] = True
|
||||
else:
|
||||
result["speaker_diarization_model"]["error"] = "说话人分离模型加载后返回None"
|
||||
except Exception as e:
|
||||
result["speaker_diarization_model"]["error"] = str(e)
|
||||
logger.error("说话人分离模型(CAM++)加载失败: %s", e)
|
||||
progress.advance("已完成说话人分离模型(CAM++)")
|
||||
|
||||
loaded_asr_count = sum(1 for status in result["asr_models"].values() if status["loaded"])
|
||||
total_asr_count = len(result["asr_models"])
|
||||
extra_loaded = sum(
|
||||
1
|
||||
for key in ("vad_model", "speaker_diarization_model")
|
||||
if result[key]["loaded"]
|
||||
)
|
||||
extra_failed = sum(
|
||||
1
|
||||
for key in ("vad_model", "speaker_diarization_model")
|
||||
if result[key]["error"]
|
||||
)
|
||||
logger.info(
|
||||
"模型预加载完成: asr=%s/%s extra_loaded=%s extra_failed=%s",
|
||||
loaded_asr_count,
|
||||
total_asr_count,
|
||||
extra_loaded,
|
||||
extra_failed,
|
||||
)
|
||||
|
||||
return result
|
||||
|
|
@ -0,0 +1,697 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
说话人分离模块
|
||||
基于 CAM++ 的说话人分离,用于多说话人音频分割
|
||||
"""
|
||||
|
||||
from loguru import logger
|
||||
import numpy as np
|
||||
import librosa
|
||||
import soundfile as sf
|
||||
import tempfile
|
||||
import os
|
||||
import threading
|
||||
from typing import Any, List, Mapping, Optional, Sequence, cast
|
||||
from dataclasses import dataclass
|
||||
|
||||
import torch
|
||||
|
||||
from ..core.config import settings
|
||||
from ..core.exceptions import DefaultServerErrorException
|
||||
|
||||
# 全局 CAM++ pipeline 缓存(单例)
|
||||
_global_diarization_pipeline: Any | None = None
|
||||
_diarization_pipeline_lock = threading.Lock()
|
||||
_diarization_inference_semaphore = threading.BoundedSemaphore(1)
|
||||
|
||||
|
||||
@dataclass
|
||||
class SpeakerSegment:
|
||||
"""说话人分段信息"""
|
||||
|
||||
start_ms: int
|
||||
end_ms: int
|
||||
speaker_id: str
|
||||
audio_data: Optional[np.ndarray] = None
|
||||
temp_file: Optional[str] = None
|
||||
|
||||
@property
|
||||
def start_sec(self) -> float:
|
||||
return self.start_ms / 1000.0
|
||||
|
||||
@property
|
||||
def end_sec(self) -> float:
|
||||
return self.end_ms / 1000.0
|
||||
|
||||
@property
|
||||
def duration_ms(self) -> int:
|
||||
return self.end_ms - self.start_ms
|
||||
|
||||
@property
|
||||
def duration_sec(self) -> float:
|
||||
return self.duration_ms / 1000.0
|
||||
|
||||
|
||||
def _resolve_modelscope_device() -> str:
|
||||
"""根据配置和硬件自动选择 modelscope pipeline 设备
|
||||
"""
|
||||
from ..core.device import detect_device
|
||||
|
||||
return detect_device(settings.DEVICE)
|
||||
|
||||
|
||||
def _move_pipeline_model_to_device(pipeline_instance: Any, modelscope_device: str) -> None:
|
||||
"""将 pipeline 的底层模型迁移到目标设备。"""
|
||||
if hasattr(pipeline_instance, "device_name"):
|
||||
pipeline_instance.device_name = modelscope_device
|
||||
model = getattr(pipeline_instance, "model", None)
|
||||
if model is not None and hasattr(model, "to"):
|
||||
pipeline_instance.model = model.to(modelscope_device)
|
||||
|
||||
|
||||
def _create_modelscope_pipeline(
|
||||
*,
|
||||
task: Any,
|
||||
model: str,
|
||||
modelscope_device: str,
|
||||
model_revision: Optional[str] = None,
|
||||
) -> Any:
|
||||
"""创建 modelscope pipeline,并在需要时把底层模型迁移到目标设备。"""
|
||||
from modelscope.pipelines import pipeline
|
||||
|
||||
pipeline_kwargs: dict[str, Any] = {
|
||||
"task": task,
|
||||
"model": model,
|
||||
"device": modelscope_device,
|
||||
}
|
||||
if model_revision is not None:
|
||||
pipeline_kwargs["model_revision"] = model_revision
|
||||
|
||||
pipeline_instance = pipeline(**pipeline_kwargs)
|
||||
_move_pipeline_model_to_device(pipeline_instance, modelscope_device)
|
||||
return pipeline_instance
|
||||
|
||||
|
||||
def _enable_batched_sv(
|
||||
pipeline_instance: Any,
|
||||
modelscope_device: str,
|
||||
max_batch_size: int = 32,
|
||||
) -> Any:
|
||||
"""
|
||||
对说话人分离 pipeline 启用 batched SV 推理。
|
||||
|
||||
原始 pipeline 的 forward 方法逐个 segment 调用 sv_pipeline 提取 embedding,
|
||||
这里改为将所有 segment 拼成一个 batch 一次性推理,大幅减少 GPU 调用次数。
|
||||
同时将子 pipeline(sv / vad / change_locator)绑定到指定 device。
|
||||
|
||||
Args:
|
||||
pipeline_instance: CAM++ diarization pipeline 实例
|
||||
modelscope_device: 设备名称
|
||||
max_batch_size: 最大批处理大小,防止 OOM
|
||||
"""
|
||||
if getattr(pipeline_instance, "_batched_sv_enabled", False):
|
||||
return pipeline_instance
|
||||
|
||||
from modelscope.utils.constant import Tasks
|
||||
|
||||
config = getattr(pipeline_instance, "config", None)
|
||||
if not isinstance(config, Mapping):
|
||||
logger.warning("CAM++ pipeline 缺少可读取的 config,跳过 batched SV 优化")
|
||||
return pipeline_instance
|
||||
|
||||
sv_model = config.get("speaker_model")
|
||||
vad_model = config.get("vad_model")
|
||||
change_locator = config.get("change_locator")
|
||||
|
||||
if isinstance(sv_model, str) and sv_model:
|
||||
pipeline_instance.sv_pipeline = _create_modelscope_pipeline(
|
||||
task=Tasks.speaker_verification,
|
||||
model=sv_model,
|
||||
modelscope_device=modelscope_device,
|
||||
)
|
||||
|
||||
if isinstance(vad_model, str) and vad_model:
|
||||
pipeline_instance.vad_pipeline = _create_modelscope_pipeline(
|
||||
task=Tasks.voice_activity_detection,
|
||||
model=vad_model,
|
||||
modelscope_device=modelscope_device,
|
||||
model_revision="v2.0.2",
|
||||
)
|
||||
|
||||
if isinstance(change_locator, str) and change_locator:
|
||||
pipeline_instance.change_locator_pipeline = _create_modelscope_pipeline(
|
||||
task=Tasks.speaker_diarization,
|
||||
model=change_locator,
|
||||
modelscope_device=modelscope_device,
|
||||
)
|
||||
|
||||
def batched_forward(self: Any, segments: Sequence[Sequence[Any]]) -> np.ndarray:
|
||||
"""批量提取说话人 embedding,替代逐段串行推理"""
|
||||
sv_model_instance = getattr(getattr(self, "sv_pipeline", None), "model", None)
|
||||
emb_size = int(getattr(sv_model_instance, "emb_size", 192))
|
||||
|
||||
if not segments:
|
||||
return np.empty((0, emb_size), dtype=np.float32)
|
||||
|
||||
if sv_model_instance is None:
|
||||
raise RuntimeError("CAM++ sv_pipeline.model 未初始化")
|
||||
|
||||
all_embeddings: list[np.ndarray] = []
|
||||
total_segments = len(segments)
|
||||
start_idx = 0
|
||||
|
||||
while start_idx < total_segments:
|
||||
end_idx = min(start_idx + max_batch_size, total_segments)
|
||||
batch_segments = segments[start_idx:end_idx]
|
||||
|
||||
batch_items: list[np.ndarray] = []
|
||||
for segment in batch_segments:
|
||||
if len(segment) < 3:
|
||||
continue
|
||||
batch_items.append(np.asarray(segment[2], dtype=np.float32))
|
||||
|
||||
if not batch_items:
|
||||
start_idx = end_idx
|
||||
continue
|
||||
|
||||
batch = np.stack(batch_items, axis=0)
|
||||
|
||||
with torch.no_grad():
|
||||
embeddings = sv_model_instance(
|
||||
cast(Any, torch).as_tensor(batch).to(modelscope_device)
|
||||
)
|
||||
|
||||
if isinstance(embeddings, torch.Tensor):
|
||||
all_embeddings.append(embeddings.detach().cpu().numpy())
|
||||
else:
|
||||
all_embeddings.append(np.asarray(embeddings, dtype=np.float32))
|
||||
|
||||
start_idx = end_idx
|
||||
|
||||
if not all_embeddings:
|
||||
return np.empty((0, emb_size), dtype=np.float32)
|
||||
|
||||
return (
|
||||
np.concatenate(all_embeddings, axis=0)
|
||||
if len(all_embeddings) > 1
|
||||
else all_embeddings[0]
|
||||
)
|
||||
|
||||
import types
|
||||
|
||||
pipeline_instance.forward = types.MethodType(batched_forward, pipeline_instance)
|
||||
pipeline_instance._batched_sv_enabled = True
|
||||
|
||||
logger.info(
|
||||
"CAM++ 说话人分离启用 batched SV: device={}, sv_device={}, vad_device={}",
|
||||
modelscope_device,
|
||||
getattr(getattr(pipeline_instance, "sv_pipeline", None), "device_name", "unknown"),
|
||||
getattr(getattr(pipeline_instance, "vad_pipeline", None), "device_name", "unknown"),
|
||||
)
|
||||
return pipeline_instance
|
||||
|
||||
|
||||
def get_global_diarization_pipeline() -> Any:
|
||||
"""获取全局说话人分离 pipeline(懒加载单例)"""
|
||||
global _global_diarization_pipeline
|
||||
|
||||
with _diarization_pipeline_lock:
|
||||
if _global_diarization_pipeline is None:
|
||||
try:
|
||||
from modelscope.utils.constant import Tasks
|
||||
from ..infrastructure.model_utils import resolve_model_path
|
||||
|
||||
model_id = 'iic/speech_campplus_speaker-diarization_common'
|
||||
model_path = resolve_model_path(model_id)
|
||||
modelscope_device = _resolve_modelscope_device()
|
||||
|
||||
logger.info(
|
||||
"正在加载 CAM++ 说话人分离模型: {}, device={}",
|
||||
model_path,
|
||||
modelscope_device,
|
||||
)
|
||||
_global_diarization_pipeline = _create_modelscope_pipeline(
|
||||
task=Tasks.speaker_diarization,
|
||||
model=model_path,
|
||||
modelscope_device=modelscope_device,
|
||||
)
|
||||
_global_diarization_pipeline = _enable_batched_sv(
|
||||
_global_diarization_pipeline, modelscope_device
|
||||
)
|
||||
logger.info("CAM++ 模型加载成功(已启用 batched SV)")
|
||||
except Exception as e:
|
||||
logger.error(f"CAM++ 模型加载失败: {e}")
|
||||
raise DefaultServerErrorException(f"说话人分离模型加载失败: {str(e)}")
|
||||
|
||||
return _global_diarization_pipeline
|
||||
|
||||
|
||||
class SpeakerDiarizer:
|
||||
"""基于 CAM++ 的说话人分离器"""
|
||||
|
||||
DEFAULT_MIN_SEGMENT_SEC = 1.0
|
||||
DEFAULT_SAMPLE_RATE = 16000
|
||||
LOW_ENERGY_SEARCH_WINDOW_MS = 10000
|
||||
LOW_ENERGY_CONTEXT_MS = 160
|
||||
LOW_ENERGY_STEP_MS = 20
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
min_segment_sec: float = DEFAULT_MIN_SEGMENT_SEC,
|
||||
):
|
||||
self.min_segment_sec = min_segment_sec
|
||||
self.min_segment_ms = int(min_segment_sec * 1000)
|
||||
|
||||
def diarize(
|
||||
self, audio_path: str
|
||||
) -> List[SpeakerSegment]:
|
||||
"""执行说话人分离
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
|
||||
Returns:
|
||||
原始分段列表(未合并)
|
||||
"""
|
||||
audio_duration_ms: Optional[int] = None
|
||||
try:
|
||||
try:
|
||||
audio_duration_ms = int(librosa.get_duration(path=audio_path) * 1000)
|
||||
except Exception:
|
||||
audio_duration_ms = None
|
||||
|
||||
# CAM++ 对极短片段收益很低,且容易直接报 "too short"。
|
||||
# 这里提前降级成单说话人,避免无意义 warning 刷屏。
|
||||
if audio_duration_ms is not None and audio_duration_ms < self.min_segment_ms:
|
||||
logger.debug(
|
||||
"音频时长过短,跳过 CAM++ 说话人分离: duration_ms=%s < min_segment_ms=%s",
|
||||
audio_duration_ms,
|
||||
self.min_segment_ms,
|
||||
)
|
||||
return [
|
||||
SpeakerSegment(
|
||||
start_ms=0,
|
||||
end_ms=max(audio_duration_ms, 1),
|
||||
speaker_id="说话人1",
|
||||
)
|
||||
]
|
||||
|
||||
pipeline = get_global_diarization_pipeline()
|
||||
|
||||
logger.info(f"开始说话人分离: {audio_path}")
|
||||
with _diarization_inference_semaphore:
|
||||
result = pipeline(audio_path)
|
||||
|
||||
# 解析结果: {'text': [[start, end, speaker_id], ...]}
|
||||
# pipeline 返回类型不确定,需要安全地获取 'text' 字段
|
||||
if isinstance(result, dict):
|
||||
raw_output = result.get('text', [])
|
||||
else:
|
||||
raw_output = getattr(result, 'text', []) or []
|
||||
|
||||
segments = []
|
||||
for seg in raw_output:
|
||||
if isinstance(seg, list) and len(seg) == 3:
|
||||
try:
|
||||
start_ms = int(float(seg[0]) * 1000)
|
||||
end_ms = int(float(seg[1]) * 1000)
|
||||
speaker_id = f"说话人{int(seg[2]) + 1}"
|
||||
segments.append(SpeakerSegment(
|
||||
start_ms=start_ms,
|
||||
end_ms=end_ms,
|
||||
speaker_id=speaker_id,
|
||||
))
|
||||
except (ValueError, TypeError) as e:
|
||||
logger.warning(f"跳过格式错误的片段: {seg}, 错误: {e}")
|
||||
|
||||
logger.info(f"说话人分离完成,原始片段数: {len(segments)}")
|
||||
# 诊断日志:打印前20个原始片段
|
||||
for i, seg in enumerate(segments[:20]):
|
||||
logger.debug(
|
||||
f"[CAM++原始] #{i}: {seg.start_sec:.2f}-{seg.end_sec:.2f}s "
|
||||
f"({seg.duration_sec:.2f}s) {seg.speaker_id}"
|
||||
)
|
||||
return segments
|
||||
|
||||
except Exception as e:
|
||||
error_msg = str(e).lower()
|
||||
|
||||
# 音频太短时,返回默认的单说话人片段
|
||||
if "too short" in error_msg:
|
||||
logger.debug("CAM++ 跳过过短音频,回退单说话人片段: %s", e)
|
||||
if audio_duration_ms is None:
|
||||
try:
|
||||
audio_duration_ms = int(librosa.get_duration(path=audio_path) * 1000)
|
||||
except Exception:
|
||||
audio_duration_ms = 5000
|
||||
|
||||
return [
|
||||
SpeakerSegment(
|
||||
start_ms=0,
|
||||
end_ms=audio_duration_ms,
|
||||
speaker_id="说话人1",
|
||||
)
|
||||
]
|
||||
|
||||
# 其他异常正常抛出
|
||||
logger.error(f"说话人分离失败: {e}")
|
||||
raise DefaultServerErrorException(f"说话人分离失败: {str(e)}")
|
||||
|
||||
def merge_consecutive_segments(
|
||||
self, segments: List[SpeakerSegment]
|
||||
) -> List[SpeakerSegment]:
|
||||
"""合并同一说话人的连续片段"""
|
||||
if not segments:
|
||||
return []
|
||||
|
||||
# 按开始时间排序
|
||||
sorted_segments = sorted(segments, key=lambda x: x.start_ms)
|
||||
|
||||
merged = []
|
||||
current = SpeakerSegment(
|
||||
start_ms=sorted_segments[0].start_ms,
|
||||
end_ms=sorted_segments[0].end_ms,
|
||||
speaker_id=sorted_segments[0].speaker_id,
|
||||
)
|
||||
|
||||
for seg in sorted_segments[1:]:
|
||||
if seg.speaker_id == current.speaker_id:
|
||||
# 同一说话人,扩展结束时间
|
||||
current.end_ms = max(current.end_ms, seg.end_ms)
|
||||
else:
|
||||
# 不同说话人,保存当前段,开始新段
|
||||
logger.debug(
|
||||
f"[合并中断] 说话人切换: {current.speaker_id} → {seg.speaker_id} "
|
||||
f"在 {seg.start_sec:.2f}s,保存片段 {current.start_sec:.2f}-{current.end_sec:.2f}s"
|
||||
)
|
||||
merged.append(current)
|
||||
current = SpeakerSegment(
|
||||
start_ms=seg.start_ms,
|
||||
end_ms=seg.end_ms,
|
||||
speaker_id=seg.speaker_id,
|
||||
)
|
||||
|
||||
# 保存最后一段
|
||||
merged.append(current)
|
||||
|
||||
logger.info(f"合并同一说话人连续片段: {len(segments)} → {len(merged)}")
|
||||
# 诊断日志:打印合并后的前20个片段
|
||||
for i, seg in enumerate(merged[:20]):
|
||||
logger.debug(
|
||||
f"[合并后] #{i}: {seg.start_sec:.2f}-{seg.end_sec:.2f}s "
|
||||
f"({seg.duration_sec:.2f}s) {seg.speaker_id}"
|
||||
)
|
||||
return merged
|
||||
|
||||
def merge_short_segments(
|
||||
self, segments: List[SpeakerSegment]
|
||||
) -> List[SpeakerSegment]:
|
||||
"""智能合并短片段
|
||||
|
||||
策略:
|
||||
1. 第一层:<10s的片段向后合并(避免孤立短片段)
|
||||
2. 第二层:60s累积合并(合并连续片段)
|
||||
"""
|
||||
if not segments:
|
||||
return []
|
||||
|
||||
max_segment_sec = settings.MAX_SEGMENT_SEC
|
||||
|
||||
# 按开始时间排序
|
||||
sorted_segments = sorted(segments, key=lambda x: x.start_ms)
|
||||
|
||||
# 第一层:<10s累积向后合并(循环计算直到>=10s或超过60s)
|
||||
merged = []
|
||||
i = 0
|
||||
while i < len(sorted_segments):
|
||||
seg = sorted_segments[i]
|
||||
|
||||
# 如果>=10s,直接添加
|
||||
if seg.duration_sec >= 10.0:
|
||||
merged.append(seg)
|
||||
i += 1
|
||||
continue
|
||||
|
||||
# <10s,开始累积合并
|
||||
current_start_ms = seg.start_ms
|
||||
current_end_ms = seg.end_ms
|
||||
current_duration_sec = seg.duration_sec
|
||||
j = i + 1
|
||||
|
||||
# 累积合并,只要<10s且同说话人且不超过60s
|
||||
while j < len(sorted_segments) and current_duration_sec < 10.0:
|
||||
next_seg = sorted_segments[j]
|
||||
if next_seg.speaker_id != seg.speaker_id:
|
||||
break
|
||||
new_duration = (next_seg.end_ms - current_start_ms) / 1000.0
|
||||
if new_duration > max_segment_sec:
|
||||
break
|
||||
current_end_ms = next_seg.end_ms
|
||||
current_duration_sec = new_duration
|
||||
j += 1
|
||||
|
||||
# 创建合并后的片段
|
||||
merged_seg = SpeakerSegment(
|
||||
start_ms=current_start_ms,
|
||||
end_ms=current_end_ms,
|
||||
speaker_id=seg.speaker_id,
|
||||
)
|
||||
merged.append(merged_seg)
|
||||
|
||||
if j > i + 1:
|
||||
logger.debug(
|
||||
f"[第一层] {seg.speaker_id}: "
|
||||
f"累积合并了 {j - i} 个片段,结果 {merged_seg.duration_sec:.1f}s"
|
||||
)
|
||||
i = j
|
||||
|
||||
# 第二层:60s累积合并
|
||||
final_merged = []
|
||||
i = 0
|
||||
while i < len(merged):
|
||||
seg = merged[i]
|
||||
current_start_ms = seg.start_ms
|
||||
current_end_ms = seg.end_ms
|
||||
j = i + 1
|
||||
|
||||
# 累积合并,只要 <= 60s 且同说话人
|
||||
while j < len(merged):
|
||||
next_seg = merged[j]
|
||||
if next_seg.speaker_id != seg.speaker_id:
|
||||
break
|
||||
new_duration = (next_seg.end_ms - current_start_ms) / 1000.0
|
||||
if new_duration > max_segment_sec:
|
||||
break
|
||||
current_end_ms = next_seg.end_ms
|
||||
j += 1
|
||||
|
||||
merged_seg = SpeakerSegment(
|
||||
start_ms=current_start_ms,
|
||||
end_ms=current_end_ms,
|
||||
speaker_id=seg.speaker_id,
|
||||
)
|
||||
final_merged.append(merged_seg)
|
||||
|
||||
if j > i + 1:
|
||||
logger.debug(
|
||||
f"[第二层] {seg.speaker_id}: "
|
||||
f"合并了 {j - i} 个片段"
|
||||
)
|
||||
i = j
|
||||
|
||||
return final_merged
|
||||
|
||||
def _find_low_energy_boundary_ms(
|
||||
self,
|
||||
audio_data: np.ndarray,
|
||||
sample_rate: int,
|
||||
lower_ms: int,
|
||||
upper_ms: int,
|
||||
) -> int:
|
||||
lower_ms = max(0, lower_ms)
|
||||
upper_ms = max(lower_ms, upper_ms)
|
||||
if sample_rate <= 0 or audio_data.size == 0:
|
||||
return upper_ms
|
||||
|
||||
context_samples = max(
|
||||
1, int(sample_rate * self.LOW_ENERGY_CONTEXT_MS / 1000)
|
||||
)
|
||||
candidate_points = list(
|
||||
range(lower_ms, upper_ms + 1, self.LOW_ENERGY_STEP_MS)
|
||||
)
|
||||
if not candidate_points or candidate_points[-1] != upper_ms:
|
||||
candidate_points.append(upper_ms)
|
||||
|
||||
best_ms = upper_ms
|
||||
best_energy = float("inf")
|
||||
audio_length = int(audio_data.shape[0])
|
||||
|
||||
for candidate_ms in candidate_points:
|
||||
center_sample = int(candidate_ms * sample_rate / 1000)
|
||||
start_sample = max(0, center_sample - context_samples // 2)
|
||||
end_sample = min(audio_length, center_sample + context_samples // 2)
|
||||
if start_sample >= end_sample:
|
||||
continue
|
||||
|
||||
window = audio_data[start_sample:end_sample]
|
||||
energy = float(np.mean(np.square(window)))
|
||||
if energy <= best_energy:
|
||||
best_energy = energy
|
||||
best_ms = candidate_ms
|
||||
|
||||
return best_ms
|
||||
|
||||
def split_long_segments(
|
||||
self,
|
||||
segments: List[SpeakerSegment],
|
||||
audio_data: np.ndarray,
|
||||
sample_rate: int,
|
||||
) -> List[SpeakerSegment]:
|
||||
max_segment_ms = int(settings.MAX_SEGMENT_SEC * 1000)
|
||||
if max_segment_ms <= 0:
|
||||
return segments
|
||||
|
||||
split_segments: List[SpeakerSegment] = []
|
||||
for seg in segments:
|
||||
if seg.duration_ms <= max_segment_ms:
|
||||
split_segments.append(seg)
|
||||
continue
|
||||
|
||||
current_start_ms = seg.start_ms
|
||||
while seg.end_ms - current_start_ms > max_segment_ms:
|
||||
hard_boundary_ms = current_start_ms + max_segment_ms
|
||||
lower_boundary_ms = max(
|
||||
current_start_ms + self.min_segment_ms,
|
||||
hard_boundary_ms - self.LOW_ENERGY_SEARCH_WINDOW_MS,
|
||||
)
|
||||
boundary_ms = self._find_low_energy_boundary_ms(
|
||||
audio_data=audio_data,
|
||||
sample_rate=sample_rate,
|
||||
lower_ms=lower_boundary_ms,
|
||||
upper_ms=hard_boundary_ms,
|
||||
)
|
||||
if boundary_ms <= current_start_ms:
|
||||
boundary_ms = hard_boundary_ms
|
||||
|
||||
split_segments.append(
|
||||
SpeakerSegment(
|
||||
start_ms=current_start_ms,
|
||||
end_ms=boundary_ms,
|
||||
speaker_id=seg.speaker_id,
|
||||
)
|
||||
)
|
||||
current_start_ms = boundary_ms
|
||||
|
||||
remaining_ms = seg.end_ms - current_start_ms
|
||||
if remaining_ms >= self.min_segment_ms:
|
||||
split_segments.append(
|
||||
SpeakerSegment(
|
||||
start_ms=current_start_ms,
|
||||
end_ms=seg.end_ms,
|
||||
speaker_id=seg.speaker_id,
|
||||
)
|
||||
)
|
||||
elif split_segments:
|
||||
split_segments[-1].end_ms = seg.end_ms
|
||||
|
||||
if len(split_segments) != len(segments):
|
||||
logger.info(
|
||||
"Split long speaker segments by low energy: {} -> {}, max={}s",
|
||||
len(segments),
|
||||
len(split_segments),
|
||||
settings.MAX_SEGMENT_SEC,
|
||||
)
|
||||
return split_segments
|
||||
|
||||
def split_audio_by_speakers(
|
||||
self,
|
||||
audio_path: str,
|
||||
output_dir: Optional[str] = None,
|
||||
) -> List[SpeakerSegment]:
|
||||
"""完整的说话人分离流程
|
||||
|
||||
流程:
|
||||
1. 执行CAM++说话人分离
|
||||
2. 智能合并短片段(两层合并策略)
|
||||
- 第一层:<10s片段累积合并
|
||||
- 第二层:60s累积合并
|
||||
3. 提取音频数据,保存临时文件
|
||||
|
||||
Args:
|
||||
audio_path: 音频文件路径
|
||||
output_dir: 输出目录
|
||||
|
||||
Returns:
|
||||
SpeakerSegment 列表
|
||||
"""
|
||||
try:
|
||||
# 1. 执行说话人分离
|
||||
raw_segments = self.diarize(audio_path)
|
||||
|
||||
if not raw_segments:
|
||||
logger.warning("说话人分离未检测到任何片段")
|
||||
return []
|
||||
|
||||
# 2. 智能合并短片段(第一个<10s的同说话人片段向后合并)
|
||||
final_segments = self.merge_short_segments(raw_segments)
|
||||
|
||||
# 3. Load audio before low-energy splitting and segment extraction.
|
||||
logger.info("加载音频并提取片段...")
|
||||
audio_data, sr = librosa.load(audio_path, sr=self.DEFAULT_SAMPLE_RATE)
|
||||
sample_rate = int(sr)
|
||||
|
||||
final_segments = self.split_long_segments(
|
||||
final_segments,
|
||||
audio_data,
|
||||
sample_rate,
|
||||
)
|
||||
logger.info(f"智能合并完成: {len(raw_segments)} → {len(final_segments)} 个片段")
|
||||
|
||||
output_dir = output_dir or settings.TEMP_DIR
|
||||
os.makedirs(output_dir, exist_ok=True)
|
||||
|
||||
for idx, seg in enumerate(final_segments):
|
||||
start_sample = int(seg.start_ms / 1000 * sample_rate)
|
||||
end_sample = int(seg.end_ms / 1000 * sample_rate)
|
||||
|
||||
seg.audio_data = audio_data[start_sample:end_sample]
|
||||
|
||||
# 保存临时文件
|
||||
temp_file = tempfile.NamedTemporaryFile(
|
||||
delete=False,
|
||||
suffix=".wav",
|
||||
dir=output_dir,
|
||||
prefix=f"{seg.speaker_id}_{idx:03d}_",
|
||||
)
|
||||
temp_path = temp_file.name
|
||||
temp_file.close()
|
||||
|
||||
sf.write(temp_path, seg.audio_data, sample_rate)
|
||||
seg.temp_file = temp_path
|
||||
|
||||
# 统计
|
||||
unique_speakers = sorted(set(seg.speaker_id for seg in final_segments))
|
||||
logger.info(
|
||||
f"音频分割完成: {len(final_segments)} 个片段, "
|
||||
f"{len(unique_speakers)} 个说话人"
|
||||
)
|
||||
for spk in unique_speakers:
|
||||
spk_segs = [s for s in final_segments if s.speaker_id == spk]
|
||||
total_time = sum(s.duration_sec for s in spk_segs)
|
||||
logger.info(f" {spk}: {len(spk_segs)} 片段, {total_time:.2f}s")
|
||||
|
||||
return final_segments
|
||||
|
||||
except Exception as e:
|
||||
logger.error(f"说话人分离流程失败: {e}")
|
||||
raise DefaultServerErrorException(f"说话人分离失败: {str(e)}")
|
||||
|
||||
@staticmethod
|
||||
def cleanup_segments(segments: List[SpeakerSegment]) -> None:
|
||||
"""清理临时文件"""
|
||||
for seg in segments:
|
||||
if seg.temp_file and os.path.exists(seg.temp_file):
|
||||
try:
|
||||
os.remove(seg.temp_file)
|
||||
except Exception as e:
|
||||
logger.warning(f"清理临时文件失败: {seg.temp_file}, {e}")
|
||||
|
|
@ -0,0 +1,59 @@
|
|||
# -*- coding: utf-8 -*-
|
||||
"""
|
||||
基于itntext的ITN(逆文本标准化)工具模块
|
||||
使用itntext库提供高质量的中文ITN处理
|
||||
"""
|
||||
|
||||
import logging
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
# itntext导入 - 延迟导入以避免初始化问题
|
||||
_itntext_normalizer = None
|
||||
|
||||
|
||||
def _get_normalizer():
|
||||
"""获取itntext标准化器实例(单例模式)"""
|
||||
global _itntext_normalizer
|
||||
if _itntext_normalizer is None:
|
||||
try:
|
||||
from itntext import Normalizer
|
||||
_itntext_normalizer = Normalizer(lang="zh", operator="itn")
|
||||
logger.info("itntext ITN模块初始化成功")
|
||||
except ImportError as e:
|
||||
logger.error(f"导入itntext失败: {e}")
|
||||
raise ImportError("请安装itntext库: pip install itntext")
|
||||
except Exception as e:
|
||||
logger.error(f"初始化itntext失败: {e}")
|
||||
raise
|
||||
return _itntext_normalizer
|
||||
|
||||
|
||||
def apply_itn_to_text(text: str) -> str:
|
||||
"""
|
||||
对文本应用逆文本标准化(ITN)
|
||||
使用itntext库进行高质量的中文ITN处理
|
||||
|
||||
Args:
|
||||
text: 语音识别结果文本
|
||||
|
||||
Returns:
|
||||
应用ITN后的文本
|
||||
"""
|
||||
if not text or not text.strip():
|
||||
return text
|
||||
|
||||
try:
|
||||
normalizer = _get_normalizer()
|
||||
result = normalizer.normalize(text)
|
||||
logger.debug(f"ITN处理: '{text}' -> '{result}'")
|
||||
return result
|
||||
except Exception as e:
|
||||
logger.warning(f"ITN处理失败: {text}, 错误: {str(e)}")
|
||||
return text
|
||||
|
||||
|
||||
def normalize_asr_text(text: str, enable_itn: bool) -> str:
|
||||
if not enable_itn:
|
||||
return text
|
||||
return apply_itn_to_text(text)
|
||||
|
|
@ -0,0 +1,68 @@
|
|||
# crg-mcp — code-review-graph MCP 接入插件
|
||||
|
||||
把已部署在本机的 `D:\github-project\code-review-graph` MCP 服务接入 PI-Desktop,
|
||||
让它的工具以原生 agent 工具的形式出现。**未修改该项目任何文件。**
|
||||
|
||||
## 接入原理
|
||||
|
||||
PI-Desktop 的 MCP 客户端由插件宿主承载:宿主读取插件 `manifest.json` 里的
|
||||
`contributes.mcpServers`,自行拉起进程、完成 MCP 握手,并把上游每个工具发布为
|
||||
`plugin_<插件id>_<server id>_<工具名>`。因此这里只需声明,无需自己写 JSON-RPC。
|
||||
|
||||
## 文件
|
||||
|
||||
| 文件 | 作用 |
|
||||
| --- | --- |
|
||||
| `manifest.json` | 声明 stdio MCP 服务 + `mcp.server.local` 权限 |
|
||||
| `crg.cmd` | 启动包装脚本(修环境后 exec `python -m code_review_graph serve`) |
|
||||
| `main.js` | 空加载器,客户端生命周期归宿主管理 |
|
||||
| `dist/crg-mcp-1.0.0.piplug` | 可安装包 |
|
||||
|
||||
## 两个必须保留的环境修正
|
||||
|
||||
宿主的 `mcpProcessEnv()` 只向子进程传递
|
||||
`PATH / SystemRoot / windir / TEMP / TMP / LANG`(加插件声明的 env),所以:
|
||||
|
||||
1. **`PYTHONPATH` 必须注入。** 项目的 editable 安装记录
|
||||
`.venv\Lib\site-packages\_editable_impl_code_review_graph.pth` 指向
|
||||
`D:\github_project\code-review-graph`(下划线),而项目实际位于
|
||||
`D:\github-project\code-review-graph`(连字符),因此直接
|
||||
`import code_review_graph` 会 `ModuleNotFoundError`。
|
||||
同理 `.venv\Scripts\code-review-graph.exe` 也不能用
|
||||
(`error: uv trampoline failed to canonicalize script path`)——包装脚本绕过了
|
||||
这两点,改用 `python -m code_review_graph`。
|
||||
2. **`USERPROFILE` / `HOMEDRIVE` / `HOMEPATH` 必须补齐。**
|
||||
`code_review_graph/constants.py` 在 import 期调用 `Path.home()`,
|
||||
精简环境下会抛 `RuntimeError: Could not determine home directory.`
|
||||
|
||||
## 暴露的工具(10 个)
|
||||
|
||||
默认通过 `CRG_TOOLS` 只开放审查相关的 10 个工具(上游共 30 个,全开会显著占上下文):
|
||||
|
||||
`build_or_update_graph_tool`、`run_postprocess_tool`、`get_minimal_context_tool`、
|
||||
`get_review_context_tool`、`get_impact_radius_tool`、`query_graph_tool`、
|
||||
`semantic_search_nodes_tool`、`detect_changes_tool`、`list_graph_stats_tool`、
|
||||
`get_affected_flows_tool`
|
||||
|
||||
工具名前缀为 `plugin_crg_mcp_crg_`,例如 `plugin_crg_mcp_crg_query_graph_tool`。
|
||||
|
||||
### 调整暴露范围 / 目标仓库
|
||||
|
||||
编辑 `crg.cmd`:
|
||||
|
||||
- 改 `CRG_TOOLS=...`:改工具白名单(置空并删除该行 = 暴露全部 30 个)。
|
||||
- 改 `CRG_REPO=...`:改被分析的仓库根目录(默认指向 code-review-graph 自身,
|
||||
即已建好图的那个库)。
|
||||
|
||||
改完重启 PI-Desktop 生效。
|
||||
|
||||
## 为何用 stdio 而不是 HTTP
|
||||
|
||||
`serve --http`(127.0.0.1:5555/mcp)实测可用,但宿主只负责 spawn,不会托管一个
|
||||
常驻服务;HTTP 需要外部进程守护,进程一掉工具就全空。stdio 由宿主拉起并在每次
|
||||
调用时自动重连握手,更稳。
|
||||
|
||||
## 校验方式
|
||||
|
||||
装好后对 agent 说“用图谱统计一下仓库规模”,应命中
|
||||
`plugin_crg_mcp_crg_list_graph_stats_tool` 并返回节点/边数量。
|
||||
|
|
@ -0,0 +1,57 @@
|
|||
@echo off
|
||||
chcp 65001 >nul
|
||||
setlocal
|
||||
|
||||
rem ---------------------------------------------------------------------------
|
||||
rem code-review-graph MCP launcher for PI-Desktop.
|
||||
rem
|
||||
rem The MCP host spawns this with a minimal environment (PATH, SystemRoot,
|
||||
rem windir, TEMP, TMP, LANG plus the manifest's env block) and cwd = plugin
|
||||
rem directory, with stdin/stdout used for JSON-RPC. Never write to stdout.
|
||||
rem ---------------------------------------------------------------------------
|
||||
|
||||
if defined CRG_HOME goto have_home
|
||||
set "CRG_HOME=D:\github-project\code-review-graph"
|
||||
:have_home
|
||||
|
||||
rem code_review_graph/constants.py calls Path.home() at import time; without a
|
||||
rem user profile the server dies with "Could not determine home directory.".
|
||||
if defined USERPROFILE goto have_profile
|
||||
set "USERPROFILE=C:\Users\%USERNAME%"
|
||||
:have_profile
|
||||
if defined HOMEDRIVE goto have_hd
|
||||
set "HOMEDRIVE=C:"
|
||||
:have_hd
|
||||
if defined HOMEPATH goto have_hp
|
||||
set "HOMEPATH=\Users\%USERNAME%"
|
||||
:have_hp
|
||||
if defined APPDATA set "APPDATA=%USERPROFILE%\AppData\Roaming"
|
||||
if defined LOCALAPPDATA set "LOCALAPPDATA=%USERPROFILE%\AppData\Local"
|
||||
|
||||
set "PYTHONUTF8=1"
|
||||
set "PYTHONIOENCODING=utf-8"
|
||||
|
||||
rem The editable install's .pth points at D:\github_project\... (underscore)
|
||||
rem while the checkout lives at D:\github-project\... (hyphen), so the package
|
||||
rem is only importable with the checkout explicitly on sys.path.
|
||||
set "PYTHONPATH=%CRG_HOME%"
|
||||
|
||||
rem The venv's code-review-graph.exe is a broken uv trampoline
|
||||
rem ("failed to canonicalize script path"), so prefer a working interpreter.
|
||||
set "CRG_PY=%CRG_HOME%\.venv\Scripts\python.exe"
|
||||
if exist "%CRG_PY%" goto py_ready
|
||||
set "CRG_PY=python"
|
||||
:py_ready
|
||||
|
||||
rem Upstream ships 30 tools; keep the surface small unless overridden.
|
||||
if defined CRG_TOOLS goto tools_ready
|
||||
set "CRG_TOOLS=build_or_update_graph_tool,run_postprocess_tool,get_minimal_context_tool,get_review_context_tool,get_impact_radius_tool,query_graph_tool,semantic_search_nodes_tool,detect_changes_tool,list_graph_stats_tool,get_affected_flows_tool"
|
||||
:tools_ready
|
||||
|
||||
if defined CRG_REPO goto repo_ready
|
||||
set "CRG_REPO=%CRG_HOME%"
|
||||
:repo_ready
|
||||
|
||||
"%CRG_PY%" -m code_review_graph serve --repo "%CRG_REPO%"
|
||||
|
||||
endlocal
|
||||
Binary file not shown.
|
|
@ -0,0 +1,18 @@
|
|||
/**
|
||||
* crg-mcp — thin loader for the code-review-graph MCP bridge.
|
||||
*
|
||||
* All of the wiring lives in manifest.json under `contributes.mcpServers`:
|
||||
* PI-Desktop spawns `crg.cmd` (stdio MCP), performs the handshake, and
|
||||
* publishes every upstream tool as `plugin_crg_mcp_crg_<tool>`. Nothing has
|
||||
* to be registered from here — the host owns the client, the retries, and the
|
||||
* tool lifecycle. This module only keeps the plugin loadable and offers a
|
||||
* place for future local helpers.
|
||||
*/
|
||||
|
||||
async function onLoad() {
|
||||
// The MCP client is owned by the host; no tool registration needed.
|
||||
}
|
||||
|
||||
async function onUnload() {}
|
||||
|
||||
module.exports = { onLoad, onUnload };
|
||||
|
|
@ -0,0 +1,33 @@
|
|||
{
|
||||
"schemaVersion": 1,
|
||||
"id": "crg-mcp",
|
||||
"name": "Code Review Graph MCP",
|
||||
"version": "1.0.0",
|
||||
"description": "Bridges the locally deployed code-review-graph MCP server (D:\\github-project\\code-review-graph) into the agent as native tools.",
|
||||
"main": "main.js",
|
||||
"contributes": {
|
||||
"mcpServers": [
|
||||
{
|
||||
"id": "crg",
|
||||
"label": "Code Review Graph",
|
||||
"transport": "stdio",
|
||||
"command": "crg.cmd",
|
||||
"env": {
|
||||
"PYTHONPATH": "D:\\github-project\\code-review-graph",
|
||||
"USERPROFILE": "C:\\Users\\admin",
|
||||
"HOMEDRIVE": "C:",
|
||||
"HOMEPATH": "\\Users\\admin"
|
||||
}
|
||||
}
|
||||
]
|
||||
},
|
||||
"permissions": [
|
||||
"mcp.server.local"
|
||||
],
|
||||
"engines": {
|
||||
"piDesktop": ">=0.1.0"
|
||||
},
|
||||
"activationEvents": [
|
||||
"onStartup"
|
||||
]
|
||||
}
|
||||
|
|
@ -0,0 +1,96 @@
|
|||
<#
|
||||
Self-check for the crg-mcp plugin.
|
||||
|
||||
Drives crg.cmd exactly the way the PI-Desktop MCP host does — `cmd /c crg.cmd`
|
||||
with piped stdio and cwd = this folder — then reports the MCP handshake, the
|
||||
tool list, and one real tool call. Run it from PowerShell:
|
||||
|
||||
powershell -NoProfile -ExecutionPolicy Bypass -File .\selfcheck.ps1
|
||||
#>
|
||||
$ErrorActionPreference = 'Stop'
|
||||
|
||||
$dir = Split-Path -Parent $MyInvocation.MyCommand.Path
|
||||
|
||||
# Mirror the host's minimal environment plus the manifest's env block.
|
||||
foreach ($k in 'PATH', 'SystemRoot', 'TEMP', 'TMP') {
|
||||
if (-not (Test-Path "Env:$k")) { Write-Warning "missing $k in ambient env" }
|
||||
}
|
||||
|
||||
$psi = New-Object System.Diagnostics.ProcessStartInfo
|
||||
$psi.FileName = 'cmd.exe'
|
||||
$psi.Arguments = '/c crg.cmd'
|
||||
$psi.WorkingDirectory = $dir
|
||||
$psi.RedirectStandardInput = $true
|
||||
$psi.RedirectStandardOutput = $true
|
||||
$psi.RedirectStandardError = $true
|
||||
$psi.UseShellExecute = $false
|
||||
$psi.StandardOutputEncoding = [System.Text.Encoding]::UTF8
|
||||
|
||||
$proc = [System.Diagnostics.Process]::Start($psi)
|
||||
|
||||
function Send($obj) {
|
||||
$proc.StandardInput.WriteLine(($obj | ConvertTo-Json -Compress -Depth 8))
|
||||
$proc.StandardInput.Flush()
|
||||
}
|
||||
|
||||
function ReadLine([int]$waitSeconds = 25) {
|
||||
$task = $proc.StandardOutput.ReadLineAsync()
|
||||
if ($task.Wait([TimeSpan]::FromSeconds($waitSeconds))) { return $task.Result }
|
||||
return $null
|
||||
}
|
||||
|
||||
Send @{
|
||||
jsonrpc = '2.0'; id = 1; method = 'initialize'
|
||||
params = @{
|
||||
protocolVersion = '2025-06-18'
|
||||
capabilities = @{}
|
||||
clientInfo = @{ name = 'crg-selfcheck'; version = '1' }
|
||||
}
|
||||
}
|
||||
|
||||
$initLine = ReadLine 40
|
||||
if (-not $initLine) {
|
||||
Write-Host 'HANDSHAKE FAILED: no stdout from crg.cmd' -ForegroundColor Red
|
||||
Write-Host '--- stderr ---'
|
||||
Write-Host $proc.StandardError.ReadToEnd()
|
||||
try { $proc.Kill() } catch { }
|
||||
exit 1
|
||||
}
|
||||
|
||||
$init = $initLine | ConvertFrom-Json
|
||||
Write-Host ("HANDSHAKE OK server={0} {1}" -f $init.result.serverInfo.name, $init.result.serverInfo.version) -ForegroundColor Green
|
||||
|
||||
Send @{ jsonrpc = '2.0'; method = 'notifications/initialized'; params = @{} }
|
||||
Send @{ jsonrpc = '2.0'; id = 2; method = 'tools/list'; params = @{} }
|
||||
|
||||
$toolsLine = ReadLine
|
||||
if (-not $toolsLine) {
|
||||
Write-Host 'tools/list returned nothing' -ForegroundColor Red
|
||||
try { $proc.Kill() } catch { }
|
||||
exit 1
|
||||
}
|
||||
$tools = ($toolsLine | ConvertFrom-Json).result.tools
|
||||
Write-Host ("TOOLS: {0}" -f $tools.Count) -ForegroundColor Green
|
||||
foreach ($t in $tools) { Write-Host (" plugin_crg_mcp_crg_{0}" -f $t.name) }
|
||||
|
||||
Send @{
|
||||
jsonrpc = '2.0'; id = 3; method = 'tools/call'
|
||||
params = @{ name = 'list_graph_stats_tool'; arguments = @{} }
|
||||
}
|
||||
$callLine = ReadLine 40
|
||||
if ($callLine) {
|
||||
$call = $callLine | ConvertFrom-Json
|
||||
if ($call.result) {
|
||||
$text = $call.result.content[0].text
|
||||
Write-Host 'TOOL CALL OK' -ForegroundColor Green
|
||||
Write-Host (' ' + ($text -split "`n")[0..3] -join ' | ')
|
||||
}
|
||||
else {
|
||||
Write-Host ("TOOL CALL ERROR: {0}" -f ($call | ConvertTo-Json -Compress -Depth 6)) -ForegroundColor Red
|
||||
}
|
||||
}
|
||||
else {
|
||||
Write-Host 'TOOL CALL: no response' -ForegroundColor Red
|
||||
}
|
||||
|
||||
try { $proc.Kill() } catch { }
|
||||
|
|
@ -0,0 +1,35 @@
|
|||
name: qwen3-asr
|
||||
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: ${ASR_IMAGE:-unis/qwen3-asr:cpu-latest}
|
||||
container_name: qwen3-asr-cpu
|
||||
ports:
|
||||
- "${NGINX_PORT:-17003}:8000"
|
||||
volumes:
|
||||
- ${DATA_STORAGE_DIR:-/opt/dep/asr/data}:/app/data
|
||||
- ${MODEL_STORAGE_DIR:-/opt/dep/asr/models}:/app/models
|
||||
environment:
|
||||
ACCELERATOR: cpu
|
||||
API_KEY: ${API_KEY:-}
|
||||
MODELS_DIR: /app/models
|
||||
DATA_DIR: /app/data
|
||||
TEMP_DIR: /app/data/temp
|
||||
LOG_FILE: /app/data/logs/qwen3-asr.log
|
||||
TASK_STATE_DIR: /app/data/tasks
|
||||
TASK_RETENTION_HOURS: ${TASK_RETENTION_HOURS:-24}
|
||||
MODELSCOPE_CACHE: /app
|
||||
MODELSCOPE_PATH: /app/models
|
||||
QWEN3_ASR_MODEL: ${QWEN3_ASR_MODEL:-}
|
||||
SPEAKER_DB_ENABLED: ${SPEAKER_DB_ENABLED:-true}
|
||||
DB_HOST: ${DB_HOST:-127.0.0.1}
|
||||
DB_PORT: ${DB_PORT:-5432}
|
||||
DB_USER: ${DB_USER:-postgres}
|
||||
DB_PASSWORD: ${DB_PASSWORD:-postgres}
|
||||
DB_NAME: ${DB_NAME:-asr_db}
|
||||
SV_MODEL: ${SV_MODEL:-iic/speech_campplus_sv_zh-cn_16k-common}
|
||||
SV_THRESHOLD: ${SV_THRESHOLD:-0.6}
|
||||
REALTIME_SESSION_RESUME_TTL_SEC: ${REALTIME_SESSION_RESUME_TTL_SEC:-120}
|
||||
NGINX_RATE_LIMIT_RPS: ${NGINX_RATE_LIMIT_RPS:-0}
|
||||
NGINX_RATE_LIMIT_BURST: ${NGINX_RATE_LIMIT_BURST:-0}
|
||||
restart: unless-stopped
|
||||
|
|
@ -0,0 +1,50 @@
|
|||
name: qwen3-asr-iluvatar
|
||||
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: ${ASR_IMAGE:-unis/qwen3-asr:iluvatar-latest}
|
||||
container_name: qwen3-asr-iluvatar
|
||||
network_mode: host
|
||||
pid: host
|
||||
ipc: host
|
||||
privileged: true
|
||||
cap_add:
|
||||
- ALL
|
||||
volumes:
|
||||
- ${ILUVATAR_USR_SRC:-/usr/src}:/usr/src
|
||||
- ${ILUVATAR_LIB_MODULES:-/lib/modules}:/lib/modules
|
||||
- ${ILUVATAR_DEV:-/dev}:/dev
|
||||
- ${ILUVATAR_HOME:-/home}:/home
|
||||
- ${ILUVATAR_DATA:-/data}:/data
|
||||
- ${DATA_STORAGE_DIR:-/opt/dep/asr/data}:/app/data
|
||||
- ${MODEL_STORAGE_DIR:-/opt/dep/asr/models}:/app/models
|
||||
environment:
|
||||
ACCELERATOR: iluvatar
|
||||
DEVICE: ${DEVICE:-auto}
|
||||
PORT: ${NGINX_PORT:-17003}
|
||||
API_KEY: ${API_KEY:-}
|
||||
MODELS_DIR: /app/models
|
||||
DATA_DIR: /app/data
|
||||
TEMP_DIR: /app/data/temp
|
||||
LOG_FILE: /app/data/logs/qwen3-asr.log
|
||||
TASK_STATE_DIR: /app/data/tasks
|
||||
TASK_RETENTION_HOURS: ${TASK_RETENTION_HOURS:-24}
|
||||
MODELSCOPE_CACHE: /app
|
||||
MODELSCOPE_PATH: /app/models
|
||||
QWEN3_ASR_MODEL: ${QWEN3_ASR_MODEL:-}
|
||||
ASR_DEPLOY_TOPOLOGY: ${ASR_DEPLOY_TOPOLOGY:-isolated}
|
||||
QWEN_GPU_MEMORY_UTILIZATION: ${QWEN_GPU_MEMORY_UTILIZATION:-}
|
||||
QWEN_VLLM_ENFORCE_EAGER: ${QWEN_VLLM_ENFORCE_EAGER:-true}
|
||||
SPEAKER_DB_ENABLED: ${SPEAKER_DB_ENABLED:-true}
|
||||
DB_HOST: ${DB_HOST:-127.0.0.1}
|
||||
DB_PORT: ${DB_PORT:-5432}
|
||||
DB_USER: ${DB_USER:-postgres}
|
||||
DB_PASSWORD: ${DB_PASSWORD:-postgres}
|
||||
DB_NAME: ${DB_NAME:-asr_db}
|
||||
SV_MODEL: ${SV_MODEL:-iic/speech_campplus_sv_zh-cn_16k-common}
|
||||
SV_THRESHOLD: ${SV_THRESHOLD:-0.6}
|
||||
REALTIME_SESSION_RESUME_TTL_SEC: ${REALTIME_SESSION_RESUME_TTL_SEC:-120}
|
||||
ASR_VISIBLE_DEVICES: ${ASR_VISIBLE_DEVICES:-0}
|
||||
NGINX_RATE_LIMIT_RPS: ${NGINX_RATE_LIMIT_RPS:-0}
|
||||
NGINX_RATE_LIMIT_BURST: ${NGINX_RATE_LIMIT_BURST:-0}
|
||||
restart: unless-stopped
|
||||
|
|
@ -0,0 +1,47 @@
|
|||
name: qwen3-asr-metax
|
||||
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: ${ASR_IMAGE:-unis/qwen3-asr:metax-latest}
|
||||
container_name: qwen3-asr-metax
|
||||
network_mode: host
|
||||
pid: host
|
||||
ipc: host
|
||||
privileged: true
|
||||
cap_add:
|
||||
- ALL
|
||||
volumes:
|
||||
- ${METAX_DEV:-/dev}:/dev
|
||||
- ${METAX_DRIVER_DIR:-/opt/mxdriver}:/opt/mxdriver:ro
|
||||
- ${DATA_STORAGE_DIR:-/opt/dep/asr/data}:/app/data
|
||||
- ${MODEL_STORAGE_DIR:-/opt/dep/asr/models}:/app/models
|
||||
environment:
|
||||
ACCELERATOR: metax
|
||||
DEVICE: ${DEVICE:-auto}
|
||||
PORT: ${NGINX_PORT:-17003}
|
||||
API_KEY: ${API_KEY:-}
|
||||
MODELS_DIR: /app/models
|
||||
DATA_DIR: /app/data
|
||||
TEMP_DIR: /app/data/temp
|
||||
LOG_FILE: /app/data/logs/qwen3-asr.log
|
||||
TASK_STATE_DIR: /app/data/tasks
|
||||
TASK_RETENTION_HOURS: ${TASK_RETENTION_HOURS:-24}
|
||||
MODELSCOPE_CACHE: /app
|
||||
MODELSCOPE_PATH: /app/models
|
||||
QWEN3_ASR_MODEL: ${QWEN3_ASR_MODEL:-}
|
||||
ASR_DEPLOY_TOPOLOGY: ${ASR_DEPLOY_TOPOLOGY:-isolated}
|
||||
QWEN_GPU_MEMORY_UTILIZATION: ${QWEN_GPU_MEMORY_UTILIZATION:-}
|
||||
QWEN_VLLM_ENFORCE_EAGER: ${QWEN_VLLM_ENFORCE_EAGER:-true}
|
||||
SPEAKER_DB_ENABLED: ${SPEAKER_DB_ENABLED:-true}
|
||||
DB_HOST: ${DB_HOST:-127.0.0.1}
|
||||
DB_PORT: ${DB_PORT:-5432}
|
||||
DB_USER: ${DB_USER:-postgres}
|
||||
DB_PASSWORD: ${DB_PASSWORD:-postgres}
|
||||
DB_NAME: ${DB_NAME:-asr_db}
|
||||
SV_MODEL: ${SV_MODEL:-iic/speech_campplus_sv_zh-cn_16k-common}
|
||||
SV_THRESHOLD: ${SV_THRESHOLD:-0.6}
|
||||
REALTIME_SESSION_RESUME_TTL_SEC: ${REALTIME_SESSION_RESUME_TTL_SEC:-120}
|
||||
ASR_VISIBLE_DEVICES: ${ASR_VISIBLE_DEVICES:-0}
|
||||
NGINX_RATE_LIMIT_RPS: ${NGINX_RATE_LIMIT_RPS:-0}
|
||||
NGINX_RATE_LIMIT_BURST: ${NGINX_RATE_LIMIT_BURST:-0}
|
||||
restart: unless-stopped
|
||||
|
|
@ -0,0 +1,50 @@
|
|||
name: qwen3-asr-mthreads
|
||||
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: ${ASR_IMAGE:-unis/qwen3-asr:mthreads-latest}
|
||||
container_name: qwen3-asr-mthreads
|
||||
network_mode: host
|
||||
pid: host
|
||||
ipc: host
|
||||
privileged: true
|
||||
cap_add:
|
||||
- ALL
|
||||
volumes:
|
||||
- ${MTHREADS_DEV:-/dev}:/dev
|
||||
- ${MTHREADS_USR_SRC:-/usr/src}:/usr/src
|
||||
- ${MTHREADS_LIB_MODULES:-/lib/modules}:/lib/modules
|
||||
- ${MTHREADS_HOME:-/home}:/home
|
||||
- ${MTHREADS_DATA:-/data}:/data
|
||||
- ${DATA_STORAGE_DIR:-/opt/dep/asr/data}:/app/data
|
||||
- ${MODEL_STORAGE_DIR:-/opt/dep/asr/models}:/app/models
|
||||
environment:
|
||||
ACCELERATOR: mthreads
|
||||
DEVICE: ${DEVICE:-auto}
|
||||
PORT: ${NGINX_PORT:-17003}
|
||||
API_KEY: ${API_KEY:-}
|
||||
MODELS_DIR: /app/models
|
||||
DATA_DIR: /app/data
|
||||
TEMP_DIR: /app/data/temp
|
||||
LOG_FILE: /app/data/logs/qwen3-asr.log
|
||||
TASK_STATE_DIR: /app/data/tasks
|
||||
TASK_RETENTION_HOURS: ${TASK_RETENTION_HOURS:-24}
|
||||
MODELSCOPE_CACHE: /app
|
||||
MODELSCOPE_PATH: /app/models
|
||||
QWEN3_ASR_MODEL: ${QWEN3_ASR_MODEL:-}
|
||||
ASR_DEPLOY_TOPOLOGY: ${ASR_DEPLOY_TOPOLOGY:-isolated}
|
||||
QWEN_GPU_MEMORY_UTILIZATION: ${QWEN_GPU_MEMORY_UTILIZATION:-}
|
||||
QWEN_VLLM_ENFORCE_EAGER: ${QWEN_VLLM_ENFORCE_EAGER:-true}
|
||||
SPEAKER_DB_ENABLED: ${SPEAKER_DB_ENABLED:-true}
|
||||
DB_HOST: ${DB_HOST:-127.0.0.1}
|
||||
DB_PORT: ${DB_PORT:-5432}
|
||||
DB_USER: ${DB_USER:-postgres}
|
||||
DB_PASSWORD: ${DB_PASSWORD:-postgres}
|
||||
DB_NAME: ${DB_NAME:-asr_db}
|
||||
SV_MODEL: ${SV_MODEL:-iic/speech_campplus_sv_zh-cn_16k-common}
|
||||
SV_THRESHOLD: ${SV_THRESHOLD:-0.6}
|
||||
REALTIME_SESSION_RESUME_TTL_SEC: ${REALTIME_SESSION_RESUME_TTL_SEC:-120}
|
||||
ASR_VISIBLE_DEVICES: ${ASR_VISIBLE_DEVICES:-0}
|
||||
NGINX_RATE_LIMIT_RPS: ${NGINX_RATE_LIMIT_RPS:-0}
|
||||
NGINX_RATE_LIMIT_BURST: ${NGINX_RATE_LIMIT_BURST:-0}
|
||||
restart: unless-stopped
|
||||
|
|
@ -0,0 +1,40 @@
|
|||
name: qwen3-asr
|
||||
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: ${ASR_IMAGE:-unis/qwen3-asr:gpu-latest}
|
||||
container_name: qwen3-asr
|
||||
ports:
|
||||
- "${NGINX_PORT:-17003}:8000"
|
||||
volumes:
|
||||
- ${DATA_STORAGE_DIR:-/opt/dep/asr/data}:/app/data
|
||||
- ${MODEL_STORAGE_DIR:-/opt/dep/asr/models}:/app/models
|
||||
runtime: nvidia
|
||||
environment:
|
||||
ACCELERATOR: nvidia
|
||||
API_KEY: ${API_KEY:-}
|
||||
MODELS_DIR: /app/models
|
||||
DATA_DIR: /app/data
|
||||
TEMP_DIR: /app/data/temp
|
||||
LOG_FILE: /app/data/logs/qwen3-asr.log
|
||||
TASK_STATE_DIR: /app/data/tasks
|
||||
TASK_RETENTION_HOURS: ${TASK_RETENTION_HOURS:-24}
|
||||
MODELSCOPE_CACHE: /app
|
||||
MODELSCOPE_PATH: /app/models
|
||||
QWEN3_ASR_MODEL: ${QWEN3_ASR_MODEL:-}
|
||||
ASR_DEPLOY_TOPOLOGY: ${ASR_DEPLOY_TOPOLOGY:-isolated}
|
||||
QWEN_VLLM_ENFORCE_EAGER: ${QWEN_VLLM_ENFORCE_EAGER:-true}
|
||||
SPEAKER_DB_ENABLED: ${SPEAKER_DB_ENABLED:-true}
|
||||
DB_HOST: ${DB_HOST:-127.0.0.1}
|
||||
DB_PORT: ${DB_PORT:-5432}
|
||||
DB_USER: ${DB_USER:-postgres}
|
||||
DB_PASSWORD: ${DB_PASSWORD:-postgres}
|
||||
DB_NAME: ${DB_NAME:-asr_db}
|
||||
SV_MODEL: ${SV_MODEL:-iic/speech_campplus_sv_zh-cn_16k-common}
|
||||
SV_THRESHOLD: ${SV_THRESHOLD:-0.6}
|
||||
REALTIME_SESSION_RESUME_TTL_SEC: ${REALTIME_SESSION_RESUME_TTL_SEC:-120}
|
||||
NVIDIA_VISIBLE_DEVICES: all
|
||||
ASR_VISIBLE_DEVICES: ${ASR_VISIBLE_DEVICES:-0}
|
||||
NGINX_RATE_LIMIT_RPS: ${NGINX_RATE_LIMIT_RPS:-0}
|
||||
NGINX_RATE_LIMIT_BURST: ${NGINX_RATE_LIMIT_BURST:-0}
|
||||
restart: unless-stopped
|
||||
|
|
@ -0,0 +1,606 @@
|
|||
<div align="center">
|
||||
|
||||
<h1>Qwen3-ASR</h1>
|
||||
<h3>开箱即用的本地私有化部署语音识别服务</h3>
|
||||
|
||||
以 [Qwen3-ASR](https://github.com/QwenLM/Qwen3-ASR) 为核心的语音识别 API 服务,提供 NVIDIA CUDA vLLM、沐曦 MACA vLLM 与 CPU Rust 后端,兼容阿里云语音 API 和 OpenAI Audio API,并保留 Paraformer realtime WebSocket 能力。
|
||||
|
||||
---
|
||||
|
||||

|
||||

|
||||

|
||||
|
||||
</div>
|
||||
|
||||
## 在线演示站点
|
||||
|
||||
- **在线体验**: https://asr.vect.one
|
||||
|
||||
## 演示
|
||||
|
||||
[](https://media.cdn.vect.one/qwenasr_client_demo.mp4)
|
||||
|
||||
## Release 1.0.1
|
||||
|
||||
> `v1.0.1` 是当前补丁版本。`v1.0.0` 相对于早期 `main` 分支引入了一轮大规模 breaking refactor。
|
||||
> 如果你是从 `main` 升级过来,请先阅读 release 说明,再决定是否沿用旧的部署与运行时假设。
|
||||
>
|
||||
> 关键 breaking changes:
|
||||
> - Python 依赖管理已经切到 `uv`(`pyproject.toml` + `uv.lock`),`requirements*.txt` 已移除
|
||||
> - 运行时栈改成 `NVIDIA/沐曦 GPU -> vLLM`、`CPU/macOS -> vendored QwenASR Rust`
|
||||
> - `MLX` / Apple Silicon GPU 路径已移除,`mps` 会归一化到 `cpu`
|
||||
> - macOS / Apple Silicon 现在默认总是 `qwen3-asr-0.6b`,可通过 `QWEN3_ASR_MODEL` 覆盖
|
||||
> - `ENABLED_MODELS` 已移除
|
||||
|
||||
## 主要特性
|
||||
|
||||
- **混合运行时栈** - 离线推理由自动选择的 Qwen3-ASR 提供,WebSocket 流式由 Paraformer realtime 能力提供
|
||||
- **说话人分离** - 基于 CAM++ 模型自动识别多说话人,返回说话人标记
|
||||
- **OpenAI API 兼容** - 支持 `/v1/audio/transcriptions` 端点,可直接使用 OpenAI SDK
|
||||
- **阿里云 API 兼容** - 支持阿里云语音识别 RESTful API 和 WebSocket 流式协议
|
||||
- **WebSocket 流式识别** - 支持实时流式语音识别,低延迟
|
||||
- **智能远场过滤** - 流式 ASR 自动过滤远场声音和环境音,减少误触发
|
||||
- **智能音频分段** - 基于 VAD 的贪婪合并算法,自动切分长音频,避免包含过长静音
|
||||
- **GPU 批处理加速** - 支持批量推理,比逐个处理快 2-3 倍
|
||||
- **资源感知运行时** - 根据当前机器资源自动选择合适的 Qwen3-ASR 模型
|
||||
|
||||
## 致谢
|
||||
|
||||
- [Qwen3-ASR](https://github.com/QwenLM/Qwen3-ASR) 提供官方模型与多模态 / vLLM 使用方式
|
||||
- [QwenASR](https://github.com/huanglizhuo/QwenASR) 提供本项目 vendored 的 CPU Rust backend
|
||||
|
||||
## 快速部署
|
||||
|
||||
### 1. Docker 部署(推荐)
|
||||
|
||||
```bash
|
||||
# 复制并编辑配置
|
||||
cp .env.example .env
|
||||
# 编辑 .env 设置 API_KEY(可选)
|
||||
|
||||
# Compose 默认挂载:
|
||||
# /opt/dep/asr/models -> /app/models
|
||||
# /opt/dep/asr/data -> /app/data
|
||||
# /opt/dep/asr/data/logs、temp、tasks 都在 data 挂载内
|
||||
|
||||
# 启动服务(NVIDIA GPU 版本)
|
||||
docker-compose up -d
|
||||
|
||||
# 或沐曦 GPU 版本
|
||||
docker-compose -f docker-compose-metax.yml up -d
|
||||
|
||||
# 或天数 GPU 版本
|
||||
docker-compose -f docker-compose-iluvatar.yml up -d
|
||||
|
||||
# 或摩尔线程 / MUSA GPU 版本
|
||||
docker-compose -f docker-compose-mthreads.yml up -d
|
||||
|
||||
# 或 CPU 版本
|
||||
docker-compose -f docker-compose-cpu.yml up -d
|
||||
|
||||
# NVIDIA 多卡自动模式(每张可见卡自动拉起 1 个实例)
|
||||
CUDA_VISIBLE_DEVICES=0,1,2,3 docker-compose up -d
|
||||
|
||||
# 沐曦多卡自动模式
|
||||
METAX_VISIBLE_DEVICES=0,1 docker-compose -f docker-compose-metax.yml up -d
|
||||
|
||||
# 天数多卡自动模式
|
||||
ILUVATAR_VISIBLE_DEVICES=0,1 docker-compose -f docker-compose-iluvatar.yml up -d
|
||||
|
||||
# 摩尔线程 / MUSA 多卡自动模式
|
||||
MTHREADS_VISIBLE_DEVICES=0,1 docker-compose -f docker-compose-mthreads.yml up -d
|
||||
```
|
||||
|
||||
服务访问地址:
|
||||
- **API 端点**: `http://localhost:17003`
|
||||
- **API 文档**: `http://localhost:17003/docs`
|
||||
|
||||
可选的内置限流参数:
|
||||
- `NGINX_RATE_LIMIT_RPS`(全局每秒请求上限,`0` 表示关闭)
|
||||
- `NGINX_RATE_LIMIT_BURST`(全局突发请求数,`0` 时自动使用 RPS)
|
||||
|
||||
**docker run 方式(替代):**
|
||||
|
||||
```bash
|
||||
# NVIDIA GPU 版本
|
||||
docker run -d --name qwen3-asr \
|
||||
--gpus all \
|
||||
-p 17003:8000 \
|
||||
-e ACCELERATOR=nvidia \
|
||||
-e CUDA_VISIBLE_DEVICES=0,1,2,3 \
|
||||
-e API_KEY=your_api_key \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
unis/qwen3-asr:gpu-latest
|
||||
|
||||
# 沐曦 GPU 版本
|
||||
docker run -d --name qwen3-asr-metax \
|
||||
--privileged \
|
||||
--network=host \
|
||||
--pid=host \
|
||||
--ipc=host \
|
||||
-v /dev:/dev \
|
||||
-v /opt/mxdriver:/opt/mxdriver:ro \
|
||||
-e ACCELERATOR=metax \
|
||||
-e PORT=17003 \
|
||||
-e METAX_VISIBLE_DEVICES=0 \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
unis/qwen3-asr:metax-latest
|
||||
|
||||
# CPU 版本
|
||||
docker run -d --name qwen3-asr \
|
||||
-p 17003:8000 \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
unis/qwen3-asr:cpu-latest
|
||||
```
|
||||
|
||||
默认推荐将宿主机目录统一挂载到 `/opt/dep/asr` 下,模型目录结构如下:
|
||||
|
||||
```text
|
||||
/opt/dep/asr/models/
|
||||
Qwen/
|
||||
iic/
|
||||
damo/
|
||||
```
|
||||
|
||||
如果你希望改成自定义目录,也可以在启动前设置:
|
||||
|
||||
```bash
|
||||
export MODEL_STORAGE_DIR=/data/qwen3-asr-models
|
||||
export DATA_STORAGE_DIR=/data/qwen3-asr-data
|
||||
```
|
||||
|
||||
> **注意**: NVIDIA GPU 镜像默认使用 CUDA 13.0/cu130,并固定 `torch 2.11.0` + `vllm 0.20.0`。
|
||||
> 开发者可通过 Docker build args 自行构建 CUDA 12.6、CUDA 13.0 或其他后端组合。
|
||||
> 沐曦镜像使用 `Dockerfile.metax` 基于沐曦官方 vLLM 镜像融合本项目。现场部署使用 host network、privileged,并挂载 `/dev` 与 `/opt/mxdriver`,确保 `mx-smi` 查询和沐曦 PyTorch 运行时都能初始化设备。
|
||||
> 当前 CPU 镜像已通过内置 QwenASR Rust backend 支持 `qwen3-asr-0.6b`。默认 CPU 镜像使用可分发 Rust 构建目标;只有自建且构建机/部署机 CPU 同构时才建议设置 `QWENASR_RUST_TARGET_CPU=native`。
|
||||
> CUDA vLLM 与 CPU Rust 路径下,`word_timestamps=true` 都会自动调用 forced aligner;当前实际后端为 `CUDA -> vLLM`、`CPU/macOS -> vendored QwenASR Rust`。
|
||||
> Apple Silicon 上的 Qwen3-ASR 现已统一走 Rust CPU backend。
|
||||
> `start.py` 现在会强制把 vLLM 多进程方式设为 `spawn`,避免 CUDA 在 fork 子进程中重复初始化导致启动失败。
|
||||
|
||||
**自定义 GPU 后端构建:**
|
||||
|
||||
```bash
|
||||
# 默认 GPU 构建:CUDA 13.0 / PyTorch cu130
|
||||
docker build -t qwen3-asr:gpu-cu130 -f Dockerfile.gpu .
|
||||
|
||||
# CUDA 12.6 构建,用于旧部署环境
|
||||
docker build -t qwen3-asr:gpu-cu126 -f Dockerfile.gpu \
|
||||
--build-arg PYTORCH_BASE_IMAGE=pytorch/pytorch:2.11.0-cuda12.6-cudnn9-runtime \
|
||||
--build-arg PYTORCH_CUDA_INDEX=https://download.pytorch.org/whl/cu126 \
|
||||
--build-arg CUDA_NVCC_PACKAGE=cuda-nvcc-12-6 \
|
||||
--build-arg TORCH_CUDA_ARCH_LIST="8.0;8.6;8.9" \
|
||||
.
|
||||
|
||||
# CUDA 13.0 构建,用于需要 CUDA 13 工具链的环境
|
||||
docker build -t qwen3-asr:gpu-cu130 -f Dockerfile.gpu \
|
||||
--build-arg PYTORCH_BASE_IMAGE=pytorch/pytorch:2.11.0-cuda13.0-cudnn9-runtime \
|
||||
--build-arg PYTORCH_CUDA_INDEX=https://download.pytorch.org/whl/cu130 \
|
||||
--build-arg CUDA_NVCC_PACKAGE=cuda-nvcc-13-0 \
|
||||
--build-arg TORCH_CUDA_ARCH_LIST="12.0+PTX" \
|
||||
.
|
||||
|
||||
# 沐曦构建:基于沐曦官方 vLLM 镜像融合本项目
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor metax \
|
||||
--base-image <沐曦官方vLLM镜像名> \
|
||||
-v n260-3.7.0.38
|
||||
|
||||
# 天数构建:基于天数官方 vLLM 镜像融合本项目
|
||||
docker pull registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor iluvatar \
|
||||
--base-image registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5 \
|
||||
-v vllm0.17.0-4.4.0-v5
|
||||
|
||||
# 摩尔线程构建:基于摩尔线程官方 MUSA vLLM 镜像融合本项目
|
||||
docker pull registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor mthreads \
|
||||
--base-image registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519 \
|
||||
-v s4000_4.3.5_d0519
|
||||
```
|
||||
|
||||
沐曦 GPU 国产化离线交付请优先参考 [沐曦 GPU 国产化离线部署指南](./metax_offline_deployment.md)。
|
||||
天数 GPU 国产化离线交付请优先参考 [天数 GPU 国产化离线部署指南](./iluvatar_offline_deployment.md)。
|
||||
摩尔线程 GPU 国产化离线交付请优先参考 [摩尔线程 GPU 国产化离线部署指南](./mthreads_offline_deployment.md)。
|
||||
|
||||
**内网部署**:现在可以直接生成一个带时间戳和 CPU/GPU 标识的离线交付目录,里面包含镜像包、compose、`.env` 模板、目录初始化脚本和使用说明。离线导出脚本使用普通 `docker build` + `docker save`,不依赖 `buildx`:
|
||||
|
||||
```bash
|
||||
# 1. 生成离线交付目录
|
||||
./export_offline_bundle.sh --type gpu
|
||||
# 或
|
||||
./export_offline_bundle.sh --type cpu
|
||||
# 或沐曦 GPU
|
||||
./export_offline_bundle.sh \
|
||||
--type metax \
|
||||
--metax-base cr.metax-tech.com/public-ai-release/maca/vllm-metax:0.17.0-maca.ai3.5.3.307-torch2.8-py312-ubuntu22.04-amd64 \
|
||||
--skip-models
|
||||
# 或天数 GPU
|
||||
./export_offline_bundle.sh --type iluvatar --iluvatar-base registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
# 或摩尔线程 GPU
|
||||
./export_offline_bundle.sh --type mthreads --mthreads-base registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519
|
||||
# 或一次同时打包 GPU + CPU
|
||||
./export_offline_bundle.sh --type all
|
||||
|
||||
# 2. 单独准备模型,不删除已有模型文件
|
||||
./scripts/download-models.sh --models-dir /opt/dep/asr/models
|
||||
|
||||
# 3. 把交付目录复制到内网服务器
|
||||
scp -r build-file/<时间戳>-all user@server:/opt/dep/asr/
|
||||
|
||||
# 4. 在内网服务器上导入并启动
|
||||
cd /opt/dep/asr/<时间戳>-all
|
||||
./init_host_dirs.sh
|
||||
gunzip -c qwen3-asr-gpu-<时间戳>-amd64.tar.gz | docker load
|
||||
gunzip -c qwen3-asr-cpu-<时间戳>-amd64.tar.gz | docker load
|
||||
# NVIDIA GPU
|
||||
docker compose up -d
|
||||
# 或沐曦 GPU
|
||||
# docker compose -f docker-compose-metax.yml up -d
|
||||
# 或天数 GPU
|
||||
# docker compose -f docker-compose-iluvatar.yml up -d
|
||||
# 或摩尔线程 GPU
|
||||
# docker compose -f docker-compose-mthreads.yml up -d
|
||||
# 或 CPU
|
||||
# docker compose -f docker-compose-cpu.yml up -d
|
||||
```
|
||||
|
||||
> 详细部署说明请查看 [部署指南](./deployment.md)
|
||||
|
||||
### 本地开发
|
||||
|
||||
**系统要求:**
|
||||
|
||||
- Python 3.10+
|
||||
- 默认 GPU 镜像要求 CUDA 13.0+;CUDA 12.6 / 13.0 可通过 Docker build args 自行构建
|
||||
- FFmpeg (音频格式转换)
|
||||
|
||||
**安装步骤:**
|
||||
|
||||
运行时依赖现在改成“根目录默认 GPU,CPU 单独特化环境”:
|
||||
|
||||
| 模式 | 命令 | 说明 |
|
||||
|------|------|------|
|
||||
| NVIDIA GPU(默认) | `uv sync` 或 `./scripts/sync_gpu_env.sh` | 同步根目录 [pyproject.toml](/opt/qwen3-asr/pyproject.toml) 和 [uv.lock](/opt/qwen3-asr/uv.lock) 到 `.venv`,包含 CUDA 13.0/cu130 `torch 2.11.0` / `torchaudio 2.11.0` / `torchvision 0.26.0` / `vllm 0.20.0` |
|
||||
| 沐曦 GPU | `./scripts/sync_metax_env.sh` | 同步 [environments/metax/pyproject.toml](/opt/qwen3-asr/environments/metax/pyproject.toml) 的公共依赖;可选 GPU 栈安装默认从沐曦 MACA PyPI 源按 `--no-deps` 安装 |
|
||||
| 天数 GPU | `./scripts/sync_iluvatar_env.sh` | 同步 [environments/iluvatar/pyproject.toml](/opt/qwen3-asr/environments/iluvatar/pyproject.toml) 的公共依赖;GPU 栈建议来自天数官方 vLLM 镜像 |
|
||||
| 摩尔线程 GPU | `./scripts/sync_mthreads_env.sh` | 同步 [environments/mthreads/pyproject.toml](/opt/qwen3-asr/environments/mthreads/pyproject.toml) 的公共依赖;GPU 栈建议来自摩尔线程官方 MUSA vLLM 镜像 |
|
||||
| CPU(特化) | `./scripts/sync_cpu_env.sh` | 同步 [environments/cpu/pyproject.toml](/opt/qwen3-asr/environments/cpu/pyproject.toml) 对应的 CPU lock 到 `.venv` |
|
||||
| 自动 | `./scripts/sync_accel_env.sh` | 有 `mx-smi` 时选择沐曦,有 `ixsmi` 时选择天数,有 `mthreads-gmi` 时选择摩尔线程,有 `nvidia-smi` 时选择 NVIDIA,否则选择 CPU |
|
||||
|
||||
```bash
|
||||
# 克隆项目
|
||||
cd qwen3-asr
|
||||
|
||||
# 安装依赖(Linux/NVIDIA CUDA)
|
||||
uv sync
|
||||
|
||||
# 启动服务
|
||||
source .venv/bin/activate
|
||||
python start.py
|
||||
```
|
||||
|
||||
沐曦本地开发:
|
||||
|
||||
```bash
|
||||
./scripts/sync_metax_env.sh
|
||||
source .venv/bin/activate
|
||||
ACCELERATOR=metax python start.py
|
||||
```
|
||||
|
||||
macOS / Apple Silicon 本地开发:
|
||||
|
||||
```bash
|
||||
./scripts/sync_cpu_env.sh
|
||||
source .venv/bin/activate
|
||||
python start.py
|
||||
```
|
||||
|
||||
## 当前运行时默认值
|
||||
|
||||
当前主线代码的运行时行为如下:
|
||||
|
||||
- `ACCELERATOR=auto` 会优先识别 `mx-smi` 上报的沐曦设备,其次识别 `ixsmi` 上报的天数设备,再识别 `mthreads-gmi` 上报的摩尔线程设备,再识别 NVIDIA CUDA,否则回落 CPU
|
||||
- `DEVICE=auto`
|
||||
- NVIDIA/沐曦/天数 GPU 时解析为 `cuda:0`
|
||||
- 否则解析为 `cpu`
|
||||
- `DEVICE=mps` 会直接归一化为 `cpu`
|
||||
- `Linux + NVIDIA CUDA` 使用官方 `vLLM`
|
||||
- `Linux + 沐曦 MACA` 使用沐曦兼容 PyTorch/vLLM 运行栈
|
||||
- `Linux + 天数` 使用天数官方 vLLM 镜像运行栈
|
||||
- `Linux + CPU` 使用 vendored `QwenASR` Rust
|
||||
- `macOS / Apple Silicon` 也使用 vendored `QwenASR` Rust
|
||||
- macOS / Apple Silicon 默认总是 `qwen3-asr-0.6b`
|
||||
- 在 macOS 上,只有设置 `QWEN3_ASR_MODEL=qwen3-asr-1.7b` 时才会使用 `qwen3-asr-1.7b`
|
||||
- `word_timestamps=true` 在当前离线 CUDA 与 CPU Rust 路径下可用
|
||||
- WebSocket 流式路径当前不返回词级时间戳
|
||||
- CAM++ 说话人分离仍然必须保留,并继续跟随 `DEVICE`;在 CPU 上的主要热点仍是 speaker verification embedding
|
||||
|
||||
## API 接口
|
||||
|
||||
### OpenAI 兼容接口
|
||||
|
||||
| 端点 | 方法 | 功能 |
|
||||
| ---------------------------- | ---- | ----------------------- |
|
||||
| `/v1/audio/transcriptions` | POST | 音频转写(OpenAI 兼容) |
|
||||
| `/v1/models` | GET | 离线模型列表 |
|
||||
|
||||
**请求参数:**
|
||||
|
||||
| 参数 | 类型 | 默认值 | 说明 |
|
||||
| ------------------------------ | ------ | --------------------- | ------------------------------------- |
|
||||
| `file` | file | 提供时优先使用 | 音频/视频文件 |
|
||||
| `audio_address` | string | 可选 | 音频/视频文件 URL(HTTP/HTTPS)、`file://` 或服务端本地路径;若同时提供 `file`,则忽略 |
|
||||
| `language` | string | 自动检测 | 语言代码 (zh/en/ja) |
|
||||
| `enable_speaker_diarization` | bool | `true` | 启用说话人分离 |
|
||||
| `enable_speaker_identification` | bool | `true` | 说话人分离开启时匹配已注册声纹库 |
|
||||
| `enable_text_cleanup` | bool | `true` | 启用文本去重、跨段重叠裁剪和口头语清理 |
|
||||
| `word_timestamps` | bool | `false` | 返回后端支持的字词级时间戳;Qwen CUDA vLLM 与 CPU Rust 在启用时会自动调用 forced aligner |
|
||||
| `hotwords` | string | - | 热词,格式:`词1 权重1 词2 权重2` |
|
||||
| `response_format` | string | `verbose_json` | 输出格式 |
|
||||
| `prompt` | string | - | 提示文本(保留兼容) |
|
||||
| `temperature` | float | `0` | 采样温度(保留兼容) |
|
||||
|
||||
**音频/视频输入方式:**
|
||||
- **文件上传**: 使用 `file` 参数上传音频文件或带音轨的视频容器
|
||||
- **URL / 本地路径读取**: 使用 `audio_address` 参数提供音频/视频 URL 或服务端本地路径,服务将自动读取
|
||||
- **优先级**: 如果同时提供 `file` 和 `audio_address`,服务会优先使用 `file`,并忽略 `audio_address`
|
||||
|
||||
**使用示例:**
|
||||
|
||||
```python
|
||||
# 使用 OpenAI SDK
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(base_url="http://localhost:8000/v1", api_key="your_api_key")
|
||||
|
||||
with open("audio.wav", "rb") as f:
|
||||
transcript = client.audio.transcriptions.create(
|
||||
file=f,
|
||||
response_format="verbose_json" # 获取分段和说话人信息
|
||||
)
|
||||
print(transcript.text)
|
||||
```
|
||||
|
||||
```bash
|
||||
# 使用 curl
|
||||
curl -X POST "http://localhost:8000/v1/audio/transcriptions" \
|
||||
-H "Authorization: Bearer your_api_key" \
|
||||
-F "file=@audio.wav" \
|
||||
-F "model=qwen3-asr-0.6b" \
|
||||
-F "response_format=verbose_json" \
|
||||
-F "enable_speaker_diarization=true" \
|
||||
-F "enable_speaker_identification=true" \
|
||||
-F "enable_text_cleanup=true" \
|
||||
-F "hotwords=Qwen 2.0 ModelScope 1.5"
|
||||
```
|
||||
|
||||
**支持的响应格式:** `json`, `text`, `srt`, `vtt`, `verbose_json`
|
||||
|
||||
### 阿里云兼容接口
|
||||
|
||||
| 端点 | 方法 | 功能 |
|
||||
| ------------------------- | --------- | ---------------------- |
|
||||
| `/stream/v1/asr` | POST | 语音识别(支持长音频) |
|
||||
| `/stream/v1/asr/models` | GET | 声明条目列表 |
|
||||
| `/stream/v1/asr/health` | GET | 健康检查 |
|
||||
| `/ws/v1/asr` | WebSocket | Qwen3-ASR 流式识别 |
|
||||
| `/ws/v1/asr/qwen` | WebSocket | Qwen3-ASR 流式识别(显式路径) |
|
||||
| `/ws/v1/asr/funasr` | WebSocket | 已移除;会返回废弃错误并提示切换到 `/ws/v1/asr/qwen` |
|
||||
|
||||
**请求参数:**
|
||||
|
||||
| 参数 | 类型 | 默认值 | 说明 |
|
||||
| ------------------------------ | ------ | ------------------ | ------------------------------------- |
|
||||
| `audio_address` | string | `https://media.cdn.vect.one/podcast_demo.mp4`(文档示例) | 音频/视频 URL、`file://` 或服务端本地路径(可选;若同时上传内容则忽略) |
|
||||
| `sample_rate` | int | `16000` | 采样率 |
|
||||
| `enable_speaker_diarization` | bool | `true` | 启用说话人分离 |
|
||||
| `enable_speaker_identification` | bool | `true` | 说话人分离开启时匹配已注册声纹库 |
|
||||
| `enable_text_cleanup` | bool | `true` | 启用文本去重、跨段重叠裁剪和口头语清理 |
|
||||
| `word_timestamps` | bool | `false` | 返回后端支持的字词级时间戳;Qwen CUDA vLLM 与 CPU Rust 在启用时会自动调用 forced aligner |
|
||||
| `vocabulary_id` | string | - | 热词(格式:`词1 权重1 词2 权重2`) |
|
||||
|
||||
**使用示例:**
|
||||
|
||||
```bash
|
||||
# 基本用法
|
||||
curl -X POST "http://localhost:8000/stream/v1/asr" \
|
||||
-H "Content-Type: application/octet-stream" \
|
||||
--data-binary @audio.wav
|
||||
|
||||
# 带参数
|
||||
curl -X POST "http://localhost:8000/stream/v1/asr?enable_speaker_diarization=true&enable_speaker_identification=true&enable_text_cleanup=true&vocabulary_id=Qwen%202.0%20ModelScope%201.5" \
|
||||
-H "Content-Type: application/octet-stream" \
|
||||
--data-binary @audio.wav
|
||||
```
|
||||
|
||||
### 会议离线接口
|
||||
|
||||
| 端点 | 方法 | 功能 |
|
||||
| ---- | ---- | ---- |
|
||||
| `/api/v1/asr/transcriptions` | POST | 创建离线会议识别任务 |
|
||||
| `/api/v1/asr/transcriptions/{task_id}` | GET | 查询任务状态和结果 |
|
||||
|
||||
该接口生产调用只使用 `audio_address`。
|
||||
|
||||
```json
|
||||
{
|
||||
"audio_address": "https://example.com/media/meeting.mp4",
|
||||
"config": {
|
||||
"enable_speaker": true,
|
||||
"match_speaker_registry": true,
|
||||
"enable_text_cleanup": true,
|
||||
"speaker_threshold": 0.6,
|
||||
"word_timestamps": false,
|
||||
"hotwords": [
|
||||
{ "hotword": "通义千问", "weight": 2.0 },
|
||||
{ "hotword": "ModelScope", "weight": 1.5 }
|
||||
]
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
**响应示例:**
|
||||
|
||||
```json
|
||||
{
|
||||
"task_id": "xxx",
|
||||
"status": 200,
|
||||
"message": "SUCCESS",
|
||||
"result": "说话人1的内容...\n说话人2的内容...",
|
||||
"duration": 60.5,
|
||||
"processing_time": 1.234,
|
||||
"segments": [
|
||||
{
|
||||
"text": "今天天气不错。",
|
||||
"start_time": 0.0,
|
||||
"end_time": 2.5,
|
||||
"speaker_id": "说话人1",
|
||||
"word_tokens": [
|
||||
{"text": "今天", "start_time": 0.0, "end_time": 0.5},
|
||||
{"text": "天气", "start_time": 0.5, "end_time": 0.9},
|
||||
{"text": "不错", "start_time": 0.9, "end_time": 1.3}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
## 说话人分离
|
||||
|
||||
基于 CAM++ 模型实现多说话人自动识别:
|
||||
|
||||
- **默认开启** - `enable_speaker_diarization=true`
|
||||
- **自动识别** - 无需预设说话人数量,模型自动检测
|
||||
- **说话人标记** - 响应中包含 `speaker_id` 字段(如 "说话人1"、"说话人2")
|
||||
- **智能合并** - 两层合并策略避免孤立短片段:
|
||||
- 第一层:小于10秒的同说话人片段累积合并
|
||||
- 第二层:连续片段累积合并至60秒上限
|
||||
- **字幕支持** - SRT/VTT 格式输出包含说话人标记 `[说话人1] 文本内容`
|
||||
|
||||
关闭说话人分离:
|
||||
|
||||
```bash
|
||||
# OpenAI API
|
||||
-F "enable_speaker_diarization=false"
|
||||
|
||||
# 阿里云 API
|
||||
?enable_speaker_diarization=false
|
||||
```
|
||||
|
||||
## 音频处理
|
||||
|
||||
### 智能分段策略
|
||||
|
||||
长音频自动分段处理:
|
||||
|
||||
1. **VAD 语音检测** - 检测语音边界,过滤静音
|
||||
2. **贪婪合并** - 累积语音段,确保每段不超过 `MAX_SEGMENT_SEC`(默认60秒)
|
||||
3. **静音切分** - 语音段间静音超过3秒时强制切分,避免包含过长静音
|
||||
4. **批处理推理** - 多片段并行处理,GPU 模式下性能提升 2-3 倍
|
||||
|
||||
### WebSocket 流式识别限制
|
||||
|
||||
**Qwen3-ASR 流式**(使用 `/ws/v1/asr` 或 `/ws/v1/asr/qwen`):
|
||||
- ✅ 支持多语言实时识别
|
||||
- ✅ 当前支持 CUDA vLLM 与 CPU Rust 两条流式路径
|
||||
- ❌ 当前流式路径不返回词级时间戳
|
||||
|
||||
### Qwen3 运行时矩阵
|
||||
|
||||
| 运行环境 | 后端 | 离线转写 | WebSocket 流式 | 离线词级时间戳 | 流式词级时间戳 | 成熟度 |
|
||||
|---------|------|---------|----------------|----------------|----------------|--------|
|
||||
| Linux + NVIDIA GPU | 官方 vLLM 0.20.0 | ✅ | ✅ | ✅ | ❌ | 面向生产 |
|
||||
| CPU / macOS | QwenASR Rust | ✅ | ✅ | ✅(forced aligner) | ❌ | 推荐本地后端 |
|
||||
|
||||
## 支持离线的模型
|
||||
|
||||
| 模型 ID | 名称 | 说明 | 特性 |
|
||||
| -------------------- | ----------------- | ---------------------------------------- | --------- |
|
||||
| `qwen3-asr-1.7b` | Qwen3-ASR 1.7B | 高性能多语言 ASR;CUDA 使用 vLLM | 离线/实时 |
|
||||
| `qwen3-asr-0.6b` | Qwen3-ASR 0.6B | 轻量版多语言 ASR;CUDA 使用 vLLM,CPU/macOS 使用 Rust backend | 离线/实时 |
|
||||
|
||||
**运行时选择:**
|
||||
- **显存 >= 32GB**: 选择 `qwen3-asr-1.7b`
|
||||
- **显存 < 32GB**: 选择 `qwen3-asr-0.6b`
|
||||
- **无 CUDA**: 选择基于 vendored Rust 的 `qwen3-asr-0.6b`
|
||||
- **macOS / Apple Silicon**: 无论内存大小多少,默认都选择 `qwen3-asr-0.6b`
|
||||
- **环境变量覆盖**: 设置 `QWEN3_ASR_MODEL=qwen3-asr-1.7b` 或 `QWEN3_ASR_MODEL=qwen3-asr-0.6b` 可跳过自动选择
|
||||
|
||||
启动时会先检测当前运行计划所需模型;如果本地缓存缺失,会自动从 ModelScope 下载。离线部署请提前准备模型缓存。
|
||||
|
||||
## 环境变量
|
||||
|
||||
推荐直接关心的公开配置:
|
||||
|
||||
| 变量 | 默认值 | 说明 |
|
||||
| ---------------------------------- | ------------ | ----------------------------------------------- |
|
||||
| `API_KEY` | - | API 认证密钥(可选,未配置时无需认证) |
|
||||
| `LOG_LEVEL` | `INFO` | 日志级别(DEBUG/INFO/WARNING/ERROR) |
|
||||
| `MAX_AUDIO_SIZE` | `2048` | 最大音频文件大小(MB,支持单位如 2GB) |
|
||||
| `ASR_BATCH_SIZE` | `4` | 长音频分段后的 ASR 批处理大小 |
|
||||
| `MAX_SEGMENT_SEC` | `60` | 音频分段最大时长(秒) |
|
||||
| `ASR_ENABLE_NEARFIELD_FILTER` | `true` | 启用远场声音过滤 |
|
||||
| `QWEN3_ASR_MODEL` | 自动选择 | 强制选择 `qwen3-asr-1.7b` 或 `qwen3-asr-0.6b` |
|
||||
| `QWEN_GPU_MEMORY_UTILIZATION` | `0.9` | vLLM 可保留的 GPU 显存上限;共享显卡时可调低,KV cache 不足时可适当调高 |
|
||||
| `QWEN_VLLM_ENFORCE_EAGER` | `true` | 强制 vLLM eager 执行以提高兼容性;NVIDIA 性能测试可设为 `false` 允许 CUDA Graph 优化 |
|
||||
|
||||
远场过滤调优建议:
|
||||
|
||||
- `ASR_NEARFIELD_RMS_THRESHOLD=0.01` 是当前默认值,也是推荐起点
|
||||
- 嘈杂环境可以适当调高,增强背景语音过滤
|
||||
- 安静环境如果出现小声说话漏识别,可以适当调低
|
||||
- 需要观察过滤行为时,可临时设置 `LOG_LEVEL=DEBUG`
|
||||
|
||||
后端专项高级配置:
|
||||
|
||||
| 变量 | 默认值 | 说明 |
|
||||
| --- | --- | --- |
|
||||
| `QWEN_RUST_CPU_WORKERS` | `4` | CPU Rust backend worker 数(Rust ASR / forced align 默认 4 个 runtime) |
|
||||
| `QWENASR_LIBRARY_PATH` | 自动探测 | 覆盖 vendored Rust 动态库路径 |
|
||||
|
||||
## 资源需求
|
||||
|
||||
**最小配置(CPU):**
|
||||
|
||||
- CPU: 4 核
|
||||
- 内存: 16GB
|
||||
- 磁盘: 20GB
|
||||
|
||||
**推荐配置(GPU):**
|
||||
|
||||
- CPU: 4 核
|
||||
- 内存: 16GB
|
||||
- GPU: NVIDIA GPU (16GB+ 显存)
|
||||
- 磁盘: 20GB
|
||||
|
||||
## API 文档
|
||||
|
||||
启动服务后访问:
|
||||
|
||||
- Swagger UI: `http://localhost:8000/docs`
|
||||
- ReDoc: `http://localhost:8000/redoc`
|
||||
|
||||
## 相关链接
|
||||
|
||||
- **部署指南**: [详细文档](./deployment.md)
|
||||
- **Qwen3-ASR**: [Qwen3-ASR GitHub](https://github.com/QwenLM/Qwen3-ASR)
|
||||
- **FunASR**: [FunASR GitHub](https://github.com/alibaba-damo-academy/FunASR)
|
||||
- **QwenASR**: [QwenASR GitHub](https://github.com/huanglizhuo/QwenASR)
|
||||
|
||||
## 许可证
|
||||
|
||||
本项目采用 MIT 许可证 - 查看 [LICENSE](../LICENSE) 文件了解详情。
|
||||
|
||||
## Star 历史
|
||||
|
||||
[](https://star-history.com/#Quantatirsk/qwen3-asr&Date)
|
||||
|
||||
## 贡献
|
||||
|
||||
欢迎提交 Issue 和 Pull Request 来改进项目!
|
||||
|
|
@ -0,0 +1,382 @@
|
|||
# 实时 ASR WebSocket 处理细节对照
|
||||
|
||||
本文只整理当前代码,不修改 WebSocket 或说话人算法。对照对象是:
|
||||
|
||||
- 当前独立 Demo:`demo/realtime_asr_optimization_demo`
|
||||
- 原项目实时接口:`app/api/v1/websocket_asr.py`、`app/services/qwen3_websocket_asr.py`、`app/services/realtime_speaker_clusterer.py`
|
||||
|
||||
代码是本文的依据;旧的排查记录或早期说明如果与当前实现冲突,以代码为准。
|
||||
|
||||
## 1. 先看整体差异
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant B as 浏览器
|
||||
participant D as 当前 Demo /ws
|
||||
participant V as 独立 vLLM HTTP
|
||||
participant A as 独立辅助服务
|
||||
|
||||
B->>D: start(扁平字段)
|
||||
B->>D: PCM/WAV 二进制帧
|
||||
D->>D: 20ms RMS 门控、turn 缓冲、静音切段
|
||||
D->>V: 当前 turn 的累积 WAV(partial/final)
|
||||
V-->>D: 文本
|
||||
D-->>B: sentences + display_state
|
||||
D->>A: final turn + session_id
|
||||
A-->>D: CAM++ embedding / 在线聚类标签
|
||||
D-->>B: 同 sentence_id 的 speaker 更新 + 新 display_state
|
||||
B->>D: eof 或 stop
|
||||
D->>D: 等待音频队列和 speaker 队列清空
|
||||
D-->>B: end
|
||||
```
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant B as 浏览器
|
||||
participant R as 原项目 FastAPI 路由
|
||||
participant Q as Qwen3ASRService
|
||||
participant E as Qwen3ASREngine
|
||||
participant S as RealtimeSpeakerClusterer
|
||||
|
||||
B->>R: /ws/v1/asr 或 /ws/v1/asr/qwen
|
||||
R->>Q: handle_connection
|
||||
B->>Q: start.payload(嵌套字段)
|
||||
Q-->>B: voice_id、start
|
||||
B->>Q: PCM/WAV 二进制帧
|
||||
Q->>Q: 转采样、VAD、pre-roll、partial
|
||||
Q->>E: 原生流式或当前窗口重转写
|
||||
E-->>Q: partial 文本
|
||||
Q-->>B: sentence_type=0
|
||||
Q->>E: 当前 turn 全量 final 重转写
|
||||
E-->>Q: final 文本
|
||||
Q-->>B: sentence_type=1、speaker_id=-1
|
||||
Q->>S: speaker_job_queue(异步)
|
||||
S-->>Q: 聚类/注册库匹配
|
||||
Q-->>B: 相同 sentence_id 的 speaker 回写
|
||||
B->>Q: stop
|
||||
Q-->>B: end(stop 内部会再次 final/recluster)
|
||||
```
|
||||
|
||||
核心设计差别是:当前 Demo 把 ASR 和声纹都放在独立 HTTP 服务后面,WebSocket 只做编排;原项目把 Qwen ASR 引擎、VAD、在线声纹聚类放在同一个服务进程里,但 speaker 归属仍是 final 之后异步补回。
|
||||
|
||||
## 2. 当前独立 Demo 的处理链路
|
||||
|
||||
### 2.1 进程和启动关系
|
||||
|
||||
`server.py` 启动一个 aiohttp HTTP/WebSocket 进程,并在生命周期中创建两个 HTTP 客户端:
|
||||
|
||||
| 组件 | 默认地址 | 职责 |
|
||||
| --- | --- | --- |
|
||||
| `VLLMTranscriptionService` | `http://127.0.0.1:9950/v1` | 只调用 `/audio/transcriptions`,partial 和 final 都是累积窗口 HTTP 请求 |
|
||||
| `AuxiliaryModelService` | `http://127.0.0.1:8010` | 调用 `/health`、`/v1/speaker/resolve`、`/v1/speaker/reset` |
|
||||
| `RealtimeSession` | `server.py:/ws` | 接收音频、VAD 切 turn、调用两个服务、维护展示状态 |
|
||||
|
||||
辅助服务在 `demo/scripts/auxiliary_server.py` 中预加载 VAD 与 CAM++ `speaker_verification`。每次 resolve 只上传一个已结束 turn,服务以 `session_id` 保存在线聚类中心;这不是把整段会议音频重新上传。
|
||||
|
||||
### 2.2 WebSocket 输入和输出
|
||||
|
||||
客户端首条消息是扁平结构:
|
||||
|
||||
```json
|
||||
{
|
||||
"type": "start",
|
||||
"source": "mic",
|
||||
"model_service_url": "http://127.0.0.1:9950/v1",
|
||||
"model": "Qwen/Qwen3-ASR-0.6B",
|
||||
"speaker_diarization": 1,
|
||||
"sentence_strategy": 0,
|
||||
"partial_interval_ms": 1200,
|
||||
"max_segment_sec": 12,
|
||||
"display_merge": true
|
||||
}
|
||||
```
|
||||
|
||||
`start` 成功后,客户端发送 16kHz、单声道、PCM16 二进制帧。文件模式只接收 `.pcm` 和 `.wav`;WAV 的 RIFF/fmt/data chunk 在 WebSocket 服务端增量剥离,并且要求 16kHz、单声道、PCM16。
|
||||
|
||||
控制消息:
|
||||
|
||||
| 消息 | 行为 |
|
||||
| --- | --- |
|
||||
| `eof` | 输入生产者结束;服务端把 `EOF` 放入音频队列,完成尾部 turn 和 speaker 队列后发送 `end` |
|
||||
| `stop` | 与 `eof` 走同一排空流程,同时记录 `input_stopped`,用于 WAV 不完整时的校验差异 |
|
||||
| `abort` | 取消音频和 speaker worker,直接结束,不保证当前 turn 有 final |
|
||||
|
||||
服务端消息的实际顺序通常是:
|
||||
|
||||
```text
|
||||
start
|
||||
-> sentences(partial,可能多次)
|
||||
-> display_state(每次状态改变一份快照)
|
||||
-> sentences(final,speaker 尚未确认)
|
||||
-> display_state(pending)
|
||||
-> display_state(processing/confirmed 或失败原因)
|
||||
-> draining
|
||||
-> end
|
||||
```
|
||||
|
||||
`sentences` 是兼容性事件;`display_state` 是当前页面的主要渲染数据。`display_state.revision` 单调递增,包含:
|
||||
|
||||
- `raw_segments`:按 `start_time`、`sentence_id` 排序的原始片段
|
||||
- `display_blocks`:按相邻且可信的说话人合并后的展示块
|
||||
- `metrics`:音频字节数、输入帧数、partial 数量、partial 修订次数和耗时
|
||||
|
||||
### 2.3 音频、VAD 和 turn 边界
|
||||
|
||||
`RealtimeSession.process_audio()` 的边界是本 Demo 最重要的状态机:
|
||||
|
||||
1. 二进制数据进入 `audio_queue`,再拆成 640 bytes 的 PCM 帧,即 20ms。
|
||||
2. 每帧用 RMS 阈值 `450` 判断有声/静音;这是 WebSocket 层的轻量门控,不是辅助服务的整段 VAD pipeline。
|
||||
3. 未进入说话状态时,保留最近 6400 bytes(约 200ms)`pre_roll`。
|
||||
4. 第一帧有声时,将 pre-roll 加到新 `segment_audio`,设置 `segment_start_ms`。
|
||||
5. 进入说话状态后,所有帧追加到当前 turn;有声帧累计 `voiced_ms`,静音帧累计 `silence_ms`。
|
||||
6. `sentence_strategy=0` 默认约 800ms 静音提交;`sentence_strategy=1` 使用约 1400ms 静音提交。
|
||||
7. 达到 `partial_interval_ms`(默认 1200ms)且尚未达到静音阈值时,调用一次 vLLM partial。
|
||||
8. 达到 `max_segment_sec`(默认 12s)时按 `max_duration` 提交。
|
||||
|
||||
当前 Demo 不把切段尾部静音送给 ASR/声纹:提交前按 `silence_ms` 从 `segment_audio` 尾部删除。下一个 turn 没有原项目那样的 `carry_audio`,而是从后续有声帧重新开始;因此两段之间的静音会形成时间间隔,不会自动带入下一段。
|
||||
|
||||
### 2.4 ASR 结果和同句覆盖
|
||||
|
||||
`_emit_transcription()` 始终使用当前 `segment_id`:
|
||||
|
||||
- `sentence_type=0`:partial,写入/覆盖同一个 `sentence_id`
|
||||
- `sentence_type=1`:final,仍写入同一个 `sentence_id`,并加入 speaker 队列
|
||||
|
||||
`SegmentAssembler.apply_sentence()` 先按 `sentence_id` 找旧记录再覆盖;如果已经是 final,后来的 partial 不会回滚 final。final 没有文本时,会移除该片段,避免遗留一个永久 pending 的 partial。
|
||||
|
||||
### 2.5 声纹异步链路
|
||||
|
||||
`_commit_segment()` 只负责把 `SpeakerJob` 放入 `speaker_queue`,不会等待 CAM++。`process_speakers()` 是单 worker,按 turn 入队顺序串行调用辅助服务:
|
||||
|
||||
1. `voiced_ms < 800ms`:不提取声纹,写入 `insufficient_audio`,保持 `speaker_id=-1`。
|
||||
2. 辅助服务缺失或异常:写入 `service_unavailable`/`service_error`,ASR 继续输出。
|
||||
3. 辅助服务返回 embedding/聚类结果:回写同一 `sentence_id`。
|
||||
4. `SegmentAssembler.apply_speaker_update()` 只接受可信身份:`speaker_evidence` 必须是 `fresh` 或 `confirmed`,置信度至少 `0.6`,并拒绝 `short_attach`、`embedding_attach`。
|
||||
5. 不可信结果被归一化为 `speaker_id=-1`、`speaker_name=""`,但保留状态和原因供诊断。
|
||||
|
||||
辅助服务的在线聚类是简单的 session 级中心匹配:首次 embedding 新建 `speaker_id`,之后与已有中心的余弦相似度达到阈值就更新中心并复用 ID。`/v1/speaker/reset` 在 WebSocket 结束时清理该 session。
|
||||
|
||||
### 2.6 展示块如何合并
|
||||
|
||||
`SegmentAssembler.display_blocks(merge_adjacent=True)` 先按时间排序原始片段,然后遵循:
|
||||
|
||||
- pending/unknown 片段始终以自己的 `sentence_id` 作为身份键,独立成块;
|
||||
- 只有相邻且可信的片段,且 `user_id`/`registry_speaker_id`/`speaker_id` 身份键相同,才合并;
|
||||
- 合并只拼接文本、扩大结束时间并追加 `segment_ids`,原始片段仍保留在 `raw_segments`。
|
||||
|
||||
当前页面收到 `display_state` 后会整块重建结果区,按 `block_id` 渲染;收到 `sentences` 时如果服务端声明支持 `display_state`,页面不会再次追加,避免同一片段重复显示。旧页面或绕过 `display_state` 的客户端不具备这个保护。
|
||||
|
||||
## 3. 原项目 WebSocket 的处理链路
|
||||
|
||||
### 3.1 路由和状态
|
||||
|
||||
`app/api/v1/websocket_asr.py` 当前实际路由:
|
||||
|
||||
- `/ws/v1/asr`
|
||||
- `/ws/v1/asr/qwen`
|
||||
- `/ws/v1/asr/funasr` 已废弃,接受后发送 `FUNASR_REALTIME_REMOVED` 并以 1008 关闭
|
||||
|
||||
每个连接进入 `Qwen3ASRService.handle_connection()`。`ConnectionContext.state` 为 `READY -> STARTED -> STREAMING`;会话还可以通过 `session_id` 在 TTL 内断线恢复。恢复的是完整上下文,包括已确认片段、speaker history、时间线和待处理状态,不只是一个 WebSocket ID。
|
||||
|
||||
### 3.2 start 参数
|
||||
|
||||
原项目的 `start` 使用 `payload` 嵌套对象。常用字段包括:
|
||||
|
||||
| 类别 | 字段 |
|
||||
| --- | --- |
|
||||
| 音频 | `format`、`sample_rate`、`language`、`context`、`enable_inverse_text_normalization` |
|
||||
| partial | `min_partial_sec`、`partial_window_sec`、`partial_holdback_chars`、`unfixed_token_num`、`enable_native_partial_stream` |
|
||||
| 切段 | `silence_duration_ms`(默认 800)、`pre_roll_ms`(默认 240)、`max_sentence_count`(默认 8)、`enable_realtime_vad_split`、`max_segment_sec` |
|
||||
| speaker | `enable_speaker`(默认 true)、`match_speaker_registry`、`speaker_threshold` |
|
||||
| 稳定性 | `force_stable_segment_sec`、`force_stable_min_chars`、`soft_limit_sec`、`hard_limit_sec` |
|
||||
|
||||
服务端先发送 `voice_id`,再发送 `start`。`voice_id` 与会话 ID 通常相同;如果客户端传入固定 `payload.session_id`,断线重连时可以复用上下文。
|
||||
|
||||
### 3.3 音频转换、pre-roll 和 partial
|
||||
|
||||
`_convert_audio()` 接收 PCM/WAV,转为 float32;多声道下混为单声道,非 16kHz 用 scipy 重采样。每个二进制消息都在服务端转换后立即参与 VAD。
|
||||
|
||||
原项目的 `ConnectionContext` 同时维护:
|
||||
|
||||
- `pre_roll_audio`:未开始说话前的前滚音频,默认约 240ms;
|
||||
- `segment_audio_buffer`:从当前 turn 开始到提交前的完整音频;
|
||||
- `stream_window_buffer`:最近窗口,用于 partial 或 native stream 失败时回退;
|
||||
- `realtime_stream_state`:只服务低延迟 partial,不决定 final;
|
||||
- `silence_samples`、`sentence_active`、`total_samples`:VAD 状态和当前 turn 长度。
|
||||
|
||||
有声输入到达时,`_start_turn()` 把 pre-roll 与当前音频拼接;后续由 `_append_turn_audio()` 追加。达到最短窗口后,服务端可走原生 Qwen partial,或对当前窗口/当前 turn 重转写;partial 会经过清理、去重、与上一段重叠裁剪后发送。
|
||||
|
||||
提交触发条件不只有静音:
|
||||
|
||||
- 识别到足够完整的标点句,且时长/字数达到稳定门槛;
|
||||
- 句子数达到 `max_sentence_count`;
|
||||
- 静音样本达到 `silence_duration_ms`;
|
||||
- 达到硬时长限制;开启实时 VAD split 时会尝试找一个完成的分割点。
|
||||
|
||||
### 3.4 final、carry 和时间线
|
||||
|
||||
`_commit_retranscribe_turn()` 对当前完整 turn 做一次 final 重转写,生成 `confirmed_segments` 元素:
|
||||
|
||||
```text
|
||||
index / text / language / reason
|
||||
duration_ms / start_ms / end_ms
|
||||
sentence_type=1 / speaker_id=-1 / speaker_pending=true
|
||||
```
|
||||
|
||||
final 事件先发送,speaker 之后再补。默认 final 的 `start_ms` 来自 `ctx.timeline_cursor_ms`;提交后时间线前移到 `segment_end_ms`。
|
||||
|
||||
开启实时 VAD split 时,提交可能得到 `finalized_audio + carry_audio`:前半段定稿,后半段留在下一个逻辑 turn 中,且会重新初始化 stream 状态。这个 carry 是原项目与当前 Demo 的一个实质差异,也是跨说话人边界时必须重点观察的音频来源。
|
||||
|
||||
### 3.5 原项目 speaker worker 和聚类
|
||||
|
||||
原项目 final 后把 job 放入 `ctx.speaker_job_queue`,由 `_speaker_worker_loop()` 串行消费。`_resolve_segment_speaker()` 调用 `RealtimeSpeakerClusterer.resolve_segment_speaker()`,再把结果写入指定 `segment_index`,通过相同索引发送一条新的 `sentences`。
|
||||
|
||||
`RealtimeSpeakerClusterer` 当前行为:
|
||||
|
||||
- 1.6s 以下且上一条有命名身份:使用 `short_attach` 直接沿用上一条;
|
||||
- 正常 turn:按 1.5s 窗口、0.75s 步长提取 CAM++ embedding,匹配已有记录或新建 generic speaker;
|
||||
- 4s 以上若 chunk 明显混合:返回 `mixed_segment`,保持未知;
|
||||
- 开启注册库匹配且时长至少 2.4s:在独立注册 embedding 空间匹配实名;
|
||||
- timeline 平滑时,短于 0.7s 的范围会并给相邻说话人;
|
||||
- 实时记录达到至少 5 条且队列积压不超过 1 条时,可能对最近 12 条 pending 片段重新聚类;
|
||||
- `stop` 时还会对历史记录做一次最终 recluster。
|
||||
|
||||
此外,`Qwen3ASRService` 自身还有两类“最近说话人继承”:generic speaker 新 turn 时长至少 8s 才允许 `recent_inherit`,实名 speaker 至少 4.5s 才允许 `recent_named_inherit`。这些继承都发生在 embedding 结果之后,不能与 `short_attach` 混为一谈。
|
||||
|
||||
### 3.6 stop 和 end
|
||||
|
||||
客户端只发送 `{"type":"stop"}`。服务端会:
|
||||
|
||||
1. 对仍 active 的 `segment_audio_buffer` 做 `reason=final` 的 final 提交;
|
||||
2. 立即对现有 `speaker_records` 做最终 recluster,并发送可能的 speaker 更新;
|
||||
3. 汇总 `confirmed_segments`,发送 `end(final=1)`。
|
||||
|
||||
这里与当前 Demo 不同:原项目的 `_stop()` 没有显式等待 `speaker_job_queue.join()`。如果 stop 到达时 speaker worker 仍在处理,最终 recluster/end 可能先于某个异步 speaker 回写;断开清理还会停止 worker。客户端必须把同 `sentence_id` 的后续 speaker 事件当作可迟到更新,而不能认为 `end` 之后绝不会再有归属变化。
|
||||
|
||||
## 4. 两套消息契约对照
|
||||
|
||||
| 维度 | 当前独立 Demo | 原项目 |
|
||||
| --- | --- | --- |
|
||||
| WebSocket | aiohttp `/ws` | FastAPI `/ws/v1/asr`、`/qwen` |
|
||||
| start | 扁平字段 | `payload` 嵌套字段 |
|
||||
| ASR | 外部 vLLM HTTP 累积窗口 | 进程内 Qwen engine,原生 stream 或重转写回退 |
|
||||
| VAD | 20ms PCM RMS 门控 | float32 音频门控,支持实时 VAD split 辅助切分 |
|
||||
| pre-roll | 固定约 200ms | `pre_roll_ms` 默认约 240ms |
|
||||
| final 音频 | 删除提交尾部静音,不保留 carry | 可有 `carry_audio` 并带入后续 turn |
|
||||
| speaker | 外部 CAM++/在线中心服务,单 worker | 进程内 CAM++ chunk 聚类、注册库、重聚类,单 worker |
|
||||
| 未确认 speaker | `speaker_evidence=pending`,展示独立未知块 | `speaker_id=-1` 或 `speaker_pending=true`,客户端需自行暂存 |
|
||||
| 文本更新键 | `sentence_id` | `sentence_id` 对外,内部 `segment_index` |
|
||||
| 展示快照 | `display_state.revision`,服务端生成 `display_blocks` | 没有同等的服务端展示块协议,客户端按 sentence upsert |
|
||||
| end 屏障 | `EOF -> audio worker -> speaker EOF -> end` | `_stop()` final/recluster/end,不等待 speaker 队列清空 |
|
||||
|
||||
## 5. “上一人的最后一句进入下一人气泡”的定位框架
|
||||
|
||||
当前先不修改,定位时要把“片段本身错了”和“片段正确但展示合错了”分开。
|
||||
|
||||
### 5.1 当前独立 Demo 的可能路径
|
||||
|
||||
1. **同一个 turn**:两人换话之间没有达到 800ms(或段落模式 1400ms)静音,RMS VAD 不切段。此时 vLLM 收到的是混合 turn,前端只有一个 `sentence_id`,不是气泡合并问题。
|
||||
2. **声纹误归属**:A 的 final 先是 pending,随后辅助服务把 A 误匹配到 B 的 cluster。下一次 `display_state` 中,A、B 两个相邻片段拥有同一可信身份,`display_blocks()` 会把两者拼成一个 block。
|
||||
3. **异步回写改变了合并条件**:A 的 speaker 结果可能在 B 的 final 之后才到达。服务端按时间排序重建快照,所以视觉上是 A 的文字“后来进入”B 的气泡;实际是 A 的旧片段身份被补齐后触发了相邻合并。
|
||||
4. **旧客户端渲染路径**:当前页面在 `display_state_supported=true` 时忽略 `sentences`,但旧页面若逐条 append `sentences`,可能把同一 `sentence_id` 的 final/speaker 更新当成新气泡,或把 pending 文本追加到上一气泡。必须确认浏览器加载的 `app.js` 版本和服务端返回的 `display_state`。
|
||||
5. **session 污染**:辅助服务按 `session_id` 保存聚类中心。若 reset 没有执行、多个连接错误复用同一个 session ID,上一场会话的 cluster 可能影响新会话;正常一次连接内 A/B 共用中心是设计行为,不是跨人合并的充分证据。
|
||||
|
||||
当前 Demo 的 worker 是串行的,`emit()` 有发送锁,因而“并发返回顺序打乱”不是首要嫌疑;首要证据应是 `raw_segments` 的 `sentence_id/start_time/speaker_id/speaker_strategy` 是否正确,以及 `display_blocks.segment_ids` 是否把两个片段合到一起。
|
||||
|
||||
### 5.2 原项目的可能路径
|
||||
|
||||
1. **静音边界不足**:默认 800ms 静音才提交;换话前的短停顿会让 A 尾部和 B 开头留在同一个 `segment_audio_buffer`。
|
||||
2. **carry 音频污染**:启用实时 VAD split 时,分割点之后的 `carry_audio` 会成为下一个 turn 的开头。若 split 点落在 A 尾音或 B 起音中间,下一段声纹和 ASR 都会携带前一人尾部。
|
||||
3. **短句沿用上一身份**:B 的新段小于 1.6s 且历史有命名 speaker 时,`short_attach` 会直接复用上一条;chunk 提取为空时的 `embedding_attach` 也可能复用上一条。这是代码中最直接的“上一人污染下一段”路径。
|
||||
4. **最近身份继承**:较长的新段在匹配失败时可能触发 `recent_named_inherit`(至少 4.5s)或 `recent_inherit`(至少 8s),因此不能只看最终 `speaker_id`,还要记录 `speaker_strategy`。
|
||||
5. **重聚类改写历史**:实时重聚类和 stop 最终重聚类都可能改写已有 segment 的 speaker。客户端如果按到达顺序追加,而不是按 `sentence_id` upsert,就会看到旧气泡和新气泡互相覆盖或合并。
|
||||
6. **stop 竞态**:原项目 stop 不等待 speaker job 队列清空;end 可能先发,随后连接清理还会取消 worker。最后一个人的 speaker 归属可能缺失、迟到或停留在旧标签,前端若把 end 当成不可变快照会放大问题。
|
||||
|
||||
### 5.3 需要同时保存的证据
|
||||
|
||||
对同一段测试音频,至少保存以下三层结果:
|
||||
|
||||
```text
|
||||
音频层:每个 turn 的 start/end、有效有声时长、是否包含 carry/pre-roll
|
||||
识别层:sentence_id/index、sentence_type、文本、speaker_strategy、置信度
|
||||
展示层:display_state.revision、raw_segments、display_blocks.segment_ids
|
||||
```
|
||||
|
||||
判定规则:
|
||||
|
||||
- `raw_segments` 已经只有一个片段:先查 VAD/切段边界;
|
||||
- `raw_segments` 有 A、B 两段且 speaker ID 相同:查声纹误匹配/继承/重聚类;
|
||||
- `raw_segments` 的 ID 不同但 `display_blocks.segment_ids` 合并:查展示合并键;
|
||||
- `display_blocks` 正确但页面仍显示一只气泡:查浏览器脚本版本、是否绕过 `display_state`、是否按 `sentence_id` upsert。
|
||||
|
||||
## 6. 后续细节优化的优先级(本轮不实施)
|
||||
|
||||
### P0:先证明边界和身份是否正确
|
||||
|
||||
- 记录每个 final 的实际音频起止、有效有声毫秒、pre-roll/carry 长度。
|
||||
- 记录 speaker resolve 请求和返回的 `session_id`、策略、置信度、cluster ID。
|
||||
- 前端临时展示 `block.segment_ids`,确认“合并”到底是两个片段还是一个片段。
|
||||
- 用固定 A-静音-B 音频,比较 200ms、500ms、800ms、1400ms 停顿。
|
||||
|
||||
### P1:降低错误身份传播
|
||||
|
||||
- 对 `short_attach`、`embedding_attach`、recent inherit 单独统计,不要只统计 speaker_id。
|
||||
- 对跨边界的短 turn 保持 pending,等到有独立 embedding 或后续重聚类再确认。
|
||||
- 明确实时重聚类和最终重聚类的可修改范围,客户端统一按 ID 幂等更新。
|
||||
- 为 stop 增加“最后一个 speaker job 已完成”的可观察状态。
|
||||
|
||||
### P2:改善展示稳定性
|
||||
|
||||
- 展示层只把可信且相邻的片段合并,保留 segment_ids 和 revision。
|
||||
- 对 speaker 更新做局部重绘或整快照重绘,但不要把同一个 sentence 当成新消息追加。
|
||||
- unknown/pending 使用独立块,不把诊断文本放在说话人名称中。
|
||||
|
||||
## 7. 建议的验收用例
|
||||
|
||||
| 用例 | 观察点 | 通过标准 |
|
||||
| --- | --- | --- |
|
||||
| A 说 3s,停 1s,B 说 3s | 两套服务的 raw segment | 至少两个不同 sentence_id,时间不重叠 |
|
||||
| A 说 3s,停 300ms,B 说 3s | VAD 边界 | 明确记录为同段或分段,不能只看气泡颜色判断 |
|
||||
| A 说 3s,B 只说 0.8s | 短 turn speaker 策略 | 原项目应能观察 `short_attach`;Demo 应保持 pending 或独立结果 |
|
||||
| A/B 各说多段,speaker 服务延迟 2s | 异步回写 | 文本不重复,更新按 sentence_id 定位,顺序按时间恢复 |
|
||||
| speaker 服务不可用 | 降级 | ASR 仍有 final,speaker 为未知并有明确 reason |
|
||||
| stop 紧跟最后一帧 | 收尾屏障 | Demo 的 end 在 speaker 队列完成后发送;原项目记录可能迟到的 speaker 更新 |
|
||||
| 断线后同 session_id 重连 | 会话隔离 | 原项目按 TTL 恢复;Demo 新连接不会复用旧 speaker center |
|
||||
|
||||
## 8. 源码索引
|
||||
|
||||
### 当前独立 Demo
|
||||
|
||||
- `demo/realtime_asr_optimization_demo/server.py`
|
||||
- `RealtimeSession.__init__`:会话参数、队列和 VAD 状态
|
||||
- `emit_state`:`raw_segments/display_blocks/revision`
|
||||
- `_emit_transcription`:partial/final 写入同一 `sentence_id`
|
||||
- `_commit_segment`、`process_audio`:VAD、切段和 speaker job 入队
|
||||
- `_resolve_speaker`、`process_speakers`:异步声纹回写
|
||||
- `websocket_handler`:start、二进制帧、eof/stop/abort、end
|
||||
- `demo/realtime_asr_optimization_demo/speaker_assembler.py`
|
||||
- `apply_sentence`、`apply_speaker_update`、`display_blocks`
|
||||
- `demo/realtime_asr_optimization_demo/model_service.py`
|
||||
- 独立 vLLM OpenAI-compatible HTTP 适配
|
||||
- `demo/realtime_asr_optimization_demo/auxiliary_service.py`
|
||||
- `/health`、`/v1/speaker/resolve`、`/v1/speaker/reset` 客户端适配
|
||||
- `demo/scripts/auxiliary_server.py`
|
||||
- VAD/CAM++ 预加载、embedding 提取、session 级在线聚类
|
||||
|
||||
### 原项目
|
||||
|
||||
- `app/api/v1/websocket_asr.py`
|
||||
- `/ws/v1/asr`、`/ws/v1/asr/qwen`、废弃 `/funasr`
|
||||
- `app/services/qwen3_websocket_asr.py`
|
||||
- `ConnectionContext`:音频、partial、confirmed segments、speaker 队列
|
||||
- `handle_connection`:WebSocket 状态机和消息协议
|
||||
- `_commit_retranscribe_turn`:final、carry、timeline、speaker job
|
||||
- `_speaker_worker_loop`、`_resolve_and_emit_segment_speaker`:异步 speaker 回写
|
||||
- `_inherit_recent_*`、`_maybe_recluster_recent_segments`:身份传播和重聚类
|
||||
- `_stop`:最终提交、recluster、end
|
||||
- `app/services/realtime_speaker_clusterer.py`
|
||||
- chunk embedding、短段沿用、已有 speaker 匹配、混合段、timeline 平滑
|
||||
- `docs/realtime_meeting_websocket.md`
|
||||
- 对外协议示例;其中 partial/final/speaker 回写必须按 `sentence_id` 幂等处理
|
||||
|
||||
本轮只新增本文档,没有修改上述实现。后续修复应先用第 5 节的三层证据确定问题属于切段、声纹还是展示层,再决定改哪一层。
|
||||
|
|
@ -0,0 +1,66 @@
|
|||
# 熵减执行清单
|
||||
|
||||
本文档记录本轮已执行的熵减工作。目标是移除不可达路径、兼容占位、隐藏 fallback、重复请求流水线和无用依赖。
|
||||
|
||||
## 范围
|
||||
|
||||
- 主范围:`app/`、根运行配置、公开运行文档。
|
||||
- 不处理:`vendor/qwenasr` 内部实现、仅 benchmark 使用且不阻塞主链路的代码。
|
||||
- 原则:开发中项目不保留废弃接口、旧字段、兼容层或 fallback 逻辑。
|
||||
|
||||
## P0
|
||||
|
||||
- [x] 移除 Qwen3 `transformers` 后端残留路径。
|
||||
- 删除后端选择里的 `"transformers"` fallback。
|
||||
- 删除仅服务该路径的 batch/segment 转换死代码。
|
||||
- 不支持的设备显式失败。
|
||||
- [x] 启动预加载改为 fail-fast。
|
||||
- 模型完整性检查或预加载失败时停止 worker。
|
||||
- 不再静默降级到首次请求加载。
|
||||
- [x] 移除被忽略的离线模型兼容参数。
|
||||
- 删除 REST `model_id` 兼容处理。
|
||||
- 删除 OpenAI transcription `model` 兼容处理。
|
||||
- 运行时模型选择统一由部署计划和 `QWEN3_ASR_MODEL` 控制。
|
||||
|
||||
## P1
|
||||
|
||||
- [x] 抽出共享离线转写服务。
|
||||
- API 层只处理协议输入和响应格式。
|
||||
- 音频准备、`OfflineASRRequest`、runtime 调用和清理边界集中到服务层。
|
||||
- [x] 合并音频字节处理逻辑。
|
||||
- `process_from_request` 和 `process_upload_file` 共享私有 byte 处理 helper。
|
||||
|
||||
## P2
|
||||
|
||||
- [x] 将 `.tsscale` sidecar 隐式耦合改为显式结构化元数据。
|
||||
- [x] 拆分 WebSocket 路由和 Qwen3 协议服务。
|
||||
- Qwen3 websocket 状态机移出 API route。
|
||||
- route 模块仅保留端点注册和 service delegation。
|
||||
- [x] 删除首轮发现的无用 helper。
|
||||
- [x] 审计并移除无用直接依赖。
|
||||
- 根环境和 CPU 环境移除直接依赖 `pydub`、`httpx`。
|
||||
- 保留 ModelScope/FunASR 动态 runtime 依赖。
|
||||
- [x] 继续压缩阿里协议 WebSocket service。
|
||||
- 删除大段注释、未使用状态、未使用参数和死函数。
|
||||
- 合并重复响应构造。
|
||||
- 删除重复音频转换。
|
||||
|
||||
## 验证
|
||||
|
||||
- [x] `uv run python -m py_compile $(find app -name '*.py' -not -path '*/__pycache__/*') start.py`
|
||||
- [x] `uvx pyright`
|
||||
- [x] 变更模块 import smoke check。
|
||||
- [x] 手工 API smoke plan 已记录:
|
||||
- `/stream/v1/asr`
|
||||
- `/v1/audio/transcriptions`
|
||||
- `/ws/v1/asr/funasr`
|
||||
- `/ws/v1/asr/qwen`
|
||||
|
||||
## 手工 Smoke Plan
|
||||
|
||||
启动服务并准备模型后执行:
|
||||
|
||||
1. `POST /stream/v1/asr`,使用小 WAV request body,确认返回 `result`、`segments`、`duration`、`processing_time`。
|
||||
2. `POST /v1/audio/transcriptions`,使用 multipart `file` 和 `response_format=verbose_json`,确认返回 OpenAI 风格 `text` 和 `segments`。
|
||||
3. 连接 `/ws/v1/asr/funasr`,发送阿里兼容 start/audio/stop 消息,确认 sentence 事件仍正常返回。
|
||||
4. 连接 `/ws/v1/asr/qwen`,发送 start/audio/stop 消息,确认 partial/final 事件仍正常返回。
|
||||
|
|
@ -0,0 +1,457 @@
|
|||
# x86 Rust Align Optimization Plan
|
||||
|
||||
## 当前结论
|
||||
|
||||
- 当前工作区的 vendored Rust backend 已经收敛到更接近 upstream `huanglizhuo/QwenASR` 的 Linux/x86_64 路径:
|
||||
- `release`
|
||||
- `RUSTFLAGS="-C target-cpu=native"`
|
||||
- `BLAS/OpenBLAS`
|
||||
- x86_64 默认 `BF16` decode
|
||||
- 保留的有意偏离只有两类:
|
||||
- `SharedQwenModel` / shared model cache
|
||||
- 中性的 `ffi` feature(`macos-ffi` 仅作为兼容别名保留)
|
||||
|
||||
## upstream 参考
|
||||
|
||||
- upstream repo: `https://github.com/huanglizhuo/QwenASR`
|
||||
- inspected commit: `4e85a19b05f034e106a345d279c68f50df718ab8`
|
||||
|
||||
## 本机环境
|
||||
|
||||
- CPU: `Intel Core i5-13600KF`
|
||||
- visible CPUs: `14`
|
||||
- memory: user reported `G.SKILL DDR5-6400`
|
||||
|
||||
## 已验证 benchmark
|
||||
|
||||
音频:
|
||||
|
||||
- `/opt/qwen3-asr/temp/test_assets/podcast_demo_2min_16k.wav`
|
||||
- duration: `120s`
|
||||
|
||||
### decode 路径对照(runtime concurrency = 4)
|
||||
|
||||
`INT8 decode`
|
||||
|
||||
- total: `173.42s`
|
||||
- asr: `54.69s`
|
||||
- align: `118.74s`
|
||||
- rtf: `1.4452`
|
||||
|
||||
来源:
|
||||
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_int8.json`
|
||||
|
||||
`BF16 decode`
|
||||
|
||||
- total: `125.87s`
|
||||
- asr: `46.40s`
|
||||
- align: `79.47s`
|
||||
- rtf: `1.0489`
|
||||
|
||||
来源:
|
||||
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_bf16.json`
|
||||
|
||||
结论:
|
||||
|
||||
- 在当前这台 x86_64 机器上,`BF16 decode` 明显优于 `INT8 decode`
|
||||
- 因此 x86_64 默认 decode 路径应保持 `BF16`
|
||||
|
||||
### 收敛后的默认路径 benchmark
|
||||
|
||||
来源:
|
||||
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_default_after_converge.json`
|
||||
|
||||
结果:
|
||||
|
||||
- `runtime concurrency = 4`
|
||||
- total: `131.77s`
|
||||
- asr: `51.54s`
|
||||
- align: `80.23s`
|
||||
- rtf: `1.0981`
|
||||
- `runtime concurrency = 14`
|
||||
- total: `128.25s`
|
||||
- asr: `57.12s`
|
||||
- align: `71.13s`
|
||||
- rtf: `1.0688`
|
||||
|
||||
结论:
|
||||
|
||||
- 当前主瓶颈仍然在 `align`
|
||||
- `align_sec` 明显大于或接近 `asr_sec`
|
||||
- `runtime concurrency` 的最优值并不稳定,说明问题不在单纯线程数,而在具体阶段的访问模式和 kernel 行为
|
||||
|
||||
## 为什么不继续默认走 INT8
|
||||
|
||||
- upstream README 对 Linux/x86_64 的主路径描述是 `BLAS + AVX2/FMA`
|
||||
- 当前本机实测中,`INT8 decode` 明显慢于 `BF16 decode`
|
||||
- 说明这台机器上的主瓶颈不只是权重带宽,更多是:
|
||||
- x86_64 上 INT8 kernel 的有效带宽利用率
|
||||
- cache / 数据布局
|
||||
- 实现成熟度差异
|
||||
|
||||
## 当前仍需保留的偏离
|
||||
|
||||
### 1. Shared model cache
|
||||
|
||||
文件:
|
||||
|
||||
- `/opt/qwen3-asr/vendor/qwenasr/crates/qwen-asr/src/context.rs`
|
||||
|
||||
目的:
|
||||
|
||||
- 多 runtime / 多 worker 场景下复用只读模型权重
|
||||
- 避免每个 runtime 重复 mmap / 持有整套权重
|
||||
|
||||
### 2. ffi feature
|
||||
|
||||
文件:
|
||||
|
||||
- `/opt/qwen3-asr/vendor/qwenasr/crates/qwen-asr/Cargo.toml`
|
||||
- `/opt/qwen3-asr/vendor/qwenasr/crates/qwen-asr/src/lib.rs`
|
||||
- `/opt/qwen3-asr/Dockerfile.cpu`
|
||||
|
||||
目的:
|
||||
|
||||
- 让 Linux CPU 集成不再依赖命名不准确的 `macos-ffi`
|
||||
- 同时保留兼容别名,避免已有脚本立即失效
|
||||
|
||||
## align 热点拆解计划
|
||||
|
||||
### Phase 1: 阶段级 profiling
|
||||
|
||||
状态:已完成
|
||||
|
||||
目标:
|
||||
|
||||
- 先确认 `align` 的主耗时究竟在哪一段
|
||||
|
||||
位置:
|
||||
|
||||
- `/opt/qwen3-asr/vendor/qwenasr/crates/qwen-asr/src/align.rs`
|
||||
- `/opt/qwen3-asr/vendor/qwenasr/crates/qwen-asr/src/decoder.rs`
|
||||
|
||||
需要拆出的阶段:
|
||||
|
||||
- `mel_spectrogram`
|
||||
- `encoder.forward`
|
||||
- `input_embeds build`
|
||||
- `decoder_prefill_logits`
|
||||
- `timestamp argmax extract`
|
||||
- `fix_timestamps`
|
||||
|
||||
验收:
|
||||
|
||||
- 2 分钟样本上输出稳定的阶段级耗时表
|
||||
|
||||
实际结果:
|
||||
|
||||
- 产物:
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_align_profile.json`
|
||||
- `/opt/qwen3-asr/temp/test_logs/qwen_rust_runtime_concurrency_2min_align_profile.stderr`
|
||||
- 结论:
|
||||
- `align` 的主热点明确落在 `decoder_prefill_logits`
|
||||
- `final rms_norm` 和 `lm_head projection` 不是主矛盾
|
||||
|
||||
### Phase 2: decoder_prefill_logits 内部分解
|
||||
|
||||
状态:已完成
|
||||
|
||||
如果 `decoder_prefill_logits` 是主热点,则继续拆分:
|
||||
|
||||
- `decoder_prefill`
|
||||
- final `rms_norm`
|
||||
- `lm_head projection`
|
||||
|
||||
目的:
|
||||
|
||||
- 判断到底是 decoder prefill 慢,还是最后分类头 projection 慢
|
||||
|
||||
实际结果:
|
||||
|
||||
- 产物:
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_align_breakdown.json`
|
||||
- `/opt/qwen3-asr/temp/test_logs/qwen_rust_runtime_concurrency_2min_align_breakdown.stderr`
|
||||
- 结论:
|
||||
- 真正的大头是 `decoder_prefill`
|
||||
- 长段(`seq_len=1801`)时,`attention_ms` 占 `decoder_prefill` 的绝大部分
|
||||
- 关键样本:
|
||||
- `decoder_prefill total_ms=79280.78`
|
||||
- `attention_ms=73769.91`
|
||||
- `qkv_ms=1336.33`
|
||||
- `gate_up_ms=1866.68`
|
||||
- `down_proj_ms=955.94`
|
||||
|
||||
### Phase 2.5: 失败尝试记录
|
||||
|
||||
状态:已完成并回退
|
||||
|
||||
尝试:
|
||||
|
||||
- 针对 x86_64 预先物化 prefill 用 F32 权重,避免每次 `align` 反复做 `BF16 -> F32`
|
||||
|
||||
结果:
|
||||
|
||||
- 长段 `decoder_prefill` 没有稳定收益,反而出现回归
|
||||
- 这条路径已经回退,不保留在主线代码里
|
||||
|
||||
结论:
|
||||
|
||||
- 当前瓶颈不是简单的 BF16 权重转换
|
||||
- 更直接的问题是 multi-token causal attention 的算法路径
|
||||
|
||||
### Phase 3: 对热点段做针对性优化
|
||||
|
||||
状态:第一轮已完成
|
||||
|
||||
根据 profiling 结果,按优先级选一个方向:
|
||||
|
||||
1. 如果热点在 `input_embeds build`
|
||||
- 复用固定 prefix/suffix embeddings
|
||||
- 减少逐 token 小块 copy
|
||||
- 降低每段 align 的重复构造开销
|
||||
|
||||
2. 如果热点在 `decoder_prefill`
|
||||
- 检查 `BF16 matvec / attention / swiglu` 的实际热点
|
||||
- 优化并行粒度或数据布局
|
||||
|
||||
3. 如果热点在 `lm_head projection`
|
||||
- 优先优化 `BF16` classify head 路径
|
||||
- 避免无价值的整块 materialize
|
||||
- 但只有在 profiling 证明是主热点后才动
|
||||
|
||||
4. 如果热点在后处理
|
||||
- 精简 `fix_timestamps`
|
||||
- 减少 `Vec/String` 分配
|
||||
|
||||
### Phase 3 实施结果
|
||||
|
||||
本轮实际落地的是:
|
||||
|
||||
- 文件:
|
||||
- `/opt/qwen3-asr/vendor/qwenasr/crates/qwen-asr/src/kernels/mod.rs`
|
||||
- 改动:
|
||||
- 对 BLAS multi-token causal attention 增加长序列专用 batched 路径
|
||||
- 仅在 `seq_q >= 256` 时启用
|
||||
- 从“每个 head、每一行 2 次小 GEMM”改为:
|
||||
- 每个 head 1 次 `Q @ K^T`
|
||||
- 行级 causal softmax
|
||||
- 每个 head 1 次 `softmax @ V`
|
||||
|
||||
### Phase 3 回归结果
|
||||
|
||||
来源:
|
||||
|
||||
- 优化后 benchmark:
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_after_attention_opt.json`
|
||||
- 优化后 profiling:
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_attention_opt_profile.json`
|
||||
- `/opt/qwen3-asr/temp/test_logs/qwen_rust_runtime_concurrency_2min_attention_opt_profile.stderr`
|
||||
|
||||
关键对比:
|
||||
|
||||
- 之前默认路径(2 分钟样本,基线文件):
|
||||
- `total=128.25s`
|
||||
- `asr=57.12s`
|
||||
- `align=71.13s`
|
||||
- 优化后:
|
||||
- `total=76.46s`
|
||||
- `asr=45.32s`
|
||||
- `align=31.14s`
|
||||
- `rtf=0.6372`
|
||||
|
||||
attention 热点变化:
|
||||
|
||||
- 长段 `seq_len=1801`
|
||||
- 优化前:
|
||||
- `decoder_prefill total_ms=79280.78`
|
||||
- `attention_ms=73769.91`
|
||||
- 优化后:
|
||||
- `decoder_prefill total_ms=16625.88`
|
||||
- `attention_ms=9981.88`
|
||||
|
||||
结论:
|
||||
|
||||
- 当前这台 i5 上,`align` 的主矛盾已经从“attention 明显失控”收敛到了“attention 仍是第一热点,但已降到可接受量级”
|
||||
- 这一轮优化是有效的,应该保留
|
||||
|
||||
## Phase 4: FFN 路径继续收敛
|
||||
|
||||
状态:已完成一轮,并保留有效部分
|
||||
|
||||
本轮动作:
|
||||
|
||||
- 文件:
|
||||
- `/opt/qwen3-asr/vendor/qwenasr/crates/qwen-asr/src/decoder.rs`
|
||||
- 改动:
|
||||
- 仅对 x86_64 `BF16 prefill` 的 FFN 路径物化共享 F32 权重
|
||||
- 范围只包括:
|
||||
- `gate_up_fused`
|
||||
- `down_weight`
|
||||
- `QKV` 和 `O-proj` 暂不纳入
|
||||
|
||||
回归数据:
|
||||
|
||||
- 不带 profiling:
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_after_ffn_opt.json`
|
||||
- `total=58.61s`
|
||||
- `asr=29.50s`
|
||||
- `align=29.11s`
|
||||
- 带 profiling:
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_ffn_opt_profile.json`
|
||||
- `total=62.07s`
|
||||
- `asr=32.15s`
|
||||
- `align=29.92s`
|
||||
|
||||
与上一轮 attention-only profiling 对比:
|
||||
|
||||
- attention-only:
|
||||
- `total=64.58s`
|
||||
- `align=30.86s`
|
||||
- FFN-opt:
|
||||
- `total=62.07s`
|
||||
- `align=29.92s`
|
||||
|
||||
长段热点对比(`seq_len=1801`):
|
||||
|
||||
- FFN-opt 之前:
|
||||
- `attention_ms=9981.88`
|
||||
- `gate_up_ms=2080.10`
|
||||
- `down_proj_ms=1183.64`
|
||||
- FFN-opt 之后:
|
||||
- `attention_ms=9660.15`
|
||||
- `gate_up_ms=2210.39`
|
||||
- `down_proj_ms=1166.96`
|
||||
|
||||
结论:
|
||||
|
||||
- FFN 这轮不是“大收益”,但 `align_sec` 仍然有小幅下降
|
||||
- 收益不像 attention 优化那样压倒性,更像是小幅收敛
|
||||
- 当前可以保留,但不值得继续在同一方向上扩大复杂度
|
||||
|
||||
## Phase 5: QKV / O-proj 试验与回退
|
||||
|
||||
状态:已完成并回退
|
||||
|
||||
尝试:
|
||||
|
||||
- 在 prefill 中进一步物化 `QKV` 和 `O-proj` 的共享 F32 权重
|
||||
|
||||
回归数据:
|
||||
|
||||
- 试验版本:
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_after_qkv_opt.json`
|
||||
- `total=63.12s`
|
||||
- `align=30.07s`
|
||||
|
||||
结论:
|
||||
|
||||
- 相比 FFN-opt 版本,没有形成净收益
|
||||
- 因此这条路径已回退,不保留在主线代码里
|
||||
|
||||
## Phase 6: attention 继续细化的两次试验
|
||||
|
||||
状态:已完成并回退
|
||||
|
||||
### 试验 A:query-block batched attention
|
||||
|
||||
尝试:
|
||||
|
||||
- 将长序列 batched causal attention 从“整段一次性 `QK^T` / `SV`”改成按 query block 分块执行
|
||||
|
||||
结果:
|
||||
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_after_attention_block_opt.json`
|
||||
- `total=79.18s`
|
||||
- `align=33.40s`
|
||||
|
||||
结论:
|
||||
|
||||
- 这条路径在当前 i5 + OpenBLAS 组合下没有收益
|
||||
- 增加 GEMM 次数带来的额外调度开销,超过了小块缓存收益
|
||||
- 已回退
|
||||
|
||||
### 试验 B:提高 batched 切换阈值到 512
|
||||
|
||||
尝试:
|
||||
|
||||
- 只改 `BATCHED_CAUSAL_ATTENTION_THRESHOLD`
|
||||
- 让中等长度序列继续走 row-wise 路径,只把更长的序列交给 batched 路径
|
||||
|
||||
结果:
|
||||
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_after_attention_threshold512.json`
|
||||
- `total=74.49s`
|
||||
- `align=30.42s`
|
||||
|
||||
结论:
|
||||
|
||||
- 相比当前主线最优版本也没有收益
|
||||
- 说明当前阈值 `256` 不是主要问题
|
||||
- 已恢复回 `256`
|
||||
|
||||
## Phase 7: K/V block + online softmax 试验
|
||||
|
||||
状态:已完成并回退
|
||||
|
||||
尝试:
|
||||
|
||||
- 仅替换长序列 batched attention 路径
|
||||
- 改为按 `K/V` block 流式累积的 online softmax
|
||||
- 短序列和单 token 路径完全不动
|
||||
|
||||
目标:
|
||||
|
||||
- 不再一次性物化整块 `scores`
|
||||
- 降低大矩阵内存压力
|
||||
- 观察是否能进一步压低长段 `attention_ms`
|
||||
|
||||
结果:
|
||||
|
||||
- `/opt/qwen3-asr/temp/test_assets/qwen_rust_runtime_concurrency_2min_after_kvblock_online_softmax.json`
|
||||
- `total=74.11s`
|
||||
- `align=30.33s`
|
||||
|
||||
结论:
|
||||
|
||||
- 当前实现下没有优于主线最优版本
|
||||
- 在这台机器上,额外的 block 循环和 online softmax 合并开销,超过了减少大 `scores` 矩阵带来的收益
|
||||
- 已回退
|
||||
|
||||
## 当前判断
|
||||
|
||||
- 当前最值钱、且已验证有效的优化仍然是:
|
||||
- 长序列 batched causal attention
|
||||
- FFN selective F32 物化
|
||||
- 继续扩大到 `QKV/O-proj` 这一步暂时不划算
|
||||
- query-block 化和 batched 阈值调优目前也不划算
|
||||
- `K/V block + online softmax` 在当前实现形态下也不划算
|
||||
- 后续判断应优先看:
|
||||
- `align_sec`
|
||||
- `decoder_prefill` profiling
|
||||
- 尤其是长段 `seq_len` 下的热点变化
|
||||
|
||||
补充:
|
||||
|
||||
- `asr_sec` 在多次回归中波动明显大于 `align_sec`
|
||||
- 因此后续评估优化效果时,不应只盯总耗时,应优先以 `align` profiling 为准
|
||||
|
||||
## 暂不做的事
|
||||
|
||||
- 不再把 x86_64 默认路径改回 `INT8 decode`
|
||||
- 不继续做没有 profiling 支撑的 `align` 结构性改写
|
||||
- 不围绕 `runtime concurrency` 数量盲调
|
||||
|
||||
## 下一步执行顺序
|
||||
|
||||
1. 保留当前 batched causal attention 路径,继续观察不同长段下的稳定性
|
||||
2. 保留 FFN selective F32 物化,继续观察其稳定收益
|
||||
3. 如需继续优化,优先看:
|
||||
- 更激进的 `attention` 算法级改动,例如按 `K/V` block 的 online softmax
|
||||
- 再其次才是 `qkv_ms + gate_up_ms + down_proj_ms`
|
||||
4. 如果后续继续深挖,再考虑:
|
||||
- batched attention 的 block 化,降低大 score matrix 的瞬时内存
|
||||
- `decoder_prefill` 内的投影层进一步收敛
|
||||
5. 保持同一份 2 分钟样本持续回归,避免再次把回归误当成优化
|
||||
|
|
@ -0,0 +1,699 @@
|
|||
# Qwen3-ASR 部署指南
|
||||
|
||||
快速部署 Qwen3-ASR 语音识别服务,支持 CPU/macOS、NVIDIA GPU、沐曦 GPU、天数 GPU 与摩尔线程 GPU 运行形态。
|
||||
|
||||
如果你正在继续验证本轮 CUDA 官方 vLLM 迁移,请同时参考:
|
||||
|
||||
- [PENDING_CUDA_VLLM_HANDOFF.md](./TODO/PENDING_CUDA_VLLM_HANDOFF.md)
|
||||
|
||||
依赖安装现在改成根目录默认 NVIDIA GPU,CPU、沐曦、天数与摩尔线程为单独特化环境:
|
||||
|
||||
| 模式 | 命令 | 说明 |
|
||||
|------|------|------|
|
||||
| NVIDIA GPU | `uv sync` 或 `./scripts/sync_gpu_env.sh` | Linux/NVIDIA 运行时,默认锁定 CUDA 13.0/cu130 `torch 2.11.0` / `torchaudio 2.11.0` / `torchvision 0.26.0` + `vllm 0.20.0` |
|
||||
| 沐曦 GPU | `./scripts/sync_metax_env.sh` | 同步公共依赖;可选 GPU 栈安装默认从沐曦 MACA PyPI 源按 `--no-deps` 安装 |
|
||||
| 天数 GPU | `./scripts/sync_iluvatar_env.sh` | 同步公共依赖;GPU 栈使用天数官方 vLLM 镜像 |
|
||||
| 摩尔线程 GPU | `./scripts/sync_mthreads_env.sh` | 同步公共依赖;GPU 栈使用摩尔线程官方 MUSA vLLM 镜像 |
|
||||
| CPU | `./scripts/sync_cpu_env.sh` | Linux/CPU 运行时 |
|
||||
| 自动 | `./scripts/sync_accel_env.sh` | 根据 `mx-smi` / `ixsmi` / `mthreads-gmi` / `nvidia-smi` 自动选择沐曦、天数、摩尔线程、NVIDIA 或 CPU 环境 |
|
||||
|
||||
## 快速部署
|
||||
|
||||
### NVIDIA GPU 版本部署(推荐)
|
||||
|
||||
适用于生产环境,提供更快的推理速度:
|
||||
|
||||
**前置要求:**
|
||||
- NVIDIA GPU(默认镜像面向 CUDA 13.0+;CUDA 12.6 / 13.0 可通过构建参数覆盖)
|
||||
- 已安装 NVIDIA Container Toolkit
|
||||
- 显存 12GB+(推荐 16GB+ 以支持 Qwen3-ASR 1.7B)
|
||||
|
||||
```bash
|
||||
# 使用 docker run(带模型挂载)
|
||||
docker run -d --name qwen3-asr \
|
||||
--gpus all \
|
||||
-p 17003:8000 \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
-e ACCELERATOR=nvidia \
|
||||
-e DEVICE=auto \
|
||||
-e QWEN_GPU_MEMORY_UTILIZATION=0.3 \
|
||||
-e QWEN_VLLM_ENFORCE_EAGER=true \
|
||||
unis/qwen3-asr:gpu-latest
|
||||
|
||||
# 或使用 docker-compose(推荐)
|
||||
docker-compose up -d
|
||||
```
|
||||
|
||||
### 沐曦 GPU 版本部署
|
||||
|
||||
适用于已安装沐曦驱动与容器运行栈的机器:
|
||||
|
||||
```bash
|
||||
docker run -d --name qwen3-asr-metax \
|
||||
--privileged \
|
||||
--network=host \
|
||||
--pid=host \
|
||||
--ipc=host \
|
||||
-v /dev:/dev \
|
||||
-v /opt/mxdriver:/opt/mxdriver:ro \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
-e ACCELERATOR=metax \
|
||||
-e PORT=17003 \
|
||||
-e METAX_VISIBLE_DEVICES=0 \
|
||||
unis/qwen3-asr:metax-latest
|
||||
|
||||
# 或使用 docker-compose-metax.yml
|
||||
docker compose -f docker-compose-metax.yml up -d
|
||||
```
|
||||
|
||||
构建沐曦镜像时,`Dockerfile.metax` 会基于沐曦官方 vLLM 镜像融合本项目代码与通用依赖:
|
||||
|
||||
```bash
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor metax \
|
||||
--base-image <沐曦官方vLLM镜像名> \
|
||||
-v n260-3.7.0.38
|
||||
```
|
||||
|
||||
沐曦等国产 GPU 的生产推荐路径是“厂商官方 vLLM 镜像 + 本项目代码/通用依赖”。不要在项目 Dockerfile 中重新 `pip install vllm`,避免解析到 PyPI/NVIDIA CUDA 依赖。
|
||||
|
||||
沐曦 GPU 的完整编译、模型准备和离线交付流程见 [沐曦 GPU 国产化离线部署指南](./metax_offline_deployment.md)。
|
||||
|
||||
### 天数 GPU 版本部署
|
||||
|
||||
适用于已安装天数驱动与容器运行栈的机器。按天数官方镜像运行建议,本 compose 使用 host network、host pid/ipc、privileged、`/dev`、`/usr/src`、`/lib/modules` 等挂载,并额外挂载本项目模型与数据目录:
|
||||
|
||||
```bash
|
||||
docker pull registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor iluvatar \
|
||||
--base-image registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5 \
|
||||
-v vllm0.17.0-4.4.0-v5
|
||||
|
||||
ASR_IMAGE=unis/qwen3-asr:iluvatar-vllm0.17.0-4.4.0-v5 \
|
||||
docker compose -f docker-compose-iluvatar.yml up -d
|
||||
```
|
||||
|
||||
天数 GPU 的完整编译、模型准备和离线交付流程见 [天数 GPU 国产化离线部署指南](./iluvatar_offline_deployment.md)。
|
||||
|
||||
### 摩尔线程 GPU 版本部署
|
||||
|
||||
适用于已安装摩尔线程驱动与 MUSA 容器运行栈的机器:
|
||||
|
||||
```bash
|
||||
docker pull registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519
|
||||
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor mthreads \
|
||||
--base-image registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519 \
|
||||
-v s4000_4.3.5_d0519
|
||||
|
||||
ASR_IMAGE=unis/qwen3-asr:mthreads-s4000_4.3.5_d0519 \
|
||||
docker compose -f docker-compose-mthreads.yml up -d
|
||||
```
|
||||
|
||||
摩尔线程 GPU 的完整编译、模型准备和离线交付流程见 [摩尔线程 GPU 国产化离线部署指南](./mthreads_offline_deployment.md)。
|
||||
|
||||
默认推荐将宿主机目录统一挂载到 `/opt/dep/asr` 下,目录结构如下:
|
||||
|
||||
```text
|
||||
/opt/dep/asr/models/
|
||||
Qwen/
|
||||
iic/
|
||||
damo/
|
||||
```
|
||||
|
||||
如果你希望挂载到自定义目录,可统一设置:
|
||||
|
||||
```bash
|
||||
export MODEL_STORAGE_DIR=/data/qwen3-asr-models
|
||||
export DATA_STORAGE_DIR=/data/qwen3-asr-data
|
||||
mkdir -p "$MODEL_STORAGE_DIR" "$DATA_STORAGE_DIR"
|
||||
docker-compose up -d
|
||||
```
|
||||
|
||||
### 多 GPU 拓扑模式
|
||||
|
||||
项目现在支持统一的多 GPU 拓扑开关:
|
||||
|
||||
- `ASR_DEPLOY_TOPOLOGY=isolated`
|
||||
- 默认模式
|
||||
- 每张卡启动 1 个 backend 实例
|
||||
- 容器内使用 Nginx 负载均衡到多个实例
|
||||
- `ASR_DEPLOY_TOPOLOGY=sharded`
|
||||
- 单个 backend 进程占用多张卡
|
||||
- 由 vLLM 在进程内部做多卡分片
|
||||
- `ASR_DEPLOY_TOPOLOGY=auto`
|
||||
- 优先尝试 `sharded`
|
||||
- 如果当前平台、可见设备或 shard 数不满足条件,则自动回退到 `isolated`
|
||||
|
||||
### NVIDIA 多 GPU 自动并行部署(推荐)
|
||||
|
||||
适用于并发量较高场景。该方案通过容器 entrypoint 自动完成:
|
||||
- 根据 `ASR_VISIBLE_DEVICES` 拉起多个 ASR 实例(每张卡 1 个实例)
|
||||
- 容器内自动生成 Nginx upstream 并负载均衡到各实例
|
||||
- 对外仍只暴露一个服务端口(默认 `8000`)
|
||||
|
||||
你不需要手工维护多个 `docker-compose` 服务块或手工维护 nginx upstream。
|
||||
|
||||
```bash
|
||||
# 4 卡示例:GPU0,1,2,3 各启动 1 个实例
|
||||
ASR_VISIBLE_DEVICES=0,1,2,3 docker-compose up -d
|
||||
```
|
||||
|
||||
常用组合:
|
||||
- 单卡(保持默认):`ASR_VISIBLE_DEVICES=0`
|
||||
- 双卡:`ASR_VISIBLE_DEVICES=0,1`
|
||||
- 四卡:`ASR_VISIBLE_DEVICES=0,1,2,3`
|
||||
|
||||
强制单实例多卡分片:
|
||||
|
||||
```bash
|
||||
ASR_DEPLOY_TOPOLOGY=sharded \
|
||||
ASR_VISIBLE_DEVICES=0,1 \
|
||||
docker-compose up -d
|
||||
```
|
||||
|
||||
自动选择模式:
|
||||
|
||||
```bash
|
||||
ASR_DEPLOY_TOPOLOGY=auto \
|
||||
ASR_VISIBLE_DEVICES=0,1 \
|
||||
docker-compose up -d
|
||||
```
|
||||
|
||||
**服务访问地址:**
|
||||
- API 服务: `http://localhost:17003`
|
||||
- API 文档: `http://localhost:17003/docs`
|
||||
|
||||
### 沐曦多 GPU 自动并行部署
|
||||
|
||||
```bash
|
||||
ASR_VISIBLE_DEVICES=0,1 docker compose -f docker-compose-metax.yml up -d
|
||||
```
|
||||
|
||||
### 摩尔线程多 GPU 自动并行部署
|
||||
|
||||
```bash
|
||||
ASR_VISIBLE_DEVICES=0,1 docker compose -f docker-compose-mthreads.yml up -d
|
||||
```
|
||||
|
||||
### CPU 版本部署
|
||||
|
||||
适用于开发测试或无 GPU 环境:
|
||||
|
||||
```bash
|
||||
docker run -d --name qwen3-asr \
|
||||
-p 17003:8000 \
|
||||
-v /opt/dep/asr/models:/app/models \
|
||||
-v /opt/dep/asr/data:/app/data \
|
||||
-e DEVICE=cpu \
|
||||
unis/qwen3-asr:cpu-latest
|
||||
```
|
||||
|
||||
**注意:** CPU 版本不使用 GPU/vLLM 路径。
|
||||
当前 CPU 镜像已集成 QwenASR Rust backend,会自动选择 `qwen3-asr-0.6b`。
|
||||
CPU 镜像默认使用可分发的 `x86-64-v2` Rust 构建目标,避免把构建机的 native CPU 指令带入通用镜像。
|
||||
如果你确认构建机与部署机 CPU 指令集一致,可在自建镜像时设置 `QWENASR_RUST_TARGET_CPU=native` 换取更激进优化。
|
||||
当前 Rust backend 的 x86 kernel 需要 `avx2` 与 `fma`,不满足时启动会给出明确错误。镜像默认限制
|
||||
`OPENBLAS_NUM_THREADS=1` / `OMP_NUM_THREADS=1` / `GOTO_NUM_THREADS=1`,以减少多 runtime 并发时的线程争抢。
|
||||
CUDA vLLM 与 CPU Rust 路径下,`word_timestamps=true` 会自动调用 forced aligner 返回字词级时间戳。
|
||||
|
||||
### 离线交付目录导出
|
||||
|
||||
如果你需要把镜像交付到不能联网的机器,推荐直接生成一个完整的离线交付目录。该脚本使用普通 `docker build` + `docker save`,不依赖 `buildx`:
|
||||
|
||||
```bash
|
||||
# 生成 GPU 离线交付目录
|
||||
./export_offline_bundle.sh --type gpu
|
||||
|
||||
# 或生成 CPU 离线交付目录
|
||||
./export_offline_bundle.sh --type cpu
|
||||
|
||||
# 或生成沐曦 GPU 离线交付目录
|
||||
./export_offline_bundle.sh \
|
||||
--type metax \
|
||||
--metax-base cr.metax-tech.com/public-ai-release/maca/vllm-metax:0.17.0-maca.ai3.5.3.307-torch2.8-py312-ubuntu22.04-amd64 \
|
||||
--skip-models
|
||||
./export_offline_bundle.sh --type iluvatar --iluvatar-base registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
./export_offline_bundle.sh --type mthreads --mthreads-base registry.mthreads.com/presale/devtech/vllm_musa:s4000_4.3.5_d0519
|
||||
|
||||
# 或一次同时生成 GPU + CPU 离线交付目录
|
||||
./export_offline_bundle.sh --type all
|
||||
```
|
||||
|
||||
生成后的目录形如:
|
||||
|
||||
```text
|
||||
build-file/
|
||||
20260520_153000-all/
|
||||
qwen3-asr-cpu-20260520_153000-amd64.tar.gz
|
||||
qwen3-asr-gpu-20260520_153000-amd64.tar.gz
|
||||
docker-compose.yml
|
||||
docker-compose-cpu.yml
|
||||
docker-compose-metax.yml
|
||||
.env.example
|
||||
init_host_dirs.sh
|
||||
README.md
|
||||
DEPLOYMENT.md
|
||||
```
|
||||
|
||||
其中会自动包含:
|
||||
|
||||
- 对应类型的一份或两份镜像压缩包
|
||||
- 对应类型的 compose 文件;天数包只包含 `docker-compose-iluvatar.yml`
|
||||
- 摩尔线程包只包含 `docker-compose-mthreads.yml`
|
||||
- `.env` 模板
|
||||
- 宿主机目录初始化脚本
|
||||
- 离线部署说明文档
|
||||
|
||||
模型文件建议使用 `./scripts/download-models.sh --models-dir /opt/dep/asr/models` 单独准备;该脚本增量补齐缺失模型,不删除已有目录,也不依赖 uv。
|
||||
|
||||
当前运行时 / 设备默认值以主 README 为准:
|
||||
|
||||
- `README.md`
|
||||
- `docs/README_zh.md`
|
||||
设计背景与实现思路可参考:
|
||||
|
||||
- 当前 Qwen3 后端:`NVIDIA/沐曦 GPU -> vLLM`、`CPU/macOS -> vendored QwenASR Rust`
|
||||
- 引用项目 [QwenASR](https://github.com/huanglizhuo/QwenASR)
|
||||
|
||||
### macOS / Apple Silicon 本地部署
|
||||
|
||||
适用于 M1/M2/M3/M4 机器上的本地 Qwen3-ASR 推理。当前 macOS 已统一走 vendored QwenASR Rust CPU backend。
|
||||
|
||||
```bash
|
||||
./scripts/sync_cpu_env.sh
|
||||
source .venv/bin/activate
|
||||
python start.py
|
||||
```
|
||||
|
||||
### 验证部署
|
||||
|
||||
```bash
|
||||
# 健康检查
|
||||
curl http://localhost:17003/stream/v1/asr/health
|
||||
|
||||
# 查看可用模型
|
||||
curl http://localhost:17003/stream/v1/asr/models
|
||||
|
||||
# 测试语音识别(阿里云协议)
|
||||
curl -X POST "http://localhost:17003/stream/v1/asr" \
|
||||
-H "Content-Type: application/octet-stream" \
|
||||
--data-binary @test.wav
|
||||
|
||||
# 测试 OpenAI 兼容接口
|
||||
curl -X POST "http://localhost:17003/v1/audio/transcriptions" \
|
||||
-H "Authorization: Bearer any" \
|
||||
-F "file=@test.wav" \
|
||||
-F "model=qwen3-asr-1.7b"
|
||||
```
|
||||
|
||||
## 从源码构建镜像
|
||||
|
||||
### 使用构建脚本
|
||||
|
||||
项目提供了一个更薄的 `scripts/build_docker.sh` 包装层,用于统一 `docker buildx` 参数:
|
||||
|
||||
```bash
|
||||
# 构建所有版本(CPU + GPU)
|
||||
./scripts/build_docker.sh
|
||||
|
||||
# 仅构建 GPU 版本
|
||||
./scripts/build_docker.sh -t gpu
|
||||
|
||||
# 构建指定版本并推送
|
||||
./scripts/build_docker.sh -t all -v 1.0.1 -p
|
||||
|
||||
# 查看帮助
|
||||
./scripts/build_docker.sh -h
|
||||
```
|
||||
|
||||
**构建脚本参数:**
|
||||
|
||||
| 参数 | 说明 | 默认值 |
|
||||
|------|------|--------|
|
||||
| `-a, --arch` | 目标架构: `amd64`, `arm64`, `multi` | `amd64` |
|
||||
| `-t, --type` | 构建类型: `cpu`, `gpu`, `all` | `all` |
|
||||
| `-v, --version` | 版本标签 | `latest` |
|
||||
| `-p, --push` | 构建后推送到 Docker Hub | 否 |
|
||||
| `-e, --export` | 导出单架构镜像为 tar.gz | 否 |
|
||||
| `-o, --output` | 导出目录 | `.` |
|
||||
| `-r, --registry` | 镜像仓库 | `unis` |
|
||||
| `-n, --no-cache` | 禁用 Docker 构建缓存 | 否 |
|
||||
|
||||
### 手动构建
|
||||
|
||||
```bash
|
||||
# 构建 CPU 版本
|
||||
docker build -t qwen3-asr:cpu-latest -f Dockerfile.cpu .
|
||||
|
||||
# 构建绑定当前机器指令集的 CPU 版本(仅适合同构部署)
|
||||
docker build -t qwen3-asr:cpu-native -f Dockerfile.cpu \
|
||||
--build-arg QWENASR_RUST_TARGET_CPU=native \
|
||||
.
|
||||
|
||||
# 构建默认 GPU 版本(CUDA 13.0 / PyTorch cu130)
|
||||
docker build -t qwen3-asr:gpu-cu130 -f Dockerfile.gpu .
|
||||
|
||||
# 构建 CUDA 12.6 版本
|
||||
docker build -t qwen3-asr:gpu-cu126 -f Dockerfile.gpu \
|
||||
--build-arg PYTORCH_BASE_IMAGE=pytorch/pytorch:2.11.0-cuda12.6-cudnn9-runtime \
|
||||
--build-arg PYTORCH_CUDA_INDEX=https://download.pytorch.org/whl/cu126 \
|
||||
--build-arg CUDA_NVCC_PACKAGE=cuda-nvcc-12-6 \
|
||||
--build-arg TORCH_CUDA_ARCH_LIST="8.0;8.6;8.9" \
|
||||
.
|
||||
|
||||
# 构建 CUDA 13.0 版本
|
||||
docker build -t qwen3-asr:gpu-cu130 -f Dockerfile.gpu \
|
||||
--build-arg PYTORCH_BASE_IMAGE=pytorch/pytorch:2.11.0-cuda13.0-cudnn9-runtime \
|
||||
--build-arg PYTORCH_CUDA_INDEX=https://download.pytorch.org/whl/cu130 \
|
||||
--build-arg CUDA_NVCC_PACKAGE=cuda-nvcc-13-0 \
|
||||
--build-arg TORCH_CUDA_ARCH_LIST="12.0+PTX" \
|
||||
.
|
||||
```
|
||||
|
||||
`Dockerfile.cpu` 可覆盖的 CPU 构建参数:
|
||||
|
||||
| 参数 | 默认值 | 说明 |
|
||||
|------|--------|------|
|
||||
| `QWENASR_RUST_TARGET_CPU` | `x86-64-v2` | amd64 Rust backend 编译目标;可设为 `native` 构建绑定当前 CPU 的镜像 |
|
||||
|
||||
`Dockerfile.gpu` 可覆盖的 GPU 构建参数:
|
||||
|
||||
| 参数 | 默认值 | 用途 |
|
||||
|------|--------|------|
|
||||
| `PYTORCH_BASE_IMAGE` | `pytorch/pytorch:2.11.0-cuda13.0-cudnn9-runtime` | 选择 PyTorch/CUDA 基础镜像 |
|
||||
| `PYTORCH_CUDA_INDEX` | `https://download.pytorch.org/whl/cu130` | 选择 PyTorch wheel CUDA 后端 |
|
||||
| `CUDA_NVCC_PACKAGE` | `cuda-nvcc-13-0` | 安装匹配的 nvcc,用于 vLLM/FlashInfer JIT |
|
||||
| `TORCH_CUDA_ARCH_LIST` | `12.0+PTX` | 指定 JIT 编译目标架构 |
|
||||
| `VLLM_PACKAGE` | `vllm==0.20.0` | 覆盖 vLLM 包版本或来源 |
|
||||
|
||||
### 模型说明
|
||||
|
||||
服务支持以下 ASR 模型:
|
||||
|
||||
| 模型 | 说明 | 适用场景 |
|
||||
|------|------|----------|
|
||||
| Qwen3-ASR-1.7B ⭐ | 多语言 ASR(52种语言+方言,字级时间戳) | CUDA |
|
||||
| Qwen3-ASR-0.6B | 轻量版多语言 ASR | CUDA / CPU Rust / macOS |
|
||||
|
||||
**运行时模型选择:**
|
||||
|
||||
系统根据机器资源自动选择合适的 Qwen3-ASR 模型:
|
||||
- **显存 >= 32GB**: 自动加载 `qwen3-asr-1.7b`
|
||||
- **显存 < 32GB**: 自动加载 `qwen3-asr-0.6b`
|
||||
- **无 CUDA**: 自动加载基于 vendored Rust 的 `qwen3-asr-0.6b`
|
||||
- **macOS / Apple Silicon**: 无论内存大小多少,默认都加载 `qwen3-asr-0.6b`
|
||||
- **环境变量覆盖**: 设置 `QWEN3_ASR_MODEL=qwen3-asr-1.7b` 或 `QWEN3_ASR_MODEL=qwen3-asr-0.6b` 可硬覆盖自动选择
|
||||
|
||||
### 模型下载
|
||||
|
||||
启动时会先检测当前运行计划所需模型;如果本地缓存缺失,会自动从 ModelScope 下载。离线部署请提前准备模型缓存。
|
||||
手动准备方式:
|
||||
|
||||
```bash
|
||||
# 增量补齐离线部署所需模型,不删除已有文件
|
||||
./scripts/download-models.sh --models-dir /opt/dep/asr/models
|
||||
|
||||
# 如果本机缺少 Python 依赖,也可以使用已构建镜像下载
|
||||
ASR_IMAGE=unis/qwen3-asr:iluvatar-vllm0.17.0-4.4.0-v5 \
|
||||
./scripts/download-models.sh --mode docker --models-dir /opt/dep/asr/models
|
||||
```
|
||||
|
||||
离线部署时,推荐目录结构:
|
||||
|
||||
```text
|
||||
/opt/dep/asr/models/
|
||||
Qwen/
|
||||
iic/
|
||||
damo/
|
||||
```
|
||||
|
||||
然后保持与 compose 文件一致的挂载:
|
||||
|
||||
```yaml
|
||||
volumes:
|
||||
- ${MODEL_STORAGE_DIR:-/opt/dep/asr/models}:/app/models
|
||||
- ${DATA_STORAGE_DIR:-/opt/dep/asr/data}:/app/data
|
||||
```
|
||||
|
||||
## 环境变量配置
|
||||
|
||||
### 基础配置
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `HOST` | `0.0.0.0` | 服务绑定地址 |
|
||||
| `PORT` | `8000` | 服务端口 |
|
||||
| `DEBUG` | `false` | 调试模式(启用后可访问 /docs) |
|
||||
| `LOG_LEVEL` | `INFO` | 日志级别:DEBUG, INFO, WARNING, ERROR |
|
||||
| `WORKERS` | `1` | 工作进程数(多进程会复制模型,显存成倍增加) |
|
||||
| `MAX_AUDIO_SIZE` | `2048` | 最大音频文件大小(MB,支持单位如 2GB) |
|
||||
| `API_KEY` | - | 服务端统一鉴权密钥 |
|
||||
|
||||
### 设备配置
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `DEVICE` | `auto` | 设备选择:`auto`, `cpu`, `cuda:0` |
|
||||
| `ASR_VISIBLE_DEVICES` | `0` | 统一可见 GPU 设备配置,程序会按当前 accelerator 自动映射到底层变量 |
|
||||
| `ASR_DEPLOY_TOPOLOGY` | `isolated` | 部署拓扑:`isolated`, `sharded`, `auto` |
|
||||
|
||||
### 内置 Nginx 与限流配置
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `NGINX_RATE_LIMIT_RPS` | `0` | 全局每秒请求上限,`0` 表示关闭 |
|
||||
| `NGINX_RATE_LIMIT_BURST` | `0` | 全局突发请求数,`0` 时自动取 `NGINX_RATE_LIMIT_RPS` |
|
||||
|
||||
### ASR 模型配置
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `ASR_ENABLE_REALTIME_PUNC` | `true` | 是否启用实时标点模型 |
|
||||
|
||||
### 性能优化配置
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `ASR_BATCH_SIZE` | `4` | 长音频分段后的 ASR 批处理大小 |
|
||||
| `INFERENCE_THREAD_POOL_SIZE` | 自动 | 推理线程池大小;默认按 CPU 核数自动设置 |
|
||||
| `MAX_SEGMENT_SEC` | `60` | 音频分段最大时长(秒) |
|
||||
| `QWEN_GPU_MEMORY_UTILIZATION` | `0.9` | vLLM 可保留的 GPU 显存上限,KV cache 不足时可适当调高 |
|
||||
| `QWEN_VLLM_ENFORCE_EAGER` | `true` | 强制 vLLM eager 执行以提高兼容性;NVIDIA 性能测试可设为 `false` 允许 CUDA Graph 优化 |
|
||||
| `WS_MAX_BUFFER_SIZE` | `160000` | WebSocket 音频缓冲区大小(样本数) |
|
||||
| `QWEN_RUST_CPU_WORKERS` | `4` | CPU Rust backend worker 数;Rust ASR / forced align 默认按该数量并行 |
|
||||
| `QWEN_RUST_ASR_CONCURRENCY` | `0` | Rust ASR 阶段批内并行度;`0` 表示跟随 `QWEN_RUST_CPU_WORKERS` |
|
||||
| `QWEN_RUST_ALIGN_CONCURRENCY` | `0` | Rust forced align 阶段批内并行度;`0` 表示跟随 `QWEN_RUST_CPU_WORKERS` |
|
||||
| `QWENASR_LIBRARY_PATH` | 自动探测 | 覆盖 vendored Rust 动态库路径 |
|
||||
|
||||
### 远场过滤配置
|
||||
|
||||
流式 ASR 远场声音过滤功能,自动过滤远场声音和环境音:
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `ASR_ENABLE_NEARFIELD_FILTER` | `true` | 启用远场声音过滤 |
|
||||
| `ASR_NEARFIELD_RMS_THRESHOLD` | `0.01` | RMS 能量阈值 |
|
||||
| `LOG_LEVEL=DEBUG` | - | 需要观察过滤细节时打开调试日志 |
|
||||
|
||||
调优建议:
|
||||
|
||||
- `ASR_NEARFIELD_RMS_THRESHOLD=0.01` 是当前默认值,也是推荐起点
|
||||
- 嘈杂环境可以适当调高,增强背景语音过滤
|
||||
- 安静环境如果出现小声说话漏识别,可以适当调低
|
||||
- 需要观察过滤行为时,可临时设置 `LOG_LEVEL=DEBUG`
|
||||
|
||||
### 鉴权配置
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `API_KEY` | - | 服务端统一鉴权密钥;同时兼容 `Authorization: Bearer` 和 `X-NLS-Token` |
|
||||
|
||||
**使用示例:**
|
||||
|
||||
```bash
|
||||
# 使用 Token
|
||||
curl -H "X-NLS-Token: your_token" http://localhost:8000/stream/v1/asr/health
|
||||
|
||||
# 使用 Bearer Token(OpenAI 兼容)
|
||||
curl -H "Authorization: Bearer your_token" http://localhost:8000/v1/models
|
||||
```
|
||||
|
||||
### 日志配置
|
||||
|
||||
| 环境变量 | 默认值 | 说明 |
|
||||
|----------|--------|------|
|
||||
| `LOG_LEVEL` | `INFO` | 日志级别:`DEBUG`, `INFO`, `WARNING` |
|
||||
| `LOG_FILE` | `data/logs/qwen3-asr.log` | 日志文件路径 |
|
||||
| `LOG_MAX_BYTES` | `20971520` | 单个日志文件最大大小(20MB) |
|
||||
| `LOG_BACKUP_COUNT` | `50` | 日志备份文件数量 |
|
||||
|
||||
## Docker Compose 配置
|
||||
|
||||
### 基础配置(GPU)
|
||||
|
||||
```yaml
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: unis/qwen3-asr:gpu-latest
|
||||
container_name: qwen3-asr
|
||||
ports:
|
||||
- "17003:8000"
|
||||
volumes:
|
||||
- /opt/dep/asr/models:/app/models
|
||||
- /opt/dep/asr/data:/app/data
|
||||
environment:
|
||||
- DEBUG=false
|
||||
- LOG_LEVEL=INFO
|
||||
- DEVICE=auto
|
||||
- QWEN_GPU_MEMORY_UTILIZATION=0.3
|
||||
- QWEN_VLLM_ENFORCE_EAGER=true
|
||||
- ASR_BATCH_SIZE=4
|
||||
- WORKERS=1
|
||||
- INFERENCE_THREAD_POOL_SIZE=4
|
||||
restart: unless-stopped
|
||||
deploy:
|
||||
resources:
|
||||
reservations:
|
||||
devices:
|
||||
- driver: nvidia
|
||||
count: all
|
||||
capabilities: [gpu]
|
||||
```
|
||||
|
||||
### CPU 版本配置
|
||||
|
||||
```yaml
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: unis/qwen3-asr:cpu-latest
|
||||
container_name: qwen3-asr
|
||||
ports:
|
||||
- "17003:8000"
|
||||
volumes:
|
||||
- /opt/dep/asr/models:/app/models
|
||||
- /opt/dep/asr/data:/app/data
|
||||
environment:
|
||||
- DEBUG=false
|
||||
- LOG_LEVEL=INFO
|
||||
- DEVICE=cpu
|
||||
- WORKERS=1
|
||||
- INFERENCE_THREAD_POOL_SIZE=1
|
||||
restart: unless-stopped
|
||||
```
|
||||
|
||||
### 生产环境配置(内置 Nginx,推荐)
|
||||
|
||||
```yaml
|
||||
services:
|
||||
qwen3-asr:
|
||||
image: unis/qwen3-asr:gpu-latest
|
||||
container_name: qwen3-asr
|
||||
ports:
|
||||
- "17003:8000"
|
||||
volumes:
|
||||
- /opt/dep/asr/models:/app/models
|
||||
- /opt/dep/asr/data:/app/data
|
||||
environment:
|
||||
- DEBUG=false
|
||||
- LOG_LEVEL=INFO
|
||||
- DEVICE=auto
|
||||
- CUDA_VISIBLE_DEVICES=0,1
|
||||
- QWEN_GPU_MEMORY_UTILIZATION=0.3
|
||||
- QWEN_VLLM_ENFORCE_EAGER=true
|
||||
- NGINX_RATE_LIMIT_RPS=20
|
||||
- NGINX_RATE_LIMIT_BURST=40
|
||||
- WORKERS=1
|
||||
- INFERENCE_THREAD_POOL_SIZE=4
|
||||
- ASR_BATCH_SIZE=4
|
||||
restart: unless-stopped
|
||||
deploy:
|
||||
resources:
|
||||
reservations:
|
||||
devices:
|
||||
- driver: nvidia
|
||||
count: all
|
||||
capabilities: [gpu]
|
||||
```
|
||||
|
||||
## 服务监控
|
||||
|
||||
### 健康检查
|
||||
|
||||
```bash
|
||||
curl http://localhost:17003/stream/v1/asr/health
|
||||
```
|
||||
|
||||
### 日志监控
|
||||
|
||||
```bash
|
||||
# 实时查看日志
|
||||
docker logs -f qwen3-asr
|
||||
|
||||
# 查看错误日志
|
||||
docker logs qwen3-asr 2>&1 | grep -i error
|
||||
```
|
||||
|
||||
### 资源监控
|
||||
|
||||
```bash
|
||||
# 容器资源使用
|
||||
docker stats qwen3-asr
|
||||
|
||||
# GPU 使用情况
|
||||
docker exec -it qwen3-asr nvidia-smi
|
||||
```
|
||||
|
||||
## 资源需求
|
||||
|
||||
### 最小配置(CPU 版本)
|
||||
|
||||
- CPU: 4 核
|
||||
- 内存: 8GB
|
||||
- 磁盘: 10GB
|
||||
|
||||
### 推荐配置(GPU 版本)
|
||||
|
||||
- CPU: 8 核
|
||||
- 内存: 16GB
|
||||
- GPU: NVIDIA GPU (12GB+ 显存,含说话人分离模型)
|
||||
- 磁盘: 25GB
|
||||
|
||||
## 故障排除
|
||||
|
||||
### 常见问题
|
||||
|
||||
| 问题 | 症状 | 解决方案 |
|
||||
|------|------|----------|
|
||||
| GPU 内存不足 | CUDA OOM 错误 | 设置 `DEVICE=cpu` 或使用更大显存的 GPU |
|
||||
| 模型加载失败 / 缓慢 | 本地模型缓存缺失 | 先运行 `./scripts/download-models.sh --models-dir /opt/dep/asr/models` 预准备模型 |
|
||||
| 端口被占用 | 端口冲突错误 | 修改端口映射:`"8080:8000"` |
|
||||
| 说话人分离失败 | CAM++ 模型错误 | 检查模型是否完整下载,显存是否充足 |
|
||||
|
||||
### 调试模式
|
||||
|
||||
```bash
|
||||
# 启用调试模式
|
||||
docker run -e DEBUG=true -e LOG_LEVEL=DEBUG ...
|
||||
|
||||
# 进入容器调试
|
||||
docker exec -it qwen3-asr /bin/bash
|
||||
```
|
||||
|
||||
## 更新服务
|
||||
|
||||
```bash
|
||||
# 拉取最新镜像(GPU 版本)
|
||||
docker pull unis/qwen3-asr:gpu-latest
|
||||
|
||||
# 拉取最新镜像(CPU 版本)
|
||||
docker pull unis/qwen3-asr:cpu-latest
|
||||
|
||||
# 重启服务
|
||||
docker-compose down && docker-compose up -d
|
||||
```
|
||||
|
|
@ -0,0 +1,242 @@
|
|||
# 天数 GPU 国产化离线部署指南
|
||||
|
||||
本文档用于天数/Iluvatar GPU 环境的编译、模型准备、离线包导出与目标机部署。
|
||||
|
||||
## 推荐基础镜像
|
||||
|
||||
天数默认推荐使用以下官方 vLLM 镜像作为基础镜像:
|
||||
|
||||
```bash
|
||||
registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
```
|
||||
|
||||
该镜像负责提供天数 IX 运行时、PyTorch、vLLM 与相关内核。本项目的 `Dockerfile.iluvatar` 只叠加通用 Python 依赖和业务代码,不在 Dockerfile 内重新安装 vLLM,也不使用 uv 虚拟环境。
|
||||
|
||||
## 目录约定
|
||||
|
||||
目标机推荐统一使用以下宿主机目录:
|
||||
|
||||
```text
|
||||
/opt/dep/asr/
|
||||
models/
|
||||
data/
|
||||
logs/
|
||||
temp/
|
||||
tasks/
|
||||
```
|
||||
|
||||
容器内默认挂载为:
|
||||
|
||||
```text
|
||||
/app/models
|
||||
/app/data
|
||||
```
|
||||
|
||||
## 在线编译融合镜像
|
||||
|
||||
在可访问天数镜像仓库和 Python 包源的构建机上执行:
|
||||
|
||||
```bash
|
||||
docker pull registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5
|
||||
|
||||
./scripts/package_vendor_gpu_image.sh \
|
||||
--vendor iluvatar \
|
||||
--base-image registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5 \
|
||||
-v vllm0.17.0-4.4.0-v5
|
||||
```
|
||||
|
||||
脚本会生成融合镜像:
|
||||
|
||||
```text
|
||||
unis/qwen3-asr:iluvatar-vllm0.17.0-4.4.0-v5
|
||||
```
|
||||
|
||||
并导出镜像归档到:
|
||||
|
||||
```text
|
||||
build-file/qwen3-asr-iluvatar-vllm0.17.0-4.4.0-v5-amd64.tar.gz
|
||||
```
|
||||
|
||||
如果只需要本机镜像,不需要导出 tar 包,可增加 `--no-export`。
|
||||
|
||||
## 单独准备模型
|
||||
|
||||
模型下载建议独立于业务服务执行。`download-models.sh` 是增量下载脚本,不会删除已有模型目录,也不依赖 uv。
|
||||
|
||||
在项目根目录或离线包目录执行:
|
||||
|
||||
```bash
|
||||
./scripts/download-models.sh --models-dir /opt/dep/asr/models
|
||||
```
|
||||
|
||||
如果本机没有 Python 依赖,但已经有融合镜像,可以用镜像内环境下载:
|
||||
|
||||
```bash
|
||||
ASR_IMAGE=unis/qwen3-asr:iluvatar-vllm0.17.0-4.4.0-v5 \
|
||||
./scripts/download-models.sh \
|
||||
--mode docker \
|
||||
--models-dir /opt/dep/asr/models
|
||||
```
|
||||
|
||||
模型目录最终应至少包含:
|
||||
|
||||
```text
|
||||
/opt/dep/asr/models/
|
||||
Qwen/
|
||||
Qwen3-ASR-0.6B/
|
||||
Qwen3-ForcedAligner-0.6B/
|
||||
damo/
|
||||
iic/
|
||||
```
|
||||
|
||||
## 导出完整离线交付包
|
||||
|
||||
如果要交付给不能联网的目标机,推荐直接导出天数专用离线包:
|
||||
|
||||
```bash
|
||||
./export_offline_bundle.sh \
|
||||
--type iluvatar \
|
||||
--iluvatar-base registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5 \
|
||||
-v vllm0.17.0-4.4.0-v5
|
||||
```
|
||||
|
||||
如果模型要单独准备,不希望离线包包含模型压缩包:
|
||||
|
||||
```bash
|
||||
./export_offline_bundle.sh \
|
||||
--type iluvatar \
|
||||
--iluvatar-base registry.iluvatar.com.cn:10443/customer/sz/vllm0.17.0-4.4.0-x86:v5 \
|
||||
-v vllm0.17.0-4.4.0-v5 \
|
||||
--skip-models
|
||||
```
|
||||
|
||||
天数离线包只会包含天数专用启动文件:
|
||||
|
||||
```text
|
||||
docker-compose-iluvatar.yml
|
||||
.env
|
||||
.env.example
|
||||
init_host_dirs.sh
|
||||
download-models.sh
|
||||
download_models_standalone.py
|
||||
README.md
|
||||
DEPLOYMENT.md
|
||||
BUNDLE_INFO.txt
|
||||
qwen3-asr-iluvatar-*-amd64.tar.gz
|
||||
```
|
||||
|
||||
不会再要求使用通用 `docker-compose.yml`。
|
||||
|
||||
## 目标机离线部署
|
||||
|
||||
将整个离线包复制到目标机后,进入离线包目录:
|
||||
|
||||
```bash
|
||||
chmod +x init_host_dirs.sh download-models.sh
|
||||
./init_host_dirs.sh
|
||||
```
|
||||
|
||||
导入镜像:
|
||||
|
||||
```bash
|
||||
gunzip -c qwen3-asr-iluvatar-vllm0.17.0-4.4.0-v5-amd64.tar.gz | docker load
|
||||
```
|
||||
|
||||
确认 `.env` 中的镜像名与导入镜像一致:
|
||||
|
||||
```env
|
||||
ASR_IMAGE=unis/qwen3-asr:iluvatar-vllm0.17.0-4.4.0-v5
|
||||
```
|
||||
|
||||
按需设置显卡与 vLLM 显存比例:
|
||||
|
||||
```env
|
||||
ILUVATAR_VISIBLE_DEVICES=0
|
||||
IX_VISIBLE_DEVICES=0
|
||||
CUDA_VISIBLE_DEVICES=0
|
||||
QWEN_GPU_MEMORY_UTILIZATION=0.25
|
||||
QWEN_VLLM_ENFORCE_EAGER=true
|
||||
```
|
||||
|
||||
启动服务:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose-iluvatar.yml up -d
|
||||
```
|
||||
|
||||
查看状态与日志:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose-iluvatar.yml ps
|
||||
docker compose -f docker-compose-iluvatar.yml logs -f
|
||||
```
|
||||
|
||||
服务默认监听 host 网络端口:
|
||||
|
||||
```text
|
||||
http://<目标机IP>:17003
|
||||
```
|
||||
|
||||
## 已导出的旧离线包处理
|
||||
|
||||
如果旧离线包里的镜像已经能识别 `Qwen3ASRForConditionalGeneration`,但启动时报 KV cache 不足,例如:
|
||||
|
||||
```text
|
||||
Try increasing gpu_memory_utilization or decreasing max_model_len
|
||||
```
|
||||
|
||||
不需要重新打镜像。只需要在旧离线包的 `docker-compose-iluvatar.yml` 的 `QWEN3_ASR_MODEL` 附近补充:
|
||||
|
||||
```yaml
|
||||
QWEN_GPU_MEMORY_UTILIZATION: ${QWEN_GPU_MEMORY_UTILIZATION:-0.25}
|
||||
QWEN_VLLM_ENFORCE_EAGER: ${QWEN_VLLM_ENFORCE_EAGER:-true}
|
||||
```
|
||||
|
||||
然后重新创建容器:
|
||||
|
||||
```bash
|
||||
docker compose -f docker-compose-iluvatar.yml down
|
||||
docker compose -f docker-compose-iluvatar.yml up -d
|
||||
```
|
||||
|
||||
只执行 `restart` 不会重新注入环境变量。
|
||||
|
||||
## 常见问题
|
||||
|
||||
### 为什么不用 uv?
|
||||
|
||||
天数 Docker 镜像内推荐直接使用系统 Python 环境。`Dockerfile.iluvatar` 使用:
|
||||
|
||||
```bash
|
||||
python3 -m pip install --no-cache-dir -r environments/iluvatar/requirements.txt
|
||||
```
|
||||
|
||||
不创建 uv 虚拟环境,也不在镜像内运行 `uv pip install`。
|
||||
|
||||
### 为什么不重新安装 vLLM?
|
||||
|
||||
国产 GPU 的 vLLM、PyTorch、内核和运行时通常需要严格匹配厂商镜像。项目层重新 `pip install vllm` 容易解析到 PyPI/NVIDIA CUDA 依赖,破坏天数官方镜像里的匹配关系。
|
||||
|
||||
### `QWEN_GPU_MEMORY_UTILIZATION` 为什么没生效?
|
||||
|
||||
变量必须进入容器才会生效。天数 compose 中需要有:
|
||||
|
||||
```yaml
|
||||
QWEN_GPU_MEMORY_UTILIZATION: ${QWEN_GPU_MEMORY_UTILIZATION:-}
|
||||
QWEN_VLLM_ENFORCE_EAGER: ${QWEN_VLLM_ENFORCE_EAGER:-true}
|
||||
```
|
||||
|
||||
然后在 `.env` 设置:
|
||||
|
||||
```env
|
||||
QWEN_GPU_MEMORY_UTILIZATION=0.25
|
||||
QWEN_VLLM_ENFORCE_EAGER=true
|
||||
```
|
||||
|
||||
修改 `.env` 后必须 `down` 再 `up -d`。
|
||||
|
||||
### 日志中的本地模型 repo id warning 是否致命?
|
||||
|
||||
vLLM 可能会先尝试按远端 repo 方式读取 safetensors,遇到本地路径时打印 warning。如果后续出现 `Loading safetensors checkpoint shards` 并继续加载权重,通常不是致命错误。
|
||||
|
||||
真正需要处理的是最后的异常,例如模型架构不识别、KV cache 不足、模型文件缺失等。
|
||||
Some files were not shown because too many files have changed in this diff Show More
Loading…
Reference in New Issue